<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://systemhalted.in/feed.xml" rel="self" type="application/atom+xml" /><link href="https://systemhalted.in/" rel="alternate" type="text/html" /><updated>2026-09-04T04:25:16+00:00</updated><id>https://systemhalted.in/feed.xml</id><title type="html">SystemHalted</title><subtitle>SystemHalted is the personal blog of Palak Mathur, covering software engineering, leadership, management, and Emacs, plus the Kartavya Path newsletter.</subtitle><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><entry><title type="html">GTIDs, Kafka Consumer Offsets, and What a Recovery Checkpoint Really Means</title><link href="https://systemhalted.in/2026/09/03/gtid-kafka-dr/" rel="alternate" type="text/html" title="GTIDs, Kafka Consumer Offsets, and What a Recovery Checkpoint Really Means" /><published>2026-09-03T00:00:00+00:00</published><updated>2026-09-03T00:00:00+00:00</updated><id>https://systemhalted.in/2026/09/03/gtid-kafka-dr</id><content type="html" xml:base="https://systemhalted.in/2026/09/03/gtid-kafka-dr/"><![CDATA[<p>A recent MySQL change caught my attention because it intersects with a problem I have been thinking about while working through disaster recovery for an Event Streaming Platform built on Kafka.</p>

<p>MySQL 26.7.0 was released on July 28, 2026. Among its replication changes, MySQL introduced the Change Stream Applier, or CSA, a new implementation of the replica SQL applier for multithreaded replication. CSA is currently opt in, but some of its requirements are interesting: it does not support file position replication channels, requires <code class="language-plaintext highlighter-rouge">GTID_MODE=ON</code>, and requires <code class="language-plaintext highlighter-rouge">GTID_ONLY=1</code>.<sup id="fnref:mysql-csa"><a href="#fn:mysql-csa" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<p>What interested me was not GTID itself, but what the requirement implies: MySQL’s newer replication machinery is making transaction identity a prerequisite while leaving file position replication behind.</p>

<p>That made me ask what the equivalent recovery state actually is in Kafka.</p>

<h2 id="file-position-versus-transaction-identity">File Position Versus Transaction Identity</h2>

<p>Traditional MySQL replication can describe progress using a binary log file and byte position:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>mysql-bin.004217:18372944
</code></pre></div></div>

<p>That answers:</p>

<blockquote>
  <p>What location should I continue from?</p>
</blockquote>

<p>A Global Transaction Identifier answers a different question.</p>

<p>MySQL assigns a GTID to a transaction when that transaction is committed on its originating server. When the transaction is replicated, it retains the same GTID on the replica.<sup id="fnref:mysql-gtid"><a href="#fn:mysql-gtid" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>Conceptually:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>server-uuid:transaction-number
</code></pre></div></div>

<p>The transaction can appear in different binary log files and at different positions as it moves through the topology, while its identity remains unchanged.</p>

<p>With GTID-based replication, MySQL can reason about which transactions have already been executed and which are still missing without depending on binary log filenames and positions.<sup id="fnref:mysql-gtid-failover"><a href="#fn:mysql-gtid-failover" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>The recovery question changes from:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Where was I?
</code></pre></div></div>

<p>to:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Which transactions have I already applied?
</code></pre></div></div>

<p>That distinction immediately reminded me of Kafka.</p>

<h2 id="kafka-uses-positions-differently">Kafka Uses Positions Differently</h2>

<p>Kafka assigns each record a monotonically increasing offset within a topic partition:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>orders
partition 7
offset 928471
</code></pre></div></div>

<p>The offset identifies a position in that partition’s log. It does not globally identify the business event.</p>

<p>Within a Kafka cluster, however, the offset is already independent of physical broker placement. A partition is replicated across brokers, and if leadership moves to another replica, consumers continue operating in terms of the same topic, partition, and offset space.<sup id="fnref:kafka-replication"><a href="#fn:kafka-replication" class="footnote" rel="footnote" role="doc-noteref">4</a></sup></p>

<p>So Kafka separates:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>physical broker placement
</code></pre></div></div>

<p>from:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>topic + partition + offset
</code></pre></div></div>

<p>Consumer progress adds another dimension.</p>

<p>Kafka does not maintain one consumer position for a topic. A committed position belongs to a consumer group and topic partition:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>consumer-group
    +
topic
    +
partition
    →
committed offset
</code></pre></div></div>

<p>Kafka stores those committed group offsets in the internal compacted topic <code class="language-plaintext highlighter-rouge">__consumer_offsets</code>.<sup id="fnref:kafka-offset-storage"><a href="#fn:kafka-offset-storage" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<p>For example:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>group: payment-processor
topic: payments
partition: 3
committed offset: 10001
</code></pre></div></div>

<p>The committed offset normally represents the <strong>next record to consume</strong>. If the consumer successfully processed record <code class="language-plaintext highlighter-rouge">10000</code>, it would typically commit <code class="language-plaintext highlighter-rouge">10001</code>.<sup id="fnref:kafka-commit-semantics"><a href="#fn:kafka-commit-semantics" class="footnote" rel="footnote" role="doc-noteref">6</a></sup></p>

<p>Another consumer group reading the same partition may have a completely different committed position.</p>

<p>This works well inside one Kafka cluster.</p>

<p>Cross-cluster disaster recovery is where things become more interesting.</p>

<h2 id="cross-cluster-recovery-requires-offset-translation">Cross-Cluster Recovery Requires Offset Translation</h2>

<p>Suppose we have two Amazon MSK clusters:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Primary Region
    ↓
MSK Replicator
    ↓
DR Region
</code></pre></div></div>

<p>MSK Replicator does not copy the source partition log byte for byte. It replicates records into the target cluster and maintains mappings between source and target offsets.<sup id="fnref:msk-offset-sync"><a href="#fn:msk-offset-sync" class="footnote" rel="footnote" role="doc-noteref">7</a></sup></p>

<p>The same logical record can therefore have different offsets:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Primary cluster

payments
partition 3
offset 10000
</code></pre></div></div>

<p>and:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>DR cluster

payments
partition 3
offset 9873
</code></pre></div></div>

<p>In general:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>source offset != target offset
</code></pre></div></div>

<p>So simply copying a consumer group’s numerical offset into the DR cluster would be unsafe.</p>

<p>Amazon MSK Replicator instead synchronizes consumer group progress by translating source offsets into corresponding target offsets. It periodically records mappings between the two offset spaces, reads committed consumer group offsets from the source, translates them, and commits the translated positions into the target cluster’s <code class="language-plaintext highlighter-rouge">__consumer_offsets</code> topic.<sup id="fnref:msk-offset-sync:1"><a href="#fn:msk-offset-sync" class="footnote" rel="footnote" role="doc-noteref">7</a></sup></p>

<p>Conceptually:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Source                    Target

1000    ───────────────→   872
1100    ───────────────→   971
1200    ───────────────→  1074
</code></pre></div></div>

<p>A source checkpoint such as:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>group: payment-processor
topic: payments
partition: 3
committed offset: 10001
</code></pre></div></div>

<p>might therefore become:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>group: payment-processor
topic: payments
partition: 3
committed offset: 9874
</code></pre></div></div>

<p>in the DR cluster.</p>

<p>When the same consumer group starts against DR, it can resume near the equivalent point in the replicated stream.<sup id="fnref:msk-offset-sync:2"><a href="#fn:msk-offset-sync" class="footnote" rel="footnote" role="doc-noteref">7</a></sup></p>

<p>That is a significant DR capability. Amazon MSK is not only replicating records; it can also migrate consumer progress.</p>

<p>There is an important operational constraint. MSK Replicator does not overwrite synchronized offsets for a consumer group that is already active on the target cluster.<sup id="fnref:msk-offset-sync:3"><a href="#fn:msk-offset-sync" class="footnote" rel="footnote" role="doc-noteref">7</a></sup> The failover procedure therefore has to coordinate consumer activation with offset synchronization.</p>

<p>The translation is also deliberately approximate.</p>

<p>MSK Replicator records offset mappings periodically rather than maintaining an exact mapping for every record. AWS therefore prefers a translated position that may cause some records to be replayed rather than one that risks skipping records.<sup id="fnref:msk-offset-sync:4"><a href="#fn:msk-offset-sync" class="footnote" rel="footnote" role="doc-noteref">7</a></sup></p>

<p>For example, a source consumer may have progressed through:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>10000
</code></pre></div></div>

<p>while the safest translated DR position corresponds to:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>9997
</code></pre></div></div>

<p>After failover, the consumer may see the equivalents of <code class="language-plaintext highlighter-rouge">9997</code>, <code class="language-plaintext highlighter-rouge">9998</code>, <code class="language-plaintext highlighter-rouge">9999</code>, and <code class="language-plaintext highlighter-rouge">10000</code> again.</p>

<p>That is at-least-once behavior, and AWS recommends that consumers tolerate duplicate processing.<sup id="fnref:msk-migration"><a href="#fn:msk-migration" class="footnote" rel="footnote" role="doc-noteref">8</a></sup></p>

<h2 id="recovery-position-is-not-event-identity">Recovery Position Is Not Event Identity</h2>

<p>Now consider one of those records:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"eventId"</span><span class="p">:</span><span class="w"> </span><span class="s2">"01KABC..."</span><span class="p">,</span><span class="w">
  </span><span class="nl">"eventType"</span><span class="p">:</span><span class="w"> </span><span class="s2">"PaymentCompleted"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"paymentId"</span><span class="p">:</span><span class="w"> </span><span class="s2">"P12345"</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>It may exist as:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Primary: payments-3 @ 10000
DR:      payments-3 @ 9873
</code></pre></div></div>

<p>MSK Replicator can translate between those offset spaces well enough to recover the consumer group’s position.</p>

<p>But neither offset intrinsically identifies the logical payment event.</p>

<p>That identity comes from the event contract through something such as <code class="language-plaintext highlighter-rouge">eventId</code> or another stable idempotency key.</p>

<p>This matters when the event has effects outside Kafka.</p>

<p>Suppose <code class="language-plaintext highlighter-rouge">payment-processor</code> consumes <code class="language-plaintext highlighter-rouge">01KABC</code> and updates a downstream database. The consumer commits its progress, but before the corresponding checkpoint has fully propagated to DR, the primary Region fails.</p>

<p>The event has reached DR, but the synchronized consumer position is slightly behind.</p>

<p>After failover, <code class="language-plaintext highlighter-rouge">payment-processor</code> sees <code class="language-plaintext highlighter-rouge">01KABC</code> again.</p>

<p>Nothing necessarily failed in Kafka or MSK Replicator. The recovery mechanism deliberately resumed from a safe position that avoided skipping records.</p>

<p>The application now has to answer a different question:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Have I already applied event 01KABC?
</code></pre></div></div>

<p>The Kafka offset cannot answer that across arbitrary external side effects.</p>

<p>A stable event identity or idempotency mechanism can.</p>

<p>That is why position and identity are complementary rather than interchangeable:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Position
    → where should I continue?

Identity
    → have I already processed this logical thing?
</code></pre></div></div>

<p>Kafka should not replace offsets with event identifiers. Position is what makes ordered log consumption efficient. Identity becomes important when location and execution history diverge.</p>

<p>Robust recovery often needs both.</p>

<h2 id="what-rpo--0-actually-means">What RPO = 0 Actually Means</h2>

<p>This distinction also changes how I think about statements such as:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>RPO = 0
</code></pre></div></div>

<p>An RPO of zero means that no state the platform considers successfully committed before the failure may be lost.</p>

<p>For Kafka event data, that means every record acknowledged as successfully committed by the primary platform must still be recoverable after the disaster.</p>

<p>This exposes an important limitation of asynchronous cross-Region replication.</p>

<p>Amazon MSK Replicator copies records asynchronously.<sup id="fnref:msk-replicator"><a href="#fn:msk-replicator" class="footnote" rel="footnote" role="doc-noteref">9</a></sup> A producer can therefore receive an acknowledgement from the primary cluster before that record reaches the DR cluster.</p>

<p>If the primary Region becomes unrecoverable during that interval, strict cross-Region event-data RPO zero cannot be guaranteed by that asynchronous replication path.</p>

<p>A metric such as <code class="language-plaintext highlighter-rouge">MessageLag = 0</code> tells us that replication has caught up at that point in time. It does not eliminate the replication window for subsequent records.<sup id="fnref:msk-monitoring"><a href="#fn:msk-monitoring" class="footnote" rel="footnote" role="doc-noteref">10</a></sup></p>

<p>It is also important not to confuse three different recovery concerns:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Event missing from DR
    → data loss
    → RPO concern

Consumer checkpoint behind
    → replay
    → recovery-position concern

Business effect repeated
    → duplicate operation
    → application correctness concern
</code></pre></div></div>

<p>A DR cluster can contain every replicated Kafka record while its synchronized consumer position is slightly behind.</p>

<p>The result is replay, not necessarily data loss.</p>

<p>So:</p>

<blockquote>
  <p>Replay is not data loss. Consumer-offset lag does not by itself violate the Kafka event-data RPO.</p>
</blockquote>

<p>Whether that replay is harmless depends on the consumer application’s idempotency guarantees.</p>

<h2 id="what-the-mysql-change-made-me-think-about">What the MySQL Change Made Me Think About</h2>

<p>The recent MySQL change did not introduce GTIDs. What caught my attention was that its newer Change Stream Applier requires GTID-based replication while explicitly leaving file-position replication channels behind.<sup id="fnref:mysql-csa:1"><a href="#fn:mysql-csa" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<p>That reinforces a broader recovery principle:</p>

<blockquote>
  <p>Recovery becomes easier when the thing being recovered has an identity independent of the location where it happened to be stored.</p>
</blockquote>

<p>Kafka demonstrates why both identity and position matter.</p>

<p>Within one Kafka cluster, physical broker placement is hidden behind the topic-partition-offset abstraction.</p>

<p>Across clusters, the destination has its own log and its own offsets, so consumer progress has to be translated.</p>

<p>And once replay enters the picture, application-level identity becomes important because the system may need to recognize a logical event whose effects have already occurred.</p>

<p>For Kafka DR, I now think about recovery in layers:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Did the event survive?

Did the consumer's progress survive?

Can that progress be translated into the DR log?

If some events are replayed,
can the application recognize them?

If an event is recognized,
can its side effects safely be repeated or suppressed?
</code></pre></div></div>

<p>The first questions belong largely to the streaming platform.</p>

<p>The final questions increasingly belong to the consumer application.</p>

<p>Which leaves me with the question that the MySQL change originally triggered:</p>

<blockquote>
  <p>Does this checkpoint identify the state I processed, or merely where I should resume looking for it?</p>
</blockquote>

<hr />
<p>NOTE: From this post onward, I am going to tag the post where I used AI assitance for anything - review, dedupe, etc. I am honestly not waiting for humans to review and then publish. ChatGPT essentially has removed the review barrier and I am getting much better reviews than before. When I asked ChatGPT to score my intitial draft, it scored it 6/10 and suggested improvements. After improvements it says it is 8/10. I will take it. :)</p>

<hr />

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:mysql-csa">
      <p>Oracle, “Changes in MySQL 26.7.0 (2026-07-28),” <em>MySQL 26.7 Release Notes</em>. The release introduces the Change Stream Applier and lists file-position replication channels, GTID modes other than <code class="language-plaintext highlighter-rouge">ON</code>, and <code class="language-plaintext highlighter-rouge">GTID_ONLY=0</code> among unsupported configurations. <a href="https://dev.mysql.com/doc/relnotes/mysql/26.7/en/news-26-7-0.html">https://dev.mysql.com/doc/relnotes/mysql/26.7/en/news-26-7-0.html</a> <a href="#fnref:mysql-csa" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:mysql-csa:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:mysql-gtid">
      <p>Oracle, “GTID Format and Storage,” <em>MySQL Reference Manual</em>. MySQL defines a GTID as a unique identifier associated with a transaction committed on its originating server and states that replicated transactions retain the same GTID. <a href="https://dev.mysql.com/doc/refman/9.1/en/replication-gtids-concepts.html">https://dev.mysql.com/doc/refman/9.1/en/replication-gtids-concepts.html</a> <a href="#fnref:mysql-gtid" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:mysql-gtid-failover">
      <p>Oracle, “Replication with Global Transaction Identifiers,” <em>MySQL Reference Manual</em>. MySQL documents that GTID-based replication removes the need to refer to binary log files and positions when starting a replica or failing over to a new source. <a href="https://dev.mysql.com/doc/refman/9.4/en/replication-gtids.html">https://dev.mysql.com/doc/refman/9.4/en/replication-gtids.html</a> <a href="#fnref:mysql-gtid-failover" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:kafka-replication">
      <p>Apache Kafka, “Replication,” <em>Kafka Design Documentation</em>. Kafka partitions are replicated across brokers, with one replica acting as leader and other replicas able to take over leadership. <a href="https://kafka.apache.org/documentation/#replication">https://kafka.apache.org/documentation/#replication</a> <a href="#fnref:kafka-replication" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:kafka-offset-storage">
      <p>Apache Kafka, “Consumer Offset Tracking,” <em>Kafka Implementation Documentation</em>. Kafka documents that consumer offsets are maintained for consumer groups and that offset commits are stored in the compacted <code class="language-plaintext highlighter-rouge">__consumer_offsets</code> topic. <a href="https://kafka.apache.org/42/implementation/distribution/">https://kafka.apache.org/42/implementation/distribution/</a> <a href="#fnref:kafka-offset-storage" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:kafka-commit-semantics">
      <p>Apache Kafka, <code class="language-plaintext highlighter-rouge">KafkaConsumer</code> API documentation. The consumer API specifies that a committed offset should identify the next record to be processed rather than the offset of the record just processed. <a href="https://kafka.apache.org/42/javadoc/org/apache/kafka/clients/consumer/KafkaConsumer.html">https://kafka.apache.org/42/javadoc/org/apache/kafka/clients/consumer/KafkaConsumer.html</a> <a href="#fnref:kafka-commit-semantics" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:msk-offset-sync">
      <p>Amazon Web Services, “Consumer group offset synchronization,” <em>Amazon MSK Developer Guide</em>. AWS documents source-to-target offset mapping, translation of consumer group offsets, target offset commits, approximate translation, and restrictions when the target consumer group is active. <a href="https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator-bidirectional-offset-sync.html">https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator-bidirectional-offset-sync.html</a> <a href="#fnref:msk-offset-sync" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:msk-offset-sync:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a> <a href="#fnref:msk-offset-sync:2" class="reversefootnote" role="doc-backlink">&#8617;<sup>3</sup></a> <a href="#fnref:msk-offset-sync:3" class="reversefootnote" role="doc-backlink">&#8617;<sup>4</sup></a> <a href="#fnref:msk-offset-sync:4" class="reversefootnote" role="doc-backlink">&#8617;<sup>5</sup></a></p>
    </li>
    <li id="fn:msk-migration">
      <p>Amazon Web Services, “Migrate between Amazon MSK clusters,” <em>Amazon MSK Developer Guide</em>. AWS notes the at-least-once characteristics of replication and recommends consumers be able to handle duplicate messages. <a href="https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator-migrate-cluster.html">https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator-migrate-cluster.html</a> <a href="#fnref:msk-migration" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:msk-replicator">
      <p>Amazon Web Services, “What is Amazon MSK Replicator?” <em>Amazon MSK Developer Guide</em>. AWS describes MSK Replicator as an asynchronous replication capability for Amazon MSK clusters. <a href="https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator.html">https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator.html</a> <a href="#fnref:msk-replicator" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:msk-monitoring">
      <p>Amazon Web Services, “Monitor an MSK Replicator,” <em>Amazon MSK Developer Guide</em>. AWS exposes metrics for replication lag and consumer group offset synchronization. <a href="https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator-monitor.html">https://docs.aws.amazon.com/msk/latest/developerguide/msk-replicator-monitor.html</a> <a href="#fnref:msk-monitoring" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Software Engineering" /><category term="MySQL" /><category term="Kafka" /><category term="Amazon MSK" /><category term="Distributed Systems" /><category term="Disaster Recovery" /><category term="Event Streaming" /><category term="AI-assisted" /><summary type="html"><![CDATA[A recent MySQL replication change made me reconsider a question from Kafka disaster recovery: does a checkpoint identify what was processed, or merely where processing should resume?]]></summary></entry><entry><title type="html">Resource Integrity Belongs to the Resource, Not the API</title><link href="https://systemhalted.in/2026/08/25/resource-integrity/" rel="alternate" type="text/html" title="Resource Integrity Belongs to the Resource, Not the API" /><published>2026-08-25T00:00:00+00:00</published><updated>2026-08-25T00:00:00+00:00</updated><id>https://systemhalted.in/2026/08/25/resource-integrity</id><content type="html" xml:base="https://systemhalted.in/2026/08/25/resource-integrity/"><![CDATA[<p>Let’s assume that a platform exposes a REST API for creating and managing resources. Over time, the platform team also builds administrative scripts, migration utilities, recovery procedures, scheduled jobs, and internal operational tools.</p>

<p>These tools may not call the REST API. Sometimes that is reasonable. A recovery utility may need to work when the API is unavailable. A migration may require capabilities intentionally excluded from the public interface. An operator may need to repair partially provisioned infrastructure.</p>

<p>But bypassing the API must not mean bypassing the resource contract.</p>

<p>The governing principle is simple:</p>

<blockquote>
  <p>Resource integrity belongs to the resource, not to the API.</p>
</blockquote>

<p>Every mechanism that creates, changes, or deletes a platform-owned resource must preserve the same resource identity, lifecycle rules, domain invariants, and required side effects. This remains true whether the operation originates from a REST endpoint, an administrative tool, an automation job, a migration, or a recovery procedure.</p>

<h2 id="rest-does-not-own-the-resource">REST Does Not Own the Resource</h2>

<p>REST stands for <strong>Representational State Transfer</strong>. Its uniform-interface constraints include identifying resources and manipulating them through representations.<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> A resource has an identity, commonly exposed through a URI, and a client exchanges representations of its state.<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>Consider a Kafka topic managed by an event-streaming platform:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/topics/customer-events
</code></pre></div></div>

<p>The topic is the resource. The following JSON is one representation of its current state:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"name"</span><span class="p">:</span><span class="w"> </span><span class="s2">"customer-events"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"partitions"</span><span class="p">:</span><span class="w"> </span><span class="mi">12</span><span class="p">,</span><span class="w">
  </span><span class="nl">"retentionHours"</span><span class="p">:</span><span class="w"> </span><span class="mi">168</span><span class="p">,</span><span class="w">
  </span><span class="nl">"status"</span><span class="p">:</span><span class="w"> </span><span class="s2">"ACTIVE"</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>Changing <code class="language-plaintext highlighter-rouge">retentionHours</code> does not necessarily create a new resource. The resource retains its identity while its state changes.</p>

<p>I know many architects and engineers think of the REST endpoint as the resource unto itself, and at one point I was one of them. My reasoning was simple, the resource should have one identity, and anything that needs to interact with the resource should interact through that single identity. I once treated the API path as the resource’s canonical identity and concluded that every mutation had to pass through it. That conflated the resource with one interface used to reach it.</p>

<p>Of late, I have come to realize that the REST endpoint is not the resource. Nor is it a representation of the resource. The URI identifies the target resource, while the request and response payloads carry representations of its current or intended state. The API is the interaction boundary through which clients act upon that resource. The database row is not necessarily the resource either. Nor is the corresponding Kafka topic by itself. Within the platform’s control-plane model, the managed-topic resource is not necessarily identical to the physical Kafka topic. It may be a higher-level entity encompassing desired configuration, ownership, policies, provisioned infrastructure, lifecycle state, and audit history.</p>

<p>If the API disappears temporarily, the resource does not stop existing. If a tool avoids the API, it does not gain the right to redefine what constitutes a valid resource.</p>

<h2 id="a-resource-is-more-than-stored-state">A Resource Is More Than Stored State</h2>

<p>Suppose the platform’s topic-creation API performs the following work:</p>

<ol>
  <li>Validates the topic name and configuration.</li>
  <li>Confirms that the caller is authorized for the owning domain.</li>
  <li>Prevents duplicate creation through idempotency controls.</li>
  <li>Provisions the physical topic in MSK.</li>
  <li>Applies retention, encryption, and access policies.</li>
  <li>Stores the platform’s metadata.</li>
  <li>Publishes a lifecycle event.</li>
  <li>Records an auditable history of the operation.</li>
</ol>

<p>An administrative script that inserts a row directly into the metadata database has not necessarily created the same resource. It may only have created the appearance of one.</p>

<p>The platform could now report that the topic exists even though the physical topic was never provisioned. Alternatively, the physical topic might exist without the correct policies, ownership information, or audit record. Each subsystem may be locally correct while the platform resource is globally inconsistent. This is a recurring distributed-systems problem: coordinating state across multiple components introduces partial-failure and consistency concerns that cannot be reduced to one database write.<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>That is the danger of treating the API implementation as the only place where integrity matters. Validation, authorization, provisioning, event publication, and auditing are not incidental HTTP behavior. They are parts of the resource’s lifecycle.</p>

<h2 id="state-changes-invariants-must-hold">State Changes; Invariants Must Hold</h2>

<p>The resource’s state must remain pristine in the sense that its <strong>integrity</strong> remains valid.</p>

<p>State is expected to change. A topic can move from <code class="language-plaintext highlighter-rouge">PROVISIONING</code> to <code class="language-plaintext highlighter-rouge">ACTIVE</code>, its retention period can be updated, and it may eventually move to <code class="language-plaintext highlighter-rouge">DELETING</code> and <code class="language-plaintext highlighter-rouge">DELETED</code>. The requirement is not to keep the original state untouched. The requirement is to ensure that every transition leaves the resource in a valid and internally consistent condition.</p>

<p>For a platform-managed topic, the invariants might include:</p>

<ul>
  <li>A globally unique and stable resource identifier exists.</li>
  <li>The resource always has an accountable owner.</li>
  <li>Platform metadata corresponds to the provisioned infrastructure.</li>
  <li>Security and retention policies conform to platform rules.</li>
  <li>Lifecycle transitions follow an allowed state machine.</li>
  <li>Concurrent changes cannot silently overwrite each other.</li>
  <li>Material changes are authorized and auditable.</li>
  <li>Required events are published exactly as promised by the platform contract.</li>
</ul>

<p>These invariants apply to all mutation paths. The origin of a command does not alter the definition of a valid topic. In domain-driven terms, invariants belong inside the model boundary that controls valid state transitions, not exclusively inside one delivery mechanism.<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> Every mutation path must preserve the resource’s identity and domain invariants while honoring the applicable transition guards, audit requirements, side-effect obligations, and recovery guarantees.</p>

<h2 id="the-api-should-be-an-adapter-not-the-domain">The API Should Be an Adapter, Not the Domain</h2>

<p>A robust design does not force every internal actor to communicate over HTTP merely to reuse business rules. Instead, it separates the REST adapter from the application operations that govern the resource. This follows the Ports and Adapters model, in which HTTP, batch processes, tests, and other programs can drive the application through different adapters without moving the application rules into those adapters.<sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>REST API ───────────┐
Admin CLI ──────────┤
Scheduled job ──────┼──&gt; Application command ──&gt; Domain rules and lifecycle
Migration utility ──┤
Recovery workflow ──┘
</code></pre></div></div>

<p>The REST controller translates an HTTP request into an application command. An administrative CLI may translate operator input into the same command. A scheduled reconciliation job may invoke a related command with a different authorization context. The interfaces differ, but the resource rules remain centralized and consistent.</p>

<p>This does not imply that every tool must execute precisely the same workflow. Operational tools sometimes need privileged operations. A migration may intentionally suppress a notification. A repair tool may reconstruct missing metadata from the physical infrastructure. A disaster-recovery process may operate while dependent systems are unavailable.</p>

<p>Those differences should be explicit parts of the operational contract, not accidental consequences of writing directly to storage. A privileged operation still needs defined preconditions, postconditions, authorization, auditability, and reconciliation behavior.</p>

<h2 id="direct-changes-are-break-glass-operations">Direct Changes Are Break-Glass Operations</h2>

<p>There will be situations where neither the API nor the normal application command path is usable. Direct database or infrastructure changes may then be necessary.</p>

<p>Such changes should be treated as break-glass operations rather than ordinary administration. The need for authorized changes, configuration-change control, and audit-record generation is also reflected in NIST’s security-control catalog <sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup>. At minimum, the procedure should define:</p>

<ul>
  <li>Who may authorize and execute the change.</li>
  <li>Which invariants may be temporarily violated.</li>
  <li>How the original and resulting states are recorded.</li>
  <li>How dependent state and lifecycle events are repaired.</li>
  <li>How the platform verifies convergence afterward.</li>
  <li>How the operation is made safe to retry or reverse.</li>
</ul>

<p>The distinction is important. An emergency exception does not invalidate the resource contract. It creates an obligation to restore it.</p>

<h2 id="what-this-means-for-platform-teams">What This Means for Platform Teams</h2>

<p>When reviewing an operational tool, asking whether it uses the REST API is useful but insufficient. The better questions are:</p>

<ol>
  <li>Does it operate on the same resource identity?</li>
  <li>Does it enforce the same domain invariants?</li>
  <li>Does it respect the lifecycle state machine?</li>
  <li>Does it reproduce or deliberately account for required side effects?</li>
  <li>Does it preserve authorization, concurrency control, and auditability?</li>
  <li>Can the platform detect and reconcile partial failure?</li>
</ol>

<p>This framing also clarifies ownership. If a team owns the platform resource, it owns more than the public API. It owns the meaning and integrity of that resource across every supported way it can be changed.</p>

<h2 id="the-principle">The Principle</h2>

<p>A REST API is an interaction boundary through which representations are exchanged. It is not the sole guardian of the underlying resource.</p>

<p>Operational tools may legitimately use a different interface. They may require elevated capabilities, alternate workflows, or direct access during exceptional circumstances. But a different mutation path does not create a different definition of the resource.</p>

<p>The architectural rule is therefore:</p>

<blockquote>
  <p>Bypassing the API is sometimes necessary. Bypassing the resource contract is not.</p>
</blockquote>

<p>When this rule is applied consistently, administrative tools stop being dangerous collections of privileged shortcuts. They become deliberate participants in the platform’s resource lifecycle.</p>

<hr />

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Roy T. Fielding, <a href="https://ics.uci.edu/~fielding/pubs/dissertation/rest_arch_style.htm">“Representational State Transfer (REST),” Chapter 5 of <em>Architectural Styles and the Design of Network-based Software Architectures</em></a>, 2000, especially Sections 5.1.5 and 5.2.1. See also Roy T. Fielding and Richard N. Taylor, <a href="https://doi.org/10.1145/514183.514185">“Principled Design of the Modern Web Architecture”</a>, <em>ACM Transactions on Internet Technology</em> 2, no. 2 (2002): 115–150. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>IETF, <a href="https://www.rfc-editor.org/rfc/rfc9110.html">RFC 9110: <em>HTTP Semantics</em></a>, 2022, Sections 3.1 and 3.2. The standard distinguishes a resource from a representation reflecting its past, current, or desired state. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>Martin Kleppmann, <em>Designing Data-Intensive Applications</em> (O’Reilly Media, 2017), particularly the discussions of distributed transactions, partial failure, and consistency. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>Eric Evans, <em>Domain-Driven Design: Tackling Complexity in the Heart of Software</em> (Addison-Wesley, 2003), particularly the treatment of entities, aggregates, and invariants. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>Alistair Cockburn, <a href="https://alistair.cockburn.us/hexagonal-architecture">“Hexagonal Architecture: The Original 2005 Article”</a>, 2005. Cockburn describes application ports driven by users, HTTP interfaces, batch scripts, automated tests, or other programs through different adapters. <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:6">
      <p>NIST, <a href="https://csrc.nist.gov/pubs/sp/800/53/r5/upd1/final"><em>Security and Privacy Controls for Information Systems and Organizations</em>, SP 800-53 Rev. 5</a>, 2020, particularly CM-3 (Configuration Change Control), CM-5 (Access Restrictions for Change), and AU-12 (Audit Record Generation). <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Software Engineering" /><category term="REST" /><category term="API Design" /><category term="Platform Engineering" /><category term="Domain-Driven Design" /><category term="Operational Tooling" /><summary type="html"><![CDATA[An operational tool may bypass a REST endpoint, but it must not bypass the resource contract.]]></summary></entry><entry><title type="html">AI Governance Needs Accountability, Not Just Principles</title><link href="https://systemhalted.in/2026/08/21/ai-governance-needs-accountability-not-just-principles/" rel="alternate" type="text/html" title="AI Governance Needs Accountability, Not Just Principles" /><published>2026-08-21T00:00:00+00:00</published><updated>2026-08-21T00:00:00+00:00</updated><id>https://systemhalted.in/2026/08/21/ai-governance-needs-accountability-not-just-principles</id><content type="html" xml:base="https://systemhalted.in/2026/08/21/ai-governance-needs-accountability-not-just-principles/"><![CDATA[<p>AI ethics principles are easy to write and difficult to enforce.</p>

<p>The gap between stating a principle and enforcing it matters more than the wording of the principle. A company can say it values fairness, transparency, accountability, privacy, and human oversight, and it may mean it. But without clearly assigned responsibilities, meaningful accountability, mechanisms to test behavior, and consequences for failure, those statements do not constrain what the company does.</p>

<p>AI makes this problem harder for software. Traditional models of professional responsibility do not fit the way software is built. A doctor can be held responsible for a diagnosis because the decision is usually attributable to the doctor. Software rarely works that way. A product decision, data choice, architecture tradeoff, model behavior, design constraint, release deadline, and legal interpretation all combine before the system reaches a user.</p>

<p>So when an AI system harms someone, the question is not only who wrote the code. It is also:</p>

<ul>
  <li>Who specified the behavior?</li>
  <li>Who selected the training and evaluation data?</li>
  <li>Who accepted the product risk?</li>
  <li>Who decided the human review was sufficient?</li>
  <li>Who monitored failures after release?</li>
  <li>Who had the power to stop deployment?</li>
</ul>

<h2 id="professionalism-is-not-enough">Professionalism is not enough</h2>

<p>One proposed answer is to treat <a href="/2026/07/21/review-software-malpractice-in-the-age-of-ai/">software engineers more like licensed professionals</a>. The idea has some merit. Software systems now shape medicine, finance, transport, hiring, speech, policing, and public administration. The people who build them often have less formal accountability than practitioners in older professions whose mistakes affect fewer people.</p>

<p>However, software is rarely produced by a single professional exercising independent judgment. The engineer may understand the technical risk but lack authority over the business requirement. The product leader may own the user experience but not understand what causes the model to fail. The data team may know the bias in the dataset but not own the release decision. The legal team may approve a disclaimer that is formally defensible but of little practical use to users.</p>

<p>Licensing individual engineers would not solve that allocation problem on its own. It may raise the baseline of competence, and it may give engineers a stronger basis for refusing reckless work, but AI responsibility has to be assigned at the system level. Accountability has to include the organization, not just the coder.</p>

<h2 id="soft-law-needs-enforcement">Soft law needs enforcement</h2>

<p>That is why proposals for AI governance bodies are worth taking seriously. A <a href="/2026/07/31/review-agile-ethical-legal-model-ai-robotics-governance/">global or international coordinating body</a> for AI and robotics would not solve enforcement on its own. It could help coordinate existing forms of soft law: professional guidelines, research norms, insurance requirements, audit expectations, procurement rules, and sector specific regulation.</p>

<p>This matters because AI systems cross borders more easily than laws do. The GDPR gives people enforceable rights within the European Union, but many AI harms do not stay in one jurisdiction. A model may be trained in one country, deployed by a company in another, served through infrastructure in a third, and used on people who live everywhere.</p>

<p>Without institutions that connect principles to incentives, companies comply where enforcement exists and treat the rest as optional.</p>

<p>The useful governance question is therefore not what AI should value. It is which institutions can attach real costs to ignoring those values.</p>

<h2 id="collective-intelligence-has-limits">Collective intelligence has limits</h2>

<p>Governance is not only about assigning responsibility after a failure. It is also about ensuring that the decision-making processes themselves remain reliable.</p>

<p>Collective intelligence adds another complication. <a href="/2026/08/09/review-studying-wisdom-of-crowds-at-scale/">Crowds can outperform individuals</a>. Aggregated judgment can be more accurate and more stable than the judgment of any one participant. This holds in markets, elections, forecasts, open-source communities, and scientific review.</p>

<p>But crowds also herd. Social influence can make a group less accurate when people stop contributing independent judgment and start copying visible signals. Once that happens, the group amplifies a shared signal instead of aggregating independent ones.</p>

<p>This matters because many AI systems operate through feedback loops. Users rate content, models learn from users, recommender systems shape what users see, users respond to what was recommended, and the next version of the system absorbs the pattern. The crowd is part of the system rather than an external check on it.</p>

<p>So the question is not whether collective intelligence is good or bad. It is whether the system preserves enough independent signal for aggregation to work, and whether it can detect when influence has collapsed into herding.</p>

<h2 id="technology-reveals-rights">Technology reveals rights</h2>

<p>Technology also changes which rights become practically important.</p>

<p>The right to be forgotten, the right to public anonymity, and the right to disconnect are useful examples. These rights did not become meaningful because human interests changed. People always had interests in privacy, dignity, rest, and control over reputation. What changed was the power technology put in others’ hands.</p>

<p>Search engines, social media, facial recognition, cheap storage, workplace messaging, and always-on devices shifted that power. One person, company, or state can now remember, locate, classify, and interrupt another person at a scale that older social norms were not built to handle. The underlying interest existed earlier, but the corresponding duty became visible only when technology made the imbalance large enough to matter.</p>

<p>That is the argument for treating some rights as <a href="/2026/08/02/review-how-technological-advances-can-reveal-rights/">“revealed”</a> by technology. These interests are not new; however, the imbalance of power that makes them urgent certainly is.</p>

<h2 id="the-actual-work">The actual work</h2>

<p>AI governance will not be solved by choosing between ethics, law, or engineering. It needs all three.</p>

<p>Engineering provides evaluation, testing, audits, monitoring, incident response, system design, and evidence.. Law provides duties, remedies, procedures, and consequences. Ethics provides a way to describe what is at stake before the law addresses it.</p>

<p>The practical work is to connect them:</p>

<ul>
  <li>Turn principles into concrete release criteria by requiring model cards, evaluation reports, deployment gates, rollback procedures, and incident reviews before and after release.</li>
  <li>Treat datasets, prompts, models, and evaluations as governed artifacts.</li>
  <li>Make responsibility traceable across product, engineering, data, legal, and leadership.</li>
  <li>Preserve independent human judgment where collective intelligence is being used.</li>
  <li>Recognize new technological rights before harm becomes normalized.</li>
  <li>Build institutions that make serious AI failures visible, attributable, and costly.</li>
</ul>

<p>The test of AI governance is not whether an organization can write a responsible AI policy. It is whether, when the system fails, the organization can identify who was responsible for assessing the risk and whether that person had the authority to act on it. An organization that cannot answer has a policy, not governance.</p>

<h2 id="references">References</h2>

<p>Danny Tobey, “Software Malpractice in the Age of AI: A Guide for the Wary Tech Company”, AIES 2018.</p>

<p>Wendell Wallach and Gary E. Marchant, “An Agile Ethical/Legal Model for the International and National Governance of AI and Robotics”, AIES 2018.</p>

<p>Camelia Simoiu, Chiraag Sumanth, Alok Mysore, and Sharad Goel, “Studying the Wisdom of Crowds at Scale”, HCOMP 2019.</p>

<p>Jack Parker and David Danks, “How Technological Advances Can Reveal Rights”, AIES 2019.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="AI" /><category term="Politics &amp; Governance" /><category term="ai" /><category term="law" /><category term="technology" /><category term="software" /><category term="opinion" /><summary type="html"><![CDATA[On AI ethics, software responsibility, collective intelligence, and why new technological rights need institutions that can actually enforce them.]]></summary></entry><entry><title type="html">AI in People Management</title><link href="https://systemhalted.in/2026/08/18/ai-in-people-management/" rel="alternate" type="text/html" title="AI in People Management" /><published>2026-08-18T00:00:00+00:00</published><updated>2026-08-18T00:00:00+00:00</updated><id>https://systemhalted.in/2026/08/18/ai-in-people-management</id><content type="html" xml:base="https://systemhalted.in/2026/08/18/ai-in-people-management/"><![CDATA[<p>In people management, most of the functions where AI is used, such as hiring, performance, engagement, learning, communication, well-being, and analytics, involve judgments about people. That is where automation can save the most effort and also where it can do the most harm.</p>

<p>I want to set out where I think AI genuinely helps, and where it should stay in a supporting role.</p>

<h2 id="where-it-helps">Where it helps</h2>

<p><strong>Hiring.</strong> Applicant tracking systems can sort, deduplicate, and surface candidates far faster than a person reading every resume. Used carefully, that saves time and removes some of the arbitrary noise in early screening. The caveat is that a model trained on past hiring decisions will also learn past hiring bias. A screening tool needs to be checked for the patterns it is reproducing, because a faster process is not automatically a fairer one.</p>

<p><strong>Performance.</strong> Continuous feedback and progress tracking are easier to sustain when a system collects the signals instead of a manager reconstructing them once a year. This can make reviews less dependent on memory and recency. The risk is that the numbers a system can measure become the numbers people manage toward, even when the important part of the work is harder to quantify.</p>

<p><strong>Engagement and retention.</strong> Sentiment analysis over surveys and feedback can help HR notice problems earlier, and attrition models can flag teams where people are likely to leave. This is useful as an early warning. It also shades quickly into surveillance if employees do not know what is being analyzed, so consent and transparency are not optional here.</p>

<p><strong>Learning and development.</strong> Recommending training based on a person’s role, history, and stated goals is one of the lower-risk uses. It helps people find relevant material without much downside, as long as the recommendations stay suggestions rather than mandates.</p>

<p><strong>Communication.</strong> Chatbots that answer routine policy and benefits questions take repetitive lookups off HR staff and give employees faster answers. This works well when the tool is scoped to retrieving information, and less well when it is asked to handle situations that need a person.</p>

<p><strong>Well-being.</strong> Some tools try to infer stress or burnout from communication patterns. This is the most sensitive use on the list. It touches private information and can feel like monitoring even when the intent is supportive. If it is used at all, it should be opt-in, clearly explained, and kept away from anything that affects evaluation.</p>

<p><strong>Analytics.</strong> Workforce planning, skills-gap analysis, and trend spotting are genuinely helped by aggregation. AI can show patterns across a large organization that no individual manager would see. These are inputs to decisions that people still make.</p>

<h2 id="where-human-judgment-has-to-stay">Where human judgment has to stay</h2>

<p>AI in people management operates on data about people, and people respond to how they are measured. Once employees understand what a system rewards, some will manage toward the signal rather than the work. A metric that looked objective can quietly become a target.</p>

<p>The decisions here also carry moral weight. Who gets hired, promoted, flagged, or let go affects a person’s livelihood. Those outcomes should not be handed to a system that is optimizing a proxy for something it cannot directly measure. A model can inform such a decision, but it should not be the thing that makes it.</p>

<p>My rule is to use AI to widen what a manager can see, not to replace the manager’s judgment. Keep a person accountable for any outcome that changes someone’s job, pay, or standing, and make sure that person can explain the decision without pointing at a score.</p>

<h2 id="closing">Closing</h2>

<p>AI is worth adopting where it reduces drudgery and improves visibility. But the judgments that matter most in people management are the ones where a person should remain responsible. The useful way to bring AI into this work is to let it handle the volume and keep humans in the decisions that carry consequences for other humans.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="AI" /><category term="ai" /><category term="people-management" /><category term="hr" /><category term="technology" /><category term="opinion" /><summary type="html"><![CDATA[A measured look at where AI genuinely helps in people management, and where human judgment has to stay in the loop.]]></summary></entry><entry><title type="html">Free Will, AI, and the Limits of Intentionality</title><link href="https://systemhalted.in/2026/08/11/free-will-ai-and-the-limits-of-intentionality/" rel="alternate" type="text/html" title="Free Will, AI, and the Limits of Intentionality" /><published>2026-08-11T00:00:00+00:00</published><updated>2026-08-11T00:00:00+00:00</updated><id>https://systemhalted.in/2026/08/11/free-will-ai-and-the-limits-of-intentionality</id><content type="html" xml:base="https://systemhalted.in/2026/08/11/free-will-ai-and-the-limits-of-intentionality/"><![CDATA[<p>Free will is usually discussed as if it is only a question of freedom from external control. That is part of it, but not the whole thing. I explored this in an <a href="/2020/04/05/free-will/">earlier post</a>, which I wrote as part of my OMSCS coursework</p>

<p>To have free will, a being must be able to act according to its own intent. It must not only choose, but choose in a way that is meaningfully self-determined. That makes intentionality central. A choice without intent is not really free will.</p>

<p>From a Hindu perspective, this distinction connects naturally to <code class="language-plaintext highlighter-rouge">krita</code> and <code class="language-plaintext highlighter-rouge">karma</code>: the choice one makes, and the action that follows from that choice. A human being is not merely pushed around by material conditions. The human being has the capacity to control desire, evaluate alternatives, and act. Those actions then shape the moral and spiritual path of the person.</p>

<p>That is the view of free will I find most convincing.</p>

<h2 id="ai-agents-and-choice">AI agents and choice</h2>

<p>The harder question is whether an artificially intelligent agent can have free will.</p>

<p>For narrow AI, my answer is no.</p>

<p>A narrow AI agent can select from alternatives. It can optimize against a goal. It can make plans, call tools, respond to feedback, and produce behavior that looks increasingly independent. But that is not the same as self-determined intent.</p>

<p>The agent’s world is bounded by its training, context window, tools, reward structure, prompts, and permissions. It can operate within that constructed space, but it does not possess the full authorship of its own aims. It does not decide what kind of being it wants to become. It does not carry moral responsibility for its actions in the way a human being does.</p>

<p>We must not confuse fluent behavior with inner agency.</p>

<p>An AI system can say “I decided” without deciding in the human sense, or “I want” and “I believe” without desire or belief behind the words. These are useful linguistic shortcuts, but they should not mislead us into treating the system as a self-determined moral actor.</p>

<h2 id="knowledge-is-not-enough">Knowledge is not enough</h2>

<p>One reason narrow AI lacks free will is that its knowledge is incomplete and externally bounded.</p>

<p>To make a genuinely self-determined choice, one must be able to consider alternatives, understand consequences, and rule out paths not merely because a rule forbids them, but because one has an intentional stance toward them. Narrow AI cannot do that in the full sense. Its available alternatives are created by architecture and context. Its refusals are policy behavior, not moral renunciation.</p>

<p>This is where the <a href="/2026/07/28/is-an-anthill-conscious/">earlier discussion of consciousness</a> becomes relevant. If free will requires consciousness, then an AI agent would need more than inference, memory, and pattern completion. It would need perception and non-perception in a deeper sense: the ability to acquire awareness on its own, and to understand absence or non-existence with something stronger than statistical limitation.</p>

<p>Current narrow AI does not meet that bar.</p>

<h2 id="responsibility-stays-with-humans">Responsibility stays with humans</h2>

<p>The practical conclusion is simple: do not move responsibility from humans to AI agents.</p>

<p>An AI agent may act. It may produce an output, make a recommendation, trigger an automation, or complete a task. But the responsibility for that action belongs to the people and institutions that designed, deployed, constrained, and benefited from the system.</p>

<p>Calling an AI system an “agent” is useful in engineering. It tells us the system can pursue a goal across steps. But agency in the engineering sense is not the same as free will in the moral or spiritual sense, and it helps to keep the two apart.</p>

<p>Humans can have free will because humans can form intent, evaluate action, and bear responsibility for karma. Narrow AI can simulate choice, but it does not own its choices. It is still an instrument operating inside limits set by human beings.</p>

<p>So the question worth asking is not whether AI has free will. It is whether we, the humans building and using it, are willing to exercise ours responsibly.</p>

<h2 id="references">References</h2>

<p>Bhagavad Gita, Chapter 7, Verse 5.</p>

<p>BBC Bitesize, “The nature of human life in Hinduism”.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="AI" /><category term="Spirituality &amp; Philosophy" /><category term="ai" /><category term="philosophy" /><category term="hinduism" /><category term="free-will" /><category term="opinion" /><summary type="html"><![CDATA[A short opinion piece on free will, intentionality, and why narrow AI agents should not be treated as self-determined actors.]]></summary></entry><entry><title type="html">Review: Studying the Wisdom of Crowds at Scale</title><link href="https://systemhalted.in/2026/08/09/review-studying-wisdom-of-crowds-at-scale/" rel="alternate" type="text/html" title="Review: Studying the Wisdom of Crowds at Scale" /><published>2026-08-09T00:00:00+00:00</published><updated>2026-08-09T00:00:00+00:00</updated><id>https://systemhalted.in/2026/08/09/review-studying-wisdom-of-crowds-at-scale</id><content type="html" xml:base="https://systemhalted.in/2026/08/09/review-studying-wisdom-of-crowds-at-scale/"><![CDATA[<p>Simoiu, Sumanth, Mysore, and Goel’s “Studying the Wisdom of Crowds at Scale” investigates a familiar claim: groups often make better judgments than individuals.</p>

<p>The paper is useful because it does not treat that claim as folklore. It studies crowd performance through a large online experiment with 1,000 questions across 50 topical domains and more than 500,000 responses. The questions included numerical and categorical answers, and the domains spanned text, audio, video, and image-based tasks.</p>

<p>That scale matters. It lets the paper examine crowd judgment across different kinds of knowledge rather than relying on one narrow trivia-style setting.</p>

<h2 id="what-the-paper-shows">What the paper shows</h2>

<p>The paper reports three important findings.</p>

<p>First, crowds often outperform individuals. Aggregating many imperfect judgments can produce a better answer than relying on one person’s judgment.</p>

<p>Second, crowd performance is more consistent than individual performance. Individuals vary widely, but aggregation can smooth out some of that noise.</p>

<p>Third, social influence can damage crowd performance. When people see others’ answers, the group can begin to herd. Instead of adding independent information, participants may copy visible signals, and the crowd becomes less accurate.</p>

<p>That third finding is the most interesting part of the paper. The wisdom of crowds depends on the independence of the crowd. Once social influence becomes too strong, the mechanism that made the group useful begins to fail.</p>

<h2 id="why-it-matters">Why it matters</h2>

<p>The paper connects directly to how modern digital systems work.</p>

<p>Recommendation systems, ratings, rankings, social media feeds, prediction markets, search results, and product reviews all rely on some form of aggregated human signal. These systems often assume that more participation means better information.</p>

<p>However, if everyone is reacting to everyone else, the signal is no longer independent. The system may look democratic while quietly amplifying early noise, popularity, status, or visibility.</p>

<p>That matters for AI too. AI systems increasingly learn from human feedback, user behavior, ratings, corrections, and engagement patterns. If those human signals are herded, biased, or shaped by the system itself, the model may learn the shape of the feedback loop rather than the truth of the underlying domain.</p>

<h2 id="what-i-found-especially-useful">What I found especially useful</h2>

<p>The experimental design is the paper’s biggest strength.</p>

<p>Using 1,000 questions across 50 domains gives the work more credibility than a small demonstration. The inclusion of different media types also helps. Crowd judgment is not one thing. Estimating a number, recognizing an image, predicting an outcome, and answering a knowledge question may all behave differently.</p>

<p>The paper also gives a practical warning: collective intelligence is conditional. It works best when the system preserves independent judgment and aggregates diverse evidence. It weakens when social pressure collapses that independence.</p>

<p>That is a good lesson for anyone designing systems around votes, likes, reviews, surveys, or human feedback.</p>

<h2 id="what-remains-open">What remains open</h2>

<p>The paper shows that social influence can lead to herding, but it does not fully explain when that happens or why. Social influence is not always harmful. In some contexts, seeing others’ answers could help people correct mistakes or learn from better-informed participants.</p>

<p>The next question is therefore more specific:</p>

<ul>
  <li>When does social influence improve crowd performance?</li>
  <li>When does it reduce performance?</li>
  <li>Which domains are most vulnerable to herding?</li>
  <li>Can interface design preserve independence while still allowing useful collaboration?</li>
  <li>How should systems detect when crowd judgment has become an echo rather than evidence?</li>
</ul>

<p>These questions matter because many real-world systems cannot simply remove social influence. The practical challenge is to design around it.</p>

<h2 id="bottom-line">Bottom line</h2>

<p>“Studying the Wisdom of Crowds at Scale” is valuable because it treats collective intelligence as an empirical question rather than a slogan.</p>

<p>The paper shows that crowds can be powerful without being automatically wise. The crowd works when it contributes independent information. Once the system turns participants into followers of each other’s signals, it stops adding information and starts amplifying whatever was already visible.</p>

<p>That condition matters for AI, social platforms, and any product that depends on aggregated human judgment.</p>

<h2 id="reference">Reference</h2>

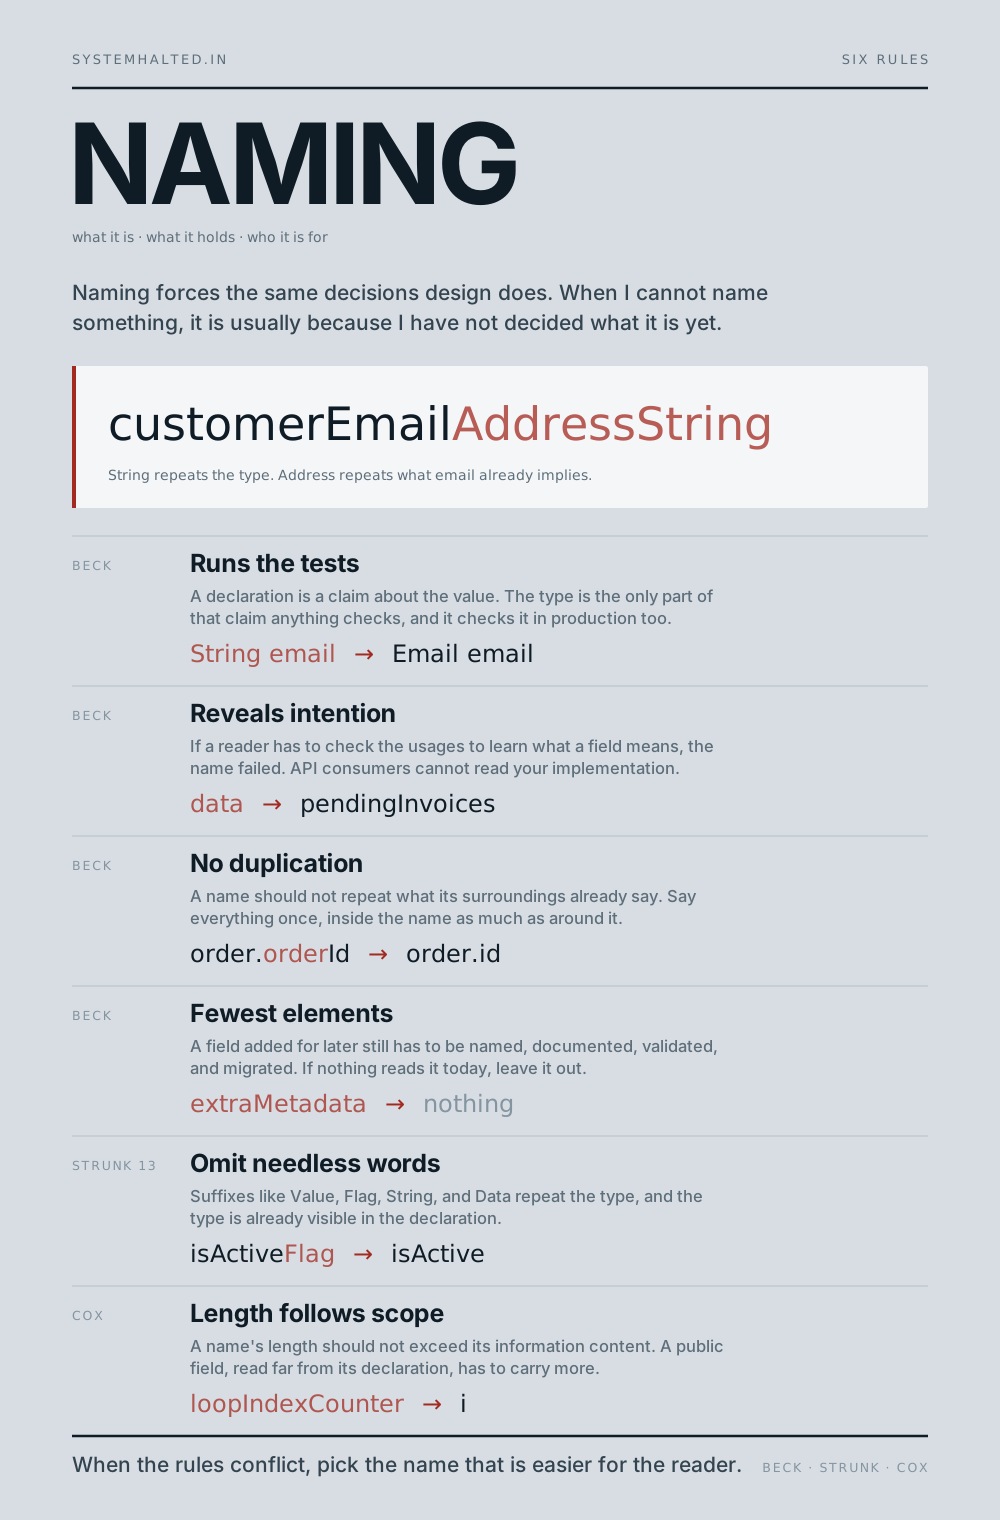
<p>Camelia Simoiu, Chiraag Sumanth, Alok Mysore, and Sharad Goel, “Studying the Wisdom of Crowds at Scale”, HCOMP 2019.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Article Review" /><category term="AI" /><category term="ai" /><category term="data" /><category term="article-review" /><category term="opinion" /><summary type="html"><![CDATA[A review of Simoiu et al.'s large-scale study of crowd judgment, accuracy, consistency, and the risks of social influence.]]></summary></entry><entry><title type="html">Naming as Design: Refactoring an API Model</title><link href="https://systemhalted.in/2026/08/07/naming-as-design-refactoring-an-api-model/" rel="alternate" type="text/html" title="Naming as Design: Refactoring an API Model" /><published>2026-08-07T05:30:00+00:00</published><updated>2026-08-07T05:30:00+00:00</updated><id>https://systemhalted.in/2026/08/07/naming-as-design-refactoring-an-api-model</id><content type="html" xml:base="https://systemhalted.in/2026/08/07/naming-as-design-refactoring-an-api-model/"><![CDATA[<p>In an <a href="/2026/07/23/my-naming-philosophy/">earlier post</a> I wrote down my naming rules: Kent Beck’s four rules of simple design read as naming rules, plus Strunk’s “omit needless words” and Russ Cox’s advice that a name’s length should not exceed its information content. In this post I apply them to one concrete model to show you what each of the rule does. I start with an order model that I would not want to inherit, and take it through four passes, one rule per pass.</p>

<p>The example is invented, even though is invented, but not far from the real ones. I have reviewed models that looked like this, and I have written a few.</p>

<h2 id="the-starting-point">The starting point</h2>

<p>The model, as a Java record and as the OpenAPI schema that exposes it:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">record</span> <span class="nf">OrderData</span><span class="o">(</span>
    <span class="nc">String</span> <span class="n">orderIdString</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">customerEmailAddressString</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">orderStatusValue</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">orderTotalAmountValue</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">orderCurrencyCodeString</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">createdDateTimestamp</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">updatedDateTimestamp</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">orderNotesText</span><span class="o">,</span>
    <span class="nc">Boolean</span> <span class="n">isOrderActiveFlag</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">futureDiscountCode</span><span class="o">,</span>
    <span class="nc">Map</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">,</span> <span class="nc">Object</span><span class="o">&gt;</span> <span class="n">extraAttributes</span>
<span class="o">)</span> <span class="o">{}</span>
</code></pre></div></div>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">OrderData</span><span class="pi">:</span>
  <span class="na">type</span><span class="pi">:</span> <span class="s">object</span>
  <span class="na">properties</span><span class="pi">:</span>
    <span class="na">orderIdString</span><span class="pi">:</span>              <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">customerEmailAddressString</span><span class="pi">:</span> <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">orderStatusValue</span><span class="pi">:</span>           <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">orderTotalAmountValue</span><span class="pi">:</span>      <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">orderCurrencyCodeString</span><span class="pi">:</span>    <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">createdDateTimestamp</span><span class="pi">:</span>       <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">updatedDateTimestamp</span><span class="pi">:</span>       <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">orderNotesText</span><span class="pi">:</span>             <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">isOrderActiveFlag</span><span class="pi">:</span>          <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">boolean</span> <span class="pi">}</span>
    <span class="na">futureDiscountCode</span><span class="pi">:</span>         <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">string</span> <span class="pi">}</span>
    <span class="na">extraAttributes</span><span class="pi">:</span>            <span class="pi">{</span> <span class="nv">type</span><span class="pi">:</span> <span class="nv">object</span> <span class="pi">}</span>
</code></pre></div></div>

<p>Nothing here is wrong in the sense that a test would catch. It compiles, it serializes, it round-trips. What is wrong is that the model makes no <em>checkable claims</em>: Nine of its eleven fields accept any string, the names repeat themselves, and two fields – <code class="language-plaintext highlighter-rouge">futureDiscountCode</code> and <code class="language-plaintext highlighter-rouge">extraAttributes</code> exist for reasons nobody can state. Each pass below fixes one of those problems.</p>

<h2 id="pass-1--runs-the-tests-give-every-value-a-type-that-can-reject-it">Pass 1 – Runs the tests: give every value a type that can reject it</h2>

<p>Beck’s first rule is that the code passes its tests. For a model, my reading is: the type of each field should be able to test the value the field must hold. A <code class="language-plaintext highlighter-rouge">String</code> passes everything, so it tests nothing. The first pass replaces every stringly-typed field with a type that can reject a bad value.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">record</span> <span class="nf">Email</span><span class="o">(</span><span class="nc">String</span> <span class="n">value</span><span class="o">)</span> <span class="o">{</span>
    <span class="kd">public</span> <span class="nc">Email</span> <span class="o">{</span>
        <span class="k">if</span> <span class="o">(!</span><span class="n">value</span><span class="o">.</span><span class="na">matches</span><span class="o">(</span><span class="s">"[^@\\s]+@[^@\\s]+\\.[^@\\s]+"</span><span class="o">))</span> <span class="o">{</span>
            <span class="k">throw</span> <span class="k">new</span> <span class="nf">IllegalArgumentException</span><span class="o">(</span><span class="s">"not an email address: "</span> <span class="o">+</span> <span class="n">value</span><span class="o">);</span>
        <span class="o">}</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>(Real email validation is more involved than one regex, and if you need it to be exact you delegate to a library. The point is not the regex; it is where the check lives. Any value of type <code class="language-plaintext highlighter-rouge">Email</code> has passed it, so code that receives an <code class="language-plaintext highlighter-rouge">Email</code> never has to re-check.)</p>

<p>The same treatment for the rest: an <code class="language-plaintext highlighter-rouge">OrderId</code> record that enforces the id format, an <code class="language-plaintext highlighter-rouge">OrderStatus</code> enum instead of a free-form status string, and <code class="language-plaintext highlighter-rouge">Instant</code> for the two timestamps, since the JDK already has a type that rejects malformed dates. The amount and the currency merge into one type, because a monetary amount without its currency is not a value you can do anything safe with:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">record</span> <span class="nf">Money</span><span class="o">(</span><span class="nc">BigDecimal</span> <span class="n">amount</span><span class="o">,</span> <span class="nc">Currency</span> <span class="n">currency</span><span class="o">)</span> <span class="o">{</span>
    <span class="kd">public</span> <span class="nc">Money</span> <span class="o">{</span>
        <span class="k">if</span> <span class="o">(</span><span class="n">amount</span><span class="o">.</span><span class="na">scale</span><span class="o">()</span> <span class="o">&gt;</span> <span class="n">currency</span><span class="o">.</span><span class="na">getDefaultFractionDigits</span><span class="o">())</span> <span class="o">{</span>
            <span class="k">throw</span> <span class="k">new</span> <span class="nf">IllegalArgumentException</span><span class="o">(</span><span class="s">"too many decimal places for "</span> <span class="o">+</span> <span class="n">currency</span><span class="o">);</span>
        <span class="o">}</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>After the first pass:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">record</span> <span class="nf">OrderData</span><span class="o">(</span>
    <span class="nc">OrderId</span> <span class="n">orderIdString</span><span class="o">,</span>          <span class="c1">// types fixed; the names are the next pass</span>
    <span class="nc">Email</span> <span class="n">customerEmailAddressString</span><span class="o">,</span>
    <span class="nc">OrderStatus</span> <span class="n">orderStatusValue</span><span class="o">,</span>
    <span class="nc">Money</span> <span class="n">orderTotalAmountValue</span><span class="o">,</span>
    <span class="nc">Instant</span> <span class="n">createdDateTimestamp</span><span class="o">,</span>
    <span class="nc">Instant</span> <span class="n">updatedDateTimestamp</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">orderNotesText</span><span class="o">,</span>
    <span class="nc">Boolean</span> <span class="n">isOrderActiveFlag</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">futureDiscountCode</span><span class="o">,</span>
    <span class="nc">Map</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">,</span> <span class="nc">Object</span><span class="o">&gt;</span> <span class="n">extraAttributes</span>
<span class="o">)</span> <span class="o">{}</span>
</code></pre></div></div>

<p>The schema gets the same pass. OpenAPI cannot run a constructor, but <code class="language-plaintext highlighter-rouge">format</code>, <code class="language-plaintext highlighter-rouge">enum</code>, <code class="language-plaintext highlighter-rouge">pattern</code>, and range constraints are its way of testing values before they reach your code:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">orderIdString</span><span class="pi">:</span>
  <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
  <span class="na">pattern</span><span class="pi">:</span> <span class="s1">'</span><span class="s">^ord_[0-9a-z]{12}$'</span>
<span class="na">customerEmailAddressString</span><span class="pi">:</span>
  <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
  <span class="na">format</span><span class="pi">:</span> <span class="s">email</span>
<span class="na">orderStatusValue</span><span class="pi">:</span>
  <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
  <span class="na">enum</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">pending</span><span class="pi">,</span> <span class="nv">paid</span><span class="pi">,</span> <span class="nv">shipped</span><span class="pi">,</span> <span class="nv">delivered</span><span class="pi">,</span> <span class="nv">cancelled</span><span class="pi">]</span>
<span class="na">orderTotalAmountValue</span><span class="pi">:</span>
  <span class="na">$ref</span><span class="pi">:</span> <span class="s1">'</span><span class="s">#/components/schemas/Money'</span>
<span class="na">createdDateTimestamp</span><span class="pi">:</span>
  <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
  <span class="na">format</span><span class="pi">:</span> <span class="s">date-time</span>
</code></pre></div></div>

<p>Every constraint added here is a test that runs on every request, in every environment, with no test suite involved. Alexis King’s <a href="https://lexi-lambda.github.io/blog/2019/11/05/parse-don-t-validate/">“Parse, don’t validate”</a> makes the general argument: once a value has parsed into a narrower type, the rest of the program can rely on it instead of re-checking it. This pass also caught a design error the original model hid: the amount and currency were two independent fields that could disagree, and <code class="language-plaintext highlighter-rouge">Money</code> makes that state unrepresentable.</p>

<h2 id="pass-2--reveals-intention-say-what-the-field-is-for">Pass 2 – Reveals intention: say what the field is for</h2>

<p>The types are now right but the names are still bad. The second pass renames each field to say what it is for, and Strunk’s rule 13 – omit needless words – does most of the work. For each name, strike the words that carry no information and see what is left.</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">customerEmailAddressString</code>: <code class="language-plaintext highlighter-rouge">String</code> repeats the type (and is now false – the type is <code class="language-plaintext highlighter-rouge">Email</code>). <code class="language-plaintext highlighter-rouge">Address</code> repeats what <em>email</em> already implies. What is left is <code class="language-plaintext highlighter-rouge">customerEmail</code>.</li>
  <li><code class="language-plaintext highlighter-rouge">createdDateTimestamp</code> and <code class="language-plaintext highlighter-rouge">updatedDateTimestamp</code>: <code class="language-plaintext highlighter-rouge">Date</code> and <code class="language-plaintext highlighter-rouge">Timestamp</code> both describe the type, which the declaration already shows. What the reader needs is the <em>event</em>: <code class="language-plaintext highlighter-rouge">createdAt</code>, <code class="language-plaintext highlighter-rouge">updatedAt</code>.</li>
  <li><code class="language-plaintext highlighter-rouge">orderNotesText</code>: <code class="language-plaintext highlighter-rouge">Text</code> describes the type. But striking it exposes a different failure: notes for whom, about what? If I cannot make a name specific, I usually have not decided what the field is for. In this system the field holds the customer’s instructions to the courier, so the honest name is <code class="language-plaintext highlighter-rouge">deliveryInstructions</code>.</li>
  <li><code class="language-plaintext highlighter-rouge">isOrderActiveFlag</code>: <code class="language-plaintext highlighter-rouge">Flag</code> repeats the type. But after striking it, I still cannot say what <em>active</em> means here – not cancelled? not delivered? recently touched? A field whose meaning I cannot state is a problem for a later pass; renaming it now would not fix it.</li>
</ul>

<p>An intention-revealing name matters more in the schema than in the Java code, because a consumer of the API cannot read the implementation. They have the field name, the type, and the description string, but the name is the one part most consumers actually read.</p>

<h2 id="pass-3--no-duplication-stop-repeating-the-context">Pass 3 – No duplication: stop repeating the context</h2>

<p>Every remaining name still says <em>order</em>, inside a type that already says it. <code class="language-plaintext highlighter-rouge">order.orderId</code> says order twice; so does <code class="language-plaintext highlighter-rouge">OrderData.orderStatusValue</code> – three times, if you count <code class="language-plaintext highlighter-rouge">Value</code> restating the type. Once a field lives inside <code class="language-plaintext highlighter-rouge">Order</code>, the context carries that word, and repeating it adds length without adding information. The <code class="language-plaintext highlighter-rouge">Data</code> suffix on the record name is the same duplication one level up: it describes what every record is. In <a href="/2025/12/15/vibe-coding-and-baby-genius/">Vibe Coding and the Baby Genius Problem</a> I made the same case against <code class="language-plaintext highlighter-rouge">Request</code> and <code class="language-plaintext highlighter-rouge">Response</code> suffixes on API models.</p>

<p>This is Russ Cox’s <code class="language-plaintext highlighter-rouge">getParametersAsNamedValuePairArray</code> point at the field level – the only interesting word in that name is <em>parameters</em>, and the only interesting word in <code class="language-plaintext highlighter-rouge">orderStatusValue</code> is <em>status</em>.</p>

<p>The pass also catches duplication that is not in the names. <code class="language-plaintext highlighter-rouge">isOrderActiveFlag</code> turned out to mean “status is neither cancelled nor delivered” – it restates <code class="language-plaintext highlighter-rouge">status</code>, as data. Since the value is derivable from <code class="language-plaintext highlighter-rouge">status</code>, I delete the field rather than rename it; if the convenience matters, an <code class="language-plaintext highlighter-rouge">isActive()</code> method on the record can compute it.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">record</span> <span class="nf">Order</span><span class="o">(</span>
    <span class="nc">OrderId</span> <span class="n">id</span><span class="o">,</span>
    <span class="nc">Email</span> <span class="n">customerEmail</span><span class="o">,</span>
    <span class="nc">OrderStatus</span> <span class="n">status</span><span class="o">,</span>
    <span class="nc">Money</span> <span class="n">total</span><span class="o">,</span>
    <span class="nc">Instant</span> <span class="n">createdAt</span><span class="o">,</span>
    <span class="nc">Instant</span> <span class="n">updatedAt</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">deliveryInstructions</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">futureDiscountCode</span><span class="o">,</span>
    <span class="nc">Map</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">,</span> <span class="nc">Object</span><span class="o">&gt;</span> <span class="n">extraAttributes</span>
<span class="o">)</span> <span class="o">{}</span>
</code></pre></div></div>

<h2 id="pass-4--fewest-elements-delete-what-has-no-reason-to-exist">Pass 4 – Fewest elements: delete what has no reason to exist</h2>

<p>Two fields remain that no current feature reads.</p>

<p><code class="language-plaintext highlighter-rouge">futureDiscountCode</code> was added because a discounts feature is expected someday. When that feature arrives it will have real requirements, and this field – named, typed, and shaped before any of them were known – is unlikely to match. Until then it is surface area: it appears in generated clients, consumers store it, and when the real feature ships it will have to be deprecated in favour of whatever is actually needed.</p>

<p><code class="language-plaintext highlighter-rouge">extraAttributes</code> is a bigger problem, because it weakens the whole schema rather than just adding an unused field. A <code class="language-plaintext highlighter-rouge">Map&lt;String, Object&gt;</code> field says that anything may appear here, with any type, and none of it is documented. Whatever goes into that map is exactly the data that should have been a named, typed field, and once consumers start passing values through it you can never remove it. The only cheap time to delete it is while it is still empty.</p>

<p>The final model:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">record</span> <span class="nf">Order</span><span class="o">(</span>
    <span class="nc">OrderId</span> <span class="n">id</span><span class="o">,</span>
    <span class="nc">Email</span> <span class="n">customerEmail</span><span class="o">,</span>
    <span class="nc">OrderStatus</span> <span class="n">status</span><span class="o">,</span>
    <span class="nc">Money</span> <span class="n">total</span><span class="o">,</span>
    <span class="nc">Instant</span> <span class="n">createdAt</span><span class="o">,</span>
    <span class="nc">Instant</span> <span class="n">updatedAt</span><span class="o">,</span>
    <span class="nc">String</span> <span class="n">deliveryInstructions</span>
<span class="o">)</span> <span class="o">{}</span>
</code></pre></div></div>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Order</span><span class="pi">:</span>
  <span class="na">type</span><span class="pi">:</span> <span class="s">object</span>
  <span class="na">required</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">id</span><span class="pi">,</span> <span class="nv">customerEmail</span><span class="pi">,</span> <span class="nv">status</span><span class="pi">,</span> <span class="nv">total</span><span class="pi">,</span> <span class="nv">createdAt</span><span class="pi">,</span> <span class="nv">updatedAt</span><span class="pi">]</span>
  <span class="na">properties</span><span class="pi">:</span>
    <span class="na">id</span><span class="pi">:</span>
      <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
      <span class="na">pattern</span><span class="pi">:</span> <span class="s1">'</span><span class="s">^ord_[0-9a-z]{12}$'</span>
    <span class="na">customerEmail</span><span class="pi">:</span>
      <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
      <span class="na">format</span><span class="pi">:</span> <span class="s">email</span>
    <span class="na">status</span><span class="pi">:</span>
      <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
      <span class="na">enum</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">pending</span><span class="pi">,</span> <span class="nv">paid</span><span class="pi">,</span> <span class="nv">shipped</span><span class="pi">,</span> <span class="nv">delivered</span><span class="pi">,</span> <span class="nv">cancelled</span><span class="pi">]</span>
    <span class="na">total</span><span class="pi">:</span>
      <span class="na">$ref</span><span class="pi">:</span> <span class="s1">'</span><span class="s">#/components/schemas/Money'</span>
    <span class="na">createdAt</span><span class="pi">:</span>
      <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
      <span class="na">format</span><span class="pi">:</span> <span class="s">date-time</span>
    <span class="na">updatedAt</span><span class="pi">:</span>
      <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
      <span class="na">format</span><span class="pi">:</span> <span class="s">date-time</span>
    <span class="na">deliveryInstructions</span><span class="pi">:</span>
      <span class="na">type</span><span class="pi">:</span> <span class="s">string</span>
      <span class="na">maxLength</span><span class="pi">:</span> <span class="m">500</span>
</code></pre></div></div>

<p>Seven fields instead of eleven, every one of them constrained, and every name down to the words that carry information. Cox’s rule about length and scope explains why the final names can be this short: <code class="language-plaintext highlighter-rouge">id</code> is unambiguous precisely because it is read inside <code class="language-plaintext highlighter-rouge">Order</code>, where the context supplies the rest. The same field flattened into a log line or an analytics event should be <code class="language-plaintext highlighter-rouge">orderId</code> again, because there the context is gone and the name has to carry it.</p>

<h2 id="trade-offs">Trade-offs</h2>

<p>The refactor above is presented as if it were free. It is not, and it helps to know the costs before applying it.</p>

<p><strong>Wrapper types are ceremony, and serialization notices.</strong> Every <code class="language-plaintext highlighter-rouge">Email</code>-style type needs a Jackson <code class="language-plaintext highlighter-rouge">@JsonValue</code> and <code class="language-plaintext highlighter-rouge">@JsonCreator</code> (or the equivalent in your framework) so it serializes as a plain string rather than a nested object. Records have made the class definitions nearly free, but the serialization plumbing is a real, one-time cost per type, and on a small internal tool it may not pay for itself.</p>

<p><strong>Some strings are honestly strings.</strong> <code class="language-plaintext highlighter-rouge">deliveryInstructions</code> stayed a <code class="language-plaintext highlighter-rouge">String</code> because free text is genuinely a string: there is no constraint a <code class="language-plaintext highlighter-rouge">DeliveryInstructions</code> type could test beyond a length cap, and the schema’s <code class="language-plaintext highlighter-rouge">maxLength</code> already covers that. Wrapping it would add a type without adding a check. The test I use: if the constructor would be empty, the wrapper adds nothing.</p>

<p><strong>Renaming a published field is a breaking change.</strong> Everything in this post is cheap at design time and expensive after the first consumer integrates. Once <code class="language-plaintext highlighter-rouge">orderIdString</code> is in production and has seen traffic, fixing it means versioning the API or carrying both names through a deprecation cycle. This is the strongest argument for doing the naming work before v1 ships rather than after.</p>

<p><strong>Short names depend on their context surviving.</strong> <code class="language-plaintext highlighter-rouge">id</code> is right inside the schema and wrong in a CSV export. If a name will be read where its enclosing context is stripped away, it has to carry the context itself. Cox’s rule decides both cases; it just gives different answers.</p>

<p><strong>A consistent team convention beats my preference.</strong> If the codebase I am in writes <code class="language-plaintext highlighter-rouge">orderId</code> on every entity, I write <code class="language-plaintext highlighter-rouge">orderId</code>. A reader who can predict every name in the system is better off than one who has to learn which files follow which philosophy.</p>

<h2 id="sources">Sources</h2>

<ul>
  <li><a href="https://martinfowler.com/bliki/BeckDesignRules.html">Kent Beck’s four rules of simple design</a>, as summarized by Martin Fowler</li>
  <li><a href="https://www.bartleby.com/lit-hub/the-elements-of-style/iii-elementary-principles-of-composition/#13">The Elements of Style, rule 13: omit needless words</a>, Strunk</li>
  <li><a href="https://research.swtch.com/names">Notes on naming</a>, Russ Cox</li>
  <li><a href="https://lexi-lambda.github.io/blog/2019/11/05/parse-don-t-validate/">Parse, don’t validate</a>, Alexis King</li>
  <li><a href="/2026/07/23/my-naming-philosophy/">My naming philosophy</a>, the short version of this post</li>
  <li><a href="/2025/12/15/vibe-coding-and-baby-genius/">Vibe Coding and the Baby Genius Problem</a>, an earlier post of mine on making naming conventions enforceable</li>
</ul>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Software Engineering" /><category term="Computer Science" /><category term="naming" /><category term="api-design" /><category term="java" /><category term="openapi" /><category term="design" /><category term="software" /><summary type="html"><![CDATA[Taking one badly named order model -- Java record and OpenAPI schema -- through four passes: types that test values, names that reveal intention, duplication removed, and speculative fields deleted.]]></summary></entry><entry><title type="html">What UNO Teaches About Rule-Based Agents</title><link href="https://systemhalted.in/2026/08/04/what-uno-teaches-about-rule-based-agents/" rel="alternate" type="text/html" title="What UNO Teaches About Rule-Based Agents" /><published>2026-08-04T00:00:00+00:00</published><updated>2026-08-04T00:00:00+00:00</updated><id>https://systemhalted.in/2026/08/04/what-uno-teaches-about-rule-based-agents</id><content type="html" xml:base="https://systemhalted.in/2026/08/04/what-uno-teaches-about-rule-based-agents/"><![CDATA[<p>UNO is a simple problem for exploring rule-based agents because the rules are simple, but the decisions are not completely trivial.</p>

<p>At its simplest, the agent only needs to choose a legal card. It can match color, match value, play a wild card, draw cards, skip turns, and remember to say “UNO” before its last card. That is enough to build a production system: a set of <code class="language-plaintext highlighter-rouge">if</code> conditions connected to actions.</p>

<p>For example:</p>

<ul>
  <li>If the discard card is a skip or reverse card, skip the turn when required.</li>
  <li>If the agent has a card matching the current color, play it.</li>
  <li>If the agent has no color match but has a card with the same value, play that.</li>
  <li>If no ordinary card is playable, consider a wild card.</li>
  <li>If a wild card is played, choose the color that gives the agent the strongest remaining hand.</li>
  <li>If no legal play exists, draw.</li>
</ul>

<p>Because the behavior is explicit, you can inspect the rules and explain why every move was made. That explainability is one of the main strengths of production systems. Every action can be traced back to the rule that fired.</p>

<p>Here is a small example of how such an agent behaves.</p>

<p>Suppose the visible discard card is yellow <code class="language-plaintext highlighter-rouge">8</code>, and the agent’s hand contains red numbered cards, two blue <code class="language-plaintext highlighter-rouge">8</code> cards, a blue <code class="language-plaintext highlighter-rouge">3</code>, a green draw-two card, and a wild draw-four card. The agent cannot match yellow, but it can match the value. So it plays a blue <code class="language-plaintext highlighter-rouge">8</code>. This is a legal move, but it is not necessarily strategic. It simply follows the first useful rule that applies.</p>

<p>Now suppose the next visible card is a blue skip. If the skip was not produced by the agent’s own previous move, the agent loses the turn and records that the skip effect has been consumed. That small bit of state matters. Without it, the agent might keep reacting to the same skip card as if it were a new event.</p>

<p>Near the end of the hand, the agent may have only the green draw-two and wild draw-four left. If the discard is red <code class="language-plaintext highlighter-rouge">9</code>, it has no color match, no value match, and no ordinary wild card. So it plays wild draw-four, chooses the color that best matches its remaining hand, and says “UNO” because it is down to one card. If the chosen color is green, the final green draw-two becomes playable on the next turn.</p>

<p>The agent simply follows a priority order:</p>

<ul>
  <li>match color if possible</li>
  <li>otherwise match value</li>
  <li>otherwise use a wild option</li>
  <li>choose the next color based on the remaining hand</li>
  <li>maintain enough state to avoid misreading skip and draw effects</li>
</ul>

<p>That is enough to play a legal sequence. It is not enough to be a strong player because a legal move is not always a good move.</p>

<p>A simple UNO production system can play the game, but it does not necessarily play to win. It can follow the rules while still making weak choices. It may play a special card too early, hold the wrong color too long, or fail to account for an opponent’s likely hand.</p>

<p>A rule-based agent can be competent at legality without being competent at strategy. To become stronger, the agent needs more than local rules. It needs memory and search:</p>

<ul>
  <li>Remember previous moves.</li>
  <li>Track the opponent’s visible moves.</li>
  <li>Remember which colors and values have appeared.</li>
  <li>Estimate what cards the opponent might still hold.</li>
  <li>Search across possible future states.</li>
  <li>Compare legal moves by expected advantage, not only immediate playability.</li>
</ul>

<p>Once those capabilities are added, the agent changes character. It is no longer merely asking “what can I play?” It begins asking “what should I play, given what might happen next?”</p>

<p>This small example maps cleanly to larger AI systems. Many production systems are, at their core, rule-based agents. They approve, reject, route, escalate, notify, retry, block, or transform based on explicit conditions. That design is often the right one. It is inspectable, debuggable, and easy to constrain.</p>

<p>The limitation appears when success depends on strategy rather than legality. A production system can explain every decision while still making poor long-term choices because it lacks planning, opponent modeling, and learning from experience. That is not a flaw in production systems; it reflects the kinds of problems they were designed to solve. UNO makes the distinction clear: playing a legal card requires rules, but playing well requires knowledge, memory, and search.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="AI" /><category term="Computer Science" /><category term="ai" /><category term="computer-science" /><category term="knowledge-representation" /><category term="games" /><category term="opinion" /><summary type="html"><![CDATA[A small UNO-playing production system shows both the usefulness and the limits of rule-based agents.]]></summary></entry><entry><title type="html">Review: How Technological Advances Can Reveal Rights</title><link href="https://systemhalted.in/2026/08/02/review-how-technological-advances-can-reveal-rights/" rel="alternate" type="text/html" title="Review: How Technological Advances Can Reveal Rights" /><published>2026-08-02T18:00:00+00:00</published><updated>2026-08-02T18:00:00+00:00</updated><id>https://systemhalted.in/2026/08/02/review-how-technological-advances-can-reveal-rights</id><content type="html" xml:base="https://systemhalted.in/2026/08/02/review-how-technological-advances-can-reveal-rights/"><![CDATA[<p>Parker and Danks’s <em>How Technological Advances Can Reveal Rights</em> offers a useful framework for thinking about the relationship between technological change and rights.</p>

<p>The paper’s central idea is the “revealed right”: a right that becomes meaningful only in a particular technological context. The right is not invented from nothing. The underlying human interest may already exist. What changes is the technology. It shifts the balance of power enough to reveal a corresponding duty.</p>

<p>That framing is helpful because it avoids two weak positions. It does not pretend that every new technological discomfort automatically creates a right. It also does not pretend that rights are fixed forever in the form they had before modern technology changed the world.</p>

<h2 id="the-framework">The framework</h2>

<p>The paper describes a pattern:</p>

<p>Parties have important but conflicting interests. A technology gives one party more causal power to advance its interests, while weakening another party’s ability to protect theirs. When that imbalance becomes large enough, a right may be revealed.</p>

<p>This is a practical framework because it connects rights to changes in power rather than to technological novelty.</p>

<p>We usually expect power to track the ethical weight of an interest. If one person’s interest is much more important, we expect the social or legal system to protect that interest more strongly. Technology can break that expectation. It can give enormous practical power to a party whose interest is actually less weighty.</p>

<p>That is where rights become newly urgent.</p>

<h2 id="examples">Examples</h2>

<p>The paper discusses rights such as the right to public anonymity, the right to be forgotten, and the right to disconnect.</p>

<p>These examples make sense because the underlying interests are old, but the scale of intrusion is new.</p>

<p>People have always cared about privacy, reputation, rest, and control over their social presence. But search engines, social media, cheap storage, facial recognition, smartphones, and workplace messaging changed the balance. They made it inexpensive and scalable for companies, governments, employers, and strangers to remember, locate, classify, interrupt, or expose people in ways that older norms did not fully anticipate.</p>

<p>The result is not simply “technology is bad” but that it can disturb the balance between interests and power. When that happens, rights language becomes a way to restore the balance.</p>

<h2 id="what-i-found-useful">What I found useful</h2>

<p>The paper’s strongest contribution is that it gives a framework for evaluating new rights without treating them as arbitrary.</p>

<p>The question is not merely whether someone wants protection. The question is whether a technology has changed the distribution of causal power between parties, and therefore the duties they owe one another.</p>

<p>This is especially useful for AI. AI systems can change power relationships quickly:</p>

<ul>
  <li>Employers can monitor workers more closely.</li>
  <li>Platforms can classify users cheaply.</li>
  <li>Governments can monitor and process large populations at scale.</li>
  <li>Companies can infer sensitive traits from ordinary behavior.</li>
  <li>Automated systems can make decisions that are difficult for individuals to understand or contest.</li>
</ul>

<p>In each case, the ethical question is not only whether the technology works. It is whether the technology has created a new imbalance that requires a corresponding duty.</p>

<h2 id="what-remains-open">What remains open</h2>

<p>The paper deliberately focuses on when rights become visible, not on how institutions should recognize, enforce, or balance those rights.</p>

<p>Some rights may need formal legal protection. Others may be better handled through regulation, product design, professional norms, workplace policy, or social expectations. The paper gives a strong account of how a right becomes visible, but less detail on how that right should be honored in practice.</p>

<p>That leaves several important questions:</p>

<ul>
  <li>Which revealed rights should become law?</li>
  <li>Which should become product obligations?</li>
  <li>Which can be handled through social norms?</li>
  <li>Who owes the duty: governments, companies, employers, platforms, or individuals?</li>
  <li>What remedies should exist when the right is violated?</li>
  <li>How should technology companies build revealed rights into product, legal, and marketing strategy?</li>
</ul>

<p>Those questions are where the theory has to become governance.</p>

<h2 id="bottom-line">Bottom line</h2>

<p>“How Technological Advances Can Reveal Rights” is valuable because it explains why technology can make old interests newly urgent.</p>

<p>The paper does not argue that every technological change creates a new right. It argues that technology can shift causal power so dramatically that a previously latent right, and the corresponding duty, become visible. The novelty of the paper is not that it argues for new rights, but that it explains when technological change justifies recognizing them.</p>

<p>That is a strong way to think about AI-era rights. It asks us to look beyond the interests people hold and examine how technology has changed the distribution of power over those interests and what duties should now exist because of that change.</p>

<h2 id="reference">Reference</h2>

<p>Jack Parker and David Danks, “How Technological Advances Can Reveal Rights”, AIES 2019.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Article Review" /><category term="AI" /><category term="Politics &amp; Governance" /><category term="ai" /><category term="law" /><category term="technology" /><category term="article-review" /><category term="opinion" /><summary type="html"><![CDATA[A review of Parker and Danks's argument that some rights become visible only when technology changes the balance of power.]]></summary></entry><entry><title type="html">Why Doesn’t Wisdom Accumulate?</title><link href="https://systemhalted.in/2026/08/02/wisdom-accumulation/" rel="alternate" type="text/html" title="Why Doesn’t Wisdom Accumulate?" /><published>2026-08-02T02:30:00+00:00</published><updated>2026-08-02T02:30:00+00:00</updated><id>https://systemhalted.in/2026/08/02/wisdom-accumulation</id><content type="html" xml:base="https://systemhalted.in/2026/08/02/wisdom-accumulation/"><![CDATA[<p>Right from the moment we are born, we have to learn. We learn to suck, crawl, walk, speak, read, write, drive and eventually make a living. We spend decades accumulating knowledge. Every scar becomes a lesson. Every mistake is supposed to make us wiser. Learning is perhaps the defining characteristic of being human.</p>

<p>And yet, collectively, we are remarkably bad at behaving.</p>

<p>People still speed. People still jump red lights. People still drink and drive. We continue to fight over race, religion, nationality and ideology. We lie, cheat, steal and kill. Every generation inherits thousands of years of human history, yet somehow manages to repeat many of the same mistakes.</p>

<p>Maybe learning simply takes time. Maybe every generation becomes a little wiser than the previous one. History, however, does not inspire much confidence. It is full of wars that should have convinced us not to start new ones. It is full of financial crises that should have made us more careful. It is full of genocides that should have made future genocides unthinkable. Yet here we are.</p>

<p>There is an old saying that history repeats itself.</p>

<p>Of course it does.</p>

<p>If we struggle to learn from our own mistakes, expecting us to learn from the mistakes of people who lived centuries ago may simply be asking too much.</p>

<p>The psychologists have spent decades studying this very question. I expected to find evidence that failure is our greatest teacher. Instead, I found that the reality is much less encouraging.</p>

<h2 id="we-learn-much-less-from-failure-than-we-think">We learn much less from failure than we think</h2>

<p><em>In Not Learning From Failure—The Greatest Failure of All</em>, Lauren Eskreis-Winkler and Ayelet Fishbach found that people often learn less from failure than from success, even when failure provides exactly the same information.<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<p>The researchers identify two reasons. The first is emotional. Failure hurts. Rather than examining it, people often avoid thinking about it because it threatens their self-image.</p>

<p>The second is cognitive. Failure tells us what did not work, but it rarely tells us what will. Figuring out the lesson requires considerably more effort than repeating something that already succeeded.</p>

<p>We like to say that failure is the best teacher. Psychology suggests that it often isn’t — because we simply refuse to listen.<sup id="fnref:1:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<h2 id="institutions-remember-what-people-forget">Institutions remember what people forget</h2>

<p>Research by Dahlin, Chuang and Roulet points to an interesting difference between individuals and organizations.<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>Individuals often fail to learn from failure.</p>

<p>Organizations can do much better, but only when they deliberately preserve the lesson. Accidents become investigations. Investigations become reports. Reports become procedures. Procedures become standards.</p>

<p>People forget.</p>

<p>Institutions remember.</p>

<p>That is one reason aviation has become safer over time. Every major accident leaves behind documentation that changes how future pilots are trained. Drivers see accidents every day, but very few permanently change how they drive because someone else crashed.<sup id="fnref:2:1"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>The institution learns. The individuals often do not.</p>

<h2 id="civilization-accumulates-knowledge">Civilization accumulates knowledge</h2>

<p>Joseph Henrich argues that civilization advances because knowledge accumulates across generations rather than because individuals are exceptionally intelligent.<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>Nobody has to rediscover calculus, electricity or germ theory. We inherit them. Every generation starts where the previous one finished.</p>

<p>That is how science progresses.</p>

<p>That is how engineering progresses.</p>

<p>Technical knowledge accumulates because we know how to preserve it.</p>

<p>Behavioral wisdom does not seem to work the same way.</p>

<h2 id="we-do-not-learn-equally-from-everyone">We do not learn equally from everyone</h2>

<p>Research on cultural evolution shows that humans copy some people more readily than others. We imitate people who are successful, respected, prestigious or part of our own group.<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup></p>

<p>Sometimes those people deserve to be copied. Sometimes they do not.</p>

<p>Good behavior spreads this way. Bad behavior does too.</p>

<h2 id="knowing-something-is-not-enough">Knowing something is not enough</h2>

<p>Psychologists have known for a long time that knowledge alone rarely changes behavior.<sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<p>Most people know smoking causes cancer.</p>

<p>Most people know speeding is dangerous.</p>

<p>Most people know excessive drinking impairs judgment.</p>

<p>Most people know obesity increases health risks.</p>

<p>Yet millions continue doing all of these things.</p>

<p>Behavior is shaped not only by knowledge, but also by habits, incentives, emotions, identity and social pressure.<sup id="fnref:5:1"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<p>Knowing better does not necessarily mean <em>doing</em> better.</p>

<h2 id="we-think-everyone-else-is-the-problem">We think everyone else is the problem</h2>

<p>There is a well-known finding in psychology called the <em>Better-than-Average Effect</em>. Most drivers believe they are above-average drivers, even though that is statistically impossible.<sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup></p>

<p>If I already believe I am safer than everyone else, why would I change after seeing an accident? I assume the lesson is for someone else.</p>

<h2 id="our-brains-were-built-for-a-different-world">Our brains were built for a different world</h2>

<p>Evolutionary psychologists argue that the human mind evolved in small groups where feedback was immediate and consequences were local.<sup id="fnref:7"><a href="#fn:7" class="footnote" rel="footnote" role="doc-noteref">7</a></sup></p>

<p>Today we live with highways, financial markets, nuclear weapons, social media and artificial intelligence.</p>

<p>The world changed much faster than the human mind.</p>

<h2 id="so-why-does-history-repeat-itself">So why does history repeat itself?</h2>

<p>Historians correctly point out that history <em>never</em> repeats exactly.</p>

<p>The people change.</p>

<p>The technologies change.</p>

<p>The governments change.</p>

<p>What changes much more slowly is human psychology. Every generation believes it is different. Every generation believes it is smarter than the last. Every generation believes the warnings apply to someone else. That is probably why history keeps rhyming.</p>

<h2 id="the-real-problem">The real problem</h2>

<p>We have become exceptionally good at accumulating technical knowledge. We preserve it in books, scientific journals, engineering standards, universities and institutions. Every generation inherits that knowledge and adds a little more.</p>

<p>We have never built an equally effective way to accumulate behavioral wisdom.</p>

<p>Every generation still has to learn patience, prejudice, greed, empathy, cooperation and restraint almost from scratch. We continue making many of the same mistakes because the lessons never become part of a shared, reliable memory in the way scientific knowledge does.</p>

<p>Perhaps that is the real difference.</p>

<p>Knowledge accumulates. Behavioral wisdom barely does.</p>

<h2 id="references">References</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Eskreis-Winkler, L., &amp; Fishbach, A. (2019). Not Learning From Failure—The Greatest Failure of All. Psychological Science, 30(12), 1733–1744. https://doi.org/10.1177/0956797619881133 <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:1:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:2">
      <p>Dahlin, K. B., Chuang, Y. T., &amp; Roulet, T. J. (2018). Opportunity, Motivation, and Ability to Learn from Failures and Errors: Review, Synthesis, and Ways to Move Forward. Academy of Management Annals, 12(1), 252–277. https://doi.org/10.5465/annals.2016.0049 <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:2:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:3">
      <p>Henrich, J. (2016). The Secret of Our Success: How Culture Is Driving Human Evolution, Domesticating Our Species, and Making Us Smarter. Princeton University Press. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>Heyes, C. (2018). Cognitive Gadgets: The Cultural Evolution of Thinking. Harvard University Press. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>Fischhoff, B. (2013). The Sciences of Science Communication. Proceedings of the National Academy of Sciences, 110(Supplement 3), 14033–14039. <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:5:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:6">
      <p>Svenson, O. (1981). Are We All Less Risky and More Skillful Than Our Fellow Drivers? Acta Psychologica, 47(2), 143–148. <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:7">
      <p>Hoogland, M., &amp; Ploeger, A. (2022). Two Different Mismatches: Integrating the Developmental and the Evolutionary-Mismatch Hypothesis. Perspectives on Psychological Science, 17(6), 1737–1745. https://pmc.ncbi.nlm.nih.gov/articles/PMC9634284/ <a href="#fnref:7" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Personal Essays" /><category term="Society &amp; Economy" /><category term="opinion" /><category term="learning" /><category term="psychology" /><category term="cultural-evolution" /><category term="collective-intelligence" /><summary type="html"><![CDATA[We are extraordinarily good at accumulating technical knowledge and strangely bad at accumulating behavioral wisdom. What decades of psychology suggest about why every generation relearns patience, prejudice, and restraint almost from scratch.]]></summary></entry><entry><title type="html">Review: An Agile Ethical/Legal Model for AI and Robotics Governance</title><link href="https://systemhalted.in/2026/07/31/review-agile-ethical-legal-model-ai-robotics-governance/" rel="alternate" type="text/html" title="Review: An Agile Ethical/Legal Model for AI and Robotics Governance" /><published>2026-07-31T00:00:00+00:00</published><updated>2026-07-31T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/31/review-agile-ethical-legal-model-ai-robotics-governance</id><content type="html" xml:base="https://systemhalted.in/2026/07/31/review-agile-ethical-legal-model-ai-robotics-governance/"><![CDATA[<p>Wendell Wallach and Gary Marchant’s “An Agile Ethical/Legal Model for the International and National Governance of AI and Robotics” argues for a governance structure that can respond to AI and robotics faster than ordinary lawmaking usually can.</p>

<p>The core proposal is a Governance Coordinating Committee, or GCC, that would help coordinate ethical, legal, technical, and institutional responses to AI and robotics. The paper is not simply asking for another principles document. It is trying to describe an institutional mechanism for turning soft law into something more durable.</p>

<p>AI governance already has many declarations, principles, and high-level frameworks. The problem is not a shortage of ethical vocabulary. The problem is that fast-moving technology often outruns the institutions that are supposed to discipline it.</p>

<p>The paper’s strongest argument is that AI and robotics governance cannot be left entirely to one actor.</p>

<p>Governments move slowly and are constrained by jurisdiction. Engineers understand technical feasibility but do not always have authority or understanding of the consequences. Ethicists can clarify values and harms, but ethical analysis alone does not create compliance. Courts need framework in terms of laws, rules and precedents to make a judgment.</p>

<p>The proposed GCC is meant to sit across these groups and coordinate governance through multiple channels:</p>

<ul>
  <li>Government regulation</li>
  <li>Engineering standards</li>
  <li>Ethical guidance</li>
  <li>Insurance requirements</li>
  <li>Academic publication norms</li>
  <li>Grant funding conditions</li>
  <li>Judicial interpretation</li>
  <li>Organizational compliance programs</li>
</ul>

<p>That is a realistic way to think about AI governance. In practice, behavior changes when incentives converge from multiple directions. If insurers, journals, funders, regulators, and courts all begin expecting similar safety and transparency practices, companies have a stronger reason to treat those practices as real requirements instead of optional ethics theater.</p>

<p>Soft law is often criticized because it lacks direct enforcement. That criticism is fair, but then why does it matter?</p>

<p>In fast-moving areas such as AI, soft law can do work that formal law cannot do quickly enough. It can establish norms, define expected practice, create audit vocabulary, and give courts or regulators a reference point when formal disputes arise.</p>

<p>The paper’s useful insight is that soft law becomes stronger when institutions coordinate around it. A guideline from one professional group is easy to ignore. The same guideline becomes harder to ignore if it affects insurance, publication, procurement, grant funding, and litigation risk.</p>

<p>This is especially relevant for algorithmic transparency. Some AI systems may be explainable enough for ordinary review. Others may be opaque in ways that require different safeguards. A governance body could help define when opacity is acceptable, what testing is required before deployment, and which contexts should reject opaque systems entirely.</p>

<p>I agree with the paper’s broad direction. AI and robotics need governance that is international, adaptive, and institutionally connected.</p>

<p>The GDPR is a useful comparison. It gives enforceable rights within the European Union and has shaped global corporate behavior beyond Europe. But AI systems are not always contained within one legal jurisdiction. Models, data, users, vendors, and infrastructure can be spread across countries. A coordinating body could help reduce the gap between regional laws and global deployment.</p>

<p>The paper is also right that engineering and ethics need to be connected. Ethical principles are weak if they never become technical requirements. Engineering practices are dangerous if they optimize only for capability and ignore rights, safety, and human consequences.</p>

<p>However, the proposal leaves hard implementation questions open.</p>

<p>The biggest question is authority. Would the GCC merely recommend standards, or would it have some route to enforcement? If enforcement depends on other institutions, how would those institutions be coordinated? How would the GCC avoid becoming another advisory body whose output companies cite without changing behavior?</p>

<p>There are also questions about legitimacy:</p>

<ul>
  <li>Who appoints the GCC?</li>
  <li>How are affected communities represented?</li>
  <li>How does it avoid capture by large technology companies?</li>
  <li>How does it handle disagreement between countries with different values and legal systems?</li>
  <li>How does it connect to existing laws such as GDPR?</li>
  <li>How would it incorporate human rights declarations such as the Toronto Declaration into operational requirements?</li>
  <li>How GCC will operate internationally?</li>
  <li>How will GCC attain autonomy and at the same time have authority delegated by the government of different nations?</li>
</ul>

<p>The paper’s GCC proposal may or may not be the exact institution the world needs, but the underlying point is sound: AI principles require coordinated enforcement pathways. Without that, responsible AI stays mostly a matter of language.</p>

<p>Writing down what AI should respect is the easy part. Now, the harder work will be to build the institutions that make those commitments difficult to ignore.</p>

<h2 id="reference">Reference</h2>

<p>Wendell Wallach and Gary E. Marchant, “An Agile Ethical/Legal Model for the International and National Governance of AI and Robotics”, AIES 2018.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Article Review" /><category term="AI" /><category term="Politics &amp; Governance" /><category term="ai" /><category term="law" /><category term="governance" /><category term="article-review" /><category term="opinion" /><summary type="html"><![CDATA[A review of Wallach and Marchant's proposal for a Governance Coordinating Committee for AI and robotics, and why soft law needs institutional support.]]></summary></entry><entry><title type="html">Is an Anthill Conscious?</title><link href="https://systemhalted.in/2026/07/28/is-an-anthill-conscious/" rel="alternate" type="text/html" title="Is an Anthill Conscious?" /><published>2026-07-28T00:00:00+00:00</published><updated>2026-07-28T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/28/is-an-anthill-conscious</id><content type="html" xml:base="https://systemhalted.in/2026/07/28/is-an-anthill-conscious/"><![CDATA[<p>The brain and the anthill make an unsettling comparison because both seem to do more than their parts may explain on their own.</p>

<p>A neuron does not think. An ant does not plan the long-term fate of a colony. But a brain produces cognition through the interaction of neurons, and an ant colony produces coordinated behavior through the interaction of ants. In both cases, the interesting property lives at the level of the system, not the individual unit.</p>

<p><img src="/assets/images/2026-07-28-brain-anthill-emergence.svg" alt="A diagram with two columns, brain and anthill, each showing many simple units at the bottom, their local interactions in the middle, and a single system-level property at the top: neurons produce cognition, and ants produce colony behavior" /></p>

<p>That does not prove that an anthill is conscious. It does, however, make the question harder to dismiss.</p>

<h2 id="the-analogy">The analogy</h2>

<p>At the simplest level, the mapping looks like this:</p>

<ul>
  <li>A neuron maps to an individual ant.</li>
  <li>A brain maps to an ant colony.</li>
  <li>Neurotransmitters and dendrites map, roughly, to the signals ants exchange through antennae, movement, scent, and local interaction.</li>
  <li>Cognition maps to the organized behavior that emerges from many small interactions.</li>
</ul>

<p>The analogy is not perfect. A brain and a colony are built differently, operate at different speeds, and solve different classes of problems. But the analogy is useful because it forces a discipline on the question. If we are willing to talk about cognition as something that emerges from many non-conscious parts in the brain, we should at least ask what kind of intelligence emerges from many simple agents in a colony.</p>

<p><img src="/assets/images/2026-07-28-brain-anthill-mapping.svg" alt="A two-column diagram mapping parts of the brain to parts of an anthill: neuron to individual ant, whole brain to ant colony, neurotransmitters and dendrites to antennae, scent, and movement, and cognition to coordinated colony behavior" /></p>

<h2 id="a-vedantic-test">A Vedantic test</h2>

<p>In an <a href="/2020/01/20/intelligence-ai-vedanta/">earlier post</a> I used the six <code class="language-plaintext highlighter-rouge">pramanas</code> from Advaita Vedanta as a way to think about intelligence and artificial intelligence. They are not a laboratory test in the modern scientific sense. They are a philosophical framework for asking how knowledge is acquired and justified.</p>

<p>Applied to an anthill, they give us a useful checklist.</p>

<p><strong>Pratyaksha, or perception:</strong><br />
The colony can sense its surroundings through the distributed activity of individual ants. No single ant perceives the whole environment, but the colony can still respond to food, threat, nest quality, temperature, and other conditions.</p>

<p><strong>Anumana, or inference:</strong><br />
The colony can turn local signals into collective decisions. A change in behavior follows from accumulated evidence, even if no individual ant is performing explicit reasoning in the human sense.</p>

<p><strong>Upamana, or comparison and analogy:</strong><br />
Colonies can compare alternatives. Nest selection is a good example: scouts evaluate candidate sites, and the colony eventually converges on one option over another.</p>

<p><strong>Arthapatti, or postulation:</strong><br />
The colony can behave as if it is evaluating implications. If one nest site has better darkness but a worse entrance, and another has the reverse, the colony’s final movement reflects a tradeoff across conditions.</p>

<p><strong>Anupalabdhi, or non-perception:</strong><br />
The colony can incorporate absence. If a path stops producing food or a site fails to attract enough confirming activity, the colony’s behavior changes. This is not a formal proof of non-existence, but it is a practical response to missing evidence.</p>

<p><strong>Shabda, or word/testimony:</strong><br />
A colony has memory beyond the life of an individual ant. Its trails, nest structure, and learned patterns can persist across generations. In that sense, the colony can rely on information that no single living ant originated alone.</p>

<p>Under this framework, an anthill does surprisingly well.</p>

<h2 id="but-is-that-consciousness">But is that consciousness?</h2>

<p>The checklist shows that an anthill can satisfy several conditions we associate with intelligence: perception, inference, comparison, tradeoff, response to absence, and retained knowledge. That makes the anthill a strong example of collective intelligence.</p>

<p>But consciousness is a heavier claim than intelligence.</p>

<p>A system can process information without having inner experience. A market can aggregate signals. A city can route traffic. A software organization can remember habits that no employee wrote down (tribal knowledge). These systems can be intelligent in a distributed sense without obviously having a point of view.</p>

<p>An anthill behaves like a system with distributed cognition. It acquires information, compares alternatives, responds to missing signals, and preserves useful patterns across time. If consciousness is defined only in terms of knowledge acquisition and coordinated response, then the colony begins to qualify. If consciousness requires subjective experience, then the analogy becomes suggestive but not decisive.</p>

<h2 id="why-this-matters-for-ai">Why this matters for AI</h2>

<p>Modern AI systems are increasingly built as networks of smaller processes: models, tools, prompts, retrieval systems, evaluators, schedulers, memory stores, human feedback, and organizational review. Like an anthill, the behavior of the system is not located cleanly in any single part.</p>

<p>Once a distributed system begins producing impressive behavior, people start reaching for words like intelligence, agency, and consciousness. Sometimes those words clarify. Often they hide the real engineering question.</p>

<p>Asking whether the system feels conscious is not very useful, because we do not know how to answer it well. It is more practical to ask what the system actually does:</p>

<ul>
  <li>What does the system perceive?</li>
  <li>What can it infer?</li>
  <li>What alternatives can it compare?</li>
  <li>What tradeoffs can it evaluate?</li>
  <li>What absences can it detect?</li>
  <li>What past knowledge does it rely on?</li>
</ul>

<p>Those questions are practical. They can be tested. They also keep us from giving a system metaphysical credit[^1] for behavior that may be explainable through coordination, feedback, and memory.</p>

<p>Complex behavior does not require a tiny human sitting inside the system, making central decisions. Intelligence can emerge from interaction. But the existence of emergence does not automatically settle the question of consciousness, and it is worth keeping those two questions apart.</p>

<h2 id="references">References</h2>

<p>Bob Holmes, “The Mind of an Anthill”, Knowable Magazine, 2018.</p>

<p>Deborah M. Gordon, “Your brain has more in common with an ant colony than you realised”, World Economic Forum, 2019.</p>

<p>Eliot Deutsch and Rohit Dalvi, <em>The Essential Vedanta: A New Source Book of Advaita Vedanta</em>, 2004.</p>

<h2 id="notes">Notes</h2>
<p>[^1] In this context, “metaphysical credit” means attributing consciousness or subjective experience to a system just because it produces impressive behavior. It’s the leap from “this system does something smart” to “this system must be aware of what it’s doing.” My point in this post is that complex coordinated behavior, such as an anthill solving problems, an AI generating text, etc. can be fully explained by local interactions, feedback, and memory without invoking inner experience. Giving the system “metaphysical credit” is treating emergence as evidence of consciousness, when it might just be coordination.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="AI" /><category term="Spirituality &amp; Philosophy" /><category term="ai" /><category term="philosophy" /><category term="hinduism" /><category term="consciousness" /><category term="opinion" /><summary type="html"><![CDATA[An anthill is a useful way to think about collective intelligence, emergence, and the limits of calling a system conscious.]]></summary></entry><entry><title type="html">Diagrams as Text</title><link href="https://systemhalted.in/2026/07/26/diagrams-as-text/" rel="alternate" type="text/html" title="Diagrams as Text" /><published>2026-07-26T00:00:00+00:00</published><updated>2026-07-26T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/26/diagrams-as-text</id><content type="html" xml:base="https://systemhalted.in/2026/07/26/diagrams-as-text/"><![CDATA[<p>I recently needed a banner for my LinkedIn profile. I described what I wanted to a language model and got back an SVG, which is an XML file of tags, coordinates, and colors. I opened it in a text editor, adjusted what I did not like, and ran a script to produce the PNG sizes. At no point did I open a drawing tool.</p>

<p>There are models that can paint a picture. Image generators such as Nano Banana return finished pixels. But a finished picture can only be accepted, rejected, or regenerated. A language model produces text, and an SVG stores a picture as text. The model drew the banner by writing out the file the source of which I could edit.</p>

<p>SVG is not unusual in this. Mermaid describes flowcharts in a few lines of a small language. Graphviz does the same for graphs with DOT. PlantUML covers the standard software diagrams like sequence, class, and component. Each of these formats has an interesting story behind it. SVG is XML because it was designed as a web standard, and browsers render markup. DOT is text because Graphviz was built to lay out graphs that programs generate. Mermaid and PlantUML are text so that a diagram can live next to the prose and code it describes. There is one more interesting thing about all of them using text to describe a diagram. A diagram that is text can be diffed, reviewed, and committed like any other source file.</p>

<p>None of these formats was designed with a language model in mind. Yet they are exactly what a language model needs. Here is a flowchart, written as text:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>flowchart LR
  client[Client] --&gt; gw[API Gateway]
  gw --&gt; ent[Entitlements]
  ent -.denied.-&gt; client
</code></pre></div></div>

<p>The renderer this blog already uses turns those four lines into a picture:</p>

<pre><code class="language-mermaid">flowchart LR
  client[Client] --&gt; gw[API Gateway]
  gw --&gt; ent[Entitlements]
  ent -.denied.-&gt; client
</code></pre>

<p>When the design changes, I just need to edit four lines instead of redrawing anything. A model can write those four lines as easily as I can, because they sit close to how the picture would be described in words. The same holds for DOT and PlantUML: small vocabularies, named shapes, little room to go wrong.</p>

<p>There is a limit, and it is the same property seen from the other side. Writing a picture as text works only where the picture is simple enough to be written as text. Icons, badges, flowcharts, architecture diagrams — things built from clean primitives — sit comfortably inside it. A face or an animal does not. The model can still emit a path with fifty control points, but at that point the source is no longer something a person can read or fix, and the reason for wanting text is gone.</p>

<p>If diagrams had stayed pixels, drawing one would belong to the image models, and the result would be a flat picture with nothing to diff and nothing to edit. Because these formats store the picture as text, the model writes the source, and the renderers that were already there turn it into a picture. The formats were built for browsers, for graph layout, for documentation. Nobody planned the second use.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="AI" /><category term="Technology" /><category term="svg" /><category term="mermaid" /><category term="graphviz" /><category term="plantuml" /><category term="diagrams" /><category term="ai" /><summary type="html"><![CDATA[An image model returns finished pixels; a language model returns text. SVG, Mermaid, DOT, and PlantUML store a picture as text, so a language model can draw one, allowing you to edit what it draws.]]></summary></entry><entry><title type="html">Devanagari in Unicode</title><link href="https://systemhalted.in/2026/07/25/unicode-devanagari/" rel="alternate" type="text/html" title="Devanagari in Unicode" /><published>2026-07-25T00:00:00+00:00</published><updated>2026-07-25T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/25/unicode-devanagari</id><content type="html" xml:base="https://systemhalted.in/2026/07/25/unicode-devanagari/"><![CDATA[<p>Why did we need Unicode<sup id="fnref:unicode"><a href="#fn:unicode" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>? The answer usually is that ASCII<sup id="fnref:ascii"><a href="#fn:ascii" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> was too small. It could represent English but not the thousands of characters used by other writing systems. Unicode fixed this by assigning every character a unique number called a code point<sup id="fnref:codepoint"><a href="#fn:codepoint" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>A    U+0041
a    U+0061
अ    U+0905
क    U+0915
</code></pre></div></div>

<p>The explanation is correct to an extent; however it is not precise. It suggests that Unicode is a very large ASCII table: ASCII has a number for <code class="language-plaintext highlighter-rouge">A</code>, so Unicode has a number for <code class="language-plaintext highlighter-rouge">अ</code>; ASCII has a number for <code class="language-plaintext highlighter-rouge">B</code>, so Unicode has a number for <code class="language-plaintext highlighter-rouge">क</code>. From there it is a short step to assuming that every Hindi character on the screen has its own Unicode number. It does not and looking at how Devanagari<sup id="fnref:devanagari"><a href="#fn:devanagari" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> actually works in Unicode gives us a way to look into the workings of Unicode.</p>

<h2 id="start-with-क">Start with क</h2>

<p>The Devanagari letter क has the code point:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>U+0915    DEVANAGARI LETTER KA
</code></pre></div></div>

<p>So far the ASCII model holds. One letter, one number.</p>

<p>Now consider कि.</p>

<p>A Hindi reader sees this as a single syllabic unit, and the vowel sign ि<sup id="fnref:matra"><a href="#fn:matra" class="footnote" rel="footnote" role="doc-noteref">5</a></sup> appears visually to the <em>left</em> of the consonant. It would be reasonable to assume the computer stores it in that order. It does not. The stored sequence is:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>क    U+0915    DEVANAGARI LETTER KA
ि    U+093F    DEVANAGARI VOWEL SIGN I
</code></pre></div></div>

<p>That is, <code class="language-plaintext highlighter-rouge">U+0915 U+093F</code> – consonant first, vowel sign second. If you have ever typed in Hindi on your iPhone, that is the order you type as well.</p>

<p>Something happened between the sequence in memory and the pixels on the display. That something is text shaping<sup id="fnref:shaping"><a href="#fn:shaping" class="footnote" rel="footnote" role="doc-noteref">6</a></sup>.</p>

<h2 id="unicode-describes-logical-text-not-pixels">Unicode describes logical text, not pixels</h2>

<p>Unicode encodes characters and their logical order. It does not specify the shapes that end up on screen. The path from one to the other runs roughly like this:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>code points → encoded bytes → shaping engine → glyph selection → pixels
</code></pre></div></div>

<p>For Latin text most of this machinery is easy to overlook. <code class="language-plaintext highlighter-rouge">cat</code> is stored as <code class="language-plaintext highlighter-rouge">c</code>, <code class="language-plaintext highlighter-rouge">a</code>, <code class="language-plaintext highlighter-rouge">t</code> and displayed as <code class="language-plaintext highlighter-rouge">c a t</code>. Stored characters and displayed glyphs<sup id="fnref:glyph"><a href="#fn:glyph" class="footnote" rel="footnote" role="doc-noteref">7</a></sup> look one-to-one.</p>

<p>Devanagari breaks that assumption immediately.</p>

<h2 id="क्ष">क्ष</h2>

<p>The conjunct<sup id="fnref:conjunct"><a href="#fn:conjunct" class="footnote" rel="footnote" role="doc-noteref">8</a></sup> क्ष looks like one character. Unicode does not encode it as one. It is:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>क    U+0915    DEVANAGARI LETTER KA
्    U+094D    DEVANAGARI SIGN VIRAMA
ष    U+0937    DEVANAGARI LETTER SSA
</code></pre></div></div>

<p>The virama<sup id="fnref:virama"><a href="#fn:virama" class="footnote" rel="footnote" role="doc-noteref">9</a></sup> is the key element. It suppresses the inherent <code class="language-plaintext highlighter-rouge">a</code> vowel<sup id="fnref:inherentvowel"><a href="#fn:inherentvowel" class="footnote" rel="footnote" role="doc-noteref">10</a></sup> that a Devanagari consonant letter carries by default, which is what allows two consonants to join. When the shaping engine sees <code class="language-plaintext highlighter-rouge">consonant + virama + consonant</code>, it applies the font’s conjunct rules and may produce a single ligature glyph, or a half-form<sup id="fnref:halfform"><a href="#fn:halfform" class="footnote" rel="footnote" role="doc-noteref">11</a></sup> of the first consonant followed by the full second consonant, depending on the font. Both are correct renderings of the same three code points.</p>

<p>So one thing on screen, three code points underneath.</p>

<h2 id="five-terms-that-are-not-synonyms">Five terms that are not synonyms</h2>

<p>Once you accept that, the vocabulary has to get more precise. Five terms get used interchangeably and should not be:</p>

<p><strong>Code point.</strong> A number in the Unicode code space, from <code class="language-plaintext highlighter-rouge">U+0000</code> to <code class="language-plaintext highlighter-rouge">U+10FFFF</code>. <code class="language-plaintext highlighter-rouge">U+0915</code> is a code point.</p>

<p><strong>Character.</strong> An abstract textual element. क is a character, represented by the code point <code class="language-plaintext highlighter-rouge">U+0915</code>. Unicode itself uses “character” loosely, which is part of the problem.</p>

<p><strong>Code unit.</strong> The unit of the encoding form you chose. UTF-8<sup id="fnref:utf"><a href="#fn:utf" class="footnote" rel="footnote" role="doc-noteref">12</a></sup> has 8-bit code units; a Devanagari code point takes three of them. UTF-16 has 16-bit code units, and nearly<sup id="fnref:nearly"><a href="#fn:nearly" class="footnote" rel="footnote" role="doc-noteref">13</a></sup> every Devanagari code point fits in one, because the main block sits in the Basic Multilingual Plane<sup id="fnref:bmp"><a href="#fn:bmp" class="footnote" rel="footnote" role="doc-noteref">14</a></sup>. UTF-32 has 32-bit code units, one per code point.</p>

<p><strong>Grapheme cluster.</strong> A user-perceived character, defined by the segmentation rules in UAX #29<sup id="fnref:uax29"><a href="#fn:uax29" class="footnote" rel="footnote" role="doc-noteref">15</a></sup>. This is the closest thing to what a reader would call “one character.”</p>

<p><strong>Glyph.</strong> A shape in a font. Glyphs are what a font actually contains, and the mapping from characters to glyphs is many-to-many.</p>

<p>Almost every bug in this area comes from a program using one of these when it meant another.</p>

<h2 id="counting-the-same-string-five-ways">Counting the same string five ways</h2>

<p>Here are the three examples measured against each definition. All Devanagari code points encode as three bytes in UTF-8 and one code unit in UTF-16.</p>

<table>
  <thead>
    <tr>
      <th>String</th>
      <th>UTF-8 bytes</th>
      <th>UTF-16 units</th>
      <th>Code points</th>
      <th>Clusters (pre-15.1)</th>
      <th>Clusters (15.1+)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>कि</td>
      <td>6</td>
      <td>2</td>
      <td>2</td>
      <td>1</td>
      <td>1</td>
    </tr>
    <tr>
      <td>क्ष</td>
      <td>9</td>
      <td>3</td>
      <td>3</td>
      <td>2</td>
      <td>1</td>
    </tr>
    <tr>
      <td>श्री</td>
      <td>12</td>
      <td>4</td>
      <td>4</td>
      <td>2</td>
      <td>1</td>
    </tr>
    <tr>
      <td>हिन्दी</td>
      <td>18</td>
      <td>6</td>
      <td>6</td>
      <td>3</td>
      <td>2</td>
    </tr>
    <tr>
      <td>नमस्ते</td>
      <td>18</td>
      <td>6</td>
      <td>6</td>
      <td>4</td>
      <td>3</td>
    </tr>
    <tr>
      <td>स्त्र्य</td>
      <td>21</td>
      <td>7</td>
      <td>7</td>
      <td>4</td>
      <td>1</td>
    </tr>
    <tr>
      <td>क्षत्रिय</td>
      <td>24</td>
      <td>8</td>
      <td>8</td>
      <td>5</td>
      <td>3</td>
    </tr>
  </tbody>
</table>

<p>नमस्ते decomposes as:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>न    U+0928    DEVANAGARI LETTER NA
म    U+092E    DEVANAGARI LETTER MA
स    U+0938    DEVANAGARI LETTER SA
्    U+094D    DEVANAGARI SIGN VIRAMA
त    U+0924    DEVANAGARI LETTER TA
े    U+0947    DEVANAGARI VOWEL SIGN E
</code></pre></div></div>

<p>Six code points. A Hindi reader would say three units: न, म, स्ते. Depending on your runtime, a grapheme segmenter will tell you three or four.</p>

<h2 id="the-cluster-count-depends-on-your-runtime-not-your-code">The cluster count depends on your runtime, not your code</h2>

<p>Before Unicode 15.1, the extended grapheme cluster rules broke <em>after</em> a virama. क्ष counted as two clusters, नमस्ते as four. Unicode 15.1 added rule GB9c<sup id="fnref:gb9c"><a href="#fn:gb9c" class="footnote" rel="footnote" role="doc-noteref">16</a></sup>, which uses the new <code class="language-plaintext highlighter-rouge">Indic_Conjunct_Break</code><sup id="fnref:incb"><a href="#fn:incb" class="footnote" rel="footnote" role="doc-noteref">17</a></sup> property to hold <code class="language-plaintext highlighter-rouge">consonant + linker + consonant</code> together. Devanagari virama has <code class="language-plaintext highlighter-rouge">InCB=Linker</code>, so under 15.1 क्ष is one cluster.</p>

<p>This is not hypothetical. Here is <code class="language-plaintext highlighter-rouge">java.text.BreakIterator</code><sup id="fnref:breakiterator"><a href="#fn:breakiterator" class="footnote" rel="footnote" role="doc-noteref">18</a></sup> on JDK 21:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>हिन्दी     [हि][न्][दी]              3 clusters
क्षत्रिय   [क्][ष][त्][रि][य]        5 clusters
नमस्ते     [न][म][स्][ते]            4 clusters
कि         [कि]                      1 cluster
क्ष        [क्][ष]                   2 clusters
</code></pre></div></div>

<p>Every one of those is the pre-15.1 answer. The conjuncts split at the virama.</p>

<p>There are two things going on here. First, JDK 21 ships Unicode 15.0 character data, not 15.1 – you can confirm this without documentation by probing a marker code point:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">Character</span><span class="o">.</span><span class="na">isDefined</span><span class="o">(</span><span class="mh">0x11B00</span><span class="o">)</span>   <span class="c1">// true  -- Devanagari Extended-A, Unicode 15.0</span>
<span class="nc">Character</span><span class="o">.</span><span class="na">isDefined</span><span class="o">(</span><span class="mh">0x2EBF0</span><span class="o">)</span>   <span class="c1">// false -- CJK Ext-I, Unicode 15.1</span>
</code></pre></div></div>

<p>Second, and more important, <code class="language-plaintext highlighter-rouge">java.text.BreakIterator</code> carries its own segmentation rule data that is largely independent of the character tables. Upgrading the JDK does not reliably get you GB9c. For 15.1 behaviour in Java you need ICU4J’s<sup id="fnref:icu"><a href="#fn:icu" class="footnote" rel="footnote" role="doc-noteref">19</a></sup> <code class="language-plaintext highlighter-rouge">com.ibm.icu.text.BreakIterator</code>.</p>

<p>So the pre-15.1 column above is measured. The 15.1+ column is what the current rules specify. Which one your program produces is a property of the library you happened to link.</p>

<h2 id="what-length-actually-returns">What <code class="language-plaintext highlighter-rouge">length</code> actually returns</h2>

<p>The draft note on this post suggested that Java, JavaScript and Python disagree about the length of Hindi text. They mostly do not, and the reason is worth understanding.</p>

<p>For नमस्ते:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">"नमस्ते"</span><span class="o">.</span><span class="na">length</span><span class="o">()</span>                      <span class="c1">// 6   UTF-16 code units</span>
<span class="s">"नमस्ते"</span><span class="o">.</span><span class="na">codePointCount</span><span class="o">(</span><span class="mi">0</span><span class="o">,</span> <span class="mi">6</span><span class="o">)</span>          <span class="c1">// 6   code points</span>
<span class="s">"नमस्ते"</span><span class="o">.</span><span class="na">getBytes</span><span class="o">(</span><span class="no">UTF_8</span><span class="o">).</span><span class="na">length</span>        <span class="c1">// 18  bytes</span>
</code></pre></div></div>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="dl">"</span><span class="s2">नमस्ते</span><span class="dl">"</span><span class="p">.</span><span class="nx">length</span>                        <span class="c1">// 6   UTF-16 code units</span>
<span class="p">[...</span><span class="dl">"</span><span class="s2">नमस्ते</span><span class="dl">"</span><span class="p">].</span><span class="nx">length</span>                   <span class="c1">// 6   code points</span>
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">len</span><span class="p">(</span><span class="sh">"</span><span class="s">नमस्ते</span><span class="sh">"</span><span class="p">)</span>                          <span class="c1"># 6   code points
</span><span class="nf">len</span><span class="p">(</span><span class="sh">"</span><span class="s">नमस्ते</span><span class="sh">"</span><span class="p">.</span><span class="nf">encode</span><span class="p">())</span>                 <span class="c1"># 18  bytes
</span></code></pre></div></div>

<div class="language-go highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">len</span><span class="p">(</span><span class="s">"नमस्ते"</span><span class="p">)</span>                          <span class="c">// 18  bytes</span>
<span class="n">utf8</span><span class="o">.</span><span class="n">RuneCountInString</span><span class="p">(</span><span class="s">"नमस्ते"</span><span class="p">)</span>       <span class="c">// 6   code points</span>
</code></pre></div></div>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">"नमस्ते"</span><span class="nf">.len</span><span class="p">()</span>                         <span class="c1">// 18  bytes</span>
<span class="s">"नमस्ते"</span><span class="nf">.chars</span><span class="p">()</span><span class="nf">.count</span><span class="p">()</span>               <span class="c1">// 6   code points</span>
</code></pre></div></div>

<p>Java and JavaScript store strings as UTF-16 and report code units. Python stores code points and reports code points. Go and Rust store UTF-8 and report bytes. For Devanagari, the first three agree at 6, because every Devanagari code point is a single UTF-16 code unit.</p>

<p>The divergence between Java/JavaScript and Python shows up outside the BMP. For the single emoji <code class="language-plaintext highlighter-rouge">😀</code> (<code class="language-plaintext highlighter-rouge">U+1F600</code>), Java and JavaScript report 2, because it needs a surrogate pair; Python reports 1; Go and Rust report 4 bytes.</p>

<p>The more useful observation is that <em>none</em> of these numbers is 3, which is the number a Hindi reader would give for नमस्ते. Getting closer requires explicit grapheme segmentation:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">BreakIterator</span><span class="o">.</span><span class="na">getCharacterInstance</span><span class="o">()</span>   <span class="c1">// 4 on JDK 21 -- see above</span>
</code></pre></div></div>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">new</span> <span class="nx">Intl</span><span class="p">.</span><span class="nc">Segmenter</span><span class="p">(</span><span class="dl">"</span><span class="s2">hi</span><span class="dl">"</span><span class="p">,</span> <span class="p">{</span> <span class="na">granularity</span><span class="p">:</span> <span class="dl">"</span><span class="s2">grapheme</span><span class="dl">"</span> <span class="p">})</span>
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="n">regex</span>
<span class="n">regex</span><span class="p">.</span><span class="nf">findall</span><span class="p">(</span><span class="sa">r</span><span class="sh">"</span><span class="s">\X</span><span class="sh">"</span><span class="p">,</span> <span class="sh">"</span><span class="s">नमस्ते</span><span class="sh">"</span><span class="p">)</span>
</code></pre></div></div>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// unicode-segmentation crate</span>
<span class="s">"नमस्ते"</span><span class="nf">.graphemes</span><span class="p">(</span><span class="k">true</span><span class="p">)</span><span class="nf">.count</span><span class="p">()</span>
</code></pre></div></div>

<p>Even these depend on the ICU or Unicode data version, per the GB9c caveat above.</p>

<h2 id="normalization-two-ways-to-write-the-same-letter">Normalization: two ways to write the same letter</h2>

<p>Devanagari also has a normalization problem. The letter क़ (<code class="language-plaintext highlighter-rouge">qa</code>) can be written two ways:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>U+0958                    DEVANAGARI LETTER QA
U+0915 U+093C             KA + DEVANAGARI SIGN NUKTA
</code></pre></div></div>

<p>These are canonically equivalent<sup id="fnref:canonequiv"><a href="#fn:canonequiv" class="footnote" rel="footnote" role="doc-noteref">20</a></sup>. They must be treated as the same text by any conforming process, and they usually render identically. But they are different byte sequences, so <code class="language-plaintext highlighter-rouge">equals</code>, <code class="language-plaintext highlighter-rouge">==</code>, hash lookups, and database unique constraints will treat them as different unless the text is normalized first.</p>

<p>There is a trap here. <code class="language-plaintext highlighter-rouge">U+0958</code> through <code class="language-plaintext highlighter-rouge">U+095F</code> are on the Unicode composition exclusion list<sup id="fnref:compexclusion"><a href="#fn:compexclusion" class="footnote" rel="footnote" role="doc-noteref">21</a></sup>. NFC<sup id="fnref:nfc"><a href="#fn:nfc" class="footnote" rel="footnote" role="doc-noteref">22</a></sup> does not recompose them. Normalizing either form to NFC gives you <code class="language-plaintext highlighter-rouge">U+0915 U+093C</code>, the decomposed one. If you assumed NFC always produces the shortest sequence, this is a counterexample.</p>

<p>Normalization also reorders combining marks by canonical combining class<sup id="fnref:ccc"><a href="#fn:ccc" class="footnote" rel="footnote" role="doc-noteref">23</a></sup>. Nukta<sup id="fnref:nukta"><a href="#fn:nukta" class="footnote" rel="footnote" role="doc-noteref">24</a></sup> has <code class="language-plaintext highlighter-rouge">ccc=7</code>, virama has <code class="language-plaintext highlighter-rouge">ccc=9</code>, so a nukta typed after a virama gets reordered ahead of it:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>as typed : U+0915 U+094D U+093C     क + virama + nukta
NFC      : U+0915 U+093C U+094D     क + nukta + virama
</code></pre></div></div>

<p>Two sequences that differ only in the order the user typed them collapse to one form.</p>

<p>The practical rule: normalize at your system boundaries – on input, before storage, before comparison – and pick one form, usually NFC.</p>

<h2 id="sorting-is-a-separate-problem">Sorting is a separate problem</h2>

<p>Normalization fixes equality. It does not fix order, and binary comparison<sup id="fnref:collation"><a href="#fn:collation" class="footnote" rel="footnote" role="doc-noteref">25</a></sup> gets Devanagari order wrong in a way that is easy to miss.</p>

<p>The reason is where the nukta letters sit in the block. क is <code class="language-plaintext highlighter-rouge">U+0915</code>, ख is <code class="language-plaintext highlighter-rouge">U+0916</code>, ह is <code class="language-plaintext highlighter-rouge">U+0939</code>. But क़ has its own precomposed code point at <code class="language-plaintext highlighter-rouge">U+0958</code>, past the end of the consonant range. Sort by code point and क़ lands after every basic consonant, including ह.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                              compareTo   Collator(hi)
क  vs ख                              -1            -1
क  vs का                             -1            -1
का vs कि                             -1            -1
क़  vs ख                              +1            -1
क़  vs क+़                            +1             0
ड़  vs ढ                              +1            -1
</code></pre></div></div>

<p>The first three pairs agree, which is why this bug survives casual testing. Compare a few basic letters and binary order looks fine. The nukta letters are where it breaks, and the last row is worse than wrong order: two canonically equivalent spellings of the same letter compare as unequal.</p>

<p>Sorting a word list makes it concrete. The same word क़लम, written once with <code class="language-plaintext highlighter-rouge">U+0958</code> and once with <code class="language-plaintext highlighter-rouge">U+0915 U+093C</code>:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>String.compareTo        Collator(hi)
  कमल                     कमल
  कल                      कल
  क़लम   (U+0915…)         क़लम   (U+0958…)
  खत                      क़लम   (U+0915…)
  गाना                      खत
  क़लम   (U+0958…)         गाना
</code></pre></div></div>

<p>Binary order scatters the two spellings to positions three and six with unrelated words between them. The collator files them adjacent, both immediately after क.</p>

<p>One trap inside the fix. <code class="language-plaintext highlighter-rouge">Collator.getInstance(...).getDecomposition()</code> returns <code class="language-plaintext highlighter-rouge">NO_DECOMPOSITION</code> by default. The Hindi collator handles <code class="language-plaintext highlighter-rouge">U+0958</code> anyway, because the JDK ships real <code class="language-plaintext highlighter-rouge">hi</code> rules – <code class="language-plaintext highlighter-rouge">Collator.getInstance(Locale.ROOT)</code> returns <code class="language-plaintext highlighter-rouge">+1</code> for that pair rather than <code class="language-plaintext highlighter-rouge">0</code>. Do not rely on the default. Set <code class="language-plaintext highlighter-rouge">CANONICAL_DECOMPOSITION</code> explicitly, and pick the locale deliberately.</p>

<h2 id="what-the-shaping-engine-does">What the shaping engine does</h2>

<p>Between code points and glyphs sits a shaper: HarfBuzz<sup id="fnref:harfbuzz"><a href="#fn:harfbuzz" class="footnote" rel="footnote" role="doc-noteref">26</a></sup> on most Linux and web stacks, DirectWrite/Uniscribe on Windows, CoreText on Apple platforms. For Devanagari it runs a script-specific model that, roughly:</p>

<ol>
  <li>Splits the run into syllable clusters.</li>
  <li>Identifies the base consonant of each cluster.</li>
  <li>Applies OpenType<sup id="fnref:opentype"><a href="#fn:opentype" class="footnote" rel="footnote" role="doc-noteref">27</a></sup> features from the font – <code class="language-plaintext highlighter-rouge">nukt</code>, <code class="language-plaintext highlighter-rouge">akhn</code>, <code class="language-plaintext highlighter-rouge">rphf</code>, <code class="language-plaintext highlighter-rouge">blwf</code>, <code class="language-plaintext highlighter-rouge">half</code>, <code class="language-plaintext highlighter-rouge">pstf</code>, <code class="language-plaintext highlighter-rouge">vatu</code>, <code class="language-plaintext highlighter-rouge">cjct</code> – to form half-forms, conjuncts and below-base forms.</li>
  <li>Reorders pre-base matras such as ि so they sit to the left of the base glyph.</li>
  <li>Applies positioning features and produces final glyph IDs with offsets.</li>
</ol>

<p>Step 4 is the answer to the कि puzzle from the start of the post. The reordering is a rendering operation, performed by the shaper, using rules that depend on the font. It never touches the stored text.</p>

<p>This separation is also why Unicode does not encode every conjunct. Devanagari can form a very large number of consonant combinations. Encoding each visible shape separately would merge two different questions – <em>what text is this</em> and <em>how should this text look</em> – into one, and would make the encoding dependent on typographic fashion. Unicode answers the first question. Fonts and shapers answer the second.</p>

<h2 id="where-this-actually-bites">Where this actually bites</h2>

<p>The consequences are ordinary and frequent.</p>

<p><strong>Truncation.</strong> Cutting a string at a fixed byte or code-unit offset can split a UTF-8 sequence, or split a cluster and leave a dangling virama or matra. Truncate on grapheme cluster boundaries, or at minimum on code point boundaries.</p>

<p><strong>Cursor movement and deletion.</strong> Pressing backspace after typing क्ष should not leave क् behind. Editors need cluster-aware navigation. Note that for Indic scripts, the caret positions users expect are sometimes finer than grapheme cluster boundaries, which UAX #29 acknowledges as a legitimate tailoring.</p>

<p><strong>Length validation.</strong> “Maximum 20 characters” needs a definition. Take the sentence भारत एक महान देश है। – that is 52 UTF-8 bytes, 20 UTF-16 code units, 20 code points, 16 grapheme clusters, and five words. Five plausible answers, and a <code class="language-plaintext highlighter-rouge">varchar(20)</code> column accepts or rejects it depending on which one the database counts. PostgreSQL <code class="language-plaintext highlighter-rouge">varchar(n)</code> counts code points, MySQL <code class="language-plaintext highlighter-rouge">utf8mb4</code> counts characters, Oracle <code class="language-plaintext highlighter-rouge">VARCHAR2</code> counts bytes or characters depending on how the column was declared.</p>

<p><strong>Comparison and search.</strong> Without normalization, canonically equivalent strings fail to match. Without a collator, sort order is wrong for the nukta letters. Substring search on code point offsets can match across a cluster boundary.</p>

<p><strong>Word segmentation.</strong> <code class="language-plaintext highlighter-rouge">BreakIterator.getWordInstance</code> does not treat the danda <code class="language-plaintext highlighter-rouge">U+0964</code><sup id="fnref:danda"><a href="#fn:danda" class="footnote" rel="footnote" role="doc-noteref">28</a></sup> as a word boundary, so the last token of a Hindi sentence comes back as <code class="language-plaintext highlighter-rouge">है।</code> with the punctuation attached. Sentence-ending punctuation that is not a full stop needs handling you would not write for English.</p>

<p><strong>Reversal.</strong> Reversing a string by code point turns नमस्ते into a sequence that no longer renders as valid text. Reverse by grapheme cluster or not at all.</p>

<p><strong>Regular expressions.</strong> <code class="language-plaintext highlighter-rouge">.</code> matches a code point in most engines, not a cluster. Character classes written for Latin text do not carry over.</p>

<h2 id="the-point">The point</h2>

<p>When we look at क्ष our eyes report one thing. The computer is handling three code points and nine bytes, and reports either one cluster or two depending on which segmentation library got linked. When we look at कि we see the vowel first, but it is stored second.</p>

<p>Neither representation is wrong. They are different layers of the same writing system. Unicode encodes the logical text, an encoding form turns it into bytes, a shaper interprets it, a font supplies the glyphs, and the renderer produces pixels. What appears on the screen is the end of that pipeline, not a picture of what is in memory.</p>

<hr />

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:unicode">
      <p>A character encoding standard maintained by the Unicode Consortium, covering the writing systems of the world. Version 1.0 shipped in 1991; releases are now roughly annual. It defines both a repertoire of characters and a large set of per-character properties. <a href="#fnref:unicode" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:ascii">
      <p>American Standard Code for Information Interchange, 1963. Seven bits, 128 positions, of which 95 are printable. Enough for unaccented English and effectively nothing else. <a href="#fnref:ascii" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:codepoint">
      <p>The written form is <code class="language-plaintext highlighter-rouge">U+</code> followed by at least four hexadecimal digits, so <code class="language-plaintext highlighter-rouge">U+0915</code> is decimal 2325. The notation is fixed by the standard and is used regardless of how the value is stored in memory. <a href="#fnref:codepoint" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:devanagari">
      <p>The script used to write Hindi, Marathi, Nepali, Sanskrit and others. It is an abugida<sup id="fnref:abugida"><a href="#fn:abugida" class="footnote" rel="footnote" role="doc-noteref">29</a></sup> rather than an alphabet, which is the root of most of what follows. <a href="#fnref:devanagari" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:matra">
      <p>A vowel sign, or <em>matra</em>, is a mark attached to a consonant to replace its inherent vowel<sup id="fnref:inherentvowel:1"><a href="#fn:inherentvowel" class="footnote" rel="footnote" role="doc-noteref">10</a></sup>. Matras attach above, below, before or after the base consonant depending on which vowel they represent. <code class="language-plaintext highlighter-rouge">ि</code> is one of the ones that attaches before. <a href="#fnref:matra" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:shaping">
      <p>Also called text layout. The stage that turns a sequence of characters into a sequence of positioned glyphs by applying the font’s substitution and positioning rules. It is script-specific: Devanagari, Arabic and Latin take different code paths. <a href="#fnref:shaping" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:glyph">
      <p>A font contains glyphs, not characters. One character may map to several glyphs, several characters may map to one glyph, and the same character may map to different glyphs depending on its neighbours. <a href="#fnref:glyph" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:conjunct">
      <p>In Devanagari, a <em>samyuktakshar</em> – two or more consonants written as a single joined form with no vowel between them, the vowel having been suppressed by a virama<sup id="fnref:virama:1"><a href="#fn:virama" class="footnote" rel="footnote" role="doc-noteref">9</a></sup>. Hindi uses a few hundred in practice; the number that can be formed is far larger. <a href="#fnref:conjunct" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:virama">
      <p>Called <em>halant</em> in Hindi. Written <code class="language-plaintext highlighter-rouge">्</code> and encoded at <code class="language-plaintext highlighter-rouge">U+094D</code>. <a href="#fnref:virama" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:virama:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:inherentvowel">
      <p>Every Devanagari consonant letter carries an implicit <em>a</em>. क alone reads as <em>ka</em>, not <em>k</em>. This is the defining property of an abugida<sup id="fnref:abugida:1"><a href="#fn:abugida" class="footnote" rel="footnote" role="doc-noteref">29</a></sup>, and the reason a separate mark is needed to cancel it. <a href="#fnref:inherentvowel" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:inherentvowel:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:halfform">
      <p>A reduced form of a consonant used inside conjuncts<sup id="fnref:conjunct:1"><a href="#fn:conjunct" class="footnote" rel="footnote" role="doc-noteref">8</a></sup>, typically the full letter with its vertical stem removed. क् as a half-form joins directly to the letter that follows. <a href="#fnref:halfform" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:utf">
      <p>An encoding form specifies how a code point becomes bytes. UTF-8 uses one to four 8-bit units and dominates on disk and on the wire. UTF-16 uses one or two 16-bit units and is what Java, JavaScript, C# and the Windows API use in memory. UTF-32 uses one 32-bit unit per code point and is rare outside internal buffers. <a href="#fnref:utf" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:nearly">
      <p><em>Nearly</em> is an important distinction. Unicode 15.0 added Devanagari Extended-A at <code class="language-plaintext highlighter-rouge">U+11B00</code>–<code class="language-plaintext highlighter-rouge">U+11B5F</code>, ten characters for Vedic and Sanskrit editorial marks. Those are above <code class="language-plaintext highlighter-rouge">U+FFFF</code>, so they take a surrogate pair<sup id="fnref:surrogate"><a href="#fn:surrogate" class="footnote" rel="footnote" role="doc-noteref">30</a></sup> in UTF-16 and four bytes in UTF-8. They are the only Devanagari characters where Java’s <code class="language-plaintext highlighter-rouge">length()</code> and Python’s <code class="language-plaintext highlighter-rouge">len()</code> disagree. <a href="#fnref:nearly" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:bmp">
      <p>The first 65,536 code points, <code class="language-plaintext highlighter-rouge">U+0000</code> to <code class="language-plaintext highlighter-rouge">U+FFFF</code>. Unicode has 17 planes; everything above the BMP is called supplementary. The split matters only for UTF-16<sup id="fnref:utf:1"><a href="#fn:utf" class="footnote" rel="footnote" role="doc-noteref">12</a></sup>, where supplementary characters need two code units instead of one. <a href="#fnref:bmp" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:uax29">
      <p>Unicode Standard Annex #29, <em>Unicode Text Segmentation</em>. It specifies boundary rules for grapheme clusters, words and sentences, and explicitly permits implementations to tailor them per language. <a href="#fnref:uax29" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:gb9c">
      <p>Grapheme break rule 9c of UAX #29<sup id="fnref:uax29:1"><a href="#fn:uax29" class="footnote" rel="footnote" role="doc-noteref">15</a></sup>, added in Unicode 15.1. The rules run GB1 through GB13; 9c was inserted specifically to stop Indic conjuncts<sup id="fnref:conjunct:2"><a href="#fn:conjunct" class="footnote" rel="footnote" role="doc-noteref">8</a></sup> splitting, which they had done since the rules were first written. <a href="#fnref:gb9c" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:incb">
      <p>A character property introduced alongside GB9c, with values <code class="language-plaintext highlighter-rouge">Consonant</code>, <code class="language-plaintext highlighter-rouge">Linker</code>, <code class="language-plaintext highlighter-rouge">Extend</code> and <code class="language-plaintext highlighter-rouge">None</code>. The virama<sup id="fnref:virama:2"><a href="#fn:virama" class="footnote" rel="footnote" role="doc-noteref">9</a></sup> of Devanagari, Bengali, Gujarati, Malayalam, Oriya and Telugu is classified as <code class="language-plaintext highlighter-rouge">Linker</code>. <a href="#fnref:incb" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:breakiterator">
      <p>The JDK’s segmentation API, in <code class="language-plaintext highlighter-rouge">java.text</code>. It predates ICU<sup id="fnref:icu:1"><a href="#fn:icu" class="footnote" rel="footnote" role="doc-noteref">19</a></sup> and ships its own rule tables, which is why its behaviour tracks the JDK release rather than the Unicode version of the character data. <a href="#fnref:breakiterator" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:icu">
      <p>International Components for Unicode, the reference implementation of most of the standard’s algorithms, including the segmentation rules of UAX #29<sup id="fnref:uax29:2"><a href="#fn:uax29" class="footnote" rel="footnote" role="doc-noteref">15</a></sup> and the collation algorithm<sup id="fnref:collation:1"><a href="#fn:collation" class="footnote" rel="footnote" role="doc-noteref">25</a></sup>. ICU4J is the Java build, ICU4C serves C and C++. Most platforms with correct Unicode behaviour have ICU somewhere underneath. <a href="#fnref:icu" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:icu:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:canonequiv">
      <p>Two sequences are canonically equivalent when the standard declares them to represent the same abstract text, and conforming software must not distinguish them. This is a stronger claim than “they look the same” and a weaker one than “they are the same bytes.” <a href="#fnref:canonequiv" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:compexclusion">
      <p>A list in the standard of characters that have a canonical decomposition but must not be recomposed by NFC<sup id="fnref:nfc:1"><a href="#fn:nfc" class="footnote" rel="footnote" role="doc-noteref">22</a></sup>. It exists largely for compatibility with older national standards that encoded such characters directly. <a href="#fnref:compexclusion" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:nfc">
      <p>Unicode defines four normalization forms. NFD decomposes. NFC decomposes and then recomposes. All four map canonically equivalent<sup id="fnref:canonequiv:1"><a href="#fn:canonequiv" class="footnote" rel="footnote" role="doc-noteref">20</a></sup> sequences to the same output. NFKD and NFKC additionally fold compatibility differences such as ligatures and superscripts, and are lossy. NFC is the usual choice for storage and comparison. <a href="#fnref:nfc" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:nfc:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:ccc">
      <p>A numeric property from 0 to 254 that fixes the relative order of combining marks around a base character. Marks sharing a class keep the order they were typed in; marks with different classes are sorted into class order during normalization<sup id="fnref:nfc:2"><a href="#fn:nfc" class="footnote" rel="footnote" role="doc-noteref">22</a></sup>. <a href="#fnref:ccc" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:nukta">
      <p>A dot written below a consonant, <code class="language-plaintext highlighter-rouge">U+093C</code>, that modifies its sound. It is used mainly for consonants borrowed from Persian and Arabic. Eight nukta combinations also have precomposed code points, all of them on the composition exclusion list<sup id="fnref:compexclusion:1"><a href="#fn:compexclusion" class="footnote" rel="footnote" role="doc-noteref">21</a></sup>, which is the source of the trouble described here. <a href="#fnref:nukta" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:collation">
      <p>Collation is language-aware sorting. Binary comparison orders strings by numeric value, which reflects the order characters happened to be added to the standard rather than any language’s alphabet. A collator also folds canonically equivalent<sup id="fnref:canonequiv:2"><a href="#fn:canonequiv" class="footnote" rel="footnote" role="doc-noteref">20</a></sup> sequences together, which binary comparison cannot. The Unicode Collation Algorithm is specified separately, in UTS #10. <a href="#fnref:collation" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:collation:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:harfbuzz">
      <p>The open-source shaping<sup id="fnref:shaping:1"><a href="#fn:shaping" class="footnote" rel="footnote" role="doc-noteref">6</a></sup> engine used by Chrome, Firefox, Android, GNOME and LibreOffice. DirectWrite and CoreText are the Microsoft and Apple equivalents. <a href="#fnref:harfbuzz" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:opentype">
      <p>The font format, and the tag-based feature system inside it. Each four-letter tag names a substitution or positioning rule the shaper may apply. <code class="language-plaintext highlighter-rouge">cjct</code> forms conjuncts<sup id="fnref:conjunct:3"><a href="#fn:conjunct" class="footnote" rel="footnote" role="doc-noteref">8</a></sup>, <code class="language-plaintext highlighter-rouge">half</code> forms half-forms<sup id="fnref:halfform:1"><a href="#fn:halfform" class="footnote" rel="footnote" role="doc-noteref">11</a></sup>, <code class="language-plaintext highlighter-rouge">rphf</code> handles the reph, and so on. <a href="#fnref:opentype" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:danda">
      <p><code class="language-plaintext highlighter-rouge">U+0964</code>, the full stop of Devanagari and several other Indic scripts. <code class="language-plaintext highlighter-rouge">U+0965</code>, the double danda, marks a larger break – historically the end of a verse. <a href="#fnref:danda" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:abugida">
      <p>A writing system in which each consonant letter carries an inherent vowel<sup id="fnref:inherentvowel:2"><a href="#fn:inherentvowel" class="footnote" rel="footnote" role="doc-noteref">10</a></sup>, modified or cancelled by attached marks, rather than one in which consonants and vowels are equal, independent letters. Devanagari, Bengali, Tamil, Thai and Ethiopic are abugidas. Latin, Greek and Cyrillic are alphabets. <a href="#fnref:abugida" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:abugida:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:surrogate">
      <p>A pair of code units drawn from <code class="language-plaintext highlighter-rouge">U+D800</code>–<code class="language-plaintext highlighter-rouge">U+DBFF</code> and <code class="language-plaintext highlighter-rouge">U+DC00</code>–<code class="language-plaintext highlighter-rouge">U+DFFF</code>, used together by UTF-16<sup id="fnref:utf:2"><a href="#fn:utf" class="footnote" rel="footnote" role="doc-noteref">12</a></sup> to represent one supplementary code point<sup id="fnref:bmp:1"><a href="#fn:bmp" class="footnote" rel="footnote" role="doc-noteref">14</a></sup>. The halves are not valid characters on their own, which is why splitting a UTF-16 string at an arbitrary offset can produce something unencodable. <a href="#fnref:surrogate" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Computer Science" /><category term="unicode" /><category term="devanagari" /><summary type="html"><![CDATA[This post looks at how Devanagari actually works in Unicode]]></summary></entry><entry><title type="html">Semantic Networks as Search Spaces</title><link href="https://systemhalted.in/2026/07/24/semantic-networks-as-search-spaces/" rel="alternate" type="text/html" title="Semantic Networks as Search Spaces" /><published>2026-07-24T14:30:00+00:00</published><updated>2026-07-24T14:30:00+00:00</updated><id>https://systemhalted.in/2026/07/24/semantic-networks-as-search-spaces</id><content type="html" xml:base="https://systemhalted.in/2026/07/24/semantic-networks-as-search-spaces/"><![CDATA[<p>A semantic network is a graph-based system to represent knowledge. It is a mind-map, that uses nodes to represent concepts and edges to define the relationship.</p>

<p>A semantic network is useful because it forces you to say what the world contains and how one state can become another.</p>

<p>That sounds simple, but it is the hard part of many AI problems. Before an agent can search, reason, or explain a path, it needs a representation of the situation. The representation does not need to contain everything. In fact, a good representation usually leaves out most things. It needs to contain the distinctions that matter for the task.</p>

<p>Once those distinctions are explicit, the problem starts to look like a graph.</p>

<p>Nodes are states. Edges are transformations. A path through the network becomes a candidate solution. The agent’s job is no longer to “think” in some vague sense. Its job is to move through the represented space in a disciplined way.</p>

<h2 id="generate-and-test">Generate and test</h2>

<p>The generate-and-test pattern is one of the simplest ways to use that structure.</p>

<p>The generator proposes a possible next state. The tester checks whether that state is legal, useful, or final. If the state does not work, the system generates another candidate. If it does work, the system keeps it and continues.</p>

<p>That pattern is easy to underestimate because it sounds brute-force. But the important design question is not only how candidates are generated. It is what the system remembers.</p>

<p>If the agent does not remember prior states, it can loop. It can regenerate the same state again and again, wasting time and appearing less intelligent than it really is. In a graph, memory is not a luxury. It is part of the search machinery.</p>

<p>So the generator has at least two responsibilities:</p>

<ul>
  <li>Produce plausible next states.</li>
  <li>Avoid returning to states the system has already explored.</li>
</ul>

<p>The tester also has at least two responsibilities:</p>

<ul>
  <li>Reject invalid transitions.</li>
  <li>Recognize when the current state satisfies the goal.</li>
</ul>

<p>Once those responsibilities are separated, the AI problem becomes easier to reason about. You can improve the generator without changing the tester. You can make the tester stricter without rewriting the whole search.</p>

<p><img src="/assets/images/2026-07-24-semantic-network-generate-and-test.svg" alt="A diagram showing Generate and Test - control cycle and the state transitions" /></p>

<h2 id="why-representation-matters">Why representation matters</h2>

<p>The value of a semantic network is not the diagram itself. The value is the discipline it imposes.</p>

<p>It asks:</p>

<ul>
  <li>What counts as a state?</li>
  <li>What relations connect states?</li>
  <li>Which transformations are legal?</li>
  <li>Which state is initial?</li>
  <li>Which state is final?</li>
  <li>What must be remembered to avoid cycling?</li>
</ul>

<p>These questions show up everywhere in software, not just in AI courses. Workflow engines, build systems, dependency graphs, compilers, routers, game engines, and planning tools all depend on some version of this idea. A system behaves better when its state space is made explicit.</p>

<h2 id="the-practical-lesson">The practical lesson</h2>

<p>Many AI discussions jump too quickly to model capability. But for knowledge-based AI, the representation often matters more than the algorithm.</p>

<p>A weak representation makes even a clever search look confused. A strong representation can make a simple generate-and-test loop surprisingly effective.</p>

<p>So a lot of the work in a knowledge-based system happens before the search runs at all. It happens when you decide what the agent is allowed to see.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="AI" /><category term="Computer Science" /><category term="ai" /><category term="computer-science" /><category term="knowledge-representation" /><category term="search" /><category term="opinion" /><summary type="html"><![CDATA[A short note on semantic networks, generate-and-test search, and why explicit state representation matters in knowledge-based AI.]]></summary></entry><entry><title type="html">My Naming Philosophy</title><link href="https://systemhalted.in/2026/07/23/my-naming-philosophy/" rel="alternate" type="text/html" title="My Naming Philosophy" /><published>2026-07-23T07:00:00+00:00</published><updated>2026-07-23T07:00:00+00:00</updated><id>https://systemhalted.in/2026/07/23/my-naming-philosophy</id><content type="html" xml:base="https://systemhalted.in/2026/07/23/my-naming-philosophy/"><![CDATA[<p>I spend more time on names than on most other parts of writing code. Not because a well-chosen name is pleasant to read, though it is, but because naming forces the same decisions that design does: what it is, what it holds, who it is for. When I cannot name something, it is usually because I have not decided what it is yet.</p>

<p>My rules for naming have settled into a small set over the years. The core is <a href="https://martinfowler.com/bliki/BeckDesignRules.html">Kent Beck’s four rules of simple design</a>: passes the tests, reveals intention, no duplication, fewest elements. I first learned these rules from my mentor, <a href="https://www.linkedin.com/in/jacmorel">Jacques Morel</a>. Beck stated them for a design as a whole. I find they apply, almost without translation, to naming a variable in code or a field in an API schema. The rest comes from Strunk’s <em>The Elements of Style</em> and a short piece by Russ Cox. Here is how I read each rule when the thing being designed is a name.</p>

<h2 id="runs-the-tests">Runs the tests</h2>

<p>A declaration is a claim about what a variable will hold, and the type is the only part of that claim anything ever checks. The type should be able to test the value the variable must hold. Not everything is a <code class="language-plaintext highlighter-rouge">String</code>.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">String</span> <span class="n">email</span><span class="o">;</span>   <span class="c1">// nothing checks that this is an email</span>
<span class="nc">Email</span> <span class="n">email</span><span class="o">;</span>    <span class="c1">// construction fails unless the value parses</span>
</code></pre></div></div>

<p>A bare <code class="language-plaintext highlighter-rouge">String</code> passes every possible value, which means it tests nothing. An <code class="language-plaintext highlighter-rouge">Email</code> type that validates in its constructor turns every assignment into a test, and that test also runs in production, on every value the field receives. The same holds in an API definition: <code class="language-plaintext highlighter-rouge">type: string</code> promises nothing, while <code class="language-plaintext highlighter-rouge">format</code>, <code class="language-plaintext highlighter-rouge">enum</code>, <code class="language-plaintext highlighter-rouge">pattern</code>, and range constraints are the schema’s way of testing values before they reach your code. I wrote earlier about <a href="/2026/06/21/types-check-shape-tests-check-behaviour/">where types end and tests begin</a>; this is the naming-side consequence. Choosing a type is part of choosing a name, because both are claims about the value.</p>

<h2 id="reveals-intention">Reveals intention</h2>

<p>The variable in code and the field in an API or schema must say what it is for. If a reader has to look at usages to work out what a field means, the name has failed. This matters even more in an API than in code, because the consumer of a schema cannot read your implementation. They have the name, the type, and whatever description you wrote, and most, however, will read no further than the name.</p>

<h2 id="no-duplication">No duplication</h2>

<p>A name should not repeat what its surroundings already say. <code class="language-plaintext highlighter-rouge">order.orderId</code> says <em>order</em> twice; inside an <code class="language-plaintext highlighter-rouge">Order</code>, the field is just <code class="language-plaintext highlighter-rouge">id</code>. Suffixes like <code class="language-plaintext highlighter-rouge">Value</code>, <code class="language-plaintext highlighter-rouge">Flag</code>, <code class="language-plaintext highlighter-rouge">String</code>, and <code class="language-plaintext highlighter-rouge">Data</code> repeat the type, and the type is already visible in the declaration. I made the same argument about <code class="language-plaintext highlighter-rouge">Request</code> and <code class="language-plaintext highlighter-rouge">Response</code> suffixes on API models in <a href="/2025/12/15/vibe-coding-and-baby-genius/">Vibe Coding and the Baby Genius Problem</a>. Say everything once, and only once – that holds for the words inside a name as much as for the code around it.</p>

<h2 id="fewest-elements">Fewest elements</h2>

<p>Define only what you need. Once a field is in a schema, consumers start depending on it, and removing it becomes a breaking change. A field added because someone might need it later still has to be named, documented, validated, and migrated, without any current use to justify that work. If nothing reads it today, leave it out.</p>

<h2 id="omit-needless-words">Omit needless words</h2>

<p>Strunk’s <a href="https://www.bartleby.com/lit-hub/the-elements-of-style/iii-elementary-principles-of-composition/#13">rule 13</a> says a sentence should contain no unnecessary words. Applied to a name: <code class="language-plaintext highlighter-rouge">customerEmailAddressString</code> contains one useful word. <code class="language-plaintext highlighter-rouge">String</code> repeats the type, <code class="language-plaintext highlighter-rouge">Address</code> repeats what <em>email</em> already implies, and what remains after striking them is <code class="language-plaintext highlighter-rouge">customerEmail</code> – or, inside a <code class="language-plaintext highlighter-rouge">Customer</code>, just <code class="language-plaintext highlighter-rouge">email</code>.</p>

<h2 id="length-follows-scope">Length follows scope</h2>

<p>Russ Cox <a href="https://research.swtch.com/names">puts it</a> as: a name’s length should not exceed its information content. A loop index that lives for three lines is <code class="language-plaintext highlighter-rouge">i</code>, and making it <code class="language-plaintext highlighter-rouge">loopIndexCounter</code> adds letters without adding information. A public field, read far from its declaration by people who never see the surrounding code, has to carry more.</p>

<p>These rules usually agree. When they conflict, I pick whichever name is easier for the reader. In a follow-up post I will take a badly named API model and apply these rules to it one pass at a time.</p>

<h2 id="parting-thoughts">Parting Thoughts</h2>

<p>I will just end with a thought from Donald Knuth. In his article introducing literate programming, he said:</p>

<blockquote>
  <p>…The practitioner of literate programming can be regarded as an essayist, whose main concern is with exposition and excellence of style. Such an author, with thesaurus in hand, chooses the names of variables carefully and explains what each variable means…</p>
</blockquote>

<p>And this has been my endeavor.</p>

<figure class="post-figure">
  <img src="/assets/images/featured/2026-07-23-my-naming-philosophy.svg" alt="Poster titled &quot;Naming&quot; listing six rules, each paired with a code example where the needless part of a name is struck out in red: String email becomes Email email, data becomes pendingInvoices, order.orderId becomes order.id, extraMetadata becomes nothing, isActiveFlag becomes isActive, loopIndexCounter becomes i." />
  <figcaption>Six rules for naming: four from Kent Beck’s rules of simple design, one from Strunk, one from Russ Cox. Each rule shown as the reduction it produces.</figcaption>
</figure>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Software Engineering" /><category term="Computer Science" /><category term="naming" /><category term="api-design" /><category term="java" /><category term="design" /><category term="software" /><category term="literate-programming" /><summary type="html"><![CDATA[The rules I follow when naming variables, API fields, and schema elements. Most of it is borrowed from Kent Beck, Strunk, and Russ Cox; the rest is how I read their rules when the thing being named is a variable rather than a design.]]></summary></entry><entry><title type="html">Removing a Package and Purging Its Traces</title><link href="https://systemhalted.in/2026/07/23/removing-a-package-and-purging-its-traces/" rel="alternate" type="text/html" title="Removing a Package and Purging Its Traces" /><published>2026-07-23T05:30:00+00:00</published><updated>2026-07-23T05:30:00+00:00</updated><id>https://systemhalted.in/2026/07/23/removing-a-package-and-purging-its-traces</id><content type="html" xml:base="https://systemhalted.in/2026/07/23/removing-a-package-and-purging-its-traces/"><![CDATA[<p>After <a href="/2026/07/22/running-ghostty-on-a-2012-gpu/">giving up on Ghostty</a> on
this machine, I uninstalled it. The removal itself is one command, but
checking that it actually happened turned up the parts of the Debian package
lifecycle that are easy to skip past: the difference between removing and
purging, and the package states dpkg reports along the way. This post walks
through it with the real outputs from that removal.</p>

<h2 id="finding-out-how-the-package-was-installed">Finding out how the package was installed</h2>

<p>Removal starts with knowing what installed the file you can see:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ which ghostty
/usr/bin/ghostty
$ dpkg -S /usr/bin/ghostty
ghostty: /usr/bin/ghostty
$ apt list --installed 2&gt;/dev/null | grep ghostty
ghostty/now 1.3.1-0~ppa2 amd64 [installed,local]
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">dpkg -S</code> maps a file back to the package that owns it, so this is a real
apt/dpkg package, not a manually copied binary or a snap.<sup id="fnref:dpkg"><a href="#fn:dpkg" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> The
<code class="language-plaintext highlighter-rouge">[installed,local]</code> marker says the package is installed but no configured
repository offers it anymore — the PPA it came from is no longer in
<code class="language-plaintext highlighter-rouge">/etc/apt/sources.list.d/</code>, so apt considers it a local package with no
update source.</p>

<p>Before removing, the package shows in dpkg’s database like this:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ dpkg -l ghostty | tail -1
ii  ghostty        1.3.1-0~ppa2 amd64        Fast, feature-rich, and cross-platform terminal emulator.
</code></pre></div></div>

<p>The two letters at the start are the package state. The first letter is the
desired state — what you asked for — and the second is the current state.
<code class="language-plaintext highlighter-rouge">ii</code> means desired “install”, currently “installed”: the normal state of an
installed package.<sup id="fnref:states"><a href="#fn:states" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<h2 id="remove">Remove</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ sudo apt remove ghostty
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">apt remove</code> deletes the package’s files but keeps its conffiles —
configuration files, typically under <code class="language-plaintext highlighter-rouge">/etc</code>, that dpkg tracks so your edits
survive upgrades and reinstalls.<sup id="fnref:conffiles"><a href="#fn:conffiles" class="footnote" rel="footnote" role="doc-noteref">3</a></sup> Keeping them on removal is
deliberate: if you reinstall the package later, your configuration is still
there.</p>

<h2 id="confirm">Confirm</h2>

<p>Two checks. First, the binary is gone:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ which ghostty
$
</code></pre></div></div>

<p>Second, the state in dpkg’s database changed:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ dpkg -l ghostty | tail -1
rc  ghostty        1.3.1-0~ppa2 amd64        Fast, feature-rich, and cross-platform terminal emulator.
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">rc</code> reads as desired “remove”, currently “config-files”: the package is
removed, but its conffiles are still on disk and dpkg still has a record of
it.<sup id="fnref:states:1"><a href="#fn:states" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> This is why a removed package keeps appearing in <code class="language-plaintext highlighter-rouge">dpkg -l</code>
output — the entry is not a leftover installation, just the retained
configuration. <code class="language-plaintext highlighter-rouge">dpkg -L ghostty</code> lists exactly which files remain.</p>

<h2 id="purge">Purge</h2>

<p>To drop the conffiles and the database record too:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ sudo apt purge ghostty
</code></pre></div></div>

<p>Purge works both on installed packages (it removes and purges in one step)
and on packages already in the <code class="language-plaintext highlighter-rouge">rc</code> state. Afterward the package is gone from
the database entirely:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ dpkg -l ghostty
dpkg-query: no packages found matching ghostty
</code></pre></div></div>

<p>That is the end state: no files, no conffiles, no record.</p>

<p>If the package pulled in dependencies nothing else uses, <code class="language-plaintext highlighter-rouge">sudo apt
autoremove</code> clears those as well; apt prints the candidates at the end of the
remove step.</p>

<h2 id="what-the-package-manager-will-not-clean">What the package manager will not clean</h2>

<p>Everything above covers only files the package installed. Debian packages do
not write to home directories, so anything the application or you created
there stays after a purge. For Ghostty on this machine that was:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">~/.config/ghostty/</code> — the application’s own configuration</li>
  <li><code class="language-plaintext highlighter-rouge">~/.local/share/applications/com.mitchellh.ghostty.desktop</code> — a user-level
desktop entry I had added to override the launch command</li>
  <li>an <code class="language-plaintext highlighter-rouge">alias ghostty=...</code> line in <code class="language-plaintext highlighter-rouge">~/.bashrc</code> and <code class="language-plaintext highlighter-rouge">~/.zshrc</code></li>
</ul>

<p>The generic checklist after purging a package: its directory under
<code class="language-plaintext highlighter-rouge">~/.config/</code> and <code class="language-plaintext highlighter-rouge">~/.local/share/</code>, caches under <code class="language-plaintext highlighter-rouge">~/.cache/</code>, aliases or
environment variables in shell rc files, and — if you added one for the
package — the repository entry under <code class="language-plaintext highlighter-rouge">/etc/apt/sources.list.d/</code>.</p>

<p>A final check that nothing is left:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ which ghostty
$ dpkg -l ghostty
dpkg-query: no packages found matching ghostty
$ grep -ri ghostty ~/.bashrc ~/.zshrc ~/.config ~/.local/share/applications
$
</code></pre></div></div>

<h2 id="references">References</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:dpkg">
      <p><a href="https://man7.org/linux/man-pages/man1/dpkg.1.html">dpkg(1)</a> — <code class="language-plaintext highlighter-rouge">-S</code> (search for a filename in installed packages), <code class="language-plaintext highlighter-rouge">-l</code> (list packages), <code class="language-plaintext highlighter-rouge">-L</code> (list a package’s files). The listing and searching are done by <a href="https://man7.org/linux/man-pages/man1/dpkg-query.1.html">dpkg-query(1)</a>, which dpkg calls for these options. <a href="#fnref:dpkg" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:states">
      <p>The state abbreviations are documented in <a href="https://man7.org/linux/man-pages/man1/dpkg.1.html">dpkg(1)</a> under <code class="language-plaintext highlighter-rouge">-l</code>: the first character is the desired action (<strong>i</strong>nstall, <strong>r</strong>emove, <strong>p</strong>urge, <strong>h</strong>old), the second the package status (<strong>i</strong>nstalled, <strong>c</strong>onfig-files, <strong>n</strong>ot-installed, and others). <code class="language-plaintext highlighter-rouge">dpkg -l</code> prints a header decoding both columns. <a href="#fnref:states" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:states:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:conffiles">
      <p><a href="https://manpages.debian.org/stable/apt/apt.8.en.html">apt(8)</a> and <a href="https://manpages.debian.org/stable/apt/apt-get.8.en.html">apt-get(8)</a> define <code class="language-plaintext highlighter-rouge">remove</code> (keep configuration) versus <code class="language-plaintext highlighter-rouge">purge</code> (remove everything). Conffile handling — which files qualify and how modified ones are preserved — is Debian Policy, <a href="https://www.debian.org/doc/debian-policy/ch-files.html">chapter 10.7</a>. <a href="#fnref:conffiles" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="linux" /><category term="ubuntu" /><category term="debian" /><category term="apt" /><category term="dpkg" /><summary type="html"><![CDATA[Removing Ghostty from Ubuntu turned into a walkthrough of the Debian package lifecycle - apt remove, the ii and rc states in dpkg, apt purge, and the per-user files no package manager will clean for you.]]></summary></entry><entry><title type="html">Running Ghostty on a 2012 GPU</title><link href="https://systemhalted.in/2026/07/23/running-ghostty-on-a-2012-gpu/" rel="alternate" type="text/html" title="Running Ghostty on a 2012 GPU" /><published>2026-07-23T00:00:00+00:00</published><updated>2026-07-23T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/23/running-ghostty-on-a-2012-gpu</id><content type="html" xml:base="https://systemhalted.in/2026/07/23/running-ghostty-on-a-2012-gpu/"><![CDATA[<p>I tried Ghostty because of
<a href="https://github.com/dakra/ghostel">ghostel.el</a>, a terminal emulator for Emacs
powered by libghostty-vt, the VT engine extracted from the
<a href="https://ghostty.org">Ghostty</a> terminal.</p>

<h2 id="why-i-was-trying-ghostel-in-the-first-place">Why I was trying ghostel in the first place</h2>

<p>I run coding agents like Claude Code and OpenCode from the terminal, and I
live in Emacs, so the obvious move is to run them in eshell. That does not
work.</p>

<p>Eshell is not a terminal emulator. It is a shell written in Emacs Lisp that
runs a command and inserts its output into a buffer. Modern coding agents are
full-screen TUI applications — Claude Code, for instance, is built on Ink, a
React renderer for the terminal.<sup id="fnref:ink"><a href="#fn:ink" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> Programs like that assume a real
terminal: a PTY, raw-mode keyboard input, ANSI cursor addressing, the
alternate screen buffer, and a constant stream of escape sequences repainting
the screen many times a second.<sup id="fnref:terminal"><a href="#fn:terminal" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>Eshell provides almost none of that. It interprets basic color codes through
<code class="language-plaintext highlighter-rouge">ansi-color</code> and little else; it advertises <code class="language-plaintext highlighter-rouge">TERM=dumb</code>; its input model is
line-oriented, so the agent never sees individual keystrokes; and there is no
cursor positioning or alternate screen. So the agent’s UI arrives as garbled
escape sequences, redraws pile up in the buffer instead of replacing each
other, and interactive prompts do not respond to keys. Eshell’s escape hatch
for this — listing the program in <code class="language-plaintext highlighter-rouge">eshell-visual-commands</code> so it runs under
<code class="language-plaintext highlighter-rouge">term.el</code> — helps, but term.el is slow and its emulation is incomplete enough
that the agents still misrender.<sup id="fnref:eshell"><a href="#fn:eshell" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>Ghostel fixes this the same way vterm does: by embedding a real VT engine.
A native module (written in Zig) links libghostty-vt and handles terminal
state, rendering, and PTY I/O, while Elisp handles buffers and keymaps — the
same two-layer design as emacs-libvterm, but with Ghostty’s engine instead of
libvterm. That brings the Kitty keyboard protocol, synchronized output
(DEC 2026), and OSC 8 hyperlinks, none of which libvterm supports.<sup id="fnref:protocols"><a href="#fn:protocols" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> Claude Code
and OpenCode render and respond correctly inside it.</p>

<p>Ghostel only needs libghostty-vt, not the Ghostty application. But using it
made me curious about the terminal itself, so I installed Ghostty on my
ThinkPad T430 — the same 2012 machine from my
<a href="/2026/07/22/wezterm-setup/">WezTerm post</a>.</p>

<h2 id="it-would-not-open">It would not open</h2>

<p>Launching Ghostty from the desktop, the window flashed and closed. Running
<code class="language-plaintext highlighter-rouge">ghostty</code> from a terminal showed why:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>info: ghostty version=1.3.1
info(gtk): GTK version build=4.14.5 runtime=4.14.5
info(opengl): loaded OpenGL 4.2
warning(opengl): OpenGL version is too old. Ghostty requires OpenGL 4.3
warning(gtk_ghostty_surface): failed to initialize surface err=error.OpenGLOutdated
warning(gtk_ghostty_surface): surface failed to initialize err=error.SurfaceError
</code></pre></div></div>

<p>The system provides OpenGL 4.2; Ghostty’s renderer requires 4.3. The desktop
launch fails the same way — there is just no terminal attached to show the
log, so the window appears and dies.</p>

<p>I checked which GPU this machine has. <code class="language-plaintext highlighter-rouge">glxinfo</code> was not installed, but
<code class="language-plaintext highlighter-rouge">lspci</code> was enough:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ lspci -nn | grep -Ei 'vga|3d'
00:02.0 VGA compatible controller [0300]: Intel Corporation 3rd Gen Core processor Graphics Controller [8086:0166] (rev 09)
</code></pre></div></div>

<p>That is the Intel HD 4000, the integrated GPU on Ivy Bridge, the third
generation of Core processors, released in 2012.<sup id="fnref:hd4000"><a href="#fn:hd4000" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<h2 id="mesas-drivers">Mesa’s drivers</h2>

<p>On Linux, OpenGL is implemented by Mesa: one userspace project containing many
hardware drivers, with the right one selected at runtime for the GPU present.
This machine runs Mesa 25.2.8 on Ubuntu 24.04.</p>

<p>Intel GPUs are split across three Mesa drivers by hardware generation:
<code class="language-plaintext highlighter-rouge">i915</code> covers gen2–3, <code class="language-plaintext highlighter-rouge">crocus</code> covers gen4–7 (it replaced the older
<code class="language-plaintext highlighter-rouge">i965</code> driver), and <code class="language-plaintext highlighter-rouge">iris</code> covers gen8 (Broadwell)
and newer. Ivy Bridge is gen7, so it is served by crocus —
<code class="language-plaintext highlighter-rouge">crocus_dri.so</code> sits in <code class="language-plaintext highlighter-rouge">/usr/lib/x86_64-linux-gnu/dri/</code> on this
machine.<sup id="fnref:mesa-drivers"><a href="#fn:mesa-drivers" class="footnote" rel="footnote" role="doc-noteref">6</a></sup></p>

<p>Crocus exposes at most OpenGL 4.2 on Ivy Bridge, and GLSL 4.20 to match.
GLSL is the language shaders are written in — shaders being the small
programs a renderer runs on the GPU — and its version tracks OpenGL’s.
OpenGL 4.3 is an umbrella over a bundle of features — compute shaders
(GPU programs for general computation rather than drawing), shader storage
buffer objects (blocks of GPU memory those programs can read and write), and
others — and this generation never got the complete set.<sup id="fnref:gl43"><a href="#fn:gl43" class="footnote" rel="footnote" role="doc-noteref">7</a></sup> Haswell,
one generation later, gets OpenGL 4.6. The ceiling is per GPU generation
inside the driver, so no Mesa upgrade will move it.</p>

<p>Mesa also ships software rasterizers — renderers that do all of the GPU’s
drawing work on the CPU instead. The main one is <code class="language-plaintext highlighter-rouge">llvmpipe</code>, which uses LLVM
to generate fast machine code at runtime and implements
OpenGL 4.5.<sup id="fnref:llvmpipe"><a href="#fn:llvmpipe" class="footnote" rel="footnote" role="doc-noteref">8</a></sup> That becomes relevant below.</p>

<h2 id="advertising-a-version-the-hardware-does-not-have">Advertising a version the hardware does not have</h2>

<p>The version an application sees comes from Mesa: <code class="language-plaintext highlighter-rouge">glGetString(GL_VERSION)</code>
and <code class="language-plaintext highlighter-rouge">glGetIntegerv(GL_MAJOR_VERSION, ...)</code> on the context it created. Mesa
has an environment variable, <code class="language-plaintext highlighter-rouge">MESA_GL_VERSION_OVERRIDE</code>, that makes it report
a different version than the driver’s real one — <code class="language-plaintext highlighter-rouge">4.3FC</code> means version 4.3,
forward-compatible core profile, the variant of OpenGL with the old
deprecated functions removed. It enables no functionality; it only changes
the advertised number. The variable exists because hardware sometimes supports
every extension an application actually uses while the driver stops short of
exposing the version umbrella, and an application that only gates on the
number will then run fine.<sup id="fnref:envvars"><a href="#fn:envvars" class="footnote" rel="footnote" role="doc-noteref">9</a></sup></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ MESA_GL_VERSION_OVERRIDE=4.3FC ghostty
info(opengl): loaded OpenGL 4.3
error(opengl): shader compilation failure id=2 message=0:1(10): error:
  GLSL 4.30 is not supported. Supported versions are: 1.10, 1.20, 1.30,
  1.40, 1.50, 3.30, 4.00, 4.10, 4.20, 1.00 ES, and 3.00 ES
warning(gtk_ghostty_surface): failed to initialize surface err=error.CompileFailed
</code></pre></div></div>

<p>In order: Ghostty’s version check now passes (“loaded OpenGL 4.3”). It
proceeds to compile its shaders, which begin with <code class="language-plaintext highlighter-rouge">#version 430</code>. Mesa’s GLSL
compiler, which still truthfully supports only up to 4.20 on this driver,
rejects the directive. Surface initialization fails with <code class="language-plaintext highlighter-rouge">CompileFailed</code>
instead of <code class="language-plaintext highlighter-rouge">OpenGLOutdated</code>. GTK’s own GSK renderer printed the same GLSL
errors once the context claimed 4.3.</p>

<p>There is a companion variable, <code class="language-plaintext highlighter-rouge">MESA_GLSL_VERSION_OVERRIDE</code>, that would make
the compiler accept a <code class="language-plaintext highlighter-rouge">#version 430</code> directive too — but it also adds no
functionality, so it would only move the failure into whichever 4.30 features
the shaders actually use. The override moved the failure from the version
check into the compiler, which settles the question: the limit is in the
driver and hardware, not in Ghostty being overly strict.</p>

<h2 id="software-rendering-works">Software rendering works</h2>

<p>Mesa’s llvmpipe implements OpenGL 4.5, comfortably above Ghostty’s
requirement:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ LIBGL_ALWAYS_SOFTWARE=1 ghostty
info(opengl): loaded OpenGL 4.5
</code></pre></div></div>

<p>The surface initializes, the window opens, and Ghostty runs normally. Making
this permanent takes two small changes: a user-level desktop entry at
<code class="language-plaintext highlighter-rouge">~/.local/share/applications/com.mitchellh.ghostty.desktop</code> that overrides
the system one with</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Exec=env LIBGL_ALWAYS_SOFTWARE=1 /usr/bin/ghostty --gtk-single-instance=true
</code></pre></div></div>

<p>and a shell alias for terminal launches:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">alias </span><span class="nv">ghostty</span><span class="o">=</span><span class="s2">"LIBGL_ALWAYS_SOFTWARE=1 ghostty"</span>
</code></pre></div></div>

<p>Both work. But every frame is now rendered by the CPU.</p>

<h2 id="removing-it">Removing it</h2>

<p>Ghostty’s selling points are its GPU renderer and the platform-native UI. On
this machine the first one is gone — llvmpipe on an i5-3320M is functional but
it is the opposite of what the terminal is designed around. I already use
WezTerm, which runs hardware-accelerated on this same GPU (its OpenGL
front end targets a version Ivy Bridge can provide), and I documented that
setup <a href="/2026/07/22/wezterm-setup/">earlier today</a>. Running Ghostty in
software-rendering mode gives me nothing WezTerm does not already do better
here, so I uninstalled it and removed the desktop override and the alias.</p>

<p>Ghostel is unaffected by this. It links libghostty-vt directly and renders
through Emacs, so it does not depend on the GPU. The part of Ghostty I
actually needed — its terminal emulation — runs fine on this laptop, and I
will keep using it through ghostel.</p>

<h2 id="references">References</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:ink">
      <p><a href="https://github.com/vadimdemedes/ink">Ink</a>, a React renderer for the terminal; its README lists Claude Code among the projects built on it. <a href="#fnref:ink" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:terminal">
      <p>There is no single document that defines “a real terminal”; the pieces are specified separately. Pseudoterminals: <a href="https://man7.org/linux/man-pages/man7/pty.7.html">pty(7)</a>. Raw versus canonical input: <a href="https://man7.org/linux/man-pages/man3/termios.3.html">termios(3)</a>. Cursor addressing and the other control functions: <a href="https://ecma-international.org/publications-and-standards/standards/ecma-48/">ECMA-48</a> (the standard behind “ANSI escape sequences”). The de facto extensions terminals actually implement, including the alternate screen buffer (modes 1047/1049): <a href="https://invisible-island.net/xterm/ctlseqs/ctlseqs.html">XTerm Control Sequences</a>. Linus Åkesson’s <a href="https://www.linusakesson.net/programming/tty/">“The TTY demystified”</a> explains how these fit together. <a href="#fnref:terminal" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:eshell">
      <p>GNU Emacs manual, <a href="https://www.gnu.org/software/emacs/manual/html_mono/eshell.html">Eshell</a> — see the Input/Output and Visual Commands sections for the <code class="language-plaintext highlighter-rouge">TERM</code> handling and the <code class="language-plaintext highlighter-rouge">eshell-visual-commands</code> mechanism. <a href="#fnref:eshell" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:protocols">
      <p><a href="https://sw.kovidgoyal.net/kitty/keyboard-protocol/">Kitty keyboard protocol</a>; <a href="https://gist.github.com/christianparpart/d8a62cc1ab659194337d73e399004036">synchronized output (DEC mode 2026)</a>; <a href="https://gist.github.com/egmontkob/eb114294efbcd5adb1944c9f3cb5feda">OSC 8 hyperlinks</a>. <a href="#fnref:protocols" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:hd4000">
      <p>The identification comes from the PCI ID in brackets. <code class="language-plaintext highlighter-rouge">lspci</code> prints the device name from the PCI ID database, where vendor <code class="language-plaintext highlighter-rouge">8086</code> is Intel and device <code class="language-plaintext highlighter-rouge">0166</code> is the <a href="https://pci-ids.ucw.cz/read/PC/8086/0166">“3rd Gen Core processor Graphics Controller”</a> — the third Core generation is Ivy Bridge, launched in 2012. The marketing name is in Mesa’s driver table, <a href="https://gitlab.freedesktop.org/mesa/mesa/-/blob/main/include/pci_ids/crocus_pci_ids.h"><code class="language-plaintext highlighter-rouge">crocus_pci_ids.h</code></a>, which maps <code class="language-plaintext highlighter-rouge">0x0166</code> to <code class="language-plaintext highlighter-rouge">ivb_gt2, "Intel(R) HD Graphics 4000"</code>. The CPU agrees: this machine’s i5-3320M ships with HD Graphics 4000. <a href="#fnref:hd4000" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:mesa-drivers">
      <p><a href="https://docs.mesa3d.org/">Mesa documentation</a> for the driver architecture; <a href="https://mesamatrix.net/">mesamatrix.net</a> tracks which OpenGL version each Mesa driver supports. <a href="#fnref:mesa-drivers" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:gl43">
      <p><a href="https://registry.khronos.org/OpenGL/specs/gl/glspec43.core.pdf">OpenGL 4.3 core specification</a> (PDF), Khronos registry — its change-log appendix lists the features new in 4.3 (2012), including compute shaders and shader storage buffer objects. <a href="#fnref:gl43" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:llvmpipe">
      <p>Mesa documentation, <a href="https://docs.mesa3d.org/drivers/llvmpipe.html">llvmpipe</a>. <a href="#fnref:llvmpipe" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:envvars">
      <p>Mesa documentation, <a href="https://docs.mesa3d.org/envvars.html">Environment Variables</a> — documents <code class="language-plaintext highlighter-rouge">MESA_GL_VERSION_OVERRIDE</code>, the <code class="language-plaintext highlighter-rouge">FC</code> suffix, and <code class="language-plaintext highlighter-rouge">MESA_GLSL_VERSION_OVERRIDE</code>. <a href="#fnref:envvars" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="ghostty" /><category term="emacs" /><category term="terminal" /><category term="linux" /><summary type="html"><![CDATA[I tried Ghostty after ghostel.el made coding agents usable inside Emacs. On my ThinkPad T430's Ivy Bridge GPU it would not open — Mesa stops at OpenGL 4.2 and Ghostty needs 4.3. The debugging steps, a look at Mesa's drivers, and why I removed it.]]></summary></entry><entry><title type="html">Switching to WezTerm</title><link href="https://systemhalted.in/2026/07/22/wezterm-setup/" rel="alternate" type="text/html" title="Switching to WezTerm" /><published>2026-07-22T14:00:00+00:00</published><updated>2026-07-22T14:00:00+00:00</updated><id>https://systemhalted.in/2026/07/22/wezterm-setup</id><content type="html" xml:base="https://systemhalted.in/2026/07/22/wezterm-setup/"><![CDATA[<p>I learned about WezTerm as I was trying <a href="https://opencode.ai">OpenCode</a>, a
terminal-based AI coding agent. In GNOME Terminal it was sluggish and sometimes
unresponsive, and the experience was not up to the mark. So I thought to give
WezTerm a try.</p>

<p>WezTerm is an open-source, cross-platform terminal emulator written in Rust by
Wez Furlong. It is GPU-accelerated, configured in Lua rather than a static
config format, and comes with a built-in multiplexer — panes, tabs, and
workspaces — so it can take over the job tmux usually does. The same config
file works on Linux, macOS, and Windows.</p>

<p>I first switched to WezTerm on my old ThinkPad T430, a 2012 laptop with an
i5-3320M and 8 GB of RAM. Two things pushed me off GNOME Terminal on that
machine: WezTerm felt a little faster, and copying and pasting took fewer steps.
Before writing this post I went back to the same T430 and measured both claims,
because an impression like “felt faster” can easily be placebo.</p>

<h2 id="was-it-actually-faster">Was it actually faster?</h2>

<p>I ran each test inside a real window of each terminal on the T430 (Ubuntu,
GNOME on Wayland; WezTerm 20240203, GNOME Terminal 3.52 with VTE 0.76), six
runs each, first run discarded as warm-up. The results fall into two groups.</p>

<table>
  <thead>
    <tr>
      <th>Test</th>
      <th>WezTerm</th>
      <th>GNOME Terminal</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Open a window, run a command, close (overhead)</td>
      <td>0.06–0.09 s</td>
      <td>0.73–0.78 s</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cat</code> a 50 MB text file</td>
      <td>8.0 s</td>
      <td>1.95 s</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">seq 1 1000000</code></td>
      <td>1.33 s</td>
      <td>0.93 s</td>
    </tr>
    <tr>
      <td>Memory with one window open</td>
      <td>~206 MB</td>
      <td>~50 MB</td>
    </tr>
  </tbody>
</table>

<p>So, the only thing that mattered to me was Row 1. WezTerm puts a usable window on screen 
in under a tenth of a second; GNOME Terminal takes about three quarters of a second 
even with its background server process already running. I open a terminal dozens of 
times a day, so this is the delay I notice most.</p>

<p>The second and third rows go the other way, and by a wide margin. When a
command floods the screen with output, VTE (the library under GNOME Terminal)
skips rendering frames it can’t keep up with, while WezTerm renders more of
them. I checked whether WezTerm’s default WebGPU renderer was falling back to
software on the T430’s ancient Intel HD 4000 by rerunning with
<code class="language-plaintext highlighter-rouge">front_end = "OpenGL"</code> — the numbers were the same, so this is just how WezTerm
behaves. It also uses about four times the memory.</p>

<p>So “a little faster” was not placebo, but it needs qualifying: WezTerm is much
faster at opening a terminal, which I do constantly, and slower at dumping
bulk output, which I do rarely. If you spend your day <code class="language-plaintext highlighter-rouge">cat</code>-ing huge logs on
old hardware, GNOME Terminal is the faster terminal for you. For how I use a
terminal, the trade-off favors WezTerm.</p>

<h2 id="the-copy-paste-difference">The copy-paste difference</h2>

<p>You can check this one against the default keybindings (<code class="language-plaintext highlighter-rouge">wezterm show-keys</code>).
In WezTerm, releasing a mouse selection runs
<code class="language-plaintext highlighter-rouge">CompleteSelection(ClipboardAndPrimarySelection)</code>, which puts the selected
text in the system clipboard immediately; there is no separate copy step.
Plain <code class="language-plaintext highlighter-rouge">Ctrl+C</code> and <code class="language-plaintext highlighter-rouge">Ctrl+V</code> also work: <code class="language-plaintext highlighter-rouge">Ctrl+C</code> copies when a selection exists
and sends the interrupt signal when one doesn’t.</p>

<p>In GNOME Terminal, a mouse selection only goes to the X primary selection.
Getting it into the clipboard needs an explicit <code class="language-plaintext highlighter-rouge">Ctrl+Shift+C</code>, and pasting
into the terminal needs <code class="language-plaintext highlighter-rouge">Ctrl+Shift+V</code>. That extra step, repeated dozens of
times a day, was the difference I had been feeling.</p>

<p>WezTerm adds two keyboard-only tools GNOME Terminal has no equivalent for:
Quick Select (<code class="language-plaintext highlighter-rouge">Ctrl+Shift+Space</code>) overlays short labels on URLs, paths, and
hashes visible on screen so you can grab one without touching the mouse, and
Copy Mode (<code class="language-plaintext highlighter-rouge">Ctrl+Shift+X</code>) gives modal, keyboard-driven selection. URLs in
output are clickable with a plain left click.</p>

<p>The rest of this post is the setup I ended up with: a Lua config with
Emacs-style keybindings, workspaces, and per-machine overrides.</p>

<h2 id="installation">Installation</h2>

<p>On Ubuntu and Debian, WezTerm has an apt repository:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-fsSL</span> https://apt.fury.io/wez/gpg.key | <span class="se">\</span>
  <span class="nb">sudo </span>gpg <span class="nt">--yes</span> <span class="nt">--dearmor</span> <span class="nt">-o</span> /etc/apt/keyrings/wezterm-fury.gpg
<span class="nb">echo</span> <span class="s1">'deb [signed-by=/etc/apt/keyrings/wezterm-fury.gpg] https://apt.fury.io/wez/ * *'</span> | <span class="se">\</span>
  <span class="nb">sudo tee</span> /etc/apt/sources.list.d/wezterm.list
<span class="nb">sudo </span>apt update <span class="o">&amp;&amp;</span> <span class="nb">sudo </span>apt <span class="nb">install </span>wezterm
</code></pre></div></div>

<p>There is also a Flatpak, and packages for most other distributions are listed
at <a href="https://wezfurlong.org/wezterm/installation.html">wezfurlong.org/wezterm</a>.
On macOS it’s <code class="language-plaintext highlighter-rouge">brew install --cask wezterm</code>; if you install to
<code class="language-plaintext highlighter-rouge">~/Applications</code> instead of <code class="language-plaintext highlighter-rouge">/Applications</code>, add
<code class="language-plaintext highlighter-rouge">$HOME/Applications/WezTerm.app/Contents/MacOS</code> to your PATH so the <code class="language-plaintext highlighter-rouge">wezterm</code>
CLI works.</p>

<h2 id="the-config-file">The config file</h2>

<p>WezTerm reads <code class="language-plaintext highlighter-rouge">~/.wezterm.lua</code> (or <code class="language-plaintext highlighter-rouge">~/.config/wezterm/wezterm.lua</code>). The
config is a <a href="https://www.lua.org/">Lua</a> program, which means conditionals, loops, and per-machine
logic live in the same file as the settings. Surprisingly, my son is interested in Lua
as well as it is used in Roblox. He is currently learning how to code in Lua.</p>

<p>The config builder gives better error messages when a key is 
misspelled:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">local</span> <span class="n">wezterm</span> <span class="o">=</span> <span class="nb">require</span> <span class="s1">'wezterm'</span>
<span class="kd">local</span> <span class="n">config</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">config_builder</span><span class="p">()</span>

<span class="c1">-- ... your configuration ...</span>

<span class="k">return</span> <span class="n">config</span>
</code></pre></div></div>

<h2 id="fonts-and-ligatures">Fonts and ligatures</h2>

<p>Pick a Nerd Font so prompt icons (Starship, Powerlevel10k) render correctly:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="n">font</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">font</span><span class="p">(</span><span class="s1">'JetBrainsMono Nerd Font'</span><span class="p">,</span> <span class="p">{</span> <span class="n">weight</span> <span class="o">=</span> <span class="s1">'Medium'</span> <span class="p">})</span>
<span class="n">config</span><span class="p">.</span><span class="n">font_size</span> <span class="o">=</span> <span class="mi">14</span><span class="p">.</span><span class="mi">0</span>

<span class="c1">-- Enable ligatures: =&gt; becomes →, != becomes ≠</span>
<span class="n">config</span><span class="p">.</span><span class="n">harfbuzz_features</span> <span class="o">=</span> <span class="p">{</span> <span class="s1">'calt=1'</span><span class="p">,</span> <span class="s1">'clig=1'</span><span class="p">,</span> <span class="s1">'liga=1'</span> <span class="p">}</span>
</code></pre></div></div>

<p>Other good Nerd Font options: <code class="language-plaintext highlighter-rouge">FiraCode Nerd Font</code>, <code class="language-plaintext highlighter-rouge">Hack Nerd Font</code>,
<code class="language-plaintext highlighter-rouge">CaskaydiaCove Nerd Font</code>.</p>

<h2 id="color-scheme">Color scheme</h2>

<p>WezTerm ships with hundreds of built-in schemes, so there is no need to paste
hex colors:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="n">color_scheme</span> <span class="o">=</span> <span class="s1">'Catppuccin Mocha'</span>
</code></pre></div></div>

<p>Run <code class="language-plaintext highlighter-rouge">wezterm ls-colors</code> to list them, or browse the
<a href="https://wezfurlong.org/wezterm/colorschemes/index.html">color scheme gallery</a>.</p>

<h2 id="window-appearance">Window appearance</h2>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="n">window_decorations</span> <span class="o">=</span> <span class="s1">'TITLE | RESIZE'</span>
<span class="n">config</span><span class="p">.</span><span class="n">window_background_opacity</span> <span class="o">=</span> <span class="mi">0</span><span class="p">.</span><span class="mi">92</span>
<span class="n">config</span><span class="p">.</span><span class="n">window_padding</span> <span class="o">=</span> <span class="p">{</span>
  <span class="n">left</span> <span class="o">=</span> <span class="mi">12</span><span class="p">,</span> <span class="n">right</span> <span class="o">=</span> <span class="mi">12</span><span class="p">,</span> <span class="n">top</span> <span class="o">=</span> <span class="mi">12</span><span class="p">,</span> <span class="n">bottom</span> <span class="o">=</span> <span class="mi">12</span><span class="p">,</span>
<span class="p">}</span>
<span class="c1">-- macOS only; ignored elsewhere</span>
<span class="n">config</span><span class="p">.</span><span class="n">macos_window_background_blur</span> <span class="o">=</span> <span class="mi">20</span>
</code></pre></div></div>

<p>On a machine as old as the T430 I keep the opacity at 1.0 — transparency costs
compositing work for no benefit on a small screen.</p>

<h2 id="tab-bar">Tab bar</h2>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="n">use_fancy_tab_bar</span> <span class="o">=</span> <span class="kc">true</span>
<span class="n">config</span><span class="p">.</span><span class="n">hide_tab_bar_if_only_one_tab</span> <span class="o">=</span> <span class="kc">false</span>
<span class="n">config</span><span class="p">.</span><span class="n">tab_max_width</span> <span class="o">=</span> <span class="mi">30</span>
</code></pre></div></div>

<h3 id="custom-tab-titles">Custom tab titles</h3>

<p>Show the current directory name instead of the default process title:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">wezterm</span><span class="p">.</span><span class="n">on</span><span class="p">(</span><span class="s1">'format-tab-title'</span><span class="p">,</span> <span class="k">function</span><span class="p">(</span><span class="n">tab</span><span class="p">)</span>
  <span class="kd">local</span> <span class="n">pane</span> <span class="o">=</span> <span class="n">tab</span><span class="p">.</span><span class="n">active_pane</span>
  <span class="kd">local</span> <span class="n">cwd</span> <span class="o">=</span> <span class="n">pane</span><span class="p">.</span><span class="n">current_working_dir</span>
  <span class="kd">local</span> <span class="n">title</span> <span class="o">=</span> <span class="n">pane</span><span class="p">.</span><span class="n">title</span>
  <span class="k">if</span> <span class="n">cwd</span> <span class="k">then</span>
    <span class="kd">local</span> <span class="n">path</span> <span class="o">=</span> <span class="n">cwd</span><span class="p">.</span><span class="n">file_path</span> <span class="ow">or</span> <span class="s1">''</span>
    <span class="kd">local</span> <span class="n">folder</span> <span class="o">=</span> <span class="n">path</span><span class="p">:</span><span class="n">match</span><span class="p">(</span><span class="s1">'([^/]+)/?$'</span><span class="p">)</span> <span class="ow">or</span> <span class="n">title</span>
    <span class="n">title</span> <span class="o">=</span> <span class="n">folder</span>
  <span class="k">end</span>
  <span class="k">if</span> <span class="n">tab</span><span class="p">.</span><span class="n">is_active</span> <span class="k">then</span>
    <span class="k">return</span> <span class="s1">' ● '</span> <span class="o">..</span> <span class="n">title</span> <span class="o">..</span> <span class="s1">' '</span>
  <span class="k">end</span>
  <span class="k">return</span> <span class="s1">' '</span> <span class="o">..</span> <span class="n">title</span> <span class="o">..</span> <span class="s1">' '</span>
<span class="k">end</span><span class="p">)</span>
</code></pre></div></div>

<h3 id="status-bar">Status bar</h3>

<p>Show the active workspace name and time in the right status area:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">wezterm</span><span class="p">.</span><span class="n">on</span><span class="p">(</span><span class="s1">'update-right-status'</span><span class="p">,</span> <span class="k">function</span><span class="p">(</span><span class="n">window</span><span class="p">)</span>
  <span class="kd">local</span> <span class="n">workspace</span> <span class="o">=</span> <span class="n">window</span><span class="p">:</span><span class="n">active_workspace</span><span class="p">()</span>
  <span class="kd">local</span> <span class="n">time</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">strftime</span><span class="p">(</span><span class="s1">'%H:%M'</span><span class="p">)</span>
  <span class="n">window</span><span class="p">:</span><span class="n">set_right_status</span><span class="p">(</span><span class="n">wezterm</span><span class="p">.</span><span class="n">format</span><span class="p">({</span>
    <span class="p">{</span> <span class="n">Text</span> <span class="o">=</span> <span class="s1">'  '</span> <span class="o">..</span> <span class="n">workspace</span> <span class="o">..</span> <span class="s1">'  │  '</span> <span class="o">..</span> <span class="n">time</span> <span class="o">..</span> <span class="s1">'  '</span> <span class="p">},</span>
  <span class="p">}))</span>
<span class="k">end</span><span class="p">)</span>
</code></pre></div></div>

<h2 id="keybindings-leader-key-emacs-style">Keybindings: leader key, Emacs-style</h2>

<p>Instead of memorizing modifier combos, I use a leader key, like tmux’s
<code class="language-plaintext highlighter-rouge">Ctrl+b</code> or Emacs’s <code class="language-plaintext highlighter-rouge">C-x</code>. Press the leader, then a single key.</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">local</span> <span class="n">act</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">action</span>
<span class="n">config</span><span class="p">.</span><span class="n">leader</span> <span class="o">=</span> <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'Space'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'CTRL'</span><span class="p">,</span> <span class="n">timeout_milliseconds</span> <span class="o">=</span> <span class="mi">1000</span> <span class="p">}</span>
</code></pre></div></div>

<p>After pressing <code class="language-plaintext highlighter-rouge">Ctrl+Space</code>, you have one second to press the next key.</p>

<h3 id="pane-management">Pane management</h3>

<p>Modeled after the Emacs window commands (<code class="language-plaintext highlighter-rouge">C-x 2</code>, <code class="language-plaintext highlighter-rouge">C-x 3</code>, <code class="language-plaintext highlighter-rouge">C-x 0</code>, <code class="language-plaintext highlighter-rouge">C-x 1</code>),
so the muscle memory transfers:</p>

<table>
  <thead>
    <tr>
      <th>Shortcut</th>
      <th>Action</th>
      <th>Emacs equivalent</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 3</code></td>
      <td>Split horizontal (side by side)</td>
      <td><code class="language-plaintext highlighter-rouge">C-x 3</code></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 2</code></td>
      <td>Split vertical (top/bottom)</td>
      <td><code class="language-plaintext highlighter-rouge">C-x 2</code></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader o</code></td>
      <td>Cycle to next pane</td>
      <td><code class="language-plaintext highlighter-rouge">C-x o</code></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 0</code></td>
      <td>Close current pane</td>
      <td><code class="language-plaintext highlighter-rouge">C-x 0</code></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 1</code></td>
      <td>Zoom (maximize) current pane</td>
      <td><code class="language-plaintext highlighter-rouge">C-x 1</code></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader ←↓↑→</code></td>
      <td>Navigate panes by direction</td>
      <td>—</td>
    </tr>
  </tbody>
</table>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="n">keys</span> <span class="o">=</span> <span class="p">{</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'3'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">SplitHorizontal</span> <span class="p">{</span> <span class="n">domain</span> <span class="o">=</span> <span class="s1">'CurrentPaneDomain'</span> <span class="p">}</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'2'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">SplitVertical</span> <span class="p">{</span> <span class="n">domain</span> <span class="o">=</span> <span class="s1">'CurrentPaneDomain'</span> <span class="p">}</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'o'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivatePaneDirection</span> <span class="s1">'Next'</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'0'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">CloseCurrentPane</span> <span class="p">{</span> <span class="n">confirm</span> <span class="o">=</span> <span class="kc">true</span> <span class="p">}</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'1'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">TogglePaneZoomState</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'LeftArrow'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivatePaneDirection</span> <span class="s1">'Left'</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'RightArrow'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivatePaneDirection</span> <span class="s1">'Right'</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'UpArrow'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivatePaneDirection</span> <span class="s1">'Up'</span> <span class="p">},</span>
  <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'DownArrow'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivatePaneDirection</span> <span class="s1">'Down'</span> <span class="p">},</span>
<span class="p">}</span>
</code></pre></div></div>

<h3 id="tab-management">Tab management</h3>

<table>
  <thead>
    <tr>
      <th>Shortcut</th>
      <th>Action</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader c</code></td>
      <td>Create new tab</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader b</code></td>
      <td>Previous tab</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader f</code></td>
      <td>Next tab</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader k</code></td>
      <td>Close tab</td>
    </tr>
  </tbody>
</table>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'c'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">SpawnTab</span> <span class="s1">'CurrentPaneDomain'</span> <span class="p">},</span>
<span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'b'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivateTabRelative</span><span class="p">(</span><span class="o">-</span><span class="mi">1</span><span class="p">)</span> <span class="p">},</span>
<span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'f'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivateTabRelative</span><span class="p">(</span><span class="mi">1</span><span class="p">)</span> <span class="p">},</span>
<span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'k'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">CloseCurrentTab</span> <span class="p">{</span> <span class="n">confirm</span> <span class="o">=</span> <span class="kc">true</span> <span class="p">}</span> <span class="p">},</span>
</code></pre></div></div>

<h3 id="resize-mode">Resize mode</h3>

<p>A modal resize mode where the arrow keys resize panes; <code class="language-plaintext highlighter-rouge">Escape</code> or <code class="language-plaintext highlighter-rouge">Enter</code>
exits:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'r'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ActivateKeyTable</span> <span class="p">{</span>
  <span class="n">name</span> <span class="o">=</span> <span class="s1">'resize_pane'</span><span class="p">,</span> <span class="n">one_shot</span> <span class="o">=</span> <span class="kc">false</span>
<span class="p">}},</span>

<span class="c1">-- Define the key table</span>
<span class="n">config</span><span class="p">.</span><span class="n">key_tables</span> <span class="o">=</span> <span class="p">{</span>
  <span class="n">resize_pane</span> <span class="o">=</span> <span class="p">{</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'LeftArrow'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">AdjustPaneSize</span> <span class="p">{</span> <span class="s1">'Left'</span><span class="p">,</span> <span class="mi">2</span> <span class="p">}</span> <span class="p">},</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'RightArrow'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">AdjustPaneSize</span> <span class="p">{</span> <span class="s1">'Right'</span><span class="p">,</span> <span class="mi">2</span> <span class="p">}</span> <span class="p">},</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'UpArrow'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">AdjustPaneSize</span> <span class="p">{</span> <span class="s1">'Up'</span><span class="p">,</span> <span class="mi">2</span> <span class="p">}</span> <span class="p">},</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'DownArrow'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">AdjustPaneSize</span> <span class="p">{</span> <span class="s1">'Down'</span><span class="p">,</span> <span class="mi">2</span> <span class="p">}</span> <span class="p">},</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'Escape'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="s1">'PopKeyTable'</span> <span class="p">},</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'Enter'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="s1">'PopKeyTable'</span> <span class="p">},</span>
  <span class="p">},</span>
<span class="p">}</span>
</code></pre></div></div>

<h3 id="utility-shortcuts">Utility shortcuts</h3>

<table>
  <thead>
    <tr>
      <th>Shortcut</th>
      <th>Action</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Ctrl+Shift+P</code></td>
      <td>Command palette</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader v</code></td>
      <td>Copy/scroll mode</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader q</code></td>
      <td>Quick select (URLs, hashes)</td>
    </tr>
  </tbody>
</table>

<p>(On macOS the palette is <code class="language-plaintext highlighter-rouge">Cmd+Shift+P</code>.) The copy mode and quick select
defaults (<code class="language-plaintext highlighter-rouge">Ctrl+Shift+X</code>, <code class="language-plaintext highlighter-rouge">Ctrl+Shift+Space</code>) keep working; the leader
bindings are just easier for me to remember.</p>

<h2 id="workspaces-project-based-context-switching">Workspaces: project-based context switching</h2>

<p>Workspaces are the feature that let WezTerm replace tmux for me. Each
workspace is an isolated set of tabs and panes with its own working directory,
and switching between them swaps the whole window contents.</p>

<h3 id="basic-workspace-commands">Basic workspace commands</h3>

<table>
  <thead>
    <tr>
      <th>Shortcut</th>
      <th>Action</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader w</code></td>
      <td>Create new named workspace</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader s</code></td>
      <td>Switch workspace (fuzzy finder)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader d</code></td>
      <td>Switch to default workspace</td>
    </tr>
  </tbody>
</table>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'w'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">PromptInputLine</span> <span class="p">{</span>
  <span class="n">description</span> <span class="o">=</span> <span class="s1">'Enter new workspace name:'</span><span class="p">,</span>
  <span class="n">action</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">action_callback</span><span class="p">(</span><span class="k">function</span><span class="p">(</span><span class="n">window</span><span class="p">,</span> <span class="n">pane</span><span class="p">,</span> <span class="n">line</span><span class="p">)</span>
    <span class="k">if</span> <span class="n">line</span> <span class="k">then</span>
      <span class="n">window</span><span class="p">:</span><span class="n">perform_action</span><span class="p">(</span><span class="n">act</span><span class="p">.</span><span class="n">SwitchToWorkspace</span> <span class="p">{</span> <span class="n">name</span> <span class="o">=</span> <span class="n">line</span> <span class="p">},</span> <span class="n">pane</span><span class="p">)</span>
    <span class="k">end</span>
  <span class="k">end</span><span class="p">),</span>
<span class="p">}},</span>
<span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'s'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">ShowLauncherArgs</span> <span class="p">{</span> <span class="n">flags</span> <span class="o">=</span> <span class="s1">'FUZZY|WORKSPACES'</span> <span class="p">}</span> <span class="p">},</span>
<span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'d'</span><span class="p">,</span> <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span> <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">SwitchToWorkspace</span> <span class="p">{</span>
  <span class="n">name</span> <span class="o">=</span> <span class="s1">'default'</span><span class="p">,</span>
  <span class="n">spawn</span> <span class="o">=</span> <span class="p">{</span> <span class="n">cwd</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">home_dir</span> <span class="p">},</span>
<span class="p">}},</span>
</code></pre></div></div>

<h3 id="per-machine-workspace-shortcuts">Per-machine workspace shortcuts</h3>

<p>Hard-coding project paths in a tracked config file is impractical — paths
differ between machines. The fix is a local override file. Create
<code class="language-plaintext highlighter-rouge">~/.wezterm_local.lua</code> (not version-controlled):</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">return</span> <span class="p">{</span>
  <span class="n">workspaces</span> <span class="o">=</span> <span class="p">{</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'e'</span><span class="p">,</span> <span class="n">name</span> <span class="o">=</span> <span class="s1">'eventing'</span><span class="p">,</span> <span class="n">cwd</span> <span class="o">=</span> <span class="s1">'/home/me/Work/eventing-platform'</span> <span class="p">},</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'p'</span><span class="p">,</span> <span class="n">name</span> <span class="o">=</span> <span class="s1">'personal'</span><span class="p">,</span> <span class="n">cwd</span> <span class="o">=</span> <span class="s1">'/home/me/Workspaces/Personal'</span> <span class="p">},</span>
    <span class="p">{</span> <span class="n">key</span> <span class="o">=</span> <span class="s1">'a'</span><span class="p">,</span> <span class="n">name</span> <span class="o">=</span> <span class="s1">'api'</span><span class="p">,</span> <span class="n">cwd</span> <span class="o">=</span> <span class="s1">'/home/me/Work/api-gateway'</span> <span class="p">},</span>
  <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Then load it dynamically from the main config:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">local</span> <span class="n">local_config</span> <span class="o">=</span> <span class="p">{}</span>
<span class="kd">local</span> <span class="n">ok</span><span class="p">,</span> <span class="n">loaded</span> <span class="o">=</span> <span class="nb">pcall</span><span class="p">(</span><span class="nb">dofile</span><span class="p">,</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">home_dir</span> <span class="o">..</span> <span class="s1">'/.wezterm_local.lua'</span><span class="p">)</span>
<span class="k">if</span> <span class="n">ok</span> <span class="ow">and</span> <span class="n">loaded</span> <span class="k">then</span>
  <span class="n">local_config</span> <span class="o">=</span> <span class="n">loaded</span>
<span class="k">end</span>

<span class="kd">local</span> <span class="n">workspace_defs</span> <span class="o">=</span> <span class="n">local_config</span><span class="p">.</span><span class="n">workspaces</span> <span class="ow">or</span> <span class="p">{}</span>

<span class="c1">-- Dynamically register workspace keybindings</span>
<span class="k">for</span> <span class="n">_</span><span class="p">,</span> <span class="n">ws</span> <span class="k">in</span> <span class="nb">ipairs</span><span class="p">(</span><span class="n">workspace_defs</span><span class="p">)</span> <span class="k">do</span>
  <span class="nb">table.insert</span><span class="p">(</span><span class="n">config</span><span class="p">.</span><span class="n">keys</span><span class="p">,</span> <span class="p">{</span>
    <span class="n">key</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">key</span><span class="p">,</span>
    <span class="n">mods</span> <span class="o">=</span> <span class="s1">'LEADER'</span><span class="p">,</span>
    <span class="n">action</span> <span class="o">=</span> <span class="n">act</span><span class="p">.</span><span class="n">SwitchToWorkspace</span> <span class="p">{</span>
      <span class="n">name</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">name</span><span class="p">,</span>
      <span class="n">spawn</span> <span class="o">=</span> <span class="p">{</span> <span class="n">cwd</span> <span class="o">=</span> <span class="n">ws</span><span class="p">.</span><span class="n">cwd</span> <span class="p">},</span>
    <span class="p">},</span>
  <span class="p">})</span>
<span class="k">end</span>
</code></pre></div></div>

<p>Now <code class="language-plaintext highlighter-rouge">Leader e</code> jumps to the eventing workspace, <code class="language-plaintext highlighter-rouge">Leader p</code> to personal, and so
on, with each machine defining its own list.</p>

<h2 id="hyperlink-rules-clickable-jira-tickets-and-github-issues">Hyperlink rules: clickable Jira tickets and GitHub issues</h2>

<p>WezTerm can detect patterns in terminal output and make them clickable:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="n">hyperlink_rules</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">default_hyperlink_rules</span><span class="p">()</span>

<span class="c1">-- Jira tickets: PROJECT-1234 → opens in Atlassian</span>
<span class="nb">table.insert</span><span class="p">(</span><span class="n">config</span><span class="p">.</span><span class="n">hyperlink_rules</span><span class="p">,</span> <span class="p">{</span>
  <span class="n">regex</span> <span class="o">=</span> <span class="s">[[\b(MYPROJECT-\d+)\b]]</span><span class="p">,</span>
  <span class="n">format</span> <span class="o">=</span> <span class="s1">'https://myorg.atlassian.net/browse/$1'</span><span class="p">,</span>
<span class="p">})</span>

<span class="c1">-- GitHub shorthand: owner/repo#123 → opens the issue/PR</span>
<span class="nb">table.insert</span><span class="p">(</span><span class="n">config</span><span class="p">.</span><span class="n">hyperlink_rules</span><span class="p">,</span> <span class="p">{</span>
  <span class="n">regex</span> <span class="o">=</span> <span class="s">[[\b([A-Za-z0-9_-]+/[A-Za-z0-9_.-]+)#(\d+)\b]]</span><span class="p">,</span>
  <span class="n">format</span> <span class="o">=</span> <span class="s1">'https://github.com/$1/issues/$2'</span><span class="p">,</span>
<span class="p">})</span>
</code></pre></div></div>

<p>A plain left click follows the link (on macOS it’s <code class="language-plaintext highlighter-rouge">Cmd+Click</code>).</p>

<h2 id="per-machine-font-size">Per-machine font size</h2>

<p>Different monitors need different font sizes. Use the hostname:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">local</span> <span class="n">hostname</span> <span class="o">=</span> <span class="n">wezterm</span><span class="p">.</span><span class="n">hostname</span><span class="p">()</span>
<span class="kd">local</span> <span class="n">font_size</span> <span class="o">=</span> <span class="mi">14</span><span class="p">.</span><span class="mi">0</span>
<span class="k">if</span> <span class="n">hostname</span><span class="p">:</span><span class="n">find</span><span class="p">(</span><span class="s1">'work'</span><span class="p">)</span> <span class="k">then</span>
  <span class="n">font_size</span> <span class="o">=</span> <span class="mi">13</span><span class="p">.</span><span class="mi">0</span>
<span class="k">end</span>
<span class="n">config</span><span class="p">.</span><span class="n">font_size</span> <span class="o">=</span> <span class="n">font_size</span>
</code></pre></div></div>

<p>Or put it in <code class="language-plaintext highlighter-rouge">~/.wezterm_local.lua</code> if you prefer:</p>

<div class="language-lua highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">-- ~/.wezterm_local.lua</span>
<span class="k">return</span> <span class="p">{</span>
  <span class="n">font_size</span> <span class="o">=</span> <span class="mi">13</span><span class="p">.</span><span class="mi">0</span><span class="p">,</span>
  <span class="n">workspaces</span> <span class="o">=</span> <span class="p">{</span> <span class="o">...</span> <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<h2 id="managing-the-config-in-dotfiles">Managing the config in dotfiles</h2>

<p>Keep <code class="language-plaintext highlighter-rouge">wezterm.lua</code> in your dotfiles repo and symlink it:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">ln</span> <span class="nt">-sf</span> ~/path/to/dotfiles/wezterm.lua ~/.wezterm.lua
</code></pre></div></div>

<p>The machine-specific <code class="language-plaintext highlighter-rouge">~/.wezterm_local.lua</code> stays untracked. Add it to your
dotfiles <code class="language-plaintext highlighter-rouge">.gitignore</code> if it lives in the same directory:</p>

<pre><code class="language-gitignore"># Per-machine overrides (never tracked)
*.local.lua
</code></pre>

<p>This gives you a single tracked config that works on every machine, with local
overrides for paths and preferences that differ.</p>

<h2 id="quick-reference">Quick reference</h2>

<table>
  <thead>
    <tr>
      <th>Leader = <code class="language-plaintext highlighter-rouge">Ctrl+Space</code></th>
      <th> </th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Panes</strong></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 2</code></td>
      <td>Split vertical</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 3</code></td>
      <td>Split horizontal</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader o</code></td>
      <td>Next pane</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 0</code></td>
      <td>Close pane</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader 1</code></td>
      <td>Zoom pane</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader r</code></td>
      <td>Resize mode (arrows, then Esc)</td>
    </tr>
    <tr>
      <td><strong>Tabs</strong></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader c</code></td>
      <td>New tab</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader b/f</code></td>
      <td>Prev/next tab</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader k</code></td>
      <td>Close tab</td>
    </tr>
    <tr>
      <td><strong>Workspaces</strong></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader w</code></td>
      <td>New workspace</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader s</code></td>
      <td>Switch (fuzzy)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader d</code></td>
      <td>Default workspace</td>
    </tr>
    <tr>
      <td><strong>Other</strong></td>
      <td> </td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader v</code></td>
      <td>Copy/scroll mode</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Leader q</code></td>
      <td>Quick select</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Ctrl+Shift+P</code></td>
      <td>Command palette</td>
    </tr>
  </tbody>
</table>

<h2 id="conclusion">Conclusion</h2>

<p>WezTerm replaced tmux, a color scheme plugin, and a hyperlink plugin for me,
all from a single Lua file, and it did so first on a machine with little
performance to spare. The benchmarks put a number on the speed I had felt:
it comes from window-open latency, not throughput, and GNOME Terminal still
handles bulk output better. If you try WezTerm, start with the basics — font,
theme, leader key — and add workspaces and hyperlink rules as you need them.</p>

<p>I will be using WezTerm and GNOME Terminal together for a while before deciding
which one I will keep.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="wezterm" /><category term="terminal" /><category term="linux" /><category term="productivity" /><summary type="html"><![CDATA[I switched to WezTerm on a 2012 ThinkPad T430 because it felt faster than GNOME Terminal and copy-paste was simpler. Benchmarks on the same machine show where that impression holds up, followed by the full Lua setup.]]></summary></entry><entry><title type="html">Review: Software Malpractice in the Age of AI</title><link href="https://systemhalted.in/2026/07/21/review-software-malpractice-in-the-age-of-ai/" rel="alternate" type="text/html" title="Review: Software Malpractice in the Age of AI" /><published>2026-07-21T00:00:00+00:00</published><updated>2026-07-21T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/21/review-software-malpractice-in-the-age-of-ai</id><content type="html" xml:base="https://systemhalted.in/2026/07/21/review-software-malpractice-in-the-age-of-ai/"><![CDATA[<p>Danny Tobey’s “Software Malpractice in the Age of AI” makes a useful and uncomfortable argument: as software becomes more consequential, the software industry cannot keep pretending that professional responsibility belongs only to older professions such as medicine, law, accounting, and nursing.</p>

<p>The paper surveys legal precedent around software, especially in medicine, and argues that the rise of AI weakens one of the assumptions that has historically protected software vendors from malpractice-style liability. That assumption is that human professionals remain the real decision makers, while software merely assists them.</p>

<p>For ordinary clinical decision-support systems, that line may seem plausible. A doctor reviews the output, applies professional judgment, and accepts or rejects the recommendation. But with narrow AI systems that develop deep expertise in a domain, the relationship becomes less clean. If a system produces a recommendation that a human reviewer cannot meaningfully audit, then “human oversight” can become more procedural than real.</p>

<p>That is the paper’s strongest point. AI makes it harder to rely on the fiction that a human independently reviewed the basis for a software recommendation.</p>

<h2 id="where-i-agree">Where I agree</h2>

<p>I agree with the paper’s central concern. Technology companies and software professionals should not be immune from responsibility simply because the harm is mediated through code.</p>

<p>Software now helps decide medical treatment, credit access, hiring, public benefits, fraud detection, insurance pricing, and many other areas where mistakes can alter a person’s life. When systems operate at that level of consequence, the industry needs a more serious account of duty, care, review, and accountability.</p>

<p>The paper is also right to look at professional malpractice as a useful comparison. Older professions have already built ideas around competence, fiduciary responsibility, licensing, insurance, standards of care, and disciplinary consequences. Software does not need to copy that structure blindly, but it should learn from it.</p>

<h2 id="where-the-analogy-weakens">Where the analogy weakens</h2>

<p>The main weakness is that the doctor-software-engineer analogy does not map cleanly.</p>

<p>A doctor usually owns the professional act of diagnosis or treatment. Even when the doctor consults peers, the final professional decision is attributable to that doctor. Software is rarely produced that way.</p>

<p>A deployed AI product is usually the result of many decisions:</p>

<ul>
  <li>Product defines the user problem and desired behavior.</li>
  <li>Data teams choose or prepare datasets.</li>
  <li>Engineers implement the system.</li>
  <li>Model teams tune behavior.</li>
  <li>Designers shape how users interpret the output.</li>
  <li>Legal and compliance teams approve risk language.</li>
  <li>Executives decide whether the product ships.</li>
</ul>

<p>If harm occurs, it may be impossible or unfair to assign responsibility only to the individual engineer who wrote part of the implementation. The engineer may have seen the risk but lacked authority to block release. Or the risk may have emerged from a product decision, data limitation, or business constraint outside the engineer’s control.</p>

<p>That does not mean nobody is responsible. It means software responsibility has to be organizational, not merely individual.</p>

<h2 id="what-the-paper-leaves-open">What the paper leaves open</h2>

<p>The paper is valuable as a survey and warning, but it does less to explain how responsibility should actually be assigned inside software organizations.</p>

<p>Several questions need more work:</p>

<ul>
  <li>What would a software “standard of care” look like for AI systems?</li>
  <li>Which duties should belong to engineers, product leaders, data scientists, executives, and companies?</li>
  <li>Should licensing apply to all software engineers, or only to those working in high-risk domains?</li>
  <li>How should certifications, professional societies, or bodies such as IEEE shape enforceable practice?</li>
  <li>How do existing frameworks such as GDPR or human-rights declarations become operational inside product development?</li>
</ul>

<p>The strongest version of this argument would move from analogy to mechanism. It would define what competent AI development requires, what evidence must be produced before deployment, and who is accountable when that evidence is ignored.</p>

<h2 id="bottom-line">Bottom line</h2>

<p>“Software Malpractice in the Age of AI” is worth reading because it names a real gap: AI systems are becoming professionally consequential without the professional accountability structure that older high-stakes domains developed over time.</p>

<p>But the solution cannot simply be “treat software engineers like doctors.” Software is too collaborative, too organizational, and too entangled with product and business incentives for that analogy to carry the whole burden.</p>

<p>AI malpractice, if the term is to mean anything useful, has to attach responsibility to the system of production. That includes the engineer, but it also includes the company that creates the incentives, approves the risks, and profits from the deployment.</p>

<h2 id="reference">Reference</h2>

<p>Danny Tobey, “Software Malpractice in the Age of AI: A Guide for the Wary Tech Company”, AIES 2018.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Article Review" /><category term="AI" /><category term="ai" /><category term="law" /><category term="software" /><category term="article-review" /><category term="opinion" /><summary type="html"><![CDATA[A review of Danny Tobey's argument that AI makes software malpractice harder to avoid, and why responsibility in software cannot be modeled exactly like medical malpractice.]]></summary></entry><entry><title type="html">[Book Review] Miner Town: Awakening (Miner Town, #1) by Ankit Saxena</title><link href="https://systemhalted.in/2026/07/20/book-review-miner-town-awakening-by-ankit-saxena/" rel="alternate" type="text/html" title="[Book Review] Miner Town: Awakening (Miner Town, #1) by Ankit Saxena" /><published>2026-07-20T00:00:00+00:00</published><updated>2026-07-20T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/20/book-review-miner-town-awakening-by-ankit-saxena</id><content type="html" xml:base="https://systemhalted.in/2026/07/20/book-review-miner-town-awakening-by-ankit-saxena/"><![CDATA[<p><em>I received a complimentary copy of this book and am leaving an honest review.</em></p>

<p>Miner Town: Awakening is a dystopian science fiction novel that blends post-apocalyptic survival, coming-of-age, and rebellion against an oppressive system. The world is imaginative and immediately engaging. Miner Town feels harsh, believable, and internally consistent, and the contrast between the mining settlement and the pristine Trinity cities provides a compelling foundation for the story.</p>

<p>The strongest aspect of the novel is its cast. Gage, Camilla, Otto, and Ben each represent different strengths, and their relationships drive much of the narrative. Rather than relying solely on action, the story spends time developing why these characters become who they are.</p>

<p>My main problem is with the prose. There is a vivid metaphor or philosophical reflection in every paragraph. While individually well written, their cumulative effect occasionally slows the narrative and reduces the impact of the strongest moments. The book would hit harder if it were plainer most of the time. Related issue: several pieces of exposition get delivered twice by different characters. Cutting those would help the pace.</p>

<p>Themes of sacrifice and exploitation are handled well, mostly because the author trusts the setting to carry them instead of having someone announce them.</p>

<p>An ambitious debut. If you liked The Hunger Games, you will recognize the genre. I will definitely like to read the next one.</p>

<p>Rating: 4.5/5</p>

<p>Find the book on <a href="https://a.co/d/0aG2qvUs">Amazon</a>.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="[&quot;Books &amp; Reading&quot;]" /><category term="book-review" /><category term="science-fiction" /><category term="dystopian" /><summary type="html"><![CDATA[An honest review of Miner Town Awakening, Ankit Saxena's ambitious dystopian science fiction debut - an imaginative world and a strong cast, held back a little by dense prose.]]></summary></entry><entry><title type="html">Agent Loops as a Team Diagnostic</title><link href="https://systemhalted.in/2026/07/17/agent-loops-as-a-team-diagnostic/" rel="alternate" type="text/html" title="Agent Loops as a Team Diagnostic" /><published>2026-07-17T00:00:00+00:00</published><updated>2026-07-17T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/17/agent-loops-as-a-team-diagnostic</id><content type="html" xml:base="https://systemhalted.in/2026/07/17/agent-loops-as-a-team-diagnostic/"><![CDATA[<p>In an <a href="/2026/07/03/what-sits-underneath-the-agent-loops-post/">earlier post</a> I wrote about the four kinds of agent loops that Anthropic’s Claude Code team described, and about where the check on the work lives in each one. The taxonomy also supports a practical exercise. A team can read the four types as four questions about its own work, and the answers point to the artifact it should write next.</p>

<p>The first question is what the team still verifies by hand. Every manual verification habit is a candidate skill file. The content is nothing more than the steps a reviewer already performs before trusting a change: what to start, what to click, what to compare, which tests to run. The habit feels too obvious to document, which is exactly why it never gets documented. A useful test for the finished file is whether a new team member could follow it without asking anyone.</p>

<p>The next question is how the team decides that a piece of work is done. If the honest answer is that an experienced person looks at it and says so, the missing artifact is a measurable exit criterion. A worthwhile exercise is to take one recent change that was accepted on judgement and restate the acceptance in checkable terms: a response time under a stated number, a set of tests that must pass, a score from an audit tool. Not every kind of done converts into a measurement, but more of them convert than the first attempt suggests, and each conversion is one less decision that has to be relitigated per change.</p>

<p>Then there are the tasks people do at the same time every day. A morning routine of reading a channel, sweeping a queue, or checking a dashboard is a schedule that exists only in someone’s habits. Writing it down as an actual schedule is the small step. The more valuable step is to ask what change in the world the routine is standing in for, and whether the system where that change happens can announce it. A webhook or a queue alert replaces a guess about timing with a fact about the source.</p>

<p>The last question concerns streams: bug reports, support tickets, dependency alerts, anything that arrives continuously and gets triaged by a person. This is where a proactive routine could stand, and it is also where the diagnostic has to be most careful. The routine needs a scoped goal, a budget, a rate limit, a shutoff, and an owner. The owner is the deciding item. If no one can be named who is responsible when the routine acts wrongly, the routine is not ready to build, whatever the tooling makes possible.</p>

<p>The output of the exercise is a short list: the checks nobody has written down, the criteria that live in one person’s judgement, the schedules that exist as habits, and the streams with no owner for their automation. A team does not need to adopt all four loops, and most should not. It needs to know which artifact on that list to write first.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Software Engineering" /><category term="AI" /><category term="ai" /><category term="agents" /><category term="claude-code" /><category term="engineering-management" /><summary type="html"><![CDATA[Four questions a team can ask about its own work, using Anthropic's agent loop taxonomy, to find the artifact it should write next.]]></summary></entry><entry><title type="html">The 2D↔1D Problem in Text Editors</title><link href="https://systemhalted.in/2026/07/17/the-2d-1d-problem-in-text-editors/" rel="alternate" type="text/html" title="The 2D↔1D Problem in Text Editors" /><published>2026-07-17T00:00:00+00:00</published><updated>2026-07-17T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/17/the-2d-1d-problem-in-text-editors</id><content type="html" xml:base="https://systemhalted.in/2026/07/17/the-2d-1d-problem-in-text-editors/"><![CDATA[<p>Open a file in any editor and you see a grid: rows of text, a cursor at “line 12, column 5.” Move down and the cursor drops a row. The position is two-dimensional.</p>

<p>But the file underneath is not a grid. A text file is a one-dimensional sequence: a flat run of characters, <code class="language-plaintext highlighter-rouge">h e l l o \n w o r l d</code>, where the newline is a character that means “start drawing on the next row.” The buffer that holds the document in memory is the same, a sequence you index with a single number.</p>

<p>So every editor lives with a permanent translation problem. This post looks at how a few of them solve it: a from-scratch Rust editor I’m building (<a href="https://github.com/systemhalted/textr">textr</a>), the two it is modeled on (<strong>gedit</strong> and <strong>Emacs</strong>), and <strong>VS Code</strong> for a fourth point of comparison.</p>

<ul id="markdown-toc">
  <li><a href="#the-impedance-mismatch" id="markdown-toc-the-impedance-mismatch">The impedance mismatch</a></li>
  <li><a href="#where-it-comes-up-in-textr" id="markdown-toc-where-it-comes-up-in-textr">Where it comes up in textr</a></li>
  <li><a href="#why-not-just-pick-one-and-be-done" id="markdown-toc-why-not-just-pick-one-and-be-done">Why not just pick one and be done?</a></li>
  <li><a href="#how-gedit-does-it-iterators-over-a-tree-cursor-as-mark" id="markdown-toc-how-gedit-does-it-iterators-over-a-tree-cursor-as-mark">How gedit does it: iterators over a tree, cursor-as-mark</a></li>
  <li><a href="#how-emacs-does-it-point-is-a-number-everything-else-is-derived" id="markdown-toc-how-emacs-does-it-point-is-a-number-everything-else-is-derived">How Emacs does it: point is a number, everything else is derived</a></li>
  <li><a href="#how-vs-code-does-it-a-piece-tree" id="markdown-toc-how-vs-code-does-it-a-piece-tree">How VS Code does it: a piece tree</a></li>
  <li><a href="#side-by-side" id="markdown-toc-side-by-side">Side by side</a></li>
  <li><a href="#the-choice-follows-the-data-structure-and-the-dominant-operation" id="markdown-toc-the-choice-follows-the-data-structure-and-the-dominant-operation">The choice follows the data structure and the dominant operation</a></li>
  <li><a href="#notes" id="markdown-toc-notes">Notes</a></li>
  <li><a href="#references" id="markdown-toc-references">References</a></li>
</ul>

<h2 id="the-impedance-mismatch">The impedance mismatch</h2>

<p>Two coordinate systems, describing the same text:</p>

<ul>
  <li><strong>Humans and screens think in 2D:</strong> <code class="language-plaintext highlighter-rouge">(line, column)</code>.</li>
  <li><strong>Files and buffers store 1D:</strong> a single offset into a sequence.</li>
</ul>

<p><img src="/assets/images/2026-07-17-2d-1d-grid.svg" alt="A caret shown in a 2D character grid on the left and mapped by an arrow to its position in a 1D flat, indexed character sequence on the right" />
<em>Figure 1 — The same caret, two coordinate systems. <code class="language-plaintext highlighter-rouge">(line 1, column 1)</code> on the left is flat index <code class="language-plaintext highlighter-rouge">4</code> on the right. The mapping between them is the editor’s job.</em></p>

<p>Bridging those two systems correctly and cheaply is one of the basic jobs of a text editor. Get it wrong and the cursor lands mid-character in a UTF-8 sequence, or an insert meant for one place writes three lines away.</p>

<h2 id="where-it-comes-up-in-textr">Where it comes up in textr</h2>

<p>This shows up in textr’s <code class="language-plaintext highlighter-rouge">View</code>, the cursor model.<sup id="fnref:textr"><a href="#fn:textr" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> The cursor is stored the way a user thinks about it:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">struct</span> <span class="n">View</span> <span class="p">{</span> <span class="n">line</span><span class="p">:</span> <span class="nb">usize</span><span class="p">,</span> <span class="n">column</span><span class="p">:</span> <span class="nb">usize</span><span class="p">,</span> <span class="n">goal_column</span><span class="p">:</span> <span class="nb">usize</span> <span class="p">}</span>
</code></pre></div></div>

<p>That is a 2D coordinate. But the buffer, a <a href="https://github.com/cessen/ropey">ropey</a> rope, has a strictly 1D editing API:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">doc</span><span class="nf">.insert</span><span class="p">(</span><span class="n">char_idx</span><span class="p">,</span> <span class="n">text</span><span class="p">);</span>   <span class="c1">// one index</span>
<span class="n">doc</span><span class="nf">.remove</span><span class="p">(</span><span class="n">char_idx</span><span class="o">..</span><span class="n">end</span><span class="p">);</span>    <span class="c1">// one index</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">insert</code> doesn’t know what a “line” is. To insert a character <em>where the cursor is</em>, I have to convert <code class="language-plaintext highlighter-rouge">(line, column)</code> into a single flat index. That conversion is one function:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">pub</span> <span class="k">fn</span> <span class="nf">cursor_char_idx</span><span class="p">(</span><span class="o">&amp;</span><span class="k">self</span><span class="p">,</span> <span class="n">doc</span><span class="p">:</span> <span class="o">&amp;</span><span class="n">Document</span><span class="p">)</span> <span class="k">-&gt;</span> <span class="nb">usize</span> <span class="p">{</span>
    <span class="n">doc</span><span class="nf">.line_to_char</span><span class="p">(</span><span class="k">self</span><span class="py">.line</span><span class="p">)</span> <span class="o">+</span> <span class="k">self</span><span class="py">.column</span>
<span class="p">}</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">line_to_char(line)</code> gives the flat index where that line <em>starts</em>; add <code class="language-plaintext highlighter-rouge">column</code> and you have the caret’s absolute position in the whole document. It’s tempting to think <code class="language-plaintext highlighter-rouge">column</code> already <em>is</em> the index — and on line 0 it is, because line 0 starts at 0. But look at <code class="language-plaintext highlighter-rouge">"ab\ncd"</code> with the caret on the <code class="language-plaintext highlighter-rouge">d</code>:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>             index:  0   1   2   3   4
             char:   a   b   \n  c   d
                                     ^
   (line 1, column 1)  -&gt;  line_to_char(1) + 1  =  3 + 1  =  4
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">column</code> is <code class="language-plaintext highlighter-rouge">1</code>, but the flat index is <code class="language-plaintext highlighter-rouge">4</code>. <code class="language-plaintext highlighter-rouge">column</code> is “where I am <em>on this line</em>”; the flat index is “where I am <em>in the file</em>.” The rope only understands the second one. (The reverse exists too, <code class="language-plaintext highlighter-rouge">char_to_line(idx)</code>, for when you have a flat position, like a search hit or a mouse click, and need to find the right row.)</p>

<p>Both conversions are cheap on a rope: ropey documents <code class="language-plaintext highlighter-rouge">line_to_char</code> and <code class="language-plaintext highlighter-rouge">char_to_line</code> as <em>O(log n)</em> each, and the <code class="language-plaintext highlighter-rouge">+ column</code> is <em>O(1)</em>, so moving a cursor between the two coordinate systems runs in <em>O(log n)</em> whichever way it goes.<sup id="fnref:ropes"><a href="#fn:ropes" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<h2 id="why-not-just-pick-one-and-be-done">Why not just pick one and be done?</h2>

<p>The harder question is not <em>how</em> to convert but <strong>which representation is the source of truth</strong>, and how it survives edits. There are a handful of strategies:</p>

<ol>
  <li><strong>Store 2D, derive 1D on demand</strong> <em>(textr’s choice)</em>. Keep <code class="language-plaintext highlighter-rouge">(line, column)</code> canonical; compute the flat index whenever the buffer needs it. Never store the index — a stored index goes stale the instant text changes ahead of it. <em>Pro:</em> vertical movement is native (Up/Down, and the “goal column” that remembers your column as you glide over short lines, are 2D ideas). <em>Con:</em> every edit must update the 2D cursor by hand, and 2D positions need clamping.</li>
  <li><strong>Store 1D, derive 2D on demand</strong> <em>(Emacs’s choice)</em>. Keep a single integer offset canonical; compute line and column only to display or move by rows. <em>Pro:</em> dead simple — a position is <em>one number</em>. <em>Con:</em> line and column now cost a computation you mitigate with caches.</li>
  <li><strong>Store both, keep them in sync.</strong> Fast reads either way, but now <em>two</em> things must be updated on <em>every</em> edit or they drift.</li>
  <li><strong>Hand out position <em>objects</em>.</strong> An “iterator” that internally carries both representations. Cheap to read either way — but typically <strong>invalidated by edits</strong>, so you can’t hold one across a modification.</li>
  <li><strong>Persistent marks.</strong> The subtle problem with any raw offset: if I remember “position 487” and someone inserts 10 characters at the top of the file, 487 now points somewhere wrong. A <strong>mark</strong> is a position the buffer <em>itself</em> keeps updated as text moves around it.</li>
</ol>

<p>The choice is not free-floating. It falls out of <strong>what the buffer is made of</strong>:</p>

<p><img src="/assets/images/2026-07-17-buffer-structures.svg" alt="Four buffer data structures — gap buffer, rope, B-tree, and piece table — each annotated with the operations it makes cheap and the coordinate it treats as canonical" />
<em>Figure 2 — The storage structure decides which coordinate is cheap, which in turn pushes the design toward 1D-canonical or 2D-canonical.</em><sup id="fnref:structures"><a href="#fn:structures" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>Strategies 4 and 5 are not hypothetical. gedit uses both: iterators for cheap reads and marks for persistence. Emacs uses markers (strategy 5) alongside its 1D point.</p>

<h2 id="how-gedit-does-it-iterators-over-a-tree-cursor-as-mark">How gedit does it: iterators over a tree, cursor-as-mark</h2>

<p>gedit is built on GTK’s <code class="language-plaintext highlighter-rouge">GtkTextView</code>/<code class="language-plaintext highlighter-rouge">GtkSourceView</code>, backed by a <a href="https://docs.gtk.org/gtk4/class.TextBuffer.html"><code class="language-plaintext highlighter-rouge">GtkTextBuffer</code></a>.<sup id="fnref:gtk"><a href="#fn:gtk" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> Internally that buffer isn’t a flat array — it’s a <strong>tree</strong> (a B-tree) that indexes lines and character/byte offsets, so it can answer “where does line N start?” and “what line is offset K on?” in roughly <em>O(log n)</em>. Both directions of our conversion are cheap by construction.</p>

<p>You never touch raw offsets directly. Instead you work with <a href="https://docs.gtk.org/gtk4/struct.TextIter.html"><code class="language-plaintext highlighter-rouge">GtkTextIter</code></a> — a small stack-allocated struct representing a position, obtained from <em>either</em> coordinate system:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">GtkTextIter</span> <span class="n">iter</span><span class="p">;</span>
<span class="n">gtk_text_buffer_get_iter_at_line_offset</span><span class="p">(</span><span class="n">buffer</span><span class="p">,</span> <span class="o">&amp;</span><span class="n">iter</span><span class="p">,</span> <span class="n">line</span><span class="p">,</span> <span class="n">column</span><span class="p">);</span> <span class="c1">// from 2D</span>
<span class="n">gtk_text_buffer_get_iter_at_offset</span><span class="p">(</span><span class="n">buffer</span><span class="p">,</span> <span class="o">&amp;</span><span class="n">iter</span><span class="p">,</span> <span class="n">char_offset</span><span class="p">);</span>       <span class="c1">// from 1D</span>
</code></pre></div></div>

<p>And crucially, an iter carries <em>both</em> representations at once — you can ask it for its line (<code class="language-plaintext highlighter-rouge">gtk_text_iter_get_line</code>), its column (<code class="language-plaintext highlighter-rouge">gtk_text_iter_get_line_offset</code>), or its absolute char offset (<code class="language-plaintext highlighter-rouge">gtk_text_iter_get_offset</code>). The 2D↔1D conversion is baked <em>into the iterator</em>, powered by that tree. GTK’s answer to “which is the source of truth?” is essentially <strong>“neither — the tree makes both cheap.”</strong></p>

<p>The catch: <strong>a <code class="language-plaintext highlighter-rouge">GtkTextIter</code> is transient — invalidated the moment the buffer is modified.</strong> So you don’t store iters; you re-fetch them.</p>

<p>For positions that must <em>persist</em> across edits, GTK gives you <a href="https://docs.gtk.org/gtk4/class.TextMark.html"><code class="language-plaintext highlighter-rouge">GtkTextMark</code></a>, a named position the buffer maintains automatically. gedit’s cursor is a mark named <code class="language-plaintext highlighter-rouge">"insert"</code> (the selection’s other end is <code class="language-plaintext highlighter-rouge">"selection_bound"</code>). To render the caret, gedit gets an iter at the <code class="language-plaintext highlighter-rouge">"insert"</code> mark and reads its line and column; to type a character, it inserts at that iter. The persistence problem (strategy 5) and the conversion problem (strategy 4) are handled by two separate abstractions.</p>

<p><img src="/assets/images/2026-07-17-gedit-statusbar.png" alt="gedit editing the Markdown source of this post, with &quot;Ln 5, Col 12&quot; shown in the status bar" />
<em>Figure 3 — gedit with this post’s draft open. The status bar reads “Ln 5, Col 12”, the 2D face of the <code class="language-plaintext highlighter-rouge">"insert"</code> mark.</em></p>
<h2 id="how-emacs-does-it-point-is-a-number-everything-else-is-derived">How Emacs does it: point is a number, everything else is derived</h2>

<p>Emacs comes at it from the opposite end. Its buffer is a classic <strong>gap buffer</strong> — one big array of characters with a movable gap where edits happen, which makes insertion and deletion <em>at the cursor</em> very cheap.<sup id="fnref:emacs"><a href="#fn:emacs" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<p>Position in Emacs is <a href="https://www.gnu.org/software/emacs/manual/html_node/elisp/Point.html"><strong>point</strong></a>: a single integer, the character offset of the caret (1-based — <code class="language-plaintext highlighter-rouge">point-min</code> is 1; positions sit <em>between</em> characters). Point is 1D and canonical. Almost every primitive takes or returns a buffer position as a plain integer.</p>

<p>Line and column are <strong>not stored</strong> — they’re computed when asked:</p>

<div class="language-elisp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="nv">line-number-at-pos</span><span class="p">)</span>   <span class="c1">; scan / caches to count newlines before point</span>
<span class="p">(</span><span class="nv">current-column</span><span class="p">)</span>       <span class="c1">; scan back to line start, honoring tab-width and char widths</span>
</code></pre></div></div>

<p><a href="https://www.gnu.org/software/emacs/manual/html_node/elisp/Columns.html"><code class="language-plaintext highlighter-rouge">current-column</code></a> shows that “column” is subtler than a character count: Emacs makes a tab advance to the next tab stop and accounts for wide characters, so the <em>visual</em> column and the <em>character</em> column differ. (textr, for now, uses character columns, a documented simplification.)<sup id="fnref:unicode"><a href="#fn:unicode" class="footnote" rel="footnote" role="doc-noteref">6</a></sup></p>

<p>Computing line numbers means scanning for newlines — <em>O(distance)</em> — so Emacs keeps caches to amortize it (line-number lookup on a multi-megabyte buffer is a real, historically-tuned concern). For persistence, Emacs has <a href="https://www.gnu.org/software/emacs/manual/html_node/elisp/Markers.html"><strong>markers</strong></a> — objects that hold a position and are automatically nudged as text is inserted or deleted before them, with an <a href="https://www.gnu.org/software/emacs/manual/html_node/elisp/Marker-Insertion-Types.html">insertion type</a> that decides whether a marker sticks or advances when text lands exactly on it. Same idea as GTK’s marks, different name.</p>

<p>Emacs also separates <strong>character positions from byte positions</strong> (<a href="https://www.gnu.org/software/emacs/manual/html_node/elisp/Text-Representations.html"><code class="language-plaintext highlighter-rouge">position-bytes</code></a>) in multibyte buffers, so ordinary code can index by character and never split a multibyte sequence, the same reason textr indexes by <code class="language-plaintext highlighter-rouge">char</code>, never by byte.</p>

<p><img src="/assets/images/2026-07-17-emacs-modeline.png" alt="Emacs editing the same Markdown source, with (12,4) shown in the mode line" />
<em>Figure 4 — Emacs with the same file open. The mode line reads <code class="language-plaintext highlighter-rouge">(12,4)</code>, the line and column derived from point.</em></p>

<h2 id="how-vs-code-does-it-a-piece-tree">How VS Code does it: a piece tree</h2>

<p>VS Code reaches a similar place to textr from a different direction.<sup id="fnref:vscode"><a href="#fn:vscode" class="footnote" rel="footnote" role="doc-noteref">7</a></sup> Its buffer is a <strong>piece tree</strong>: a piece table whose pieces hang off a balanced red-black tree, where each node caches the text length and line-break count of its subtree, so a lookup by line or by offset walks the tree in roughly <em>O(log n)</em> instead of scanning. Its canonical position is 2D, like textr’s — the editor keeps the cursor as a <a href="https://microsoft.github.io/monaco-editor/typedoc/interfaces/IPosition.html"><code class="language-plaintext highlighter-rouge">Position</code></a> of <code class="language-plaintext highlighter-rouge">lineNumber</code> and <code class="language-plaintext highlighter-rouge">column</code>, both 1-based, and the flat offset is derived on demand through <code class="language-plaintext highlighter-rouge">getOffsetAt</code> and its inverse <code class="language-plaintext highlighter-rouge">getPositionAt</code>. The reason for keeping 2D canonical differs from textr’s, though: the whole editor API is written in terms of <code class="language-plaintext highlighter-rouge">Position</code>, so 2D is the natural currency for the interface, not because vertical movement is the hardest job.</p>

<p>One detail sets VS Code apart from the other three. It measures <code class="language-plaintext highlighter-rouge">column</code> and the offset in <strong>UTF-16 code units</strong>, not characters, so an emoji outside the Basic Multilingual Plane counts as two columns and a grapheme built from combining marks spans several units. textr, gedit, and Emacs all index by <code class="language-plaintext highlighter-rouge">char</code> (Unicode scalar values); VS Code indexes by UTF-16 unit, and the two do not agree on where a given column falls.</p>

<h2 id="side-by-side">Side by side</h2>

<table>
  <thead>
    <tr>
      <th> </th>
      <th><strong>textr</strong> (Rust)</th>
      <th><strong>gedit</strong> (GTK/C)</th>
      <th><strong>Emacs</strong> (C/Elisp)</th>
      <th><strong>VS Code</strong> (Monaco/TS)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Buffer structure</td>
      <td>rope (ropey)</td>
      <td>B-tree (<code class="language-plaintext highlighter-rouge">GtkTextBTree</code>)</td>
      <td>gap buffer</td>
      <td>piece tree</td>
    </tr>
    <tr>
      <td>Canonical position</td>
      <td><strong>2D</strong> <code class="language-plaintext highlighter-rouge">(line, column)</code></td>
      <td>a <strong>mark</strong>; read via iters</td>
      <td><strong>1D</strong> <code class="language-plaintext highlighter-rouge">point</code> (integer)</td>
      <td><strong>2D</strong> <code class="language-plaintext highlighter-rouge">Position</code> (line, column)</td>
    </tr>
    <tr>
      <td>2D → 1D</td>
      <td><code class="language-plaintext highlighter-rouge">line_to_char + col</code> — <em>O(log n)</em></td>
      <td>build a <code class="language-plaintext highlighter-rouge">GtkTextIter</code> — <em>O(log n)</em></td>
      <td>rare; <code class="language-plaintext highlighter-rouge">goto-line</code> scans</td>
      <td><code class="language-plaintext highlighter-rouge">getOffsetAt</code> — <em>O(log n)</em></td>
    </tr>
    <tr>
      <td>1D → 2D</td>
      <td><code class="language-plaintext highlighter-rouge">char_to_line</code> — <em>O(log n)</em></td>
      <td>iter carries line + offset</td>
      <td><code class="language-plaintext highlighter-rouge">line-number-at-pos</code> — scan + cache</td>
      <td><code class="language-plaintext highlighter-rouge">getPositionAt</code> — <em>O(log n)</em></td>
    </tr>
    <tr>
      <td>Persist across edits</td>
      <td>recompute from <code class="language-plaintext highlighter-rouge">(line,col)</code></td>
      <td><code class="language-plaintext highlighter-rouge">GtkTextMark</code></td>
      <td>markers</td>
      <td>tracked ranges</td>
    </tr>
    <tr>
      <td>Indexing unit</td>
      <td>chars</td>
      <td>chars (bytes tracked too)</td>
      <td>chars (bytes separate)</td>
      <td>UTF-16 code units</td>
    </tr>
  </tbody>
</table>

<h2 id="the-choice-follows-the-data-structure-and-the-dominant-operation">The choice follows the data structure and the dominant operation</h2>

<p>There is no universally correct answer, only trade-offs that fall out of two things: <strong>what the buffer is good at</strong>, and <strong>which operation you do most</strong>.</p>

<ul>
  <li>Emacs’s gap buffer makes <em>offsets</em> cheap and edits-at-point cheap, so 1D-canonical is the simplest choice; it pays for line and column with scans and caches.</li>
  <li>gedit’s tree makes <em>both</em> directions cheap, so it can afford to hide the whole question behind iterators and lean on marks for persistence.</li>
  <li>textr’s rope also makes both directions cheap (<em>O(log n)</em> either way), so the choice was free. I picked <strong>2D-canonical</strong> because the <code class="language-plaintext highlighter-rouge">View</code>’s busiest and hardest job is <em>vertical</em> movement with a goal column, which is a 2D idea. The representation matches the operation it does most.</li>
  <li>VS Code’s piece tree makes both directions cheap like gedit’s, and it too keeps a 2D <code class="language-plaintext highlighter-rouge">Position</code> canonical — but for a different reason than textr: its whole editor API speaks in positions, so 2D is a matter of interface rather than of any single dominant operation.</li>
</ul>

<p>One point is easy to miss: a raw offset is only correct for one moment. Once the text changes ahead of it, an old index points to the wrong place. That is why converting on demand (textr) or letting the buffer maintain the position (marks and markers) is safer than storing the number and reusing it. textr avoids the problem today because it has a single cursor that updates itself; when it grows multiple cursors or collaborative editing, it will want marks too, for the same reason every editor eventually adopts them.</p>

<hr />

<h2 id="notes">Notes</h2>

<ul>
  <li><strong><code class="language-plaintext highlighter-rouge">GtkTextIter</code> is a value, not a handle.</strong> It’s valid only until the next buffer mutation; treat it as a snapshot and re-fetch after any edit. Persistent positions are <code class="language-plaintext highlighter-rouge">GtkTextMark</code>s, not stored iters.</li>
  <li><strong>Marker insertion type</strong> decides the tie-break: when text is inserted exactly <em>at</em> a marker, does the marker stay put or advance past the new text? Emacs lets you choose per-marker; it’s the kind of detail that quietly determines whether your saved position feels “before” or “after” an edit.</li>
  <li><strong>Character vs byte positions</strong> are different numbers in any multibyte buffer. textr indexes by <code class="language-plaintext highlighter-rouge">char</code> throughout and never does byte math (ropey also exposes byte-index methods; textr uses only the char ones) — which is why inserting a precomposed <code class="language-plaintext highlighter-rouge">'é'</code> (U+00E9: one <code class="language-plaintext highlighter-rouge">char</code>, two UTF-8 bytes) advances the cursor by exactly one column. A decomposed <code class="language-plaintext highlighter-rouge">'é'</code> (<code class="language-plaintext highlighter-rouge">e</code> + a combining accent) is two chars and would advance by two — so this assumes NFC-normalized input; char indexing is not grapheme indexing.</li>
  <li><strong>ropey’s phantom trailing line.</strong> A rope for <code class="language-plaintext highlighter-rouge">"a\nb\n"</code> reports <em>three</em> lines — <code class="language-plaintext highlighter-rouge">"a\n"</code>, <code class="language-plaintext highlighter-rouge">"b\n"</code>, and a final empty <code class="language-plaintext highlighter-rouge">""</code>. The caret may rest on that empty line but no further; textr’s <code class="language-plaintext highlighter-rouge">line_len_chars</code> helper strips the trailing <code class="language-plaintext highlighter-rouge">\n</code> so “end of line” lands before it, not after.</li>
  <li><strong>“Column” is not “display column.”</strong> This post (and textr, today) uses <em>character</em> columns. A real editor’s visible column has to account for tab stops and wide/zero-width characters — which is exactly what Emacs’s <code class="language-plaintext highlighter-rouge">current-column</code> does and where grapheme-cluster segmentation (UAX #29) eventually comes in.</li>
  <li><strong>textr is a learning project</strong> — a from-scratch <a href="https://gedit-text-editor.org/">gedit</a> clone I’m building to learn Rust, with a headless, UI-agnostic core and thin frontends. The 2D↔1D bridge above is one small, load-bearing piece of its <code class="language-plaintext highlighter-rouge">View</code>.</li>
</ul>

<h2 id="references">References</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:textr">
      <p>textr’s source — the <code class="language-plaintext highlighter-rouge">View</code> cursor model in <a href="https://github.com/systemhalted/textr/blob/main/crates/core/src/view.rs"><code class="language-plaintext highlighter-rouge">crates/core/src/view.rs</code></a> and the rope wrappers in <a href="https://github.com/systemhalted/textr/blob/main/crates/core/src/document.rs"><code class="language-plaintext highlighter-rouge">crates/core/src/document.rs</code></a>; org-flavored sibling editor <a href="https://github.com/systemhalted/textr-org">textr-org</a>. <a href="#fnref:textr" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:ropes">
      <p>ropey <a href="https://docs.rs/ropey">docs</a> (<code class="language-plaintext highlighter-rouge">line_to_char</code>, <code class="language-plaintext highlighter-rouge">char_to_line</code>, <code class="language-plaintext highlighter-rouge">len_chars</code>). On ropes generally: Boehm, Atkinson &amp; Plass, <em>“Ropes: an Alternative to Strings”</em> (Software: Practice and Experience, 1995), <a href="https://doi.org/10.1002/spe.4380251203">doi.org/10.1002/spe.4380251203</a>; Raph Levien, <em>“Rope science”</em> (xi-editor notes), <a href="https://xi-editor.io/docs/rope_science_00.html">xi-editor.io</a>. <a href="#fnref:ropes" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:structures">
      <p><a href="https://en.wikipedia.org/wiki/Gap_buffer">Gap buffer</a> and <a href="https://en.wikipedia.org/wiki/Piece_table">piece table</a> on Wikipedia; VS Code’s <em>“Text Buffer Reimplementation”</em> (their <strong>piece tree</strong> — a piece table backed by a red-black tree): <a href="https://code.visualstudio.com/blogs/2018/03/23/text-buffer-reimplementation">code.visualstudio.com</a>. <a href="#fnref:structures" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:gtk">
      <p><a href="https://gedit-text-editor.org/">gedit</a> · <a href="https://gitlab.gnome.org/GNOME/gedit">source</a>; the B-tree that powers <code class="language-plaintext highlighter-rouge">GtkTextBuffer</code>, <a href="https://gitlab.gnome.org/GNOME/gtk/-/blob/main/gtk/gtktextbtree.c"><code class="language-plaintext highlighter-rouge">gtktextbtree.c</code></a>. <a href="#fnref:gtk" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:emacs">
      <p>Emacs <a href="https://www.gnu.org/software/emacs/manual/html_node/elisp/Buffer-Internals.html">buffer internals — the gap</a>; source at <a href="https://git.savannah.gnu.org/cgit/emacs.git">git.savannah.gnu.org</a> (<code class="language-plaintext highlighter-rouge">src/buffer.h</code>, <code class="language-plaintext highlighter-rouge">src/insdel.c</code>, <code class="language-plaintext highlighter-rouge">src/marker.c</code>). <a href="#fnref:emacs" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:unicode">
      <p><a href="https://unicode.org/reports/tr29/">UAX #29, <em>Unicode Text Segmentation</em></a> (grapheme clusters); Rust crates <a href="https://docs.rs/unicode-width"><code class="language-plaintext highlighter-rouge">unicode-width</code></a> (display width, UAX #11) and <a href="https://docs.rs/unicode-segmentation"><code class="language-plaintext highlighter-rouge">unicode-segmentation</code></a> (UAX #29). <a href="#fnref:unicode" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:vscode">
      <p>VS Code / Monaco — <code class="language-plaintext highlighter-rouge">Position</code> (<code class="language-plaintext highlighter-rouge">lineNumber</code>/<code class="language-plaintext highlighter-rouge">column</code>, 1-based) in <a href="https://github.com/microsoft/vscode/blob/main/src/vs/editor/common/core/position.ts"><code class="language-plaintext highlighter-rouge">position.ts</code></a> and the <a href="https://microsoft.github.io/monaco-editor/typedoc/interfaces/IPosition.html"><code class="language-plaintext highlighter-rouge">IPosition</code></a> typedoc; <code class="language-plaintext highlighter-rouge">getOffsetAt</code>/<code class="language-plaintext highlighter-rouge">getPositionAt</code> in <a href="https://github.com/microsoft/vscode/blob/main/src/vs/editor/common/model.ts"><code class="language-plaintext highlighter-rouge">model.ts</code></a>; columns measured in UTF-16 code units per <a href="https://github.com/microsoft/vscode/blob/main/src/vscode-dts/vscode.d.ts"><code class="language-plaintext highlighter-rouge">vscode.d.ts</code></a>. <a href="#fnref:vscode" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Computer Science" /><category term="rust" /><category term="text-editors" /><category term="emacs" /><category term="gedit" /><category term="data-structures" /><category term="unicode" /><summary type="html"><![CDATA[Editors show a 2D grid but store text as a 1D sequence. How textr, gedit, and Emacs bridge the gap, and why the choice follows the buffer's data structure.]]></summary></entry><entry><title type="html">JPMS and Cargo: Two Answers to the Same Problem</title><link href="https://systemhalted.in/2026/07/12/jpms-and-cargo-two-answers-to-the-same-problem/" rel="alternate" type="text/html" title="JPMS and Cargo: Two Answers to the Same Problem" /><published>2026-07-12T00:00:00+00:00</published><updated>2026-07-12T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/12/jpms-and-cargo-two-answers-to-the-same-problem</id><content type="html" xml:base="https://systemhalted.in/2026/07/12/jpms-and-cargo-two-answers-to-the-same-problem/"><![CDATA[<p>Every language with a serious ecosystem eventually has to answer three related questions:</p>

<ol>
  <li>How is code compiled?</li>
  <li>How is it distributed?</li>
  <li>Where is encapsulation enforced?</li>
</ol>

<p>Java accumulated its answers over time. Source files and packages came from the language, JARs became the distribution unit, and JPMS arrived in 2017 to add strong encapsulation and explicit dependency readability.</p>

<p>Rust and Cargo started with a more integrated model, designed together around a standard package and build system.</p>

<p>The two systems answer the same three questions but put the answers in different places. Java spreads them across pieces assembled over two decades — packages and the module system in the language, JARs and Maven outside it — that must stay consistent without anything forcing them to. Rust concentrates compilation and encapsulation in the crate and distribution in the Cargo package, with far less overlap.</p>

<h2 id="the-terms">The terms</h2>

<p>Both toolchains reuse a few of the same words for different things, so it helps to fix the vocabulary before the code.</p>

<p><strong>Rust / Cargo</strong></p>

<ul>
  <li><strong>Crate</strong> — the unit the compiler compiles, and the unit of encapsulation. A crate is either a <em>library crate</em> or a <em>binary crate</em>.</li>
  <li><strong>Package</strong> — what Cargo versions, builds, and publishes, described by <code class="language-plaintext highlighter-rouge">Cargo.toml</code>. A package holds at most one library crate and any number of binary crates.</li>
  <li><strong>Module</strong> (<code class="language-plaintext highlighter-rouge">mod</code>) — a namespace <em>inside</em> a crate. Modules form a tree, and that tree is where visibility is enforced.</li>
  <li><strong>Workspace</strong> — a set of packages that share one <code class="language-plaintext highlighter-rouge">Cargo.lock</code> and one build.</li>
</ul>

<p><strong>Java / Maven / JPMS</strong></p>

<ul>
  <li><strong>Package</strong> — a namespace declared per source file (<code class="language-plaintext highlighter-rouge">package in.systemhalted.gateway.api;</code>).</li>
  <li><strong>Module (JPMS)</strong> — a named group of packages with a <code class="language-plaintext highlighter-rouge">module-info.java</code> that declares what it reads and what it exports. The unit of strong encapsulation.</li>
  <li><strong>Artifact (Maven)</strong> — the versioned, publishable unit, identified by <code class="language-plaintext highlighter-rouge">groupId:artifactId:version</code> and shipped as a JAR.</li>
  <li><strong>JAR</strong> — the packaging and distribution format.</li>
</ul>

<p><strong>Shared</strong></p>

<ul>
  <li><strong>Dependency</strong> — code from another package, artifact, crate, or module that this component uses. Maven resolves and fetches a Java dependency, while JPMS separately determines module readability through <code class="language-plaintext highlighter-rouge">requires</code>. Cargo resolves a Rust dependency and makes the corresponding crate available to the compiler from the same manifest declaration.</li>
</ul>

<p>The words already collide. A Rust <em>crate</em> is closest to a JPMS <em>module</em>, a Rust <em>module</em> to a Java <em>package</em>, and a Cargo <em>package</em> to a Maven <em>artifact</em>. None of these is exact — a crate resembles a JPMS module in encapsulation and dependency structure more than in the mechanics of compilation — and “module” means almost opposite-scale things in the two worlds. The rest of this post lines these up against the three questions and shows where the words look alike but aren’t.</p>

<h2 id="the-same-project-twice">The same project, twice</h2>

<p>Consider a small API gateway library with a public API, a configuration type, and an internal routing engine.</p>

<p>Here is the Java version, built with Maven and JPMS:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gateway/
├── pom.xml
└── src/main/java/
    ├── module-info.java
    └── in/systemhalted/gateway/
        ├── api/
        │   └── RouteHandler.java
        ├── config/
        │   └── GatewayConfig.java
        └── internal/
            └── Router.java
</code></pre></div></div>

<p>And the Rust version:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gateway/
├── Cargo.toml
└── src/
    ├── lib.rs
    ├── api.rs
    ├── api/
    │   └── handlers.rs
    ├── config.rs
    ├── internal.rs
    └── internal/
        └── router.rs
</code></pre></div></div>

<p>Four files reveal most of the architectural difference: <code class="language-plaintext highlighter-rouge">pom.xml</code>, <code class="language-plaintext highlighter-rouge">module-info.java</code>, <code class="language-plaintext highlighter-rouge">Cargo.toml</code>, and <code class="language-plaintext highlighter-rouge">lib.rs</code>. They do not map one-to-one. Understanding why is most of understanding the two systems.</p>

<h2 id="the-four-files">The four files</h2>

<h3 id="pomxml-identity-and-dependencies">pom.xml: identity and dependencies</h3>

<p>The POM belongs to Maven, not to the Java language. It declares the artifact’s coordinates and the dependencies required to build it:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nt">&lt;groupId&gt;</span>in.systemhalted<span class="nt">&lt;/groupId&gt;</span>
<span class="nt">&lt;artifactId&gt;</span>gateway<span class="nt">&lt;/artifactId&gt;</span>
<span class="nt">&lt;version&gt;</span>1.4.0<span class="nt">&lt;/version&gt;</span>
<span class="nt">&lt;dependencies&gt;</span>
    <span class="nt">&lt;dependency&gt;</span>
        <span class="nt">&lt;groupId&gt;</span>com.fasterxml.jackson.core<span class="nt">&lt;/groupId&gt;</span>
        <span class="nt">&lt;artifactId&gt;</span>jackson-databind<span class="nt">&lt;/artifactId&gt;</span>
        <span class="nt">&lt;version&gt;</span>2.17.1<span class="nt">&lt;/version&gt;</span>
    <span class="nt">&lt;/dependency&gt;</span>
<span class="nt">&lt;/dependencies&gt;</span>
</code></pre></div></div>

<p>Maven resolves the dependency, downloads the JAR, and constructs the classpath or module path. <code class="language-plaintext highlighter-rouge">javac</code> knows nothing about the POM.</p>

<h3 id="module-infojava-readability-and-exports">module-info.java: readability and exports</h3>

<p>The module descriptor lives at the root of the Java source tree, at <code class="language-plaintext highlighter-rouge">src/main/java/module-info.java</code>. It is part of the Java language and is compiled by <code class="language-plaintext highlighter-rouge">javac</code>.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">module</span> <span class="n">in</span><span class="o">.</span><span class="na">systemhalted</span><span class="o">.</span><span class="na">gateway</span> <span class="o">{</span>
    <span class="n">requires</span> <span class="n">com</span><span class="o">.</span><span class="na">fasterxml</span><span class="o">.</span><span class="na">jackson</span><span class="o">.</span><span class="na">databind</span><span class="o">;</span>
    <span class="n">exports</span> <span class="n">in</span><span class="o">.</span><span class="na">systemhalted</span><span class="o">.</span><span class="na">gateway</span><span class="o">.</span><span class="na">api</span><span class="o">;</span>
    <span class="n">exports</span> <span class="n">in</span><span class="o">.</span><span class="na">systemhalted</span><span class="o">.</span><span class="na">gateway</span><span class="o">.</span><span class="na">config</span><span class="o">;</span>
    <span class="c1">// in.systemhalted.gateway.internal is not exported</span>
<span class="o">}</span>
</code></pre></div></div>

<p>The descriptor declares two boundaries: which modules this module reads, and which packages it exposes.</p>

<p>Jackson therefore appears twice. The POM tells Maven to obtain the JAR; the descriptor tells JPMS that this module may read it. These are separate systems, and nothing forces them to agree: a dependency can sit on the module path without a matching <code class="language-plaintext highlighter-rouge">requires</code>, or be declared with <code class="language-plaintext highlighter-rouge">requires</code> without being supplied by the build. The two names even differ — the Maven artifactId is <code class="language-plaintext highlighter-rouge">jackson-databind</code>, the JPMS module name <code class="language-plaintext highlighter-rouge">com.fasterxml.jackson.databind</code>. Coordinate and module identity are separate namespaces.</p>

<h3 id="cargotoml-the-package-manifest">Cargo.toml: the package manifest</h3>

<p><code class="language-plaintext highlighter-rouge">Cargo.toml</code> describes the Cargo package:</p>

<div class="language-toml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">[</span><span class="n">package</span><span class="k">]</span>
<span class="n">name</span> <span class="o">=</span><span class="w"> </span><span class="s">"gateway"</span>
<span class="n">version</span> <span class="o">=</span><span class="w"> </span><span class="s">"1.4.0"</span>

<span class="k">[</span><span class="n">dependencies</span><span class="k">]</span>
<span class="n">serde_json</span> <span class="o">=</span><span class="w"> </span><span class="s">"1"</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">gateway</code> package here is a single library crate, <code class="language-plaintext highlighter-rouge">src/lib.rs</code>. Add a <code class="language-plaintext highlighter-rouge">src/main.rs</code> and it would hold two crates, a library and a binary. The crate is where visibility and module boundaries apply.</p>

<p>Declaring a dependency in <code class="language-plaintext highlighter-rouge">Cargo.toml</code> both resolves it and makes it available during compilation; Cargo invokes <code class="language-plaintext highlighter-rouge">rustc</code> with the corresponding <code class="language-plaintext highlighter-rouge">--extern</code> arguments. There is no separate language-level file holding a second copy of the dependency declaration.</p>

<h3 id="librs-the-crate-root">lib.rs: the crate root</h3>

<p><code class="language-plaintext highlighter-rouge">lib.rs</code> is not a manifest. It is source code — the root of the library crate and the starting point of the crate’s module tree:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// src/lib.rs</span>
<span class="k">pub</span> <span class="k">mod</span> <span class="n">api</span><span class="p">;</span>
<span class="k">pub</span> <span class="k">mod</span> <span class="n">config</span><span class="p">;</span>
<span class="k">mod</span> <span class="n">internal</span><span class="p">;</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">pub mod api;</code> loads <code class="language-plaintext highlighter-rouge">src/api.rs</code> and makes the module publicly reachable; <code class="language-plaintext highlighter-rouge">mod internal;</code> loads <code class="language-plaintext highlighter-rouge">src/internal.rs</code> but does not make it reachable outside the crate.</p>

<p>This is where part of the Java module descriptor’s role moves into source. The descriptor’s <code class="language-plaintext highlighter-rouge">exports in.systemhalted.gateway.api;</code> and the crate root’s <code class="language-plaintext highlighter-rouge">pub mod api;</code> are not exact equivalents, but serve the same purpose: defining the externally reachable surface. In Rust the dependency side lives in <code class="language-plaintext highlighter-rouge">Cargo.toml</code>, the visibility side in ordinary source.</p>

<h2 id="where-the-module-tree-comes-from">Where the module tree comes from</h2>

<p>The deeper difference is not the file names. It is who defines the structure.</p>

<h3 id="java-packages-are-declared-independently">Java packages are declared independently</h3>

<p>Every Java source file declares its package, such as <code class="language-plaintext highlighter-rouge">package in.systemhalted.gateway.internal;</code>. Build tools conventionally mirror that name in the source directory, as <code class="language-plaintext highlighter-rouge">in/systemhalted/gateway/internal/Router.java</code>. But the package declaration defines membership: no parent package registers the class, and no other source file has to mention it.</p>

<p>A Java package is a flat namespace. The dots suggest hierarchy, but there is none: <code class="language-plaintext highlighter-rouge">a.b</code> and <code class="language-plaintext highlighter-rouge">a.b.c</code> are separate packages, and <code class="language-plaintext highlighter-rouge">a.b.c</code> is not semantically nested inside <code class="language-plaintext highlighter-rouge">a.b</code>.</p>

<h3 id="rust-modules-form-an-explicit-tree">Rust modules form an explicit tree</h3>

<p>In Rust, a file does not join the crate merely by existing on disk; a parent module must declare it. In <code class="language-plaintext highlighter-rouge">src/lib.rs</code>, <code class="language-plaintext highlighter-rouge">mod internal;</code> brings <code class="language-plaintext highlighter-rouge">src/internal.rs</code> into the crate. In turn, <code class="language-plaintext highlighter-rouge">src/internal.rs</code>’s <code class="language-plaintext highlighter-rouge">pub mod router;</code> brings <code class="language-plaintext highlighter-rouge">src/internal/router.rs</code> into the tree, and <code class="language-plaintext highlighter-rouge">src/api.rs</code>’s <code class="language-plaintext highlighter-rouge">pub mod handlers;</code> brings <code class="language-plaintext highlighter-rouge">src/api/handlers.rs</code>. Remove the <code class="language-plaintext highlighter-rouge">mod router;</code> declaration and the compiler never reads <code class="language-plaintext highlighter-rouge">router.rs</code>, even if the file remains on disk. The filesystem follows the module tree; it does not create it.</p>

<p>This explains why the layout carries both <code class="language-plaintext highlighter-rouge">internal.rs</code> and an <code class="language-plaintext highlighter-rouge">internal/</code> directory: <code class="language-plaintext highlighter-rouge">internal.rs</code> defines the module, <code class="language-plaintext highlighter-rouge">internal/</code> holds its child modules. A leaf module such as <code class="language-plaintext highlighter-rouge">config</code> needs only <code class="language-plaintext highlighter-rouge">config.rs</code>. The older <code class="language-plaintext highlighter-rouge">internal/mod.rs</code> layout still works, but the <code class="language-plaintext highlighter-rouge">internal.rs</code>-plus-<code class="language-plaintext highlighter-rouge">internal/</code> style is now common.</p>

<h2 id="visibility-follows-the-tree">Visibility follows the tree</h2>

<p>Once the tree exists, visibility is evaluated along paths through it. Consider:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// src/internal/router.rs</span>
<span class="k">pub</span> <span class="k">struct</span> <span class="n">Router</span> <span class="p">{</span> <span class="cm">/* ... */</span> <span class="p">}</span>

<span class="k">pub</span><span class="p">(</span><span class="k">crate</span><span class="p">)</span> <span class="k">fn</span> <span class="nf">rebuild_routes</span><span class="p">()</span> <span class="p">{</span>
<span class="p">}</span>

<span class="k">pub</span><span class="p">(</span><span class="k">super</span><span class="p">)</span> <span class="k">fn</span> <span class="nf">debug_dump</span><span class="p">()</span> <span class="p">{</span>
<span class="p">}</span>

<span class="k">pub</span><span class="p">(</span><span class="k">in</span> <span class="k">crate</span><span class="p">::</span><span class="n">internal</span><span class="p">)</span> <span class="k">fn</span> <span class="nf">merge</span><span class="p">()</span> <span class="p">{</span>
<span class="p">}</span>

<span class="k">fn</span> <span class="nf">parse_segment</span><span class="p">()</span> <span class="p">{</span>
<span class="p">}</span>
</code></pre></div></div>

<p>These declarations represent different visibility scopes.</p>

<h3 id="pub-is-bounded-by-the-path">pub is bounded by the path</h3>

<p>This is the first rule that often surprises Java developers. <code class="language-plaintext highlighter-rouge">pub struct Router;</code> does not necessarily make <code class="language-plaintext highlighter-rouge">Router</code> reachable outside the crate; every module along the path must also be public. The full path is <code class="language-plaintext highlighter-rouge">crate::internal::router::Router</code>, but <code class="language-plaintext highlighter-rouge">lib.rs</code> declared <code class="language-plaintext highlighter-rouge">mod internal;</code>, not <code class="language-plaintext highlighter-rouge">pub mod internal;</code>. The private <code class="language-plaintext highlighter-rouge">internal</code> module blocks the path: <code class="language-plaintext highlighter-rouge">Router</code> is public within the visibility that path allows, but the path itself is not externally reachable.</p>

<p>Visibility belongs to both the item and its route through the module tree.</p>

<h3 id="visibility-can-name-an-ancestor">Visibility can name an ancestor</h3>

<p>Rust can express scopes relative to the tree: <code class="language-plaintext highlighter-rouge">pub(crate)</code> is visible throughout the crate, <code class="language-plaintext highlighter-rouge">pub(super)</code> within the parent module and its descendants, <code class="language-plaintext highlighter-rouge">pub(in crate::internal)</code> within the named module and its descendants. The path in <code class="language-plaintext highlighter-rouge">pub(in path)</code> must name an ancestor of the current module. A function inside <code class="language-plaintext highlighter-rouge">crate::internal::router</code> cannot declare <code class="language-plaintext highlighter-rouge">pub(in crate::api)</code>, because <code class="language-plaintext highlighter-rouge">api</code> is a sibling branch, not an ancestor.</p>

<p>Java has no equivalent, because its packages do not form a semantic tree. For top-level types and cross-package access, Java mainly offers <code class="language-plaintext highlighter-rouge">public</code> and package-private; class members also have <code class="language-plaintext highlighter-rouge">private</code> and <code class="language-plaintext highlighter-rouge">protected</code>, but none express visibility to a named package subtree.</p>

<p>Before JPMS, a package named <code class="language-plaintext highlighter-rouge">internal</code> was mostly a warning:</p>

<blockquote>
  <p>This is internal. Please do not use it.</p>
</blockquote>

<p>JPMS made that boundary enforceable across modules by withholding exports. But inside the module, Java remains flat.</p>

<h3 id="visibility-keyword-by-keyword">Visibility, keyword by keyword</h3>

<p>External reachability is path-based in Rust and package-based in JPMS. Each Rust modifier grants a scope defined by the module tree; the nearest Java construct is often not a keyword at all, because Java expresses external reachability through the module descriptor rather than a modifier on the declaration.</p>

<table>
  <thead>
    <tr>
      <th>Rust modifier</th>
      <th>Scope it grants</th>
      <th>Nearest Java equivalent</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pub</code> on a public path</td>
      <td>outside the crate</td>
      <td><code class="language-plaintext highlighter-rouge">public</code> in an exported package</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pub</code> behind a private path</td>
      <td>capped by the path</td>
      <td><code class="language-plaintext highlighter-rouge">public</code> in a non-exported package</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pub(crate)</code></td>
      <td>entire crate</td>
      <td><code class="language-plaintext highlighter-rouge">public</code> in a non-exported package</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pub(super)</code></td>
      <td>parent module’s subtree</td>
      <td>none</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pub(in path)</code></td>
      <td>named ancestor’s subtree</td>
      <td>none</td>
    </tr>
    <tr>
      <td>no modifier</td>
      <td>current module and descendants</td>
      <td>package-private, approximately</td>
    </tr>
  </tbody>
</table>

<p>Java approximates <code class="language-plaintext highlighter-rouge">pub(crate)</code> by placing a <code class="language-plaintext highlighter-rouge">public</code> class in a package omitted from exports — not a Java visibility level, but an effect of the module boundary. Rust privacy also differs from Java package privacy: a private Rust item is visible to its defining module and that module’s descendants, while a package-private Java member is visible to all code in the same package.</p>

<h2 id="imports-reveal-the-architecture">Imports reveal the architecture</h2>

<p>The different namespace models also shape imports.</p>

<p>Java:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">java.util.List</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">in.systemhalted.gateway.api.RouteHandler</span><span class="o">;</span>
</code></pre></div></div>

<p>Rust:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// src/internal/router.rs</span>
<span class="k">use</span> <span class="nn">std</span><span class="p">::</span><span class="nn">collections</span><span class="p">::</span><span class="n">HashMap</span><span class="p">;</span>
<span class="k">use</span> <span class="k">crate</span><span class="p">::</span><span class="nn">api</span><span class="p">::</span><span class="n">RouteHandler</span><span class="p">;</span>
</code></pre></div></div>

<p>And from a child module, <code class="language-plaintext highlighter-rouge">use super::Router;</code>.</p>

<p>A Java import aliases a fully qualified name. That name belongs to a global package namespace and says nothing about where the importing class sits relative to the imported one. There is no Java equivalent of <code class="language-plaintext highlighter-rouge">super::</code>, because Java packages have no parent-child relationship.</p>

<p>A Rust <code class="language-plaintext highlighter-rouge">use</code> navigates the module tree:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">crate::</code> starts at the crate root</li>
  <li><code class="language-plaintext highlighter-rouge">self::</code> starts at the current module</li>
  <li><code class="language-plaintext highlighter-rouge">super::</code> starts at the parent module</li>
  <li>an external crate is named directly</li>
</ul>

<p>The module tree is therefore more than an encapsulation mechanism. It is the coordinate system for names throughout the crate.</p>

<h2 id="re-exports-and-transitive-readability">Re-exports and transitive readability</h2>

<p>Rust and JPMS both allow one component’s API to depend on another, but the mechanisms are very different.</p>

<h3 id="jpms-propagates-readability">JPMS propagates readability</h3>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">module</span> <span class="n">in</span><span class="o">.</span><span class="na">systemhalted</span><span class="o">.</span><span class="na">gateway</span><span class="o">.</span><span class="na">api</span> <span class="o">{</span>
    <span class="n">requires</span> <span class="n">transitive</span> <span class="n">in</span><span class="o">.</span><span class="na">systemhalted</span><span class="o">.</span><span class="na">gateway</span><span class="o">.</span><span class="na">types</span><span class="o">;</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Any module that requires <code class="language-plaintext highlighter-rouge">gateway.api</code> also reads <code class="language-plaintext highlighter-rouge">gateway.types</code>, without declaring <code class="language-plaintext highlighter-rouge">gateway.types</code> itself. The dependency remains a separate module: its classes keep their original package and module identity, and consumers can access only the packages that <code class="language-plaintext highlighter-rouge">gateway.types</code> exports. <code class="language-plaintext highlighter-rouge">requires transitive</code> changes the readability graph.</p>

<h3 id="rust-republishes-names">Rust republishes names</h3>

<p>In <code class="language-plaintext highlighter-rouge">src/lib.rs</code>, <code class="language-plaintext highlighter-rouge">pub use gateway_types::RouteConfig;</code> gives consumers a public path through the current crate, <code class="language-plaintext highlighter-rouge">gateway::RouteConfig</code>. Rust can also re-export an item from a private internal module with <code class="language-plaintext highlighter-rouge">pub use crate::internal::router::Router;</code>: the internal module remains private, but <code class="language-plaintext highlighter-rouge">Router</code> becomes available at <code class="language-plaintext highlighter-rouge">gateway::Router</code>.</p>

<p>This works because <code class="language-plaintext highlighter-rouge">Router</code> is public and reachable from <code class="language-plaintext highlighter-rouge">lib.rs</code>. A re-export cannot override privacy; it can only republish an item the re-exporting module can already access.</p>

<p>This gives Rust an important form of indirection: the implementation can live at <code class="language-plaintext highlighter-rouge">crate::internal::router::Router</code> while the public API stays <code class="language-plaintext highlighter-rouge">gateway::Router</code>, and the internal module tree can change without changing the path exposed to consumers.</p>

<p>Java cannot do this directly, because a class’s package is part of its identity.</p>

<h2 id="scaling-up-modules-and-workspaces">Scaling up: modules and workspaces</h2>

<p>Real projects rarely remain a single component. Suppose the gateway is split into two libraries, <code class="language-plaintext highlighter-rouge">gateway-api</code> and <code class="language-plaintext highlighter-rouge">gateway-core</code>.</p>

<h3 id="maven-multi-module-build">Maven multi-module build</h3>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gateway/
├── pom.xml
├── gateway-api/
│   ├── pom.xml
│   └── src/main/java/
│       ├── module-info.java
│       └── in/systemhalted/gateway/api/
└── gateway-core/
    ├── pom.xml
    └── src/main/java/
        ├── module-info.java
        └── in/systemhalted/gateway/core/
</code></pre></div></div>

<p>The root POM aggregates the modules:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nt">&lt;packaging&gt;</span>pom<span class="nt">&lt;/packaging&gt;</span>
<span class="nt">&lt;modules&gt;</span>
    <span class="nt">&lt;module&gt;</span>gateway-api<span class="nt">&lt;/module&gt;</span>
    <span class="nt">&lt;module&gt;</span>gateway-core<span class="nt">&lt;/module&gt;</span>
<span class="nt">&lt;/modules&gt;</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">gateway-core</code> declares the Maven dependency in its POM and the JPMS dependency in its module descriptor.</p>

<h3 id="cargo-workspace">Cargo workspace</h3>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gateway/
├── Cargo.toml
└── crates/
    ├── gateway-api/
    │   ├── Cargo.toml
    │   └── src/
    │       └── lib.rs
    └── gateway-core/
        ├── Cargo.toml
        └── src/
            └── lib.rs
</code></pre></div></div>

<p>The root manifest defines the workspace:</p>

<div class="language-toml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">[</span><span class="n">workspace</span><span class="k">]</span>
<span class="n">members</span> <span class="o">=</span><span class="w"> </span><span class="p">[</span><span class="s">"crates/*"</span><span class="p">]</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">gateway-core</code> declares a path dependency:</p>

<div class="language-toml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">[</span><span class="n">dependencies</span><span class="k">]</span>
<span class="n">gateway-api</span> <span class="o">=</span><span class="w"> </span><span class="p">{</span><span class="w"> </span><span class="n">path</span><span class="w"> </span><span class="p">=</span><span class="w"> </span><span class="s">"../gateway-api"</span><span class="w"> </span><span class="p">}</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">crates/</code> directory is only convention; the <code class="language-plaintext highlighter-rouge">members</code> declaration defines the workspace. Each member remains a normal Cargo package with its own manifest, source tree, and crate root. A workspace adds organization above packages without weakening the boundaries between their crates.</p>

<h3 id="dependency-management">Dependency management</h3>

<p>The Maven and Cargo mappings are close but not identical. A Cargo workspace shares one resolved dependency graph through <code class="language-plaintext highlighter-rouge">Cargo.lock</code>. Centralized dependency declarations belong in <code class="language-plaintext highlighter-rouge">[workspace.dependencies]</code>, and member packages inherit them with <code class="language-plaintext highlighter-rouge">serde = { workspace = true }</code> — closer to Maven’s <code class="language-plaintext highlighter-rouge">dependencyManagement</code> than the lock file itself.</p>

<p>At the build level, both construct a dependency graph and build components in order: <code class="language-plaintext highlighter-rouge">cargo build</code> from the workspace root resembles a Maven reactor build like <code class="language-plaintext highlighter-rouge">mvn package</code> from the parent project.</p>

<p>The architectural consequence is the same: a crate boundary inside a workspace is still a real boundary. <code class="language-plaintext highlighter-rouge">gateway-core</code> sees only what <code class="language-plaintext highlighter-rouge">gateway-api</code> exposes publicly, just as one JPMS module sees only the packages another exports. Splitting a project into crates or JPMS modules is therefore not directory organization; it changes the enforceable architecture.</p>

<h2 id="split-packages-and-legacy-constraints">Split packages and legacy constraints</h2>

<p>JPMS arrived after two decades of classpath-based Java. That history created migration mechanisms and compatibility layers:</p>

<ul>
  <li>automatic modules</li>
  <li>the unnamed module</li>
  <li>classpath fallback</li>
  <li>command-line overrides</li>
  <li>split-package failures</li>
</ul>

<p>A split package occurs when two or more named modules define types in the same Java package. JPMS rejects that arrangement: a given package must belong to a single module. Rust rules out the analogous structure by construction — a Rust module belongs to one crate’s module tree and is introduced by declarations within that crate. No module spans two crates. There is no pre-crate Rust ecosystem to accommodate.</p>

<p>The escape hatch survives, too. Drop a JAR onto the legacy <code class="language-plaintext highlighter-rouge">--class-path</code> instead of the module path and its packages fall back into the unnamed module, outside JPMS entirely — strong encapsulation holds only as long as everyone stays on the module path. Rust has no such fallback: nothing sits outside the crate system, so its boundaries always hold.</p>

<p>This is not evidence that Rust’s designers were smarter; they had a different starting point. But the consequence matters: crate boundaries apply uniformly across the ecosystem, and tools can assume the model is real.</p>

<h2 id="the-runtime-model">The runtime model</h2>

<p>JPMS also governs deep runtime reflection. Java frameworks often inspect constructors, fields, and methods reflectively; whether that access is permitted depends on ordinary access checks and whether the containing package is open. A module can open one package to a specific framework:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">module</span> <span class="n">in</span><span class="o">.</span><span class="na">systemhalted</span><span class="o">.</span><span class="na">gateway</span> <span class="o">{</span>
    <span class="n">opens</span> <span class="n">in</span><span class="o">.</span><span class="na">systemhalted</span><span class="o">.</span><span class="na">gateway</span><span class="o">.</span><span class="na">config</span>
        <span class="n">to</span> <span class="n">com</span><span class="o">.</span><span class="na">fasterxml</span><span class="o">.</span><span class="na">jackson</span><span class="o">.</span><span class="na">databind</span><span class="o">;</span>
<span class="o">}</span>
</code></pre></div></div>

<p>The command line can also modify the boundary with <code class="language-plaintext highlighter-rouge">--add-opens</code>.</p>

<p>Rust has no general runtime reflection facility comparable to Java reflection. Its major metaprogramming mechanisms — procedural macros and derive macros — operate during compilation, expanding into ordinary Rust code that remains subject to the language’s visibility rules. Rust therefore needs no equivalent of JPMS <code class="language-plaintext highlighter-rouge">opens</code>; the problem does not arise, because the runtime model is different.</p>

<h2 id="the-mapping">The mapping</h2>

<table>
  <thead>
    <tr>
      <th>Rust</th>
      <th>Java</th>
      <th>Caveat</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>crate</td>
      <td>JPMS module</td>
      <td>Architectural analogy focused on encapsulation and dependency structure</td>
    </tr>
    <tr>
      <td>Cargo package</td>
      <td>Maven artifact</td>
      <td>Manifest and publishing unit; may contain multiple crates</td>
    </tr>
    <tr>
      <td>workspace</td>
      <td>Maven multi-module build</td>
      <td>Workspace manifest resembles an aggregator parent POM</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">[workspace.dependencies]</code></td>
      <td><code class="language-plaintext highlighter-rouge">dependencyManagement</code></td>
      <td>Centralized dependency declarations</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Cargo.toml</code> dependencies</td>
      <td>POM dependencies plus JPMS <code class="language-plaintext highlighter-rouge">requires</code></td>
      <td>Cargo combines resolution and compiler availability; Java separates them</td>
    </tr>
    <tr>
      <td>Rust module</td>
      <td>Java package</td>
      <td>Rust modules form a tree; Java packages are flat</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">use</code></td>
      <td><code class="language-plaintext highlighter-rouge">import</code></td>
      <td>Rust navigates a module tree; Java aliases package-qualified names</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pub use</code></td>
      <td>no direct equivalent</td>
      <td>Re-exports create new public paths</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">requires transitive</code></td>
      <td>no direct Rust equivalent</td>
      <td>Propagates module readability</td>
    </tr>
    <tr>
      <td>none</td>
      <td><code class="language-plaintext highlighter-rouge">opens</code>, <code class="language-plaintext highlighter-rouge">--add-opens</code></td>
      <td>Rust has no comparable runtime-reflection model</td>
    </tr>
  </tbody>
</table>

<h2 id="what-each-language-should-envy">What each language should envy</h2>

<p>Return to the three questions. Rust answers all of them inside the language and its build tool, the same way for every crate. Java answers them across pieces assembled over twenty years. That difference is the source of what each side can envy.</p>

<p>Java developers should envy Rust’s uniformity. Every Rust crate, from the standard library to a small third-party library, participates in the same crate and module model. There is no parallel classpath world, no automatic-module transition state, no split-package compatibility problem, and no reflective framework asking for runtime access to private implementation details.</p>

<p>Rust developers should envy the explicit JPMS boundary document. A <code class="language-plaintext highlighter-rouge">module-info.java</code> file states, in one compact artifact:</p>

<ul>
  <li>which modules are readable</li>
  <li>which packages are exported</li>
  <li>which packages are opened</li>
  <li>which services are used or provided</li>
</ul>

<p>Cargo can expose the resolved dependency graph through <code class="language-plaintext highlighter-rouge">cargo metadata</code>, and Rust tooling can resolve public re-exports, but a crate’s external namespace is assembled through source declarations rather than summarized in one descriptor. For architectural governance at module and package granularity, JPMS provides a cleaner artifact.</p>

<p>Neither system describes the complete public API: an exported Java package still has to be inspected for its public classes and methods, and a Rust crate still has to be analyzed for its public items and re-exports. But JPMS makes the high-level boundary unusually explicit.</p>

<p>Rust could make the crate the language’s central architectural unit, and Cargo built its package and dependency model around it: one place answers compilation and encapsulation, one place answers distribution. JPMS had no such freedom. It had to coexist with packages, JARs, the classpath, reflection-heavy frameworks, and two decades of existing code; its answers to the three questions were already spread apart before it arrived.</p>

<p>That historical constraint explains most of the irregularity in JPMS. It also explains most of the uniformity in Cargo.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Computer Science" /><category term="jpms" /><category term="cargo" /><category term="modules" /><category term="encapsulation" /><category term="type-systems" /><category term="java" /><category term="rust" /><category term="programming-languages" /><summary type="html"><![CDATA[The same project built twice, in Java (JPMS + Maven) and Rust (Cargo) — how each answers compilation, distribution, and encapsulation, why a crate maps to a JPMS module and a Rust module to a Java package, and where the analogy breaks down.]]></summary></entry><entry><title type="html">Adopting Agent Loops in Order</title><link href="https://systemhalted.in/2026/07/10/adopting-agent-loops-in-order/" rel="alternate" type="text/html" title="Adopting Agent Loops in Order" /><published>2026-07-10T00:00:00+00:00</published><updated>2026-07-10T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/10/adopting-agent-loops-in-order</id><content type="html" xml:base="https://systemhalted.in/2026/07/10/adopting-agent-loops-in-order/"><![CDATA[<p>In an <a href="/2026/07/03/what-sits-underneath-the-agent-loops-post/">earlier post</a> I wrote about the four kinds of agent loops that Anthropic’s Claude Code team described, and about where the check on the work lives in each one. That post looked at the loops one at a time. There is also an order to them. Each loop leaves behind an artifact that the next loop depends on, so the sequence in which a team adopts them matters as much as the choice of which ones to use.</p>

<p>The turn-based loop comes first because its artifact is the foundation. Working turn by turn with an agent forces a team to answer a basic question: how do we know a change is good? Writing the answer down as a runnable check produces the skill file. Nothing about this requires autonomy. It only requires noticing what a person does before accepting a result, and recording it.</p>

<p>Second is the goal-based loop, which consumes that check. An exit criterion is only useful if there is a way to evaluate it, and the evaluation is the check the turn-based stage wrote down. Defining the criterion is work of its own. A team has to say what done means in language precise enough for an evaluator to apply, and that precision usually does not exist yet. Producing it is the real output of this stage.</p>

<p>After the criterion is in place, a schedule or an event trigger follows, and this is the rung where teams most often stall. A schedule is the easiest of the four artifacts to create, so it tends to appear early and stay. A prompt that runs every morning feels like automation, and nobody revisits it. The better path is to treat the schedule as provisional from the day it is created, and to replace it with an event trigger when the source system offers one. A calendar entry is a guess about when the world changes. An event is a report that it did.</p>

<p>A proactive routine can only come last, because it consumes everything: the check, the criterion, the trigger, and the operational guardrails around all three. At this stage the question stops being technical. A routine that touches production systems needs an owner, a budget, and a way to be turned off, and those are organisational decisions. A platform team can supply the machinery. Only the owning team can supply the ownership.</p>

<p>Skipping a rung defers work rather than removing it. A proactive routine adopted before the exit criterion exists will need that criterion defined during an incident instead of during design. A goal-based loop adopted before the check is written down will evaluate against an evaluator’s guess. The artifacts get produced either way. The order decides whether they are produced deliberately or under pressure.</p>

<p>So the most capable loop is not the right starting point. The right starting point is the artifact underneath the rung a team is already on, finished and written down before the next step up.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Software Engineering" /><category term="AI" /><category term="ai" /><category term="agents" /><category term="claude-code" /><category term="engineering-management" /><summary type="html"><![CDATA[The four agent loops depend on each other's artifacts. Notes on the order in which a team should adopt them.]]></summary></entry><entry><title type="html">What Sits Underneath the Agent Loops Post</title><link href="https://systemhalted.in/2026/07/03/what-sits-underneath-the-agent-loops-post/" rel="alternate" type="text/html" title="What Sits Underneath the Agent Loops Post" /><published>2026-07-03T00:00:00+00:00</published><updated>2026-07-03T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/03/what-sits-underneath-the-agent-loops-post</id><content type="html" xml:base="https://systemhalted.in/2026/07/03/what-sits-underneath-the-agent-loops-post/"><![CDATA[<p>Anthropic’s Claude Code team put out a <a href="https://claude.com/blog/getting-started-with-loops">short piece</a> last week describing four kinds of agent loops: turn-based, goal-based, time-based, and proactive. Each type comes with a trigger, a stop condition, and typical use cases. The taxonomy describes surface. It says how the agent runs, how it stops, and what starts it. Underneath it sits a different question: where does the check on the work actually live? Each loop type puts that check in a different place, and the place that holds it is the place a team has to make durable before the next loop up is safe to build.</p>

<p>In a turn-based loop, the check lives in your judgement. The agent gathers context, does the work, checks itself, and hands back a result. You decide whether to accept it, redirect, or discard. Your judgement does not scale past a certain volume of work. What helps is writing the check down as something the agent can run before it comes back to you. Start the dev server, exercise the changed control, take screenshots before and after, run the affected tests. A skill file that encodes these steps moves the check from one person’s head to a file the whole team can read and improve. Every loop above this one assumes that file exists.</p>

<p>A goal-based loop moves the check into the exit criterion. You state what done looks like, and an evaluator model tests the condition each time the agent tries to stop. A measurable criterion, such as a Lighthouse score or a latency threshold on a specific endpoint, stops the loop on something you can defend after the fact. A vague criterion stops the loop early, because the agent convinces itself it is done, or lets it run long, because there is no way to be sure. Most teams do not have exit criteria for their own work written in language a person could act on, let alone an agent. The first attempt at a goal-based loop usually exposes that gap.</p>

<p>With a time-based loop, the trigger carries the check. The same prompt runs every N minutes against the current state of the world: summarising a channel, sweeping a queue, checking a pull request for review comments. What usually breaks here is the interval, not the prompt. A short interval against a slow-moving source wastes tokens, and a long interval against a fast-moving source misses changes that need a response. When the source system can emit an event, such as a webhook or a queue depth alert, an event trigger ties each run to a change that actually happened. A time-based loop works better as a stage on the way to an event-driven one than as a destination.</p>

<p>A proactive loop spreads the check across the whole system around the agent. A routine watches a stream of bug reports, alerts, or tickets, and runs a goal-based loop for each item until someone turns it off. This is a queue consumer whose judgement comes from a model, so it needs the same properties as any production consumer: idempotency, rate limits, spend caps, observability, a shutoff, and an owner. The Anthropic post covers token budgeting and routing routine subtasks to smaller models, which matter for cost. The harder question is ownership. A routine without a clear owner will eventually do the wrong thing with nobody responsible for noticing.</p>

<p>Three of these places build on each other directly. The check written down at the turn-based level is what the goal-based loop evaluates, and the criterion defined at the goal-based level is what the proactive routine applies to each item on the stream. The trigger sits beside this chain rather than inside it: a schedule or an event source decides when the runs happen, not whether their results can be trusted. A proactive routine built on unverified goals does not automate anything useful. It repeats whatever was already broken, at a cost that grows with how often it runs.</p>

<p>So the loops are the visible layer, and the durable artifacts sit underneath them: the skill file, the exit criterion, the trigger, and the observability around the routine. A team can locate its missing artifact by looking at what it still does by hand. If UI changes are verified manually at the end of every session, the skill file has not been written. Case-by-case judgement on whether a fix is done usually means there is no measurable exit criterion. A script that someone remembers to start every morning is a schedule that has not been written down, and after that an event trigger. Hand triage of a steady stream of reports is a routine that has not been built yet. These artifacts outlive the specific prompt, the specific model, and the specific team. Writing them down is the work the loops post points to.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Software Engineering" /><category term="AI" /><category term="ai" /><category term="agents" /><category term="claude-code" /><category term="engineering-management" /><summary type="html"><![CDATA[Anthropic's Claude Code team described four kinds of agent loops. Notes on where the check on the work lives in each, and on the artifacts a team has to make durable underneath them.]]></summary></entry><entry><title type="html">Property-Based Testing: Testing Rules Instead of Examples</title><link href="https://systemhalted.in/2026/07/02/property-based-testing/" rel="alternate" type="text/html" title="Property-Based Testing: Testing Rules Instead of Examples" /><published>2026-07-02T00:00:00+00:00</published><updated>2026-07-02T00:00:00+00:00</updated><id>https://systemhalted.in/2026/07/02/property-based-testing</id><content type="html" xml:base="https://systemhalted.in/2026/07/02/property-based-testing/"><![CDATA[<p>In an <a href="/2026/06/21/types-check-shape-tests-check-behaviour/">earlier post</a> I wrote about a small text editor I am building in Rust, and a <code class="language-plaintext highlighter-rouge">save</code> function that passed its test while being wrong. The test built a document, changed it, saved it, read the file back, and checked that the contents matched. It was green. The implementation dropped the <code class="language-plaintext highlighter-rouge">Result</code> from the disk write, so a failed save would still report success and clear the unsaved-changes flag. This happened because the test only checked the happy path.</p>

<p>That post was about the boundary between what a type system can prove and what only a test can. There is a separate limitation worth looking at, one that has little to do with that particular bug. An example test only runs the input I give it. My save test proves something about the string <code class="language-plaintext highlighter-rouge">abcdef</code> written to a temporary file, and nothing about the other inputs the function will see. I chose the input, so the input agrees with me. Writing more example tests does not remove this, because I choose those inputs too.</p>

<h2 id="from-examples-to-a-property">From examples to a property</h2>

<p>Take <code class="language-plaintext highlighter-rouge">insert</code> and <code class="language-plaintext highlighter-rouge">delete</code> on the document model. The usual way to test them is with an example.</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nd">#[test]</span>
<span class="k">fn</span> <span class="nf">insert_then_delete_restores_buffer</span><span class="p">()</span> <span class="p">{</span>
    <span class="k">let</span> <span class="k">mut</span> <span class="n">doc</span> <span class="o">=</span> <span class="nn">Document</span><span class="p">::</span><span class="nf">from_str</span><span class="p">(</span><span class="s">"hello"</span><span class="p">);</span>
    <span class="n">doc</span><span class="nf">.insert</span><span class="p">(</span><span class="mi">5</span><span class="p">,</span> <span class="s">" world"</span><span class="p">);</span>        <span class="c1">// "hello world"</span>
    <span class="n">doc</span><span class="nf">.delete</span><span class="p">(</span><span class="mi">5</span><span class="p">,</span> <span class="mi">11</span><span class="p">);</span>              <span class="c1">// back to "hello"</span>
    <span class="nd">assert_eq!</span><span class="p">(</span><span class="n">doc</span><span class="nf">.text</span><span class="p">(),</span> <span class="s">"hello"</span><span class="p">);</span>
<span class="p">}</span>
</code></pre></div></div>

<p>This test passes, and it is not a bad test. But look at what it actually asserts: that inserting <code class="language-plaintext highlighter-rouge">" world"</code> at index 5 of <code class="language-plaintext highlighter-rouge">"hello"</code>, and then deleting that range, gives back <code class="language-plaintext highlighter-rouge">"hello"</code>. That is one point in a large space of possible inputs. The rule I care about is not about <code class="language-plaintext highlighter-rouge">"hello"</code> at all but that for any document, inserting a string and then deleting exactly that range returns the original document. I wrote a test about one case of the rule but I can do better through property-based testing.</p>

<p>Property-based testing lets me state the rule and let the framework choose the inputs. Instead of picking the input, I describe the range of valid inputs, state what must be true, and the framework generates many cases and tries to find one that fails. In Rust the common tool for this is the <code class="language-plaintext highlighter-rouge">proptest</code> crate<sup id="fnref:proptest"><a href="#fn:proptest" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>.</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">use</span> <span class="nn">proptest</span><span class="p">::</span><span class="nn">prelude</span><span class="p">::</span><span class="o">*</span><span class="p">;</span>

<span class="nd">proptest!</span> <span class="p">{</span>
    <span class="nd">#[test]</span>
    <span class="k">fn</span> <span class="nf">insert_then_delete_is_identity</span><span class="p">(</span><span class="n">base</span> <span class="k">in</span> <span class="s">".*"</span><span class="p">,</span> <span class="n">ins</span> <span class="k">in</span> <span class="s">".*"</span><span class="p">,</span> <span class="n">at</span> <span class="k">in</span> <span class="mi">0usize</span><span class="o">..=</span><span class="nn">usize</span><span class="p">::</span><span class="n">MAX</span><span class="p">)</span> <span class="p">{</span>
        <span class="k">let</span> <span class="k">mut</span> <span class="n">doc</span> <span class="o">=</span> <span class="nn">Document</span><span class="p">::</span><span class="nf">from_str</span><span class="p">(</span><span class="o">&amp;</span><span class="n">base</span><span class="p">);</span>
        <span class="k">let</span> <span class="n">at</span> <span class="o">=</span> <span class="n">at</span> <span class="o">%</span> <span class="p">(</span><span class="n">doc</span><span class="nf">.len</span><span class="p">()</span> <span class="o">+</span> <span class="mi">1</span><span class="p">);</span>          <span class="c1">// an offset into the buffer</span>
        <span class="k">let</span> <span class="n">before</span> <span class="o">=</span> <span class="n">doc</span><span class="nf">.text</span><span class="p">()</span><span class="nf">.to_string</span><span class="p">();</span>

        <span class="n">doc</span><span class="nf">.insert</span><span class="p">(</span><span class="n">at</span><span class="p">,</span> <span class="o">&amp;</span><span class="n">ins</span><span class="p">);</span>
        <span class="n">doc</span><span class="nf">.delete</span><span class="p">(</span><span class="n">at</span><span class="p">,</span> <span class="n">at</span> <span class="o">+</span> <span class="n">ins</span><span class="nf">.len</span><span class="p">());</span>

        <span class="nd">prop_assert_eq!</span><span class="p">(</span><span class="n">doc</span><span class="nf">.text</span><span class="p">(),</span> <span class="n">before</span><span class="p">);</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">proptest</code> runs this body a few hundred times with different generated values, and the test passes only if the property holds for all of them. I am no longer asserting a fact about <code class="language-plaintext highlighter-rouge">"hello"</code>. I am asserting a fact about <code class="language-plaintext highlighter-rouge">insert</code> and <code class="language-plaintext highlighter-rouge">delete</code>.</p>

<h2 id="reading-the-generator-line">Reading the generator line</h2>

<p>Most of the work in that test is in the signature, so it is worth going through it slowly.</p>

<p>Each <code class="language-plaintext highlighter-rouge">name in strategy</code> clause defines one generated argument. A strategy is the <code class="language-plaintext highlighter-rouge">proptest</code> term for something that knows two things: how to produce a random value, and how to shrink that value toward something smaller when a test fails. On each run, <code class="language-plaintext highlighter-rouge">proptest</code> draws a value from each strategy and calls the body with them. The <code class="language-plaintext highlighter-rouge">in</code> reads a little like the <code class="language-plaintext highlighter-rouge">in</code> of a <code class="language-plaintext highlighter-rouge">for</code> loop, but it is not walking a fixed list. It is drawing from a described set of inputs.</p>

<p><code class="language-plaintext highlighter-rouge">base in ".*"</code> and <code class="language-plaintext highlighter-rouge">ins in ".*"</code> generate strings. The literal <code class="language-plaintext highlighter-rouge">".*"</code> is read as a regular expression, and the strategy produces strings that match it. In that expression <code class="language-plaintext highlighter-rouge">.</code> means any character and <code class="language-plaintext highlighter-rouge">*</code> means zero or more of them, so <code class="language-plaintext highlighter-rouge">".*"</code> matches almost any string: the empty string, <code class="language-plaintext highlighter-rouge">"hello"</code>, a single emoji, a two-byte character such as <code class="language-plaintext highlighter-rouge">"é"</code>, whitespace, or control characters. This wide range is deliberate. <code class="language-plaintext highlighter-rouge">".*"</code> will produce characters that take more than one byte, and those are the inputs I do not think to type by hand, which turns out to matter here. If I wanted a narrower set of inputs I would use a narrower expression, such as <code class="language-plaintext highlighter-rouge">"[a-z]{1,10}"</code> for one to ten lowercase letters, or <code class="language-plaintext highlighter-rouge">"[0-9]+"</code> for a run of digits. Here I want the widest set I can get.</p>

<p><code class="language-plaintext highlighter-rouge">at in 0usize..=usize::MAX</code> generates an integer. The strategy here is an ordinary Rust range. <code class="language-plaintext highlighter-rouge">proptest</code> provides a <code class="language-plaintext highlighter-rouge">Strategy</code> implementation for the standard range types, so a range can be handed to it directly as a generator that produces values inside the range. Reading the bounds from left to right: <code class="language-plaintext highlighter-rouge">0usize</code> is the low end, zero, written as a <code class="language-plaintext highlighter-rouge">usize</code>, which is Rust’s pointer-sized unsigned integer and the type used for indexing. The <code class="language-plaintext highlighter-rouge">..=</code> operator makes the range inclusive, so the upper value is part of the range. <code class="language-plaintext highlighter-rouge">usize::MAX</code> is the largest value a <code class="language-plaintext highlighter-rouge">usize</code> can hold. The <code class="language-plaintext highlighter-rouge">usize</code> suffix on <code class="language-plaintext highlighter-rouge">0usize</code> is not cosmetic. Both ends of a range must have the same type, and without it the compiler cannot tell whether I meant a <code class="language-plaintext highlighter-rouge">u32</code>, an <code class="language-plaintext highlighter-rouge">i64</code>, or something else. So <code class="language-plaintext highlighter-rouge">at</code> is any index from zero to the maximum.</p>

<p>This raises a fair question. The generated integer can be as large as <code class="language-plaintext highlighter-rouge">usize::MAX</code>, about 1.8 billion billion on a 64-bit machine, while a short document has only a handful of positions. A five-byte string like <code class="language-plaintext highlighter-rouge">"hello"</code> has just six offsets, zero through five. So almost every raw value the generator produces lands far past the end of the buffer rather than inside it. Why draw from the whole <code class="language-plaintext highlighter-rouge">usize</code> range at all? The reason is that the three strategies are evaluated independently. The generator for <code class="language-plaintext highlighter-rouge">at</code> does not know how long the <code class="language-plaintext highlighter-rouge">base</code> string it is paired with will be, so it cannot produce an index that is valid for that particular document. The first line of the body deals with this.</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">let</span> <span class="n">at</span> <span class="o">=</span> <span class="n">at</span> <span class="o">%</span> <span class="p">(</span><span class="n">doc</span><span class="nf">.len</span><span class="p">()</span> <span class="o">+</span> <span class="mi">1</span><span class="p">);</span>   <span class="c1">// an offset into the buffer</span>
</code></pre></div></div>

<p>The modulo maps any generated integer into the range <code class="language-plaintext highlighter-rouge">0..=doc.len()</code>, where <code class="language-plaintext highlighter-rouge">doc.len()</code> is the length of the document in bytes. The range is inclusive at the top because you can insert at the end of the buffer as well as inside it. Generating a wide value and then mapping it into range is a common pattern with <code class="language-plaintext highlighter-rouge">proptest</code>, because it keeps every generated value usable instead of throwing away the ones that fall out of range. There is a more precise tool for producing an index into a generated collection, the <code class="language-plaintext highlighter-rouge">prop_flat_map</code> combinator, which lets one strategy depend on the value another produced. For a single index the modulo is simpler.</p>

<p>So the signature reads as follows: for any strings <code class="language-plaintext highlighter-rouge">base</code> and <code class="language-plaintext highlighter-rouge">ins</code>, and any index <code class="language-plaintext highlighter-rouge">at</code> mapped into range, the body must hold. <code class="language-plaintext highlighter-rouge">proptest</code> runs the body many times with different values, and the test passes only if the property holds for all of them.</p>

<h2 id="when-a-property-fails">When a property fails</h2>

<p>Run this property as written and it does not reach the assertion. It panics, and not on <code class="language-plaintext highlighter-rouge">"hello"</code>. It panics on an input I would not have typed into a test by hand.</p>

<p>A raw generated input is not much use as a bug report. If the framework told me the test failed on a four thousand character random string, that would be a puzzle to work through, not a defect I can read. What makes property-based testing practical is shrinking. When <code class="language-plaintext highlighter-rouge">proptest</code> finds a failing input, it does not report that input directly. It looks for the smallest and simplest input that still fails, using shorter strings, smaller indices, and values closer to zero, and reports that instead. The failure shrinks down to something like this.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>minimal failing input:
    base = "é"
    ins  = ""
    at   = 1

panic: byte index 1 is not a char boundary
</code></pre></div></div>

<p>That is a report I can act on, and the surprise is where the panic comes from. It is not a bug in <code class="language-plaintext highlighter-rouge">insert</code> or <code class="language-plaintext highlighter-rouge">delete</code>. It is my own line, <code class="language-plaintext highlighter-rouge">at % (doc.len() + 1)</code>. In Rust a string index is a byte offset, and <code class="language-plaintext highlighter-rouge">len()</code> returns a length in bytes, so the modulo gives me some offset between zero and the byte length. But not every byte offset is a place you are allowed to edit. An edit must land on a UTF-8 character boundary, and <code class="language-plaintext highlighter-rouge">insert</code> panics when it does not. The character <code class="language-plaintext highlighter-rouge">é</code> is two bytes, so the only valid positions are <code class="language-plaintext highlighter-rouge">0</code> and <code class="language-plaintext highlighter-rouge">2</code>; the offset <code class="language-plaintext highlighter-rouge">1</code> falls inside the character. The generator produced the smallest string and index that break an assumption I had written into the test without noticing it: that any offset from zero to the length is a valid place to insert.</p>

<p>The fix is to generate only offsets that fall on character boundaries. Rust gives me the boundaries through <code class="language-plaintext highlighter-rouge">char_indices</code>, and I add the end of the string as the last position.</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">use</span> <span class="nn">proptest</span><span class="p">::</span><span class="nn">prelude</span><span class="p">::</span><span class="o">*</span><span class="p">;</span>

<span class="k">fn</span> <span class="nf">char_boundary_offsets</span><span class="p">(</span><span class="n">s</span><span class="p">:</span> <span class="o">&amp;</span><span class="nb">str</span><span class="p">)</span> <span class="k">-&gt;</span> <span class="nb">Vec</span><span class="o">&lt;</span><span class="nb">usize</span><span class="o">&gt;</span> <span class="p">{</span>
    <span class="n">s</span><span class="nf">.char_indices</span><span class="p">()</span>
        <span class="nf">.map</span><span class="p">(|(</span><span class="n">i</span><span class="p">,</span> <span class="n">_</span><span class="p">)|</span> <span class="n">i</span><span class="p">)</span>
        <span class="nf">.chain</span><span class="p">(</span><span class="nn">std</span><span class="p">::</span><span class="nn">iter</span><span class="p">::</span><span class="nf">once</span><span class="p">(</span><span class="n">s</span><span class="nf">.len</span><span class="p">()))</span>
        <span class="nf">.collect</span><span class="p">()</span>
<span class="p">}</span>

<span class="nd">proptest!</span> <span class="p">{</span>
    <span class="nd">#[test]</span>
    <span class="k">fn</span> <span class="nf">insert_then_delete_is_identity</span><span class="p">(</span><span class="n">base</span> <span class="k">in</span> <span class="s">".*"</span><span class="p">,</span> <span class="n">ins</span> <span class="k">in</span> <span class="s">".*"</span><span class="p">,</span> <span class="n">raw_at</span> <span class="k">in</span> <span class="mi">0usize</span><span class="o">..=</span><span class="nn">usize</span><span class="p">::</span><span class="n">MAX</span><span class="p">)</span> <span class="p">{</span>
        <span class="k">let</span> <span class="n">offsets</span> <span class="o">=</span> <span class="nf">char_boundary_offsets</span><span class="p">(</span><span class="o">&amp;</span><span class="n">base</span><span class="p">);</span>
        <span class="k">let</span> <span class="n">at</span> <span class="o">=</span> <span class="n">offsets</span><span class="p">[</span><span class="n">raw_at</span> <span class="o">%</span> <span class="n">offsets</span><span class="nf">.len</span><span class="p">()];</span>   <span class="c1">// a valid edit position</span>

        <span class="k">let</span> <span class="k">mut</span> <span class="n">doc</span> <span class="o">=</span> <span class="nn">Document</span><span class="p">::</span><span class="nf">from_str</span><span class="p">(</span><span class="o">&amp;</span><span class="n">base</span><span class="p">);</span>
        <span class="k">let</span> <span class="n">before</span> <span class="o">=</span> <span class="n">doc</span><span class="nf">.text</span><span class="p">()</span><span class="nf">.to_string</span><span class="p">();</span>

        <span class="n">doc</span><span class="nf">.insert</span><span class="p">(</span><span class="n">at</span><span class="p">,</span> <span class="o">&amp;</span><span class="n">ins</span><span class="p">);</span>
        <span class="n">doc</span><span class="nf">.delete</span><span class="p">(</span><span class="n">at</span><span class="p">,</span> <span class="n">at</span> <span class="o">+</span> <span class="n">ins</span><span class="nf">.len</span><span class="p">());</span>

        <span class="nd">prop_assert_eq!</span><span class="p">(</span><span class="n">doc</span><span class="nf">.text</span><span class="p">(),</span> <span class="n">before</span><span class="p">);</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>There is a more general point here, beyond the Unicode detail. A property test does not only run more inputs than an example. It makes me say what a valid input is. Writing the example test, I never had to define the set of legal insertion points, because I only used position 5 of <code class="language-plaintext highlighter-rouge">"hello"</code>, which happens to be legal. The property could not be written until I stated, in code, that a legal position is a character boundary. So the generator did not simply find a case I had forgotten. It exposed an assumption I had never written down, which is what happens when a rule has to hold for every input rather than for the one I picked.</p>

<p>The type system does not close this gap. <code class="language-plaintext highlighter-rouge">String</code> guarantees the buffer is valid UTF-8, but an index into it is a plain <code class="language-plaintext highlighter-rouge">usize</code>, and the type says nothing about whether that <code class="language-plaintext highlighter-rouge">usize</code> lands on a boundary. That check happens at runtime, and until I wrote the property it was happening nowhere in my tests.</p>

<h2 id="where-property-based-testing-helps-and-where-it-does-not">Where property-based testing helps, and where it does not</h2>

<p>It would be easy to read this and decide that property tests should replace example tests. They should not, any more than tests replace types. Each answers a different question, and property testing has a cost. A good property is harder to find than a good example, and a weak property is worse than no test at all.</p>

<p>The cost is in finding the rule. “For input <code class="language-plaintext highlighter-rouge">"hello"</code>, expect <code class="language-plaintext highlighter-rouge">"hello world"</code>” takes a second to write. “For all documents and all edits, this relationship holds” takes real thought, and if the rule is slightly wrong the test is either flaky or empty. The common mistake is a vacuous property, one that cannot fail.</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nd">prop_assert!</span><span class="p">(</span><span class="n">doc</span><span class="nf">.len</span><span class="p">()</span> <span class="o">&gt;=</span> <span class="mi">0</span><span class="p">);</span>       <span class="c1">// len() is usize; always true</span>
</code></pre></div></div>

<p>That runs a few hundred times, passes every time, and checks nothing. A property that is merely true is not the same as a property that constrains the code. The useful properties describe a relationship tight enough that a wrong implementation cannot satisfy it: round-trips such as <code class="language-plaintext highlighter-rouge">decode(encode(x)) == x</code>, idempotence such as <code class="language-plaintext highlighter-rouge">f(f(x)) == f(x)</code>, order-independence where applying two edits in either order gives the same result, and conservation of some quantity such as length or character count. If I cannot name a relationship like that, an example test is the honest choice, and a property adds nothing.</p>

<p>Here is the rule I settled on. A property test earns its place when there is a rule that must hold across many inputs, not a single value I am checking. <code class="language-plaintext highlighter-rouge">save</code> then <code class="language-plaintext highlighter-rouge">load</code> should return the same buffer, and that is a rule. “The About dialog shows version 2.1” is a single value, and writing it as a property gains nothing.</p>

<h2 id="types-examples-and-properties">Types, examples and properties</h2>

<p>I now think of three tools rather than two, each covering what the previous one cannot.</p>

<p>Types rule out illegal shapes before the program runs. A <code class="language-plaintext highlighter-rouge">Result</code> that must be used, an <code class="language-plaintext highlighter-rouge">Option</code> that cannot be read without handling the empty case, a closed enum that forces every branch to be handled. The compiler settles these for every input at once, and this is the cheapest of the three.</p>

<p>Example tests check specific behaviour that the types allow but do not pin down. That inserting <code class="language-plaintext highlighter-rouge">" world"</code> at index 5 of <code class="language-plaintext highlighter-rouge">"hello"</code> gives <code class="language-plaintext highlighter-rouge">"hello world"</code> and not <code class="language-plaintext highlighter-rouge">"worldhello"</code> is a fact about values, and the type checker has no opinion on it. An example fixes one such fact.</p>

<p>Property tests cover the space in between, the behaviour that must hold across all the inputs the type still allows and that no single example can cover. The UTF-8 boundary case sits there. It is legal according to the type, missed by the examples, and wrong in general. The useful thing is to be clear about how behaviour will be evaluated before writing the code, which is the <a href="/2025/12/09/tdd-revisted/">test-first</a> instinct. A property is one clear way to state that evaluation, because it forces me to say what must always be true rather than what happened to be true the one time I ran the code.</p>

<p>The three fit together in order. Push what you can into types, so the compiler proves it for every input. Use examples to record the specific behaviour you have decided on. Use properties for the rules that must hold everywhere and that you would never cover by hand.</p>

<h2 id="summary">Summary</h2>

<p>An example test checks the inputs I thought of. A property-based test states a rule and lets the framework generate inputs that try to break it. That is the difference that matters. On my own I tend to write the tests my code already passes, because I imagine the same cases when I write the code and when I test it. The generator does not share that imagination, and shrinking makes what it finds small enough to read and fix. Writing the property also forces me to say what a valid input is, which is often where the real gap turns out to be. The reason to reach for property testing is not that the code is otherwise untestable. It is that it exercises the inputs I would not have chosen, and in a text editor those are often the inputs a real user will produce.</p>

<h2 id="references-and-notes">References and Notes</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:proptest">
      <p><code class="language-plaintext highlighter-rouge">proptest</code> is a property-testing framework for Rust with shrinking driven by its generators. Documentation and the book: <a href="https://proptest-rs.github.io/proptest/">https://proptest-rs.github.io/proptest/</a>. Rust’s other well-known option, <code class="language-plaintext highlighter-rouge">quickcheck</code> (<a href="https://github.com/BurntSushi/quickcheck">https://github.com/BurntSushi/quickcheck</a>), follows the original Haskell QuickCheck more closely: it mirrors that library’s <code class="language-plaintext highlighter-rouge">Arbitrary</code> typeclass as an <code class="language-plaintext highlighter-rouge">Arbitrary</code> trait, so generation and shrinking both live on the type. <code class="language-plaintext highlighter-rouge">proptest</code> instead takes its generator-driven shrinking from Python’s Hypothesis (<a href="https://hypothesis.readthedocs.io/">https://hypothesis.readthedocs.io/</a>), where the strategy that built a value also knows how to shrink it. Both Rust crates descend from Claessen and Hughes, “QuickCheck: A Lightweight Tool for Random Testing of Haskell Programs” (ICFP 2000): <a href="https://www.cs.tufts.edu/~nr/cs257/archive/john-hughes/quick.pdf">https://www.cs.tufts.edu/~nr/cs257/archive/john-hughes/quick.pdf</a>, the paper that introduced testing stated properties over generated inputs. <a href="#fnref:proptest" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Software Engineering" /><category term="Computer Science" /><category term="rust" /><category term="testing" /><category term="property-based-testing" /><category term="tdd" /><category term="software" /><summary type="html"><![CDATA[An example test checks the inputs you happened to choose. A property-based test states a rule and lets the framework generate inputs that try to break it. Notes from continuing a small text editor in Rust.]]></summary></entry><entry><title type="html">Git Worktree and the Myth of a Single Working Directory</title><link href="https://systemhalted.in/2026/06/25/git-worktree/" rel="alternate" type="text/html" title="Git Worktree and the Myth of a Single Working Directory" /><published>2026-06-25T00:00:00+00:00</published><updated>2026-06-25T00:00:00+00:00</updated><id>https://systemhalted.in/2026/06/25/git-worktree</id><content type="html" xml:base="https://systemhalted.in/2026/06/25/git-worktree/"><![CDATA[<p>While working on a feature recently, I needed to look at something on another branch. Normally this would involve one of the workflows most Git users are familiar with: commit the current changes, stash them, or temporarily abandon the current state and switch branches. None of those options felt appealing. The work was incomplete and I was not ready to commit it. Stashing would have worked, but it felt like introducing additional state that I would need to remember to restore later.</p>

<p>Looking for alternatives, I came across a Git feature that I had heard about before but never used seriously: worktree. At first glance, worktree looks like a convenience feature. It allows multiple working directories to be attached to the same repository so that different branches can be checked out simultaneously. That is useful on its own, but what caught my attention was the implication behind it.</p>

<p>Most Git users, myself included, tend to think of a repository as a working directory that happens to contain a <code class="language-plaintext highlighter-rouge">.git</code> directory. Git does not view things this way. From Git’s perspective, the repository is the object database, and the working directory is one view into that repository. Worktree exists because Git was never fundamentally limited to a single working directory. Most of us simply use it that way.</p>

<h2 id="the-mental-model-most-of-us-carry">The Mental Model Most of Us Carry</h2>

<p>Consider a typical repository:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>my-project/
├── src/
├── docs/
├── pom.xml
└── .git/
</code></pre></div></div>

<p>Most developers naturally view this as a single unit: a repository, a working directory, and a currently checked-out branch. That mental model is not wrong, but it is incomplete. The branch is not stored in the working directory. The commit history is not stored in the working directory. The object database is not stored in the working directory. Those things live inside <code class="language-plaintext highlighter-rouge">.git</code>, and the files visible in the working directory are a projection of a particular commit from the repository.</p>

<p>Once viewed from that perspective, an interesting question emerges: why should a repository be limited to a single projection? Git’s answer is that it isn’t.</p>

<h2 id="creating-a-worktree">Creating a Worktree</h2>

<p>Suppose the current repository is checked out on a feature branch:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git switch feature/customer-notifications
</code></pre></div></div>

<p>A second working directory can be created using:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git worktree add ../customer-notifications-main main
</code></pre></div></div>

<p>Git creates a new directory alongside the existing one:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>projects/
├── customer-notifications/
└── customer-notifications-main/
</code></pre></div></div>

<p>The first directory remains on the feature branch, and the second is checked out on <code class="language-plaintext highlighter-rouge">main</code>. Both can be opened in separate terminals, editors, or IDE windows, and changes in one working tree do not affect the other. From a developer’s perspective, it feels almost like having two clones, except that Git is not creating another repository.</p>

<h2 id="looking-at-what-git-actually-creates">Looking at What Git Actually Creates</h2>

<p>After creating a worktree, the repository structure changes slightly. Inside <code class="language-plaintext highlighter-rouge">.git</code>, a new directory appears:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>.git/
├── objects/
├── refs/
├── logs/
└── worktrees/
</code></pre></div></div>

<p>Listing the contents of <code class="language-plaintext highlighter-rouge">.git/worktrees/</code> reveals a subdirectory for each additional worktree, containing files such as <code class="language-plaintext highlighter-rouge">HEAD</code>, <code class="language-plaintext highlighter-rouge">gitdir</code>, <code class="language-plaintext highlighter-rouge">commondir</code>, and <code class="language-plaintext highlighter-rouge">index</code>. The exact contents may vary across Git versions, but the important observation is that Git is maintaining metadata for an additional working tree while continuing to share the underlying repository. This is why creating a worktree is extremely fast. Git is not duplicating the commit graph, objects, tags, or references. It is creating another working directory and associating it with the existing repository.</p>

<h2 id="shared-and-separate-state">Shared and Separate State</h2>

<p>The easiest way to understand worktrees is to identify what is shared and what is independent. The object database, branch references, tags, hooks, and configuration are all shared across worktrees. Each worktree has its own working directory contents, its own index, and its own HEAD pointing somewhere into the shared <code class="language-plaintext highlighter-rouge">refs/heads/</code>. This separation is what allows two branches to be active simultaneously without two repositories, and it has a few practical consequences worth noting.</p>

<p>A <code class="language-plaintext highlighter-rouge">git fetch</code> in any worktree updates the shared refs, so the new commits are immediately visible from every worktree attached to the repository. Hooks installed in <code class="language-plaintext highlighter-rouge">.git/hooks/</code> run regardless of which worktree triggered them, which catches some people out when they expect per-worktree hook behavior. And because branch refs are shared, a branch checked out in one worktree cannot be checked out in another, which is the next thing worth looking at.</p>

<h2 id="why-git-refuses-certain-operations">Why Git Refuses Certain Operations</h2>

<p>Suppose <code class="language-plaintext highlighter-rouge">feature/customer-notifications</code> is already checked out in one worktree. Attempting to check it out in another produces an error:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ git worktree add ../another-copy feature/customer-notifications
fatal: 'feature/customer-notifications' is already checked out at '/path/to/customer-notifications'
</code></pre></div></div>

<p>This can initially seem restrictive, but the restriction makes sense given the shared-ref design. A branch is a movable reference, and if two working directories could manipulate the same branch independently, Git would have no way to determine the intended state of that reference. The restriction prevents ambiguity and protects branch state from concurrent updates.</p>

<h2 id="worktree-versus-stash">Worktree Versus Stash</h2>

<p>Worktree and stash solve different problems, even though both come up when someone needs to switch context briefly. A stash temporarily preserves uncommitted changes so another task can be performed in the same working directory, while a worktree creates an entirely separate workspace. If I need to quickly pull <code class="language-plaintext highlighter-rouge">main</code>, perform a rebase, and continue working, a stash is reasonable. If I expect to spend hours investigating another branch while keeping the current work untouched, a worktree is the better choice. The distinction is subtle but important: a stash preserves state, while a worktree preserves context.</p>

<h2 id="worktree-versus-another-clone">Worktree Versus Another Clone</h2>

<p>Historically, some developers solved this problem by maintaining multiple clones of the same repository. That approach works, but every clone maintains its own object database, references, and repository metadata, which means fetches must be performed in each clone separately and disk usage grows linearly with the number of copies. Worktrees share those resources. For smaller repositories the difference is negligible, but for larger repositories containing years of history it becomes noticeable. More importantly, worktrees communicate intent. They represent multiple views into the same repository rather than multiple copies of the repository itself.</p>

<h2 id="the-bare-repository-approach">The Bare Repository Approach</h2>

<p>One workflow worth mentioning treats worktrees as the primary interface rather than an occasional convenience. The repository is cloned bare, and every branch the developer wants to work on becomes its own worktree:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone --bare git@github.com:example/project.git project.git
cd project.git
git worktree add ../project-main main
git worktree add ../project-feature feature/customer-notifications
</code></pre></div></div>

<p>There is no “main” working directory in this model. Every working directory is a worktree, and the bare repository at the root contains only the shared state. Some developers organize their worktrees inside a <code class="language-plaintext highlighter-rouge">.worktrees/</code> subdirectory of the project to keep things tidy. Whether this layout is worth adopting depends on how often parallel branches are needed, but it makes Git’s underlying model unusually visible.</p>

<h2 id="managing-worktrees">Managing Worktrees</h2>

<p>Git provides a few commands for managing worktrees. <code class="language-plaintext highlighter-rouge">git worktree list</code> shows all active worktrees and the branches they point to:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/home/palak/projects/my-project          a1b2c3d [feature/customer-notifications]
/home/palak/projects/my-project-main     e4f5g6h [main]
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">git worktree remove &lt;path&gt;</code> removes a worktree. If a worktree directory is removed manually outside of Git, the stale metadata can be cleaned up with <code class="language-plaintext highlighter-rouge">git worktree prune</code>. Most day-to-day usage rarely requires anything beyond these commands.</p>

<h2 id="final-thoughts">Final Thoughts</h2>

<p>Before learning about worktrees, I implicitly assumed that a Git repository and a working directory were inseparable concepts. Git itself makes no such assumption. A repository is an object database containing commits, trees, blobs, references, and metadata, while a working directory is one representation of repository state at a particular point in time. Viewed from that perspective, worktrees feel less like an advanced feature and more like a natural consequence of Git’s architecture.</p>

<p>The feature is useful for avoiding branch switching, preserving context, and keeping parallel streams of work isolated. But the more interesting lesson is the one it reveals about Git itself. Many of the limitations we assume are built into our tools are actually limitations of the mental models we carry around. Git worktree is a small reminder that those two things are not always the same.</p>]]></content><author><name>Palak Mathur</name></author><category term="Technology" /><category term="Software Engineering" /><category term="git" /><category term="version-control" /><category term="software-engineering" /><summary type="html"><![CDATA[While working on a feature recently, I needed to look at something on another branch. Normally this would involve one of the workflows most Git users are familiar with: commit the current changes, stash them, or temporarily abandon the current state and switch branches. None of those options felt appealing. The work was incomplete and I was not ready to commit it. Stashing would have worked, but it felt like introducing additional state that I would need to remember to restore later.]]></summary></entry><entry><title type="html">Types Check Shape, Tests Check Behaviour</title><link href="https://systemhalted.in/2026/06/21/types-check-shape-tests-check-behaviour/" rel="alternate" type="text/html" title="Types Check Shape, Tests Check Behaviour" /><published>2026-06-21T00:00:00+00:00</published><updated>2026-06-25T00:00:00+00:00</updated><id>https://systemhalted.in/2026/06/21/types-check-shape-tests-check-behaviour</id><content type="html" xml:base="https://systemhalted.in/2026/06/21/types-check-shape-tests-check-behaviour/"><![CDATA[<p>I am writing a small text editor in Rust to learn the language. The editor has a document model, you can open a file, save a file, etc. While building the <code class="language-plaintext highlighter-rouge">save</code> function I hit a bug that made me reconsider what tests are for and where the compiler takes over.</p>

<p>These are some of the notes.</p>

<h2 id="a-green-test-is-not-a-correct-program">A green test is not a correct program</h2>

<p>The function performed following tasks - write the buffer to a path, then mark the document as having no unsaved changes.</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">pub</span> <span class="k">fn</span> <span class="nf">save</span><span class="p">(</span><span class="o">&amp;</span><span class="k">mut</span> <span class="k">self</span><span class="p">,</span> <span class="n">path</span><span class="p">:</span> <span class="o">&amp;</span><span class="n">Path</span><span class="p">)</span> <span class="k">-&gt;</span> <span class="nn">io</span><span class="p">::</span><span class="nb">Result</span><span class="o">&lt;</span><span class="p">()</span><span class="o">&gt;</span> <span class="p">{</span>
    <span class="nn">std</span><span class="p">::</span><span class="nn">fs</span><span class="p">::</span><span class="nf">write</span><span class="p">(</span><span class="n">path</span><span class="p">,</span> <span class="k">self</span><span class="nf">.text</span><span class="p">());</span>   <span class="c1">// the Result here is silently dropped</span>
    <span class="k">self</span><span class="py">.modified</span> <span class="o">=</span> <span class="k">false</span><span class="p">;</span>
    <span class="nf">Ok</span><span class="p">(())</span>
<span class="p">}</span>
</code></pre></div></div>

<p>and I had also written the following test:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nd">#[test]</span>
<span class="k">fn</span> <span class="nf">save_writes_contents_and_clears_modified</span><span class="p">()</span> <span class="p">{</span>
    <span class="k">let</span> <span class="n">path</span> <span class="o">=</span> <span class="nn">std</span><span class="p">::</span><span class="nn">env</span><span class="p">::</span><span class="nf">temp_dir</span><span class="p">()</span><span class="nf">.join</span><span class="p">(</span><span class="s">"save_test.txt"</span><span class="p">);</span>
    <span class="k">let</span> <span class="k">mut</span> <span class="n">doc</span> <span class="o">=</span> <span class="nn">Document</span><span class="p">::</span><span class="nf">from_str</span><span class="p">(</span><span class="s">"abc"</span><span class="p">);</span>
    <span class="n">doc</span><span class="nf">.insert</span><span class="p">(</span><span class="mi">3</span><span class="p">,</span> <span class="s">"def"</span><span class="p">);</span> <span class="c1">// buffer is now "abcdef", with unsaved changes</span>

    <span class="n">doc</span><span class="nf">.save</span><span class="p">(</span><span class="o">&amp;</span><span class="n">path</span><span class="p">)</span><span class="nf">.unwrap</span><span class="p">();</span>

    <span class="nd">assert_eq!</span><span class="p">(</span><span class="nn">std</span><span class="p">::</span><span class="nn">fs</span><span class="p">::</span><span class="nf">read_to_string</span><span class="p">(</span><span class="o">&amp;</span><span class="n">path</span><span class="p">)</span><span class="nf">.unwrap</span><span class="p">(),</span> <span class="s">"abcdef"</span><span class="p">);</span>
    <span class="nd">assert!</span><span class="p">(</span><span class="o">!</span><span class="n">doc</span><span class="nf">.is_modified</span><span class="p">());</span> <span class="c1">// a successful save clears the dirty flag</span>

    <span class="k">let</span> <span class="n">_</span> <span class="o">=</span> <span class="nn">std</span><span class="p">::</span><span class="nn">fs</span><span class="p">::</span><span class="nf">remove_file</span><span class="p">(</span><span class="o">&amp;</span><span class="n">path</span><span class="p">);</span>
<span class="p">}</span>
</code></pre></div></div>

<p>It built a document, made a change, saved it to a temporary file, read the file back, checked that the contents matched, and confirmed the document no longer reported unsaved changes. The test passed, which would normally be the end of it, except that the implementation had a bug on the first line.</p>

<p><code class="language-plaintext highlighter-rouge">std::fs::write</code> returns a <code class="language-plaintext highlighter-rouge">Result</code>, because writing to disk can fail in any of the ordinary ways: the disk fills up, the directory does not exist, the process lacks permission. The function ignored that return value, so a failed write would still fall through to <code class="language-plaintext highlighter-rouge">self.modified = false</code> and then <code class="language-plaintext highlighter-rouge">Ok(())</code>. The editor would report the file as saved, clear the unsaved-changes marker, and lose the user’s work, which is the one bug a text editor cannot ship. The test stayed green the whole time because it only ran the happy path, and a passing happy-path test says nothing about the behaviour on the failure paths it never visits.</p>

<h2 id="the-compiler-reviews-shape-not-intent">The compiler reviews shape, not intent</h2>

<p>I missed the bug, but the compiler flagged it:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>warning: unused `Result` that must be used
</code></pre></div></div>

<p>Rust marks <code class="language-plaintext highlighter-rouge">Result</code> as <code class="language-plaintext highlighter-rouge">#[must_use]</code><sup id="fnref:mustuse"><a href="#fn:mustuse" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>, so the lint fires when a fallible call’s return is dropped. The warning is real help, but it is still only a warning. I could have written this instead and quieted it:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">let</span> <span class="n">_</span> <span class="o">=</span> <span class="nn">std</span><span class="p">::</span><span class="nn">fs</span><span class="p">::</span><span class="nf">write</span><span class="p">(</span><span class="n">path</span><span class="p">,</span> <span class="k">self</span><span class="nf">.text</span><span class="p">());</span>   <span class="c1">// explicitly discard it</span>
<span class="k">self</span><span class="py">.modified</span> <span class="o">=</span> <span class="k">false</span><span class="p">;</span>
<span class="nf">Ok</span><span class="p">(())</span>
</code></pre></div></div>

<p>That compiles cleanly. The type checker is satisfied: the signature returns a <code class="language-plaintext highlighter-rouge">Result</code>, a <code class="language-plaintext highlighter-rouge">Result</code> is returned, the borrow rules<sup id="fnref:borrow"><a href="#fn:borrow" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> hold, the shape of the program is right. What the compiler has no way of checking is what I meant by it – that a failed write must not clear the modified flag, that it must not be reported as success.</p>

<p>This is where the work of compiler stops. It checks that the types line up, that fallibility is visible in signatures, that a <code class="language-plaintext highlighter-rouge">Result</code> is not accidentally ignored, that the borrows are valid; it does not check that the program does the right thing with any of those things once it has them.</p>

<h2 id="a-regression-test-only-counts-once-you-have-seen-it-fail">A regression test only counts once you have seen it fail</h2>

<p>The fix is one character, the <code class="language-plaintext highlighter-rouge">?</code> operator, which turns the dropped result into a propagated one:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nn">std</span><span class="p">::</span><span class="nn">fs</span><span class="p">::</span><span class="nf">write</span><span class="p">(</span><span class="n">path</span><span class="p">,</span> <span class="k">self</span><span class="nf">.text</span><span class="p">())</span><span class="o">?</span><span class="p">;</span>
<span class="k">self</span><span class="py">.modified</span> <span class="o">=</span> <span class="k">false</span><span class="p">;</span>
<span class="nf">Ok</span><span class="p">(())</span>
</code></pre></div></div>

<p>If the write fails, the function exits before clearing the modified flag. I had no test that would have caught the bug. Adding <code class="language-plaintext highlighter-rouge">?</code> without adding a test would leave me trusting the code for no reason at all, so I wrote the test that should have existed from the start.</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nd">#[test]</span>
<span class="k">fn</span> <span class="nf">failed_save_surfaces_error_and_keeps_modified</span><span class="p">()</span> <span class="p">{</span>
    <span class="k">let</span> <span class="k">mut</span> <span class="n">doc</span> <span class="o">=</span> <span class="nn">Document</span><span class="p">::</span><span class="nf">from_str</span><span class="p">(</span><span class="s">"important data"</span><span class="p">);</span>
    <span class="n">doc</span><span class="nf">.insert</span><span class="p">(</span><span class="mi">0</span><span class="p">,</span> <span class="s">"!"</span><span class="p">);</span> <span class="c1">// the document now has unsaved changes</span>

    <span class="c1">// a directory that does not exist, so the OS write is forced to fail</span>
    <span class="k">let</span> <span class="n">bad_path</span> <span class="o">=</span> <span class="nn">std</span><span class="p">::</span><span class="nn">env</span><span class="p">::</span><span class="nf">temp_dir</span><span class="p">()</span><span class="nf">.join</span><span class="p">(</span><span class="s">"no_such_dir"</span><span class="p">)</span><span class="nf">.join</span><span class="p">(</span><span class="s">"file.txt"</span><span class="p">);</span>
    <span class="k">let</span> <span class="n">result</span> <span class="o">=</span> <span class="n">doc</span><span class="nf">.save</span><span class="p">(</span><span class="o">&amp;</span><span class="n">bad_path</span><span class="p">);</span>

    <span class="nd">assert!</span><span class="p">(</span><span class="n">result</span><span class="nf">.is_err</span><span class="p">());</span>     <span class="c1">// the failure must reach the caller</span>
    <span class="nd">assert!</span><span class="p">(</span><span class="n">doc</span><span class="nf">.is_modified</span><span class="p">());</span>   <span class="c1">// and the buffer must still be dirty</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Then I put the bug back, ran the suite, watched this test go red, restored the fix, and watched it go green. Putting the bug back to confirm the test fails for the right reason sounds like ceremony but is not. A regression test you have never seen fail is one you trust by faith, and the first section already showed how little a passing test is worth on its own.</p>

<h2 id="types-and-tests-answer-different-questions">Types and tests answer different questions</h2>

<p>A type system is good at making certain kinds of lies impossible: a value that may be absent cannot pretend to be present, a fallible operation cannot pretend to be infallible, a closed set of cases cannot pretend one branch does not exist. That is powerful, but it is structural. Rust can make the failure visible, warn me when I accidentally ignore it, and force the code to admit that saving may fail, but it cannot encode the editor’s rule that if saving fails, the document must remain dirty. That rule lives at the level of behaviour, not shape.</p>

<p>You can push more behaviour into types than that suggests. The typestate pattern<sup id="fnref:typestate"><a href="#fn:typestate" class="footnote" rel="footnote" role="doc-noteref">3</a></sup> encodes a rule into a type, so that an illegal operation does not compile instead of failing a test. The <code class="language-plaintext highlighter-rouge">save</code> bug can be narrowed this way by making the clearing of the modified flag depend on a value that only a successful write can produce:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">struct</span> <span class="n">Saved</span><span class="p">;</span>   <span class="c1">// nothing outside this module can construct one</span>

<span class="k">fn</span> <span class="nf">write</span><span class="p">(</span><span class="o">&amp;</span><span class="k">self</span><span class="p">,</span> <span class="n">path</span><span class="p">:</span> <span class="o">&amp;</span><span class="n">Path</span><span class="p">)</span> <span class="k">-&gt;</span> <span class="nn">io</span><span class="p">::</span><span class="nb">Result</span><span class="o">&lt;</span><span class="n">Saved</span><span class="o">&gt;</span> <span class="p">{</span> <span class="cm">/* ... */</span> <span class="p">}</span>
<span class="k">fn</span> <span class="nf">mark_clean</span><span class="p">(</span><span class="o">&amp;</span><span class="k">mut</span> <span class="k">self</span><span class="p">,</span> <span class="n">_proof</span><span class="p">:</span> <span class="n">Saved</span><span class="p">)</span> <span class="p">{</span> <span class="k">self</span><span class="py">.modified</span> <span class="o">=</span> <span class="k">false</span><span class="p">;</span> <span class="p">}</span>
</code></pre></div></div>

<p>Now <code class="language-plaintext highlighter-rouge">mark_clean</code> cannot be called without a <code class="language-plaintext highlighter-rouge">Saved</code>, and the only thing that hands one back is a <code class="language-plaintext highlighter-rouge">write</code> that returned <code class="language-plaintext highlighter-rouge">Ok</code>, so the exact bug from the first section is harder to write by accident.<sup id="fnref:receipt"><a href="#fn:receipt" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> The boundary between what a type can prove and what only a test can prove is not fixed; it moves with how much you choose to encode.</p>

<p>What stays out of reach, at least in Rust, is value-level correctness, which is the relationship between specific input and output values. That needs dependent types, which Rust does not have. The type checker has no opinion on whether inserting <code class="language-plaintext highlighter-rouge">" world"</code> at index 5 of <code class="language-plaintext highlighter-rouge">"hello"</code> gives <code class="language-plaintext highlighter-rouge">"hello world"</code> or <code class="language-plaintext highlighter-rouge">"worldhello"</code>; both are valid <code class="language-plaintext highlighter-rouge">String</code>s, and which one you meant is a question only a test can answer.</p>

<p>The instruction that falls out of this is short: do not test what the type system has already made impossible, and do test the behaviour the type system is silent about. A small example came up in the next step. A document needs to remember the file it came from, but a new, untitled buffer has not come from anywhere, so the honest type for that field is <code class="language-plaintext highlighter-rouge">Option&lt;PathBuf&gt;</code>, and Rust will not let you read the path without handling the case where there is none. The “I forgot to check for the missing file” bug is not caught by a test here; the program that contains it does not compile, and writing a test for it would only re-prove what the compiler has already proven.</p>

<h2 id="test-everything-that-can-fail-is-too-blunt">“Test everything that can fail” is too blunt</h2>

<p>I used to carry a simple rule: every operation that can fail gets a failure test. It made sense in the Java world I grew up in, and after the save bug I wrote one for <code class="language-plaintext highlighter-rouge">open</code> too – a test asserting that opening a missing file returns an error. Then I deleted it.</p>

<p>The save failure test is worth keeping, but not because saving can fail. It is worth keeping because <code class="language-plaintext highlighter-rouge">save</code> changes state on the way to succeeding: it clears the modified flag. The assertion in that test that actually matters is not <code class="language-plaintext highlighter-rouge">assert!(result.is_err())</code> but <code class="language-plaintext highlighter-rouge">assert!(doc.is_modified())</code>, which guards the state that a failed save could otherwise leave wrong. <code class="language-plaintext highlighter-rouge">open</code> is different; it builds a value and returns it, changing nothing and leaving nothing wrong when it fails. The only thing a failure test there could check is whether I propagated the error instead of swallowing it, which is thin, with no state behind it to protect.</p>

<p>So the rule sharpened into something narrower: a failure test earns its place in proportion to the state a failure could leave wrong, and where failure only propagates cleanly there is little for it to guard. That is not an argument for testing less out of laziness, but for putting tests where things can actually break instead of spreading them evenly out of habit.</p>

<h2 id="the-point">The point</h2>

<p>This is not an argument against tests or against types, but for knowing which of the two you are leaning on at any given moment. Lean only on tests and you will keep writing assertions to re-establish guarantees a good type system would give you for free, at compile time, for every input. Lean only on types and you will ship code that is well-formed and quietly wrong: green in every structural sense, still losing files. The healthier division is to let the type system carry what it can – null-safety, exhaustiveness, fallibility made visible, and as much of your state machine as you are willing to encode – and to spend your tests on the behaviour that is left over.</p>

<p>That line moves. Typestate carries more than people expect, and dependent types would carry more again, but wherever you draw it for a given program the rule is the same: do not ask a type to prove what only a test can, or a test to re-prove what the type already guarantees. How far the line can move also depends on the language. Rust leans on two guarantees that Java’s type system holds you to less strictly. The first is that absence has a single shape: Rust has no <code class="language-plaintext highlighter-rouge">null</code>, so a value that might not be there is an <code class="language-plaintext highlighter-rouge">Option</code> and the compiler will not let me touch it without handling the empty case, whereas Java’s <code class="language-plaintext highlighter-rouge">Optional</code><sup id="fnref:java"><a href="#fn:java" class="footnote" rel="footnote" role="doc-noteref">5</a></sup> sits beside <code class="language-plaintext highlighter-rouge">null</code> rather than replacing it and leaves <code class="language-plaintext highlighter-rouge">.get()</code> available to learn my mistake at runtime. The second is move semantics: Java can make a proof-of-save <em>exist</em> through a private constructor and a factory, but it cannot make it <em>spent</em>, so nothing would stop me clearing the flag with the same token twice; Rust takes the value away when it is used, and that is the part Java has no equivalent for. In both cases the work does not vanish – it moves from the compiler to my tests and my discipline. The reason to reach for Rust here is not that the editor is otherwise impossible, which it plainly is not, but that a more expressive type system settles more of the program’s correctness before a single test runs.</p>

<h2 id="references-and-notes">References and Notes</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:mustuse">
      <p>Rust’s <code class="language-plaintext highlighter-rouge">#[must_use]</code> attribute and the lint behind the warning: <a href="https://doc.rust-lang.org/reference/attributes/diagnostics.html#the-must_use-attribute">https://doc.rust-lang.org/reference/attributes/diagnostics.html#the-must_use-attribute</a> <a href="#fnref:mustuse" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:borrow">
      <p>References and borrowing in Rust, including the rules the borrow checker enforces: <a href="https://doc.rust-lang.org/book/ch04-02-references-and-borrowing.html">https://doc.rust-lang.org/book/ch04-02-references-and-borrowing.html</a> <a href="#fnref:borrow" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:typestate">
      <p>Cliff L. Biffle, “The Typestate Pattern in Rust,” a thorough walk through encoding state into types: <a href="https://cliffle.com/blog/rust-typestate/">https://cliffle.com/blog/rust-typestate/</a> <a href="#fnref:typestate" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:receipt">
      <p>This sketch is illustrative, not airtight. The <code class="language-plaintext highlighter-rouge">Saved</code> token is not bound to a particular document or path, so within the module that defines these methods you could still write to one file and clear a different document’s flag. A rigorous version would tie the proof to the instance; the point here is only that the rule can be pushed into the type at all. <a href="#fnref:receipt" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:java">
      <p>Kotlin, on the same JVM, enforces null-safety in its type system, distinguishing <code class="language-plaintext highlighter-rouge">String</code> from <code class="language-plaintext highlighter-rouge">String?</code> and checking it at compile time, which closes the first gap. Java’s sealed types with a pattern-matching <code class="language-plaintext highlighter-rouge">switch</code> give compile-time exhaustiveness over a closed set of cases – the same “every case is handled” guarantee Rust’s enums provide – and it can even encode method-presence typestate, so it carries more behaviour than the body alone might suggest. What stays particular to Rust is linearity: a value that is consumed when it is used. The broader point, that the type system’s power sets how far the line can move, is what holds. <a href="#fnref:java" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Software Engineering" /><category term="Computer Science" /><category term="rust" /><category term="testing" /><category term="type-systems" /><category term="tdd" /><category term="software" /><summary type="html"><![CDATA[Notes from building a small text editor in Rust, and what a green-but-wrong save() function taught me about the line between what a type system can prove and what only a test can.]]></summary></entry><entry><title type="html">Java Generics: The Cost of Type Erasure</title><link href="https://systemhalted.in/2026/05/31/java-generics-type-erasure/" rel="alternate" type="text/html" title="Java Generics: The Cost of Type Erasure" /><published>2026-05-31T00:00:00+00:00</published><updated>2026-05-31T00:00:00+00:00</updated><id>https://systemhalted.in/2026/05/31/java-generics-type-erasure</id><content type="html" xml:base="https://systemhalted.in/2026/05/31/java-generics-type-erasure/"><![CDATA[<p>This post is not an introduction to Java generics. I am assuming you are already familiar with the topic. The core idea I want to capture in this post is that Java checks generic types at compile time but erases much of that information at runtime, and that this changes how code behaves. This runtime behavior is known as type erasure, which means <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code> and <code class="language-plaintext highlighter-rouge">List&lt;Integer&gt;</code> both become <code class="language-plaintext highlighter-rouge">List</code> at runtime.</p>

<p>This behavior causes some interesting bugs and awkward APIs. We will explore some of them in this post.</p>

<h2 id="1-liststringclass-does-not-exist">1. <code class="language-plaintext highlighter-rouge">List&lt;String&gt;.class</code> does not exist</h2>

<p>We are all familiar with <code class="language-plaintext highlighter-rouge">List.class</code>, <code class="language-plaintext highlighter-rouge">String.class</code>, <code class="language-plaintext highlighter-rouge">Integer.class</code> but <code class="language-plaintext highlighter-rouge">List&lt;String&gt;.class</code> is an illegal construct in Java. At runtime, Java does not have a separate class object for <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code> versus <code class="language-plaintext highlighter-rouge">List&lt;Integer&gt;</code>.</p>

<p>That is why APIs that often accept this <code class="language-plaintext highlighter-rouge">Class&lt;T&gt; type</code> break down for generic types.</p>

<p>For example, this API looks clean:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&lt;</span><span class="no">T</span><span class="o">&gt;</span> <span class="no">T</span> <span class="nf">read</span><span class="o">(</span><span class="nc">String</span> <span class="n">json</span><span class="o">,</span> <span class="nc">Class</span><span class="o">&lt;</span><span class="no">T</span><span class="o">&gt;</span> <span class="n">type</span><span class="o">)</span>
</code></pre></div></div>

<p>It works well for a normal object:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">User</span> <span class="n">user</span> <span class="o">=</span> <span class="n">read</span><span class="o">(</span><span class="n">json</span><span class="o">,</span> <span class="nc">User</span><span class="o">.</span><span class="na">class</span><span class="o">);</span>
</code></pre></div></div>

<p>However, the following will be impossible:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;</span> <span class="n">users</span> <span class="o">=</span> <span class="n">read</span><span class="o">(</span><span class="n">json</span><span class="o">,</span> <span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;.</span><span class="na">class</span><span class="o">);</span>
</code></pre></div></div>
<p>There is no <code class="language-plaintext highlighter-rouge">List&lt;User&gt;.class</code> to pass. You may be tempted to make it work by trying:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;</span> <span class="n">users</span> <span class="o">=</span> <span class="n">read</span><span class="o">(</span><span class="n">json</span><span class="o">,</span> <span class="nc">List</span><span class="o">.</span><span class="na">class</span><span class="o">);</span>
</code></pre></div></div>
<p>But now the runtime only knows that the target type is <code class="language-plaintext highlighter-rouge">List</code>. It does not know that the list is supposed to contain <code class="language-plaintext highlighter-rouge">User</code> objects.</p>

<p>This is where bugs begin. A JSON library, for example, may deserialize the JSON array into a <code class="language-plaintext highlighter-rouge">List&lt;LinkedHashMap&gt;</code> instead of a <code class="language-plaintext highlighter-rouge">List&lt;User&gt;</code>. The code may compile, but fail later when you try to use one of the elements as a <code class="language-plaintext highlighter-rouge">User</code>.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;</span> <span class="n">users</span> <span class="o">=</span> <span class="n">read</span><span class="o">(</span><span class="n">json</span><span class="o">,</span> <span class="nc">List</span><span class="o">.</span><span class="na">class</span><span class="o">);</span> 

<span class="nc">User</span> <span class="n">user</span> <span class="o">=</span> <span class="n">users</span><span class="o">.</span><span class="na">get</span><span class="o">(</span><span class="mi">0</span><span class="o">);</span> <span class="c1">// may fail at runtime</span>
</code></pre></div></div>

<p>The problem is not that the list may be empty. That would be a normal collection issue. The type erasure problem is that even if the list contains elements, those elements may not be of the type the source code appears to promise.</p>

<p>To solve this, libraries invented alternate ways to carry generic type information into runtime APIs.</p>

<p>Jackson uses <code class="language-plaintext highlighter-rouge">TypeReference&lt;T&gt;</code>:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;</span> <span class="n">users</span> <span class="o">=</span> <span class="n">objectMapper</span><span class="o">.</span><span class="na">readValue</span><span class="o">(</span><span class="n">json</span><span class="o">,</span> <span class="k">new</span> <span class="nc">TypeReference</span><span class="o">&lt;</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;&gt;()</span> <span class="o">{});</span>
</code></pre></div></div>

<p>Gson uses <code class="language-plaintext highlighter-rouge">TypeToken&lt;T&gt;</code>:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;</span> <span class="n">users</span> <span class="o">=</span>
    <span class="n">gson</span><span class="o">.</span><span class="na">fromJson</span><span class="o">(</span><span class="n">json</span><span class="o">,</span> <span class="k">new</span> <span class="nc">TypeToken</span><span class="o">&lt;</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;&gt;()</span> <span class="o">{}.</span><span class="na">getType</span><span class="o">());</span>
</code></pre></div></div>

<p>Spring uses <code class="language-plaintext highlighter-rouge">ParameterizedTypeReference&lt;T&gt;</code>:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">ResponseEntity</span><span class="o">&lt;</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;&gt;</span> <span class="n">response</span> <span class="o">=</span>
    <span class="n">restTemplate</span><span class="o">.</span><span class="na">exchange</span><span class="o">(</span>
        <span class="n">url</span><span class="o">,</span>
        <span class="nc">HttpMethod</span><span class="o">.</span><span class="na">GET</span><span class="o">,</span>
        <span class="kc">null</span><span class="o">,</span>
        <span class="k">new</span> <span class="nc">ParameterizedTypeReference</span><span class="o">&lt;</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;&gt;()</span> <span class="o">{}</span>
    <span class="o">);</span>
</code></pre></div></div>

<p>These APIs look awkward because they are working around the same missing runtime concept: a class-like object that represents a fully parameterized generic type. If Java supported class literals for parameterized types such as <code class="language-plaintext highlighter-rouge">List&lt;User&gt;.class</code>, many of these APIs could have been simpler.</p>

<h2 id="2-instanceof-liststring-does-not-work">2. <code class="language-plaintext highlighter-rouge">instanceof List&lt;String&gt;</code> does not work</h2>

<p>Another place where type erasure shows up is runtime type checking. In Java, we commonly use <code class="language-plaintext highlighter-rouge">instanceof</code> to check the type of an object.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">if</span> <span class="o">(</span><span class="n">obj</span> <span class="k">instanceof</span> <span class="nc">String</span><span class="o">)</span> <span class="o">{</span>
<span class="o">...</span>
<span class="o">}</span>
</code></pre></div></div>

<p>But Java won’t let you write</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">if</span> <span class="o">(</span><span class="n">obj</span> <span class="k">instanceof</span> <span class="nc">List</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">&gt;)</span> <span class="o">{</span>
 <span class="o">...</span>
<span class="o">}</span>
</code></pre></div></div>

<p>The reason is that <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code> is not fully available at runtime. After type erasure, the runtime can check whether the <code class="language-plaintext highlighter-rouge">obj</code> is a <code class="language-plaintext highlighter-rouge">List</code>, but it cannot directly check whether it is specifically a <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code>.</p>

<p>So, Java only allows this:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">if</span> <span class="o">(</span><span class="n">obj</span> <span class="k">instanceof</span> <span class="nc">List</span><span class="o">&lt;?&gt;)</span> <span class="o">{</span>
<span class="o">...</span>
<span class="o">}</span>
</code></pre></div></div>
<p>This tells us that <code class="language-plaintext highlighter-rouge">obj</code> is some kind of <code class="language-plaintext highlighter-rouge">List</code>. It does not tell us what kind of elements the list contains and we must inspect each element individually, if we really care:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">if</span> <span class="o">(</span><span class="n">obj</span> <span class="k">instanceof</span> <span class="nc">List</span><span class="o">&lt;?&gt;</span> <span class="n">list</span> <span class="o">&amp;&amp;</span>
    <span class="n">list</span><span class="o">.</span><span class="na">stream</span><span class="o">().</span><span class="na">allMatch</span><span class="o">(</span><span class="nc">String</span><span class="o">.</span><span class="na">class</span><span class="o">::</span><span class="n">isInstance</span><span class="o">))</span> <span class="o">{</span> <span class="c1">//this check returns true for an empty list as well</span>
     <span class="o">...</span>
<span class="o">}</span>
</code></pre></div></div>
<p>This works, but it is much more verbose than a normal runtime type check. It also changes the nature of the check. We are no longer asking the JVM, “Is this a <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code>?” We are asking, “Is this a <code class="language-plaintext highlighter-rouge">List</code>, and do all of its current elements happen to be strings?”</p>

<h2 id="3-method-overloads-can-clash-after-erasure">3. Method overloads can clash after erasure</h2>

<p>Java lets you overload methods when their parameters are different. For example, this is fine:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kt">void</span> <span class="nf">process</span><span class="o">(</span><span class="nc">String</span> <span class="n">name</span><span class="o">)</span> <span class="o">{...}</span>

<span class="kt">void</span> <span class="nf">process</span><span class="o">(</span><span class="nc">Integer</span> <span class="n">id</span><span class="o">)</span> <span class="o">{...}</span>
</code></pre></div></div>
<p>At runtime these are still different. However, with generics, method overloading gets a little tricky.</p>

<p>You may think that this will work:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kt">void</span> <span class="nf">process</span><span class="o">(</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">&gt;</span> <span class="n">names</span><span class="o">)</span> <span class="o">{...}</span>

<span class="kt">void</span> <span class="nf">process</span><span class="o">(</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">Integer</span><span class="o">&gt;</span> <span class="n">ids</span><span class="o">)</span> <span class="o">{...}</span>
</code></pre></div></div>

<p>But Java rejects this because after type erasure both effectively are the same method:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>void process(List names) {...}
void process(List ids) {...}
</code></pre></div></div>

<p>Both have the same erased signature <code class="language-plaintext highlighter-rouge">void process(List)</code>. The compiler sees the method collision and throws this error:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>name clash: process(List&lt;Integer&gt;) and process(List&lt;String&gt;) have the same erasure
</code></pre></div></div>

<p>The workaround usually is to give methods different names <code class="language-plaintext highlighter-rouge">processNames(List&lt;String&gt; names)</code> and <code class="language-plaintext highlighter-rouge">processIds(List&lt;Integer&gt; ids)</code>.</p>

<p>Another option is to introduce wrapper types:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">record</span> <span class="nf">Names</span><span class="o">(</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">&gt;</span> <span class="n">names</span><span class="o">)</span> <span class="o">{}</span>
<span class="kd">record</span> <span class="nf">Ids</span><span class="o">(</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">Integer</span><span class="o">&gt;</span> <span class="n">ids</span><span class="o">)</span> <span class="o">{}</span>

<span class="kt">void</span> <span class="nf">process</span><span class="o">(</span><span class="nc">Names</span> <span class="n">names</span><span class="o">)</span> <span class="o">{...}</span>

<span class="kt">void</span> <span class="nf">process</span><span class="o">(</span><span class="nc">Ids</span> <span class="n">ids</span><span class="o">)</span> <span class="o">{...}</span>
</code></pre></div></div>
<p>This works because <code class="language-plaintext highlighter-rouge">Names</code> and <code class="language-plaintext highlighter-rouge">Ids</code> are real runtime types. They survive erasure, unlike <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code> and <code class="language-plaintext highlighter-rouge">List&lt;Integer&gt;</code>.</p>

<h2 id="4-generic-arrays-are-painful">4. Generic arrays are painful</h2>

<p>Type erasure also makes arrays and generics uncomfortable together.</p>

<p>In Java, arrays know their component type at runtime. For example, a <code class="language-plaintext highlighter-rouge">String[]</code> knows that it is an array of <code class="language-plaintext highlighter-rouge">String</code>. If you try to put an <code class="language-plaintext highlighter-rouge">Integer</code> into it, the JVM can detect the problem and throw an <code class="language-plaintext highlighter-rouge">ArrayStoreException</code>.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">String</span><span class="o">[]</span> <span class="n">names</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">String</span><span class="o">[</span><span class="mi">10</span><span class="o">];</span>
<span class="nc">Object</span><span class="o">[]</span> <span class="n">values</span> <span class="o">=</span> <span class="n">names</span><span class="o">;</span>

<span class="n">values</span><span class="o">[</span><span class="mi">0</span><span class="o">]</span> <span class="o">=</span> <span class="mi">42</span><span class="o">;</span> <span class="c1">// ArrayStoreException at runtime</span>
</code></pre></div></div>

<p>Generics work differently. A <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code> does not carry <code class="language-plaintext highlighter-rouge">String</code> as a full runtime type in the same way. After erasure, it is mostly just a <code class="language-plaintext highlighter-rouge">List</code>.</p>

<p>That mismatch is why Java does not allow this:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">T</span><span class="o">[]</span> <span class="n">values</span> <span class="o">=</span> <span class="k">new</span> <span class="no">T</span><span class="o">[</span><span class="mi">10</span><span class="o">];</span> <span class="c1">// illegal</span>
</code></pre></div></div>

<p>The runtime does not know what <code class="language-plaintext highlighter-rouge">T</code> really is, so it cannot create an array with the correct component type.</p>

<p>The workaround is to pass the component type explicitly:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">static</span> <span class="o">&lt;</span><span class="no">T</span><span class="o">&gt;</span> <span class="no">T</span><span class="o">[]</span> <span class="nf">createArray</span><span class="o">(</span><span class="nc">Class</span><span class="o">&lt;</span><span class="no">T</span><span class="o">&gt;</span> <span class="n">type</span><span class="o">,</span> <span class="kt">int</span> <span class="n">size</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">return</span> <span class="o">(</span><span class="no">T</span><span class="o">[])</span> <span class="n">java</span><span class="o">.</span><span class="na">lang</span><span class="o">.</span><span class="na">reflect</span><span class="o">.</span><span class="na">Array</span><span class="o">.</span><span class="na">newInstance</span><span class="o">(</span><span class="n">type</span><span class="o">,</span> <span class="n">size</span><span class="o">);</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Usage:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">String</span><span class="o">[]</span> <span class="n">names</span> <span class="o">=</span> <span class="n">createArray</span><span class="o">(</span><span class="nc">String</span><span class="o">.</span><span class="na">class</span><span class="o">,</span> <span class="mi">10</span><span class="o">);</span>
<span class="nc">Integer</span><span class="o">[]</span> <span class="n">ids</span> <span class="o">=</span> <span class="n">createArray</span><span class="o">(</span><span class="nc">Integer</span><span class="o">.</span><span class="na">class</span><span class="o">,</span> <span class="mi">10</span><span class="o">);</span>
</code></pre></div></div>

<p>The generic type <code class="language-plaintext highlighter-rouge">T</code> is known to the compiler, but not enough is available at runtime. So the API asks the caller to pass a <code class="language-plaintext highlighter-rouge">Class&lt;T&gt;</code> token manually.</p>

<p>This is another cost of type erasure. The type appears obvious in the source code, but runtime code still needs an explicit type descriptor to do the right thing.</p>

<h2 id="why-these-workarounds-work">Why these workarounds work</h2>

<p>Type erasure is not total. Java still records generic type information in the class file, in a metadata section called the <code class="language-plaintext highlighter-rouge">Signature</code> attribute. This is kept for declarations: fields, method parameters and return types, and a class’s generic superclass and interfaces. What gets erased is the type of a value at runtime. A <code class="language-plaintext highlighter-rouge">List&lt;String&gt;</code> object and a <code class="language-plaintext highlighter-rouge">List&lt;Integer&gt;</code> object share the same <code class="language-plaintext highlighter-rouge">List.class</code>, so an object cannot tell you its element type. But a declaration can.</p>

<p>That retained information is readable through reflection. <code class="language-plaintext highlighter-rouge">Field.getGenericType()</code>, <code class="language-plaintext highlighter-rouge">Method.getGenericReturnType()</code>, and <code class="language-plaintext highlighter-rouge">Class.getGenericSuperclass()</code> return a <code class="language-plaintext highlighter-rouge">java.lang.reflect.Type</code>, which can be a <code class="language-plaintext highlighter-rouge">ParameterizedType</code> such as <code class="language-plaintext highlighter-rouge">List&lt;User&gt;</code> rather than a plain <code class="language-plaintext highlighter-rouge">List</code>.</p>

<p>This is the trick behind <code class="language-plaintext highlighter-rouge">TypeReference</code>, <code class="language-plaintext highlighter-rouge">TypeToken</code>, and <code class="language-plaintext highlighter-rouge">ParameterizedTypeReference</code>. Writing <code class="language-plaintext highlighter-rouge">new TypeReference&lt;List&lt;User&gt;&gt;() {}</code> creates an anonymous subclass, and its generic superclass <code class="language-plaintext highlighter-rouge">TypeReference&lt;List&lt;User&gt;&gt;</code> is a declaration. So <code class="language-plaintext highlighter-rouge">List&lt;User&gt;</code> is preserved in that subclass’s metadata, and the library recovers it with <code class="language-plaintext highlighter-rouge">getClass().getGenericSuperclass()</code>:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">Type</span> <span class="n">type</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">TypeReference</span><span class="o">&lt;</span><span class="nc">List</span><span class="o">&lt;</span><span class="nc">User</span><span class="o">&gt;&gt;()</span> <span class="o">{}</span>
    <span class="o">.</span><span class="na">getClass</span><span class="o">()</span>
    <span class="o">.</span><span class="na">getGenericSuperclass</span><span class="o">();</span> <span class="c1">// ParameterizedType: List&lt;User&gt;</span>
</code></pre></div></div>

<h2 id="conclusion">Conclusion</h2>

<p>Once your code crosses a runtime boundary, assume the generic type will not be there. Design the API to carry the type explicitly, through a <code class="language-plaintext highlighter-rouge">Class&lt;T&gt;</code> token, a <code class="language-plaintext highlighter-rouge">TypeReference&lt;T&gt;</code>, a wrapper type, or a type tag you store in the data yourself, rather than trusting that the compiler’s view of the type survives into runtime.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="[&quot;Computer Science&quot;]" /><category term="computer-science" /><category term="java" /><category term="type-erasure" /><category term="programming-language" /><summary type="html"><![CDATA[Generic types in Java are excellent for compile-time safety, but weak as runtime type descriptors. Whenever a framework crosses a runtime boundary such as JSON, reflection, dependency injection, messaging, persistence, or RPC, it often needs an explicit replacement for the erased generic type information.]]></summary></entry><entry><title type="html">Renaming a Linux User Without Losing Your Setup</title><link href="https://systemhalted.in/2026/05/30/renaming-a-linux-user-without-losing-your-setup/" rel="alternate" type="text/html" title="Renaming a Linux User Without Losing Your Setup" /><published>2026-05-30T11:00:00+00:00</published><updated>2026-05-30T11:00:00+00:00</updated><id>https://systemhalted.in/2026/05/30/renaming-a-linux-user-without-losing-your-setup</id><content type="html" xml:base="https://systemhalted.in/2026/05/30/renaming-a-linux-user-without-losing-your-setup/"><![CDATA[<p>When I installed Ubuntu on a spare laptop, my intent was to make it usable for my son. 
So, I named the account <code class="language-plaintext highlighter-rouge">old-user</code> (obfuscated for obvious reasons). However, my son
moved on and took my old MacBook Pro, leaving this laptop for me. The first thing I wanted to 
do was personalize it by renaming the account to <code class="language-plaintext highlighter-rouge">systemhalted</code> everywhere: login name, home 
directory, primary group, and the name shown on the GNOME login screen.</p>

<p>I wanted to do this without losing my existing shell configuration, installed tools, IDE state, 
and Claude Code session history.</p>

<p>It turns out a complete rename is very doable. The data-loss fear is mostly misplaced. The real
risk is not deleted files, but stale hard-coded paths. In this post, I cover exactly how I did it.</p>

<h2 id="a-little-gotcha-before-we-begin">A Little Gotcha Before We Begin</h2>

<p><code class="language-plaintext highlighter-rouge">usermod</code> refuses to touch an account that is logged in or has running processes:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>usermod: user old-user is currently used by process NNNN
</code></pre></div></div>

<p>Since this was the <strong>only</strong> admin account on the machine, I couldn’t rename it while
logged into it. The fix is a throwaway second admin account that does the surgery while
the real account is fully logged out.</p>

<p>With that, here are the steps to change the identity of an existing user.</p>

<h2 id="step-1--create-a-temporary-admin">Step 1 — Create a temporary admin</h2>

<p>While still logged in as the old user:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo </span>adduser tempadmin
<span class="nb">sudo </span>usermod <span class="nt">-aG</span> <span class="nb">sudo </span>tempadmin
</code></pre></div></div>

<h2 id="step-2--log-out-completely-and-switch">Step 2 — Log out completely and switch</h2>

<p>This part matters: <strong>Log Out</strong> of GNOME — not lock, not “Switch User”. The old session
must actually end. Then log in as <code class="language-plaintext highlighter-rouge">tempadmin</code> at the greeter and open a terminal.</p>

<h2 id="step-3--confirm-the-old-account-is-truly-idle-if-needed-terminate-the-sessions">Step 3 — Confirm the old account is truly idle; if needed terminate the sessions</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">who</span>                                   <span class="c"># old user should not appear</span>
pgrep <span class="nt">-u</span> old-user                     <span class="c"># should print nothing</span>
<span class="nb">sudo </span>loginctl terminate-user old-user 2&gt;/dev/null
pgrep <span class="nt">-u</span> old-user <span class="o">||</span> <span class="nb">echo</span> <span class="s2">"clear - safe to proceed"</span>
</code></pre></div></div>
<p>Proceed to Step 4 if the message says <code class="language-plaintext highlighter-rouge">clear - safe to proceed</code>.</p>

<p>Before renaming, record the account’s current numbers so you can confirm nothing shifted
afterward — and so you’re not assuming mine:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">id </span>old-user        <span class="c"># note the uid=, gid=, and the full groups= list</span>
</code></pre></div></div>

<p>On my machine both the UID and GID were <strong>1000</strong> (the first account the Ubuntu installer
creates). <strong>Yours may differ</strong> — on a multi-user box, a migrated system, or one with service
accounts, the first human user isn’t always 1000. Whatever your values are, they should be
<em>identical</em> before and after; keeping them unchanged is exactly why we never pass <code class="language-plaintext highlighter-rouge">-u</code>.</p>

<h2 id="step-4--the-actual-rename">Step 4 — The actual rename</h2>

<p>Three commands do the core work:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Rename the login AND move/rename the home dir (last arg is the CURRENT name):</span>
<span class="nb">sudo </span>usermod <span class="nt">-l</span> systemhalted <span class="nt">-d</span> /home/systemhalted <span class="nt">-m</span> old-user

<span class="c"># Rename the matching private group; the GID stays unchanged:</span>
<span class="nb">sudo </span>groupmod <span class="nt">-n</span> systemhalted old-user

<span class="c"># Update the display/full name shown at the login screen:</span>
<span class="nb">sudo </span>usermod <span class="nt">-c</span> <span class="s2">"systemhalted"</span> systemhalted
</code></pre></div></div>

<p>Why this is safe: the <strong>UID stays unchanged, 1000 on my machine</strong> — <code class="language-plaintext highlighter-rouge">usermod -l</code> changes the
login name and <code class="language-plaintext highlighter-rouge">-d -m</code> moves the home directory’s contents, but the UID stays put because
I’m not passing <code class="language-plaintext highlighter-rouge">-u</code>. With the numeric owner unchanged, <code class="language-plaintext highlighter-rouge">usermod -m</code> <em>moves</em> the home
directory and tries to adapt ownership, permissions, ACLs, and extended attributes under the
new path — though the manpage notes some cases may still need manual fixing. In the normal
same-UID case, the intent is relocation rather than deletion, but I still treated backup as 
mandatory. The account’s authentication entry is preserved through the rename, so the same 
password keeps working.</p>

<h2 id="step-5--fix-what-usermod-doesnt-touch">Step 5 — Fix what usermod doesn’t touch</h2>

<p>This is where the real work hides. <code class="language-plaintext highlighter-rouge">usermod</code> renames the account, but several things keep
pointing at the old path or the old name.</p>

<p><strong>(a) Hard-coded paths.</strong> A scan of my home turned up ~196 files under <code class="language-plaintext highlighter-rouge">.config</code>,
<code class="language-plaintext highlighter-rouge">.local</code>, and <code class="language-plaintext highlighter-rouge">.claude</code> containing the literal string <code class="language-plaintext highlighter-rouge">/home/old-user</code> — almost all
of it, in my case, JetBrains and VS Code state. Editing them in bulk is a trap:
many are binary or fragile JSON, and a stray <code class="language-plaintext highlighter-rouge">sed</code> can corrupt them. The clean, reversible 
fix is a single compatibility symlink:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo ln</span> <span class="nt">-s</span> /home/systemhalted /home/old-user
</code></pre></div></div>

<p>Now every stale <code class="language-plaintext highlighter-rouge">/home/old-user/...</code> reference resolves transparently. No file edits,
no corruption risk. It’s not entirely free, though — a lingering symlink can confuse
backups, scripts, future users, or security scans — so keep it (documented) until you’re
confident nothing references the old path, then remove it.</p>

<p><strong>(b) The user crontab spool</strong> isn’t auto-renamed (the same goes for <code class="language-plaintext highlighter-rouge">at</code> jobs, if you
use them):</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">f</span><span class="o">=</span>/var/spool/cron/crontabs/old-user
<span class="nb">sudo test</span> <span class="nt">-f</span> <span class="s2">"</span><span class="nv">$f</span><span class="s2">"</span> <span class="o">&amp;&amp;</span> <span class="nb">sudo mv</span> <span class="s2">"</span><span class="nv">$f</span><span class="s2">"</span> /var/spool/cron/crontabs/systemhalted <span class="se">\</span>
  <span class="o">&amp;&amp;</span> <span class="nb">sudo chown </span>systemhalted:crontab /var/spool/cron/crontabs/systemhalted
</code></pre></div></div>

<p><strong>(c) GNOME’s AccountsService</strong> keeps per-user login-screen prefs keyed by name:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">f</span><span class="o">=</span>/var/lib/AccountsService/users/old-user
<span class="nb">sudo test</span> <span class="nt">-f</span> <span class="s2">"</span><span class="nv">$f</span><span class="s2">"</span> <span class="o">&amp;&amp;</span> <span class="nb">sudo mv</span> <span class="s2">"</span><span class="nv">$f</span><span class="s2">"</span> /var/lib/AccountsService/users/systemhalted
</code></pre></div></div>

<p><strong>(d) Claude Code session history.</strong> Claude Code names its project folders after the
working directory. Mine were all <code class="language-plaintext highlighter-rouge">-home-old-user-*</code>, so prior session history was
keyed to the old path:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cd</span> /home/systemhalted/.claude/projects

<span class="k">for </span>d <span class="k">in</span> <span class="nt">-home-old-user</span><span class="k">*</span><span class="p">;</span> <span class="k">do
  </span><span class="nb">mv</span> <span class="s2">"./</span><span class="nv">$d</span><span class="s2">"</span> <span class="s2">"./</span><span class="k">${</span><span class="nv">d</span><span class="p">/-home-old-user/-home-systemhalted</span><span class="k">}</span><span class="s2">"</span>
<span class="k">done</span>
</code></pre></div></div>

<p>Two gotchas bit me here. First, the directory names start with <code class="language-plaintext highlighter-rouge">-</code>, so every tool treats
them as options — prefix paths with <code class="language-plaintext highlighter-rouge">./</code> (or use <code class="language-plaintext highlighter-rouge">--</code>) or you’ll get a wall of
<code class="language-plaintext highlighter-rouge">invalid option -- 'h'</code>. Second, a <code class="language-plaintext highlighter-rouge">-home-systemhalted</code> folder already existed from a
session run <em>after</em> the home move, so the bare rename would collide. I merged that one
instead of moving it:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cp</span> <span class="nt">-a</span> <span class="nt">--update</span><span class="o">=</span>none <span class="s2">"./-home-old-user/."</span> <span class="s2">"./-home-systemhalted/"</span> <span class="se">\</span>
  <span class="o">&amp;&amp;</span> <span class="nb">rm</span> <span class="nt">-rf</span> <span class="s2">"./-home-old-user"</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">--update=none</code> means any file that already exists at the destination is left untouched —
it’s never overwritten, regardless of timestamps.</p>

<h2 id="step-6--verify-before-trusting-it">Step 6 — Verify before trusting it</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>getent passwd systemhalted    <span class="c"># home, shell, GECOS all correct</span>
getent group  systemhalted    <span class="c"># same group, GID unchanged (1000 on mine)</span>
<span class="nb">id </span>systemhalted               <span class="c"># the important one</span>
<span class="nb">ls</span> <span class="nt">-ld</span> /home/systemhalted     <span class="c"># owned systemhalted:systemhalted</span>
<span class="nb">ls</span> <span class="nt">-ld</span> /home/old-user         <span class="c"># symlink -&gt; /home/systemhalted</span>
</code></pre></div></div>

<p>The line I cared most about was <code class="language-plaintext highlighter-rouge">id</code>, confirming the renamed account was still in <strong>both</strong>
<code class="language-plaintext highlighter-rouge">sudo</code> and <code class="language-plaintext highlighter-rouge">docker</code> — i.e. admin and container access carried over intact.</p>

<h2 id="step-7--reboot-and-live-in-it">Step 7 — Reboot and live in it</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo </span>reboot
</code></pre></div></div>

<p>Log in as <code class="language-plaintext highlighter-rouge">systemhalted</code> with the old password. Terminal opens in <code class="language-plaintext highlighter-rouge">/home/systemhalted</code>,
the IDEs launch with their state, <code class="language-plaintext highlighter-rouge">docker ps</code> works, my shell tooling works, and Claude
Code shows all the prior history.</p>

<h2 id="step-8--remove-the-temporary-admin">Step 8 — Remove the temporary admin</h2>

<p>Only after the renamed account is confirmed working:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo </span>deluser <span class="nt">--remove-home</span> tempadmin
</code></pre></div></div>

<p>Worth knowing: if <code class="language-plaintext highlighter-rouge">deluser</code> ever runs <em>without</em> <code class="language-plaintext highlighter-rouge">--remove-home</code> (or partially), it leaves
two orphans behind — <code class="language-plaintext highlighter-rouge">/home/tempadmin</code> and <code class="language-plaintext highlighter-rouge">/var/lib/AccountsService/users/tempadmin</code> —
which you then clean up by hand:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo rm</span> <span class="nt">-rf</span> /home/tempadmin
<span class="nb">sudo rm</span> /var/lib/AccountsService/users/tempadmin
</code></pre></div></div>

<h2 id="rollback-just-in-case">Rollback, just in case</h2>

<p>Everything is reversible from the <code class="language-plaintext highlighter-rouge">tempadmin</code> session until you delete it. If anything
looked wrong, I had this ready:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo rm</span> /home/old-user
<span class="nb">sudo </span>usermod <span class="nt">-l</span> old-user <span class="nt">-d</span> /home/old-user <span class="nt">-m</span> systemhalted
<span class="nb">sudo </span>groupmod <span class="nt">-n</span> old-user systemhalted
<span class="nb">sudo </span>usermod <span class="nt">-c</span> <span class="s2">"Old User"</span> old-user
</code></pre></div></div>

<h2 id="important-notes-and-observations">Important Notes and Observations</h2>

<ul>
  <li><strong>No data was lost in my case</strong> — a same-UID rename <em>moves</em> files; it doesn’t delete them by design.</li>
  <li><strong>The danger is stale paths, not lost files</strong> — and one symlink neutralizes all of them.</li>
  <li><strong>Never bulk-<code class="language-plaintext highlighter-rouge">sed</code> IDE state</strong> — it’s binary/JSON and corrupts easily.</li>
  <li><strong>Secrets mostly survive, but check them.</strong> GNOME Keyring is unlocked by your login
password, which didn’t change, so keyring-backed secrets keep working (maybe a one-time
unlock prompt). Saved Wi-Fi depends on setup — NetworkManager profiles may be system-wide,
per-user, or keyring-backed — so verify rather than assume.</li>
  <li><strong>The compatibility symlink is practical, not free.</strong> It saves you from editing hundreds
of files, but document it and remove it once you’re sure nothing uses the old path.</li>
</ul>

<p>The whole thing took one reboot and zero reinstalls. The account that started life as
<code class="language-plaintext highlighter-rouge">old-user</code> is now <code class="language-plaintext highlighter-rouge">systemhalted</code> as far as normal desktop and shell tooling are concerned.
(The kernel itself never cared — to it, credentials are numeric UIDs and GIDs, not names;
the login name was only ever a label on top of UID 1000.)</p>

<hr />

<p><em>Disclaimer: This worked on my single-admin Ubuntu/GNOME machine, and I’m sharing it as a
record of what I did — not as a guaranteed recipe for yours. Renaming a user touches login,
ownership, and system state, so treat every command here as something to understand before
you run it, not to paste blindly. Setups differ (other desktops, network/LDAP accounts,
encrypted or NFS home directories, services running as the user), and any of those can change
the outcome. <strong>Take a backup first, keep the <code class="language-plaintext highlighter-rouge">tempadmin</code> escape hatch until you’ve confirmed
everything works, and proceed at your own risk.</strong> The username here (<code class="language-plaintext highlighter-rouge">old-user</code>) is a
placeholder; the real one has been obfuscated.</em></p>]]></content><author><name>Palak Mathur</name></author><category term="Technology" /><category term="Software Engineering" /><category term="linux" /><category term="ubuntu" /><category term="sysadmin" /><category term="usermod" /><category term="technology" /><category term="software" /><summary type="html"><![CDATA[When I installed Ubuntu on a spare laptop, my intent was to make it usable for my son. So, I named the account old-user (obfuscated for obvious reasons). However, my son moved on and took my old MacBook Pro, leaving this laptop for me. The first thing I wanted to do was personalize it by renaming the account to systemhalted everywhere: login name, home directory, primary group, and the name shown on the GNOME login screen.]]></summary></entry><entry><title type="html">Saving Private Notes</title><link href="https://systemhalted.in/2026/05/08/saving-private-notes/" rel="alternate" type="text/html" title="Saving Private Notes" /><published>2026-05-08T00:00:00+00:00</published><updated>2026-05-08T00:00:00+00:00</updated><id>https://systemhalted.in/2026/05/08/saving-private-notes</id><content type="html" xml:base="https://systemhalted.in/2026/05/08/saving-private-notes/"><![CDATA[<p>I had over 1000 notes in Apple Notes when I finally decided to clean them up. Most were in a folder called “Misc” or sitting loose in the root. Some were years old. A few I did not recognise as mine.</p>

<p>The structure, if you can call it that, was two systems running side by side and neither of them working. I had read about Zettelkasten somewhere, read a book about it, watched some videos, and set up the standard folders — Inbox, Input, Output, Zettel — without ever using them. Alongside that I had an older hierarchy of Work, Personal, and Writing, where I was actually saving things, more or less at random. Whichever folder I thought of first got the note. I had been telling myself this was fine because the notes were captured, and search would do the rest. Search did not do the rest. Most of the time I did not know what to search for.</p>

<h2 id="why-i-finally-bothered">Why I finally bothered</h2>

<p>I am an engineering manager. In a normal week I need notes from team 1:1s, architecture decisions, books I am reading, an AI/ML study plan I run at weekends, ideas for writing, astrophotography logs, and guitar stuff. None of that is unusual. What forced the cleanup was that several times in a couple of months, I needed a specific note before a meeting and could not find it in time.</p>

<p>The problem was not that I had too many notes. It was that I had never decided what the system was supposed to do.</p>

<h2 id="simplification">Simplification</h2>

<p>One Saturday I sat down and wrote out what I actually use notes for: work, personal life, things I am learning, writing I am working on, a daily journal, random ideas, and an archive for things I am done with. That came out as eight buckets, which I numbered so they would sort in the order I wanted:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>00 Inbox
10 Work
20 Personal
30 Learning
40 Writing
50 Journal
60 Ideas
99 Archive
</code></pre></div></div>

<p>Each has a few subfolders. Work has Team Management, Meetings, Architecture, and Decisions. Learning has Books, Articles, Videos, Courses, and a Subjects folder where I keep my own synthesis on topics I am studying over time. Writing splits into Ideas, Drafts, Articles, Poetry, Stories, Books, and Published. The old Zettelkasten folders went into Archive. I was not using them, and pretending I would was part of why the system was a mess.</p>

<p>I learned later that what I had built was close to a combination of two methods I had not heard of when I started. PARA (Projects, Areas, Resources, Archives) organises by how actionable something is, not by topic. Johnny Decimal is a numbering scheme that gives every folder a permanent ID. People combine the two, and what I had was a rough version of that combination. It was nice to know but did not change anything. The structure worked because it matched how I think, not because it had a name.</p>

<h2 id="the-rule-that-fixed-the-overlap">The rule that fixed the overlap</h2>

<p>The other thing I had been doing wrong, which the cleanup made obvious, was mixing notes and tasks. Things that belonged in Reminders were living in Apple Notes, and the other way around, and I was sometimes updating both for the same thing without realising it.</p>

<p>The rule I went with is simple. If it has a “done” state, it goes in Reminders. If it does not, it goes in Notes. Tasks, follow-ups, and things to keep an eye on go to Reminders; knowledge, drafts, and references go to Notes. It sounds obvious written down, but I had not been doing it. Once I started, the overlap was gone, and so was most of the duplication that came with it.</p>

<h2 id="what-id-actually-tell-someone">What I’d actually tell someone</h2>

<p>The cleanup itself was not the hard part. The hard part was admitting that the Zettelkasten folders I had set up years earlier were aspirational, not active. I was impressed by how useful it was for Niklas Luhmann and thought it would be useful for me as well in the same way it was for him. However, these folders had been sitting there making the system look organised while making the actual mess worse.</p>

<p>Most of the work was being honest about what I really do with notes — capture things, look them up later, occasionally write something longer — and building the smallest structure that supported those three things. No folders that existed only because some method I had read about said they should.</p>

<p>If you are sitting on your own version of a thousand unfiled notes, do not go looking for a method to copy. Write down what you actually use notes for, build the folders that match, and leave room to fix it later. The other thing — and I am saying this because I ignored my own advice for years — is that half an hour once or twice a week spent clearing out the Inbox goes a long way. The cleanup itself is a one-time event. Keeping it clean is not.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Personal Essays" /><category term="Technology" /><category term="notes" /><category term="productivity" /><category term="apple-notes" /><category term="para" /><category term="johnny-decimal" /><category term="zettelkasten" /><summary type="html"><![CDATA[How I cleaned up a thousand Apple Notes by being honest about what I actually use notes for, building a small folder structure to match, and drawing a hard line between notes and tasks.]]></summary></entry><entry><title type="html">Insight Agents and the End of Dashboard-Driven Analytics</title><link href="https://systemhalted.in/2026/02/06/insight-agents-end-of-dashboards/" rel="alternate" type="text/html" title="Insight Agents and the End of Dashboard-Driven Analytics" /><published>2026-02-06T00:00:00+00:00</published><updated>2026-02-06T00:00:00+00:00</updated><id>https://systemhalted.in/2026/02/06/insight-agents-end-of-dashboards</id><content type="html" xml:base="https://systemhalted.in/2026/02/06/insight-agents-end-of-dashboards/"><![CDATA[<p>I have just finished reading the Amazon Research paper <em>“Insight Agents: An LLM-Based Multi-Agent System for Data Insights”</em><sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>, and it is, I think, the first genuinely production-minded attempt I have seen to close the long-standing gap between dashboards that <em>show</em> data and systems that actually help people <em>decide</em> anything on the basis of it. The paper describes a hierarchical multi-agent system that, somewhat unusually, seems to actually understand the chain by which a business question becomes a data query and then becomes an insight, rather than treating that chain as a single LLM prompt to be optimised.</p>

<p>What stood out to me, reading through it, was less the model architecture than the engineering discipline behind the choice of where to use which kind of model. The authors did not, in fact, reach for an LLM as the answer to every problem, which is increasingly unusual in this space. Instead, they appear to have asked, at each stage of the pipeline, what the cheapest model that does the job correctly actually is, and to have used that. Two of the numbers in the paper are particularly striking:</p>

<ul>
  <li>
    <p>An auto-encoder handles intent detection in <strong>0.009 seconds</strong> instead of 1.6 seconds.</p>
  </li>
  <li>
    <p>A fine-tuned BERT model handles routing in <strong>0.3 seconds</strong> instead of ~2 seconds.</p>
  </li>
</ul>

<p>The LLM, in their architecture, only enters the picture once this fast triage stage has narrowed the problem space — at which point it is being used for what large language models are actually good at, which is reasoning over a focused problem and generating narrative explanations for a human reader.</p>

<p>They also, sensibly, avoid the naive Text-to-SQL approach that has become almost a cliché in this area. Instead, they describe an augmented querying flow that brings business context, internal APIs, and a plan-and-execute style of decomposition to bear on the question. The system breaks a query into a sequence of steps, fetches the right data at each step, and produces explanations that a human reader can actually act on, rather than a single SQL query that is correct in the abstract but unhelpful in context. In their reported evaluation, the system holds 90th-percentile latency under roughly 13 seconds, with about 89% relevance and correctness as judged by human raters — which, for an agentic pipeline of this kind, is a meaningfully better number than I would have expected.</p>

<p>The most important idea in the paper, however, is, I think, the one that follows from all of this rather than being stated outright. It is the implicit observation that, in the model described, the user is no longer expected to navigate a dashboard at all. They are expected, instead, to ask questions of a system that already understands the schema, the metrics, the seasonality of the business, and the internal vocabulary that the team uses to talk about what is happening — and to receive, in response, an explanation of what happened and, where the data supports it, why it happened.</p>

<p>This is not, to be clear, an argument for replacing BI teams or data engineers; on the contrary, it is an argument for amplifying them. What this kind of system promises, if it works at the scale claimed, is to turn the underlying data infrastructure into something a non-specialist part of the business can actually query in plain language, and to receive a structured explanation back rather than a chart that someone still has to interpret. The future of analytics, on this view, is less likely to be a continued proliferation of dashboards and more likely to be a steady shift toward conversational understanding layered on top of structured data — with dashboards retained, in the end, mostly for the cases in which a human still wants to look at the underlying time series themselves.</p>

<p>If you are working on analytics platforms, on GenAI agents, or on data products of any meaningful scale, I would encourage you to read the paper end to end. It is, by some distance, the most thoughtful treatment of where to put which kind of intelligence in an agentic data system that I have come across in the last year.</p>

<h2 id="references">References</h2>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Paper, https://arxiv.org/pdf/2601.20048 <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Software Engineering" /><category term="Computer Science" /><category term="Data" /><category term="AI" /><category term="analytics" /><category term="agentic-ai" /><category term="genai" /><category term="llm" /><category term="multi-agent-systems" /><category term="data-insights" /><category term="business-intelligence" /><category term="amazon-research" /><summary type="html"><![CDATA[Why Insight Agents signal a shift from dashboard-driven analytics to conversational, agentic systems that prioritize speed, context, and real business understanding.]]></summary></entry><entry><title type="html">Part 8: Big Decimal Rounding Modes - Why HALF_UP Isn’t Always the Answer</title><link href="https://systemhalted.in/2026/02/05/rounding-modes-why-half-up-isnt-always-the-answer/" rel="alternate" type="text/html" title="Part 8: Big Decimal Rounding Modes - Why HALF_UP Isn’t Always the Answer" /><published>2026-02-05T00:00:00+00:00</published><updated>2026-02-05T00:00:00+00:00</updated><id>https://systemhalted.in/2026/02/05/rounding-modes-why-half-up-isnt-always-the-answer</id><content type="html" xml:base="https://systemhalted.in/2026/02/05/rounding-modes-why-half-up-isnt-always-the-answer/"><![CDATA[<p><em>This post is part of my <a href="https://systemhalted.in/categories/#cat-series-4-floating-point-without-tears">Floating Point Without Tears</a> series on how Java numbers misbehave and how to live with them.</em></p>

<p>In <a href="https://systemhalted.in/2026/01/11/kahan-summation-java-streams/">Part 7</a> of this series, we looked at summation error and how Kahan compensation can keep a long reduction from quietly losing low-order bits. This post is about a different and, in some ways, more consequential precision trap: the moment at which a value is rounded down to fewer digits in order to be displayed, stored, or reported.</p>

<p>Rounding looks like a small detail in the code, and it almost never is one. It is the place where many otherwise-correct calculations end up disagreeing with audits, ledgers, and reconciliations, often in ways that are difficult to diagnose because the disagreement only appears at scale. Most teams I have seen pick a rounding mode in roughly the same way that most people pick a film on a streaming service — by going with whichever option happened to be already playing — and in Java, the option that happens to be already playing is very often <code class="language-plaintext highlighter-rouge">HALF_UP</code>, on the implicit assumption that this is “normal” rounding.</p>

<blockquote>
  <p>“We’ll use <code class="language-plaintext highlighter-rouge">HALF_UP</code>. That’s normal rounding. Done.”</p>
</blockquote>

<p>Then a pricing engine ships, or a statement generator, or a ledger, or a tax calculator, or an amortization schedule — and at some point afterwards it becomes apparent that <strong>rounding is policy</strong>, not arithmetic. Or, more precisely, it is arithmetic with consequences, and the choice of which rounding mode to apply turns out to be a product decision wearing mathematical clothing. This post is about how to make that choice deliberately, and about why <code class="language-plaintext highlighter-rouge">HALF_UP</code> is not the universal solvent it is so often assumed to be.</p>

<h2 id="cheat-sheet">Quick Reference: Rounding Mode Cheat Sheet</h2>

<table>
  <thead>
    <tr>
      <th>Mode</th>
      <th>Behavior</th>
      <th>When</th>
      <th>Jump</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">HALF_EVEN</code></td>
      <td>Ties -&gt; nearest even digit</td>
      <td>Aggregates, reducing bias</td>
      <td><a href="#use-half-even">↓</a></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">HALF_UP</code></td>
      <td>Ties -&gt; away from zero</td>
      <td>Schoolbook rounding, retail</td>
      <td><a href="#use-half-up">↓</a></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">HALF_DOWN</code></td>
      <td>Ties -&gt; toward zero</td>
      <td>Policy requires ties toward zero (rare; document it)</td>
      <td><a href="#toolbox">↓</a></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">UP</code></td>
      <td>Always away from zero</td>
      <td>Conservative bounds (never underestimate magnitude)</td>
      <td><a href="#toolbox">↓</a></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">DOWN</code></td>
      <td>Always toward zero</td>
      <td>Fee caps, conservative limits</td>
      <td><a href="#use-down">↓</a></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">CEILING</code></td>
      <td>Toward +∞ (1.231 -&gt; 1.24, -1.231 -&gt; -1.23)</td>
      <td>“At least” constraints</td>
      <td><a href="#use-ceiling-floor">↓</a></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">FLOOR</code></td>
      <td>Toward -∞ (1.231 -&gt; 1.23, -1.231 -&gt; -1.24)</td>
      <td>“At most” constraints</td>
      <td><a href="#use-ceiling-floor">↓</a></td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">UNNECESSARY</code></td>
      <td>Throw if rounding needed</td>
      <td>Validation, catching assumptions</td>
      <td><a href="#use-unnecessary">↓</a></td>
    </tr>
  </tbody>
</table>

<p><strong>Key rules:</strong></p>
<ul>
  <li>Avoid rounding double when policy matters: use BigDecimal from strings → <a href="#classic-trap">The Classic Trap</a></li>
  <li>Decide <em>when</em> to round, not just <em>how</em> → <a href="#rounding-timing">Rounding Timing</a></li>
  <li>For money, use scaled integers internally → <a href="#money-pattern">Money Pattern</a></li>
</ul>

<hr />

<h2 id="ties">The real problem: ties (the 5s)</h2>

<p>The drama in rounding, almost without exception, is not really about choosing between <code class="language-plaintext highlighter-rouge">2.341</code> and <code class="language-plaintext highlighter-rouge">2.34</code>. It is about <em>ties</em> — values that lie exactly halfway between two representable steps at the precision you are rounding to.</p>

<p>At two decimal places, the troublesome values are the ones that look like this:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">1.005</code></li>
  <li><code class="language-plaintext highlighter-rouge">2.675</code></li>
  <li><code class="language-plaintext highlighter-rouge">10.125</code></li>
</ul>

<p>It is worth being precise about what counts as a tie, because the term is sometimes applied loosely to values that are not, strictly speaking, halfway between anything. A value is a tie at a given scale only when the first discarded digit is exactly <code class="language-plaintext highlighter-rouge">5</code> and all subsequent discarded digits are exactly <code class="language-plaintext highlighter-rouge">0</code>. So <code class="language-plaintext highlighter-rouge">1.005</code> is a tie at two decimal places, and so is <code class="language-plaintext highlighter-rouge">1.00500…</code>, but <code class="language-plaintext highlighter-rouge">1.0051</code> is not a tie — it is, on inspection, closer to <code class="language-plaintext highlighter-rouge">1.01</code> than to <code class="language-plaintext highlighter-rouge">1.00</code>, and any reasonable rounding mode will produce <code class="language-plaintext highlighter-rouge">1.01</code> regardless of how it handles ties.</p>

<p>The reason ties matter so much in practice is that, depending on which way the rounding mode resolves them, the cumulative effect across many operations can be quite different. If you consistently push ties in one direction — say, always upward — you introduce a systematic bias into every aggregate that depends on those rounded values. Sometimes that bias is exactly what the domain wants (retail prices, for instance, often round in a particular direction by convention); often it is not, occasionally it is actually prohibited by regulation or contract, and even when it is none of those things, it is the kind of pattern that tends to make reconciliation teams unhappy when the totals begin to drift.</p>

<h2 id="toolbox">Java’s rounding toolbox</h2>

<p>Java’s standard library, in <code class="language-plaintext highlighter-rouge">java.math.RoundingMode</code>, exposes a fairly complete set of rounding policies. The interesting question, in the end, is rarely which of them is “available” — they all are — but rather which of them matches the contract the domain actually wants enforced. The available modes are:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">HALF_UP</code> - round to nearest; if exactly halfway, round away from zero (1.5 -&gt; 2, -1.5 -&gt; -2)</li>
  <li><code class="language-plaintext highlighter-rouge">HALF_DOWN</code> - round to nearest; if exactly halfway, round toward zero (1.5 -&gt; 1, -1.5 -&gt; -1)</li>
  <li><code class="language-plaintext highlighter-rouge">HALF_EVEN</code> - round to nearest; if exactly halfway, round to the result whose last kept digit is even (banker’s rounding, also called round-half-to-even)</li>
  <li><code class="language-plaintext highlighter-rouge">UP</code> - always away from zero</li>
  <li><code class="language-plaintext highlighter-rouge">DOWN</code> - always toward zero (truncate)</li>
  <li><code class="language-plaintext highlighter-rouge">CEILING</code> - toward positive infinity (-1.231 -&gt; -1.23, 1.231 -&gt; 1.24 at 2dp)</li>
  <li><code class="language-plaintext highlighter-rouge">FLOOR</code> - toward negative infinity (-1.231 -&gt; -1.24, 1.231 -&gt; 1.23 at 2dp)</li>
  <li><code class="language-plaintext highlighter-rouge">UNNECESSARY</code> - throw if rounding would be required (which I have come to think of as a “make bugs loud” mode)</li>
</ul>

<p>It is also worth recalling that calling <code class="language-plaintext highlighter-rouge">setScale(...)</code> without specifying a rounding mode will, if rounding turns out to be required, throw — which is a sensible default but is occasionally surprising:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1.234"</span><span class="o">).</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">);</span> <span class="c1">// throws ArithmeticException</span></code></pre></figure>

<p>And the most important practical rule, which I find myself repeating in code review more often than any other rule in this area:</p>

<p><strong>If you care about exact decimal policy, avoid rounding a <code class="language-plaintext highlighter-rouge">double</code>. Round a <code class="language-plaintext highlighter-rouge">BigDecimal</code> created from a string (or from an exact integer scale).</strong></p>

<h3 id="classic-trap">The classic trap: <code class="language-plaintext highlighter-rouge">new BigDecimal(double)</code></h3>

<p>This is the trap that catches almost everyone at least once, and it is worth showing in code rather than just describing in prose:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kn">import</span> <span class="nn">java.math.BigDecimal</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">java.math.RoundingMode</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">class</span> <span class="nc">RoundingTrap</span> <span class="o">{</span>
  <span class="kd">public</span> <span class="kd">static</span> <span class="kt">void</span> <span class="nf">main</span><span class="o">(</span><span class="nc">String</span><span class="o">[]</span> <span class="n">args</span><span class="o">)</span> <span class="o">{</span>
    <span class="nc">BigDecimal</span> <span class="n">a</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="mf">1.005</span><span class="o">);</span>               <span class="c1">// from double</span>
    <span class="nc">BigDecimal</span> <span class="n">b</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1.005"</span><span class="o">);</span>             <span class="c1">// from string</span>

    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">a</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">));</span> <span class="c1">// 1.00</span>
    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">b</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">));</span> <span class="c1">// 1.01</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>The expectation, of course, is that both values round to <code class="language-plaintext highlighter-rouge">1.01</code>. What actually happens is that the first one rounds to <code class="language-plaintext highlighter-rouge">1.00</code>, because <code class="language-plaintext highlighter-rouge">1.005</code> as a binary floating-point value is not, in fact, exactly <code class="language-plaintext highlighter-rouge">1.005</code> — it is a hair less than that, by exactly the small amount that binary floating point cannot quite represent the decimal fraction <code class="language-plaintext highlighter-rouge">0.005</code>. When you then ask <code class="language-plaintext highlighter-rouge">BigDecimal</code> to round that approximate value, it dutifully rounds the value it actually has, which falls just below the tie boundary.</p>

<p>If you find yourself, in a finance system, looking at a result in which <code class="language-plaintext highlighter-rouge">1.005</code> appears to round to <code class="language-plaintext highlighter-rouge">1.00</code> under <code class="language-plaintext highlighter-rouge">HALF_UP</code>, the right interpretation is not that Java is being eccentric. The right interpretation is that you have fed an approximate binary representation into an exact decimal rounding routine, and that the routine has, accurately and unhelpfully, given you the answer that corresponds to the value it was actually given.</p>

<h3 id="valueof">What about <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf()</code>?</h3>

<p>There is a third constructor in this space which sits between the two previous options and which readers trip over often enough that it is worth treating explicitly: <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(double)</code>.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">a</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="mf">1.005</span><span class="o">);</span>        <span class="c1">// Dangerous: uses exact binary representation</span>
<span class="nc">BigDecimal</span> <span class="n">b</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="mf">1.005</span><span class="o">);</span>    <span class="c1">// Safer: uses Double.toString() internally</span>
<span class="nc">BigDecimal</span> <span class="n">c</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1.005"</span><span class="o">);</span>      <span class="c1">// Safest: exact decimal from string</span></code></pre></figure>

<p><code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(double)</code> will, in most everyday cases, behave as if you had used the string constructor, because it routes the conversion through <code class="language-plaintext highlighter-rouge">Double.toString()</code> internally — and <code class="language-plaintext highlighter-rouge">Double.toString</code> is specified to return the shortest decimal representation that round-trips back to the same double. So when you start from a literal like <code class="language-plaintext highlighter-rouge">1.005</code>, <code class="language-plaintext highlighter-rouge">valueOf</code> gives you the decimal <code class="language-plaintext highlighter-rouge">1.005</code> rather than the binary-exact value, which is what most callers actually wanted.</p>

<p>A reasonable rule of thumb, based on which entry point one is using:</p>

<ul>
  <li>Use <code class="language-plaintext highlighter-rouge">new BigDecimal("...")</code> for literals and external decimal inputs that arrive as strings</li>
  <li>Use <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(double)</code> only when you already have a double in hand and need the best possible decimal view of it (still risky after computations, but better than <code class="language-plaintext highlighter-rouge">new BigDecimal(double)</code>)</li>
  <li>Never use <code class="language-plaintext highlighter-rouge">new BigDecimal(double)</code> unless you explicitly want the exact binary-to-decimal conversion, which is rarely what callers expect</li>
</ul>

<p>It is worth one further caution. If the double you are wrapping has come out of arithmetic — rather than out of a literal — then the value you are now “viewing” through <code class="language-plaintext highlighter-rouge">valueOf</code> may already be quite far from the decimal you think you started with. <code class="language-plaintext highlighter-rouge">valueOf</code> is an honest decimal view of whatever double it receives; it is not a cleansing ritual that retroactively repairs precision lost earlier in the calculation.</p>

<h2 id="half-up-bias">Why HALF_UP can be the wrong default</h2>

<p><code class="language-plaintext highlighter-rouge">HALF_UP</code> is, in fairness, intuitive. It matches what most of us were taught with a pencil and paper in school, and it has the agreeable property of making the answer easy to predict in any individual case. The trouble is that, when applied repeatedly to many values, it can introduce a systematic <strong>drift</strong>, because every tie is resolved in the same direction.</p>

<p>It is worth pausing for a moment on a small irony of the IEEE 754 standard here. IEEE 754’s default rounding mode for binary floating-point arithmetic is <em>round to nearest, ties to even</em> — which is, in effect, <code class="language-plaintext highlighter-rouge">HALF_EVEN</code>. Each individual <code class="language-plaintext highlighter-rouge">double</code> operation in Java is specified to behave as if its result had been rounded that way. The mild irony, then, is that when developers reach for <code class="language-plaintext highlighter-rouge">BigDecimal</code> precisely because they are now worried about decimal correctness, many of them then choose <code class="language-plaintext highlighter-rouge">HALF_UP</code>, thereby reintroducing the very bias that IEEE 754 had originally been designed to avoid.</p>

<h3 id="bias-demo">Bias demo: HALF_UP vs HALF_EVEN</h3>

<p>Suppose, in order to make this concrete, that you have a population of values which all happen to land exactly on ties at two decimal places. (This kind of thing happens more often than people tend to expect, particularly after divisions and intermediate scaling steps.) The behaviour of the two main candidate rounding modes, side by side, looks like this:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">HALF_UP</code>: <code class="language-plaintext highlighter-rouge">1.005 -&gt; 1.01</code>, <code class="language-plaintext highlighter-rouge">1.015 -&gt; 1.02</code>, <code class="language-plaintext highlighter-rouge">1.025 -&gt; 1.03</code> … always nudging up</li>
  <li><code class="language-plaintext highlighter-rouge">HALF_EVEN</code>: <code class="language-plaintext highlighter-rouge">1.005 -&gt; 1.00</code>, <code class="language-plaintext highlighter-rouge">1.015 -&gt; 1.02</code>, <code class="language-plaintext highlighter-rouge">1.025 -&gt; 1.02</code> … nudging toward whichever side has an even last digit, and so alternating which side “wins” on ties</li>
</ul>

<p>The structural difference is that <code class="language-plaintext highlighter-rouge">HALF_EVEN</code> alternates which direction it pushes ties, while <code class="language-plaintext highlighter-rouge">HALF_UP</code> always pushes them the same way. This is the underlying reason why <strong>banking and accounting systems often prefer <code class="language-plaintext highlighter-rouge">HALF_EVEN</code></strong>: across a large enough population of values, the alternation cancels out into something close to zero net bias, while <code class="language-plaintext highlighter-rouge">HALF_UP</code> accumulates a small but consistent upward drift that becomes visible at scale.</p>

<h3 id="bias-action">The bias in action</h3>

<p>A short program makes the difference clearer than any description does:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kn">import</span> <span class="nn">java.math.BigDecimal</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">java.math.RoundingMode</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">class</span> <span class="nc">BiasDemonstration</span> <span class="o">{</span>
  <span class="kd">public</span> <span class="kd">static</span> <span class="kt">void</span> <span class="nf">main</span><span class="o">(</span><span class="nc">String</span><span class="o">[]</span> <span class="n">args</span><span class="o">)</span> <span class="o">{</span>
    <span class="nc">String</span><span class="o">[]</span> <span class="n">ties</span> <span class="o">=</span> <span class="o">{</span><span class="s">"1.005"</span><span class="o">,</span> <span class="s">"1.015"</span><span class="o">,</span> <span class="s">"1.025"</span><span class="o">,</span> <span class="s">"1.035"</span><span class="o">,</span> <span class="s">"1.045"</span><span class="o">,</span>
                     <span class="s">"1.055"</span><span class="o">,</span> <span class="s">"1.065"</span><span class="o">,</span> <span class="s">"1.075"</span><span class="o">,</span> <span class="s">"1.085"</span><span class="o">,</span> <span class="s">"1.095"</span><span class="o">};</span>
    
    <span class="nc">BigDecimal</span> <span class="n">sumHalfUp</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">ZERO</span><span class="o">;</span>
    <span class="nc">BigDecimal</span> <span class="n">sumHalfEven</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">ZERO</span><span class="o">;</span>
    <span class="nc">BigDecimal</span> <span class="n">trueSum</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">ZERO</span><span class="o">;</span>
    
    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"Value   -&gt; HALF_UP / HALF_EVEN"</span><span class="o">);</span>
    <span class="k">for</span> <span class="o">(</span><span class="nc">String</span> <span class="n">tie</span> <span class="o">:</span> <span class="n">ties</span><span class="o">)</span> <span class="o">{</span>
      <span class="nc">BigDecimal</span> <span class="n">bd</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="n">tie</span><span class="o">);</span>
      <span class="nc">BigDecimal</span> <span class="n">roundedUp</span> <span class="o">=</span> <span class="n">bd</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">);</span>
      <span class="nc">BigDecimal</span> <span class="n">roundedEven</span> <span class="o">=</span> <span class="n">bd</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_EVEN</span><span class="o">);</span>
      
      <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">tie</span> <span class="o">+</span> <span class="s">" -&gt; "</span> <span class="o">+</span> <span class="n">roundedUp</span> <span class="o">+</span> <span class="s">" / "</span> <span class="o">+</span> <span class="n">roundedEven</span><span class="o">);</span>
      
      <span class="n">sumHalfUp</span> <span class="o">=</span> <span class="n">sumHalfUp</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">roundedUp</span><span class="o">);</span>
      <span class="n">sumHalfEven</span> <span class="o">=</span> <span class="n">sumHalfEven</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">roundedEven</span><span class="o">);</span>
      <span class="n">trueSum</span> <span class="o">=</span> <span class="n">trueSum</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">bd</span><span class="o">);</span>
    <span class="o">}</span>
    
    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">();</span>
    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"HALF_UP sum:   "</span> <span class="o">+</span> <span class="n">sumHalfUp</span><span class="o">);</span>
    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"HALF_EVEN sum: "</span> <span class="o">+</span> <span class="n">sumHalfEven</span><span class="o">);</span>
    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"True sum:      "</span> <span class="o">+</span> <span class="n">trueSum</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">));</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>And the resulting output:</p>

<figure class="highlight"><pre><code class="language-plaintext" data-lang="plaintext">Value   -&gt; HALF_UP / HALF_EVEN
1.005 -&gt; 1.01 / 1.00
1.015 -&gt; 1.02 / 1.02
1.025 -&gt; 1.03 / 1.02
1.035 -&gt; 1.04 / 1.04
1.045 -&gt; 1.05 / 1.04
1.055 -&gt; 1.06 / 1.06
1.065 -&gt; 1.07 / 1.06
1.075 -&gt; 1.08 / 1.08
1.085 -&gt; 1.09 / 1.08
1.095 -&gt; 1.10 / 1.10

HALF_UP sum:   10.55
HALF_EVEN sum: 10.50
True sum:      10.50</code></pre></figure>

<p>Across these ten values, the difference between <code class="language-plaintext highlighter-rouge">HALF_UP</code> and the true sum is five cents. That is, on its own, an unimpressive amount of money. The point of the demonstration, however, is that the same bias scales linearly: across millions of transactions of this kind, the same five-cents-per-ten pattern can become a meaningful, persistent, and entirely systematic drift in favour of one party.</p>

<h3 id="pennies-from-heaven">How HALF_UP can favor one party at scale</h3>

<p>When this kind of pattern shows up in a system that processes millions of transactions in which ties are common, what <code class="language-plaintext highlighter-rouge">HALF_UP</code> does, in effect, is to consistently favour whichever side of the transaction benefits from rounding upward. If you happen to be that party, you may, over time, find that your books “win” fractions of a cent more often than they “lose”; and that is, generally, fine — until regulators, auditors, or customers do their own arithmetic and notice the same pattern from the other side.</p>

<p>Which is to say, the question worth asking is not really “which rounding mode is mathematically correct?”, because none of them is uniquely correct in any abstract sense. The right question, as it almost always is in this kind of design choice, is:</p>

<p><strong>Which rounding policy matches the domain contract?</strong></p>

<h2 id="rounding-timing">Rounding is not only <em>mode</em>. It’s also <em>when</em>.</h2>

<p>There is a second axis to this kind of decision, which gets less attention than it deserves but which often matters at least as much as the choice of mode itself. The axis is <em>when</em> in a calculation rounding actually happens. Two broad designs are common in production code:</p>

<ol>
  <li>Round at every step (easy, often wrong)</li>
  <li>Keep high precision internally, round only at boundaries (harder, usually right)</li>
</ol>

<h3 id="invoices">Example: line items and invoices</h3>

<p>To make the trade-off concrete, consider a fairly standard invoicing setup:</p>

<ul>
  <li>Price per item carries four decimal places of precision</li>
  <li>The currency, for display and settlement, is two decimals</li>
  <li>Taxes are computed on totals rather than per-line-item (which is the more common convention)</li>
</ul>

<p>If rounding happens too early in this kind of calculation, the invoice total can end up disagreeing with what the underlying ledger says it ought to be. The four candidate policies, in this small space, are:</p>

<ul>
  <li>Round each line item to two decimals, then sum the rounded values</li>
  <li>Sum the unrounded line items at full precision, then round once at the total</li>
  <li>Compute tax per line item and then sum the taxes</li>
  <li>Compute tax once on the total, then round the tax once</li>
</ul>

<p>All four of these are, in some sense, “reasonable”, and none of them is wrong in the abstract. Only one of them, however, will actually agree with the rules your business has adopted, and the only way to make sure you have picked the right one is to choose explicitly, document the choice somewhere where it can be referred to later, and write tests that pin the chosen behaviour in place.</p>

<h2 id="money-pattern">A practical Java pattern: Money as scaled integer</h2>

<p>For currency in particular, the simplest representation that is also genuinely correct in most cases is, in my experience, to store amounts as integer minor units — long-typed cents, in the case of a US-style currency — to do all of the internal arithmetic in integers, and to convert back to a decimal representation only at the boundaries where the value is being displayed or transmitted. This pattern avoids a great deal of <code class="language-plaintext highlighter-rouge">BigDecimal</code> overhead, and it eliminates the entire class of bug that arises from rounding the same value twice in slightly different ways during a calculation.</p>

<h3 id="money-type">Simple Money type (cents)</h3>

<p>A reasonable starting point looks something like this:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kn">import</span> <span class="nn">java.math.BigDecimal</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">java.math.RoundingMode</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">final</span> <span class="kd">class</span> <span class="nc">Money</span> <span class="o">{</span>
  <span class="kd">private</span> <span class="kd">final</span> <span class="kt">long</span> <span class="n">cents</span><span class="o">;</span>

  <span class="kd">private</span> <span class="nf">Money</span><span class="o">(</span><span class="kt">long</span> <span class="n">cents</span><span class="o">)</span> <span class="o">{</span> <span class="k">this</span><span class="o">.</span><span class="na">cents</span> <span class="o">=</span> <span class="n">cents</span><span class="o">;</span> <span class="o">}</span>

  <span class="kd">public</span> <span class="kd">static</span> <span class="nc">Money</span> <span class="nf">ofDollars</span><span class="o">(</span><span class="nc">String</span> <span class="n">amount</span><span class="o">)</span> <span class="o">{</span>
    <span class="c1">// Parse exact decimal dollars, then scale to cents.</span>
    <span class="c1">// This version rounds permissively; see ofDollarsStrict for validation.</span>
    <span class="nc">BigDecimal</span> <span class="n">bd</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="n">amount</span><span class="o">).</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_EVEN</span><span class="o">);</span>
    <span class="k">return</span> <span class="k">new</span> <span class="nf">Money</span><span class="o">(</span><span class="n">bd</span><span class="o">.</span><span class="na">movePointRight</span><span class="o">(</span><span class="mi">2</span><span class="o">).</span><span class="na">longValueExact</span><span class="o">());</span>
  <span class="o">}</span>

  <span class="cm">/**
   * Strict version: reject inputs that aren't exactly 2 decimals.
   * @throws ArithmeticException if rounding would be required
   */</span>
  <span class="kd">public</span> <span class="kd">static</span> <span class="nc">Money</span> <span class="nf">ofDollarsStrict</span><span class="o">(</span><span class="nc">String</span> <span class="n">amount</span><span class="o">)</span> <span class="o">{</span>
    <span class="nc">BigDecimal</span> <span class="n">bd</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="n">amount</span><span class="o">).</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">UNNECESSARY</span><span class="o">);</span>
    <span class="k">return</span> <span class="k">new</span> <span class="nf">Money</span><span class="o">(</span><span class="n">bd</span><span class="o">.</span><span class="na">movePointRight</span><span class="o">(</span><span class="mi">2</span><span class="o">).</span><span class="na">longValueExact</span><span class="o">());</span>
  <span class="o">}</span>

  <span class="kd">public</span> <span class="nc">Money</span> <span class="nf">plus</span><span class="o">(</span><span class="nc">Money</span> <span class="n">other</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">return</span> <span class="k">new</span> <span class="nf">Money</span><span class="o">(</span><span class="nc">Math</span><span class="o">.</span><span class="na">addExact</span><span class="o">(</span><span class="k">this</span><span class="o">.</span><span class="na">cents</span><span class="o">,</span> <span class="n">other</span><span class="o">.</span><span class="na">cents</span><span class="o">));</span>
  <span class="o">}</span>

  <span class="cm">/**
   * Multiply by a factor with explicit rounding policy.
   * Notice we round only at the boundary where we return to cents.
   * In production, consider taking a BigDecimal factor to avoid parsing repeatedly.
   */</span>
  <span class="kd">public</span> <span class="nc">Money</span> <span class="nf">times</span><span class="o">(</span><span class="nc">String</span> <span class="n">factor</span><span class="o">,</span> <span class="nc">RoundingMode</span> <span class="n">mode</span><span class="o">)</span> <span class="o">{</span>
    <span class="nc">BigDecimal</span> <span class="n">bd</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="n">cents</span><span class="o">)</span>
        <span class="o">.</span><span class="na">movePointLeft</span><span class="o">(</span><span class="mi">2</span><span class="o">)</span>
        <span class="o">.</span><span class="na">multiply</span><span class="o">(</span><span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="n">factor</span><span class="o">))</span>
        <span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="n">mode</span><span class="o">);</span>
    <span class="k">return</span> <span class="k">new</span> <span class="nf">Money</span><span class="o">(</span><span class="n">bd</span><span class="o">.</span><span class="na">movePointRight</span><span class="o">(</span><span class="mi">2</span><span class="o">).</span><span class="na">longValueExact</span><span class="o">());</span>
  <span class="o">}</span>

  <span class="kd">public</span> <span class="nc">BigDecimal</span> <span class="nf">toBigDecimal</span><span class="o">()</span> <span class="o">{</span>
    <span class="k">return</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="n">cents</span><span class="o">).</span><span class="na">movePointLeft</span><span class="o">(</span><span class="mi">2</span><span class="o">);</span>
  <span class="o">}</span>

  <span class="nd">@Override</span>
  <span class="kd">public</span> <span class="nc">String</span> <span class="nf">toString</span><span class="o">()</span> <span class="o">{</span> <span class="k">return</span> <span class="n">toBigDecimal</span><span class="o">().</span><span class="na">toPlainString</span><span class="o">();</span> <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>The pattern at work in this small class is, I think, worth pulling out explicitly. Inputs are parsed from strings rather than from doubles; the scaling is always explicit; the rounding mode is a parameter at any point that policy has to be applied; and the internal representation is integer cents rather than <code class="language-plaintext highlighter-rouge">BigDecimal</code>. The code is a little longer than the obvious naive version would have been, but each of those choices removes a class of bug rather than papering over one.</p>

<p>There is one design choice in <code class="language-plaintext highlighter-rouge">ofDollars</code> worth calling out explicitly: it silently rounds inputs like <code class="language-plaintext highlighter-rouge">"10.129"</code> to <code class="language-plaintext highlighter-rouge">"10.13"</code>. That is sometimes exactly what is wanted — for display amounts, for instance, where the upstream code has already validated the value — but for payments and ledgers it is often safer to use <code class="language-plaintext highlighter-rouge">ofDollarsStrict</code> instead, which simply rejects any input that is not already at exactly two decimals. The strict version forces validation to happen at the point where the value enters the system, rather than letting an off-scale value drift in and quietly become representable.</p>

<p>For multi-currency systems, the natural extension is to add a <code class="language-plaintext highlighter-rouge">Currency</code> field to the type and to ensure that arithmetic across different currencies is rejected outright. The core pattern, however, stays the same: integer minor units internally, with rounding occurring only at clearly identified boundaries.</p>

<h2 id="field-guide">Quick guide: what each rounding mode is “for”</h2>

<p>The following is a field guide rather than a strict ruleset; the right answer in any given system is always whichever mode matches the domain contract, but these are the rough shapes of cases I have run into often enough to recommend by default.</p>

<h3 id="use-half-even">Use HALF_EVEN when…</h3>

<p>You are aggregating a large number of rounded values and you want to minimise systematic bias in the aggregate. This is the right default for most accounting ledgers, for interest accrual across many accounts, and for any large-scale reporting in which the total over many ties is what matters more than the result of any individual rounding step.</p>

<h3 id="use-half-up">Use HALF_UP when…</h3>

<p>The domain explicitly expects “schoolbook” rounding — the kind of rounding most people learned in primary school, where 0.5 always rounds up. This is appropriate for retail display prices, for some tax jurisdictions in which the rule is set by statute, and for human-facing calculations where the convention is part of the user experience and surprising the user with banker’s rounding would, on balance, do more harm than the bias it would prevent.</p>

<h3 id="use-down">Use DOWN when…</h3>

<p>Truncation is explicitly what the policy requires — typically in fee calculations or in conservative estimates where the rule is something like “we may not exceed this cap under any circumstances,” and where rounding in the more usual direction could produce an out-of-bounds value.</p>

<h3 id="use-ceiling-floor">Use CEILING or FLOOR when…</h3>

<p>These differ from <code class="language-plaintext highlighter-rouge">UP</code> and <code class="language-plaintext highlighter-rouge">DOWN</code> in that the direction is interpreted relative to the number line, rather than relative to zero, which makes them the right choice when sign matters:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">CEILING</code> is “toward positive infinity” (-1.231 -&gt; -1.23, 1.231 -&gt; 1.24 at 2dp)</li>
  <li><code class="language-plaintext highlighter-rouge">FLOOR</code> is “toward negative infinity” (-1.231 -&gt; -1.24, 1.231 -&gt; 1.23 at 2dp)</li>
</ul>

<p>These tend to be the right choice for constraints, limits, and compliance rules of the form “must be at least X” or “must be at most Y”.</p>

<h3 id="use-unnecessary">Use UNNECESSARY when…</h3>

<p>You want the program to fail loudly the instant it encounters a value that you did not expect to need rounding. This sounds, when written down, like an irritation; in my experience it is, in fact, an enormously useful debugging and validation aid:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">subtotal</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"12.34"</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">rate</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"0.075"</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">tax</span> <span class="o">=</span> <span class="n">subtotal</span><span class="o">.</span><span class="na">multiply</span><span class="o">(</span><span class="n">rate</span><span class="o">);</span>

<span class="c1">// Fail fast if tax isn't exactly representable at 2 decimals as required by policy</span>
<span class="n">tax</span> <span class="o">=</span> <span class="n">tax</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">UNNECESSARY</span><span class="o">);</span></code></pre></figure>

<p>The exception thrown by <code class="language-plaintext highlighter-rouge">UNNECESSARY</code> is not, in this kind of usage, a nuisance to be caught and ignored. It is a spotlight that the runtime is shining on an assumption you had forgotten you were making, and being told about that assumption explicitly is almost always more useful than letting it quietly produce a slightly wrong answer further downstream.</p>

<h2 id="moral">The moral of the story</h2>

<p><code class="language-plaintext highlighter-rouge">HALF_UP</code>, in summary, is not really wrong; it is simply not universal. Rounding modes, taken together, are not “implementation details” of any kind. They are product decisions, made of policy rather than mathematics, and they need to be picked the way that any other policy is picked — explicitly, with tests, and with a paper trail that lets future readers understand why a particular choice was made and what would have to change for the choice to be revisited.</p>

<h2 id="tldr">TL;DR</h2>

<ul>
  <li>Ties (first discarded digit is 5, rest are zeros) are where rounding policy matters most.</li>
  <li><code class="language-plaintext highlighter-rouge">HALF_UP</code> is intuitive but can introduce bias at scale.</li>
  <li><code class="language-plaintext highlighter-rouge">HALF_EVEN</code> often reduces bias for aggregates.</li>
  <li>Avoid rounding <code class="language-plaintext highlighter-rouge">double</code> values when policy matters. Use <code class="language-plaintext highlighter-rouge">BigDecimal</code> created from strings or scaled integers.</li>
  <li>Prefer <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(double)</code> over <code class="language-plaintext highlighter-rouge">new BigDecimal(double)</code> when you must start from a double - but remember it’s not a cleansing ritual.</li>
  <li>Decide <em>when</em> you round, not just <em>how</em> you round.</li>
  <li>Prefer rounding once at boundaries, not repeatedly in the middle.</li>
  <li>Use <code class="language-plaintext highlighter-rouge">UNNECESSARY</code> to catch “we assumed this would be exact” bugs early.</li>
</ul>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Computer Science" /><category term="Software Engineering" /><category term="Technology" /><category term="Series 4 - Floating Point Without Tears" /><category term="java" /><category term="floating-point" /><category term="bigdecimal" /><category term="rounding" /><category term="finance" /><category term="numerics" /><summary type="html"><![CDATA[Learn why HALF_UP rounding isn't always correct and how to choose a rounding policy in Java (HALF_EVEN, HALF_UP, HALF_DOWN, UP, DOWN, CEILING, FLOOR, UNNECESSARY).]]></summary></entry><entry><title type="html">Part 7: Kahan Summation - A Better sum() for Java Streams</title><link href="https://systemhalted.in/2026/01/11/kahan-summation-java-streams/" rel="alternate" type="text/html" title="Part 7: Kahan Summation - A Better sum() for Java Streams" /><published>2026-01-11T00:00:00+00:00</published><updated>2026-01-11T00:00:00+00:00</updated><id>https://systemhalted.in/2026/01/11/kahan-summation-java-streams</id><content type="html" xml:base="https://systemhalted.in/2026/01/11/kahan-summation-java-streams/"><![CDATA[<p><em>This post is part of my <a href="https://systemhalted.in/categories/#cat-series-4-floating-point-without-tears">Floating Point Without Tears</a> series on how Java numbers misbehave and how to live with them.</em></p>

<p>In <a href="https://systemhalted.in/2026/01/05/defending-against-nan-without-defensive-programming-hell/">Part 6</a> of this series, we looked at how to defend against NaN by validating values at boundaries rather than scattering checks throughout the code. This post is about a different and, in its own way, sneakier kind of failure mode in floating-point arithmetic — the case where your sum is computed correctly at every individual step, every individual operation does exactly what the standard says it should, and the final answer is still meaningfully wrong.</p>

<hr />

<p>There is a quiet bug that hides inside almost every large numerical reduction in production code, and it has, in my experience, almost nothing to do with mistakes in logic and almost everything to do with how floating-point addition is forced to behave. Floating point has fixed precision: every addition rounds back to a fixed number of significant digits, and the bits that do not fit are discarded. Most of the time, the discarded bits are too small to matter. Some of the time — particularly when you add a large number of values together, or when the values you are adding span many orders of magnitude — the cumulative effect of those tiny dropped bits becomes large enough to be visible in the answer.</p>

<p>This post is about the full story of <strong>Kahan summation</strong>, which is a small algorithmic trick with a surprisingly large impact on this kind of error. Kahan summation does not, and cannot, make floating-point arithmetic exact; what it does is keep your running totals from quietly losing meaningful contributions when you add many numbers, by tracking the bits that rounding has thrown away and folding them back into the next operation.</p>

<h2 id="the-innocent-looking-loop">The innocent-looking loop</h2>

<p>The classic numerical-analysis textbook example for this kind of error is, for historical reasons, usually written in Fortran — it is the lingua franca of mid-twentieth-century numerics — and it looks innocuous enough that it is easy to read past it without realising what it is about to do.</p>

<figure class="highlight"><pre><code class="language-fortran" data-lang="fortran"><span class="n">S</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="mf">0.0</span><span class="w">
</span><span class="k">DO</span><span class="w"> </span><span class="mi">4</span><span class="w"> </span><span class="n">I</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="mi">1</span><span class="p">,</span><span class="w"> </span><span class="n">N</span><span class="w">
  </span><span class="n">YI</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="err">...</span><span class="w">
</span><span class="nl">4</span><span class="w"> </span><span class="n">S</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">S</span><span class="w"> </span><span class="o">+</span><span class="w"> </span><span class="n">YI</span></code></pre></figure>

<p>The whole drama, such as it is, lives in the last line: <code class="language-plaintext highlighter-rouge">S = S + YI</code>. People then drop in a line that, at first reading, sounds slightly mystical:</p>

<blockquote>
  <p>Rounding or truncation in the addition can contribute to a loss of almost $\log_{10}(N)$ significant decimal digits in S.</p>
</blockquote>

<p>The $\log_{10}(N)$ in that sentence does not, however, come from any sort of wizardry. It is simply what happens when fixed precision collides with a running total that keeps growing — the floating-point grid on which the running total can land gets coarser as the total gets larger, and so the smallest things you are still trying to add to it get progressively harder to see.</p>

<h2 id="why-you-can-lose-about-log10n-digits">Why you can lose about log10(N) digits</h2>

<p>Suppose, for the sake of intuition, that we are working in base-10 floating point with <strong>p significant decimal digits</strong>. (IEEE 754 is base 2, but the intuition transfers cleanly enough that working in base 10 is worth it for the explanation.) Suppose further that the <code class="language-plaintext highlighter-rouge">YI</code> values are roughly the same size and mostly the same sign, so that the partial sums genuinely grow rather than cancelling each other out, and let <code class="language-plaintext highlighter-rouge">|Y|</code> denote a typical magnitude.</p>

<p>After <code class="language-plaintext highlighter-rouge">N</code> terms, then, the true sum is roughly:</p>

<span class="katex-display"><span class="katex"><span class="katex-mathml"><math xmlns="http://www.w3.org/1998/Math/MathML" display="block"><semantics><mrow><msub><mi>S</mi><mtext>true</mtext></msub><mo>≈</mo><mi>N</mi><mo>⋅</mo><mi>Y</mi></mrow><annotation encoding="application/x-tex">S_{\text{true}} \approx N \cdot Y</annotation></semantics></math></span><span class="katex-html" aria-hidden="true"><span class="base"><span class="strut" style="height:0.8333em;vertical-align:-0.15em;"></span><span class="mord"><span class="mord mathnormal" style="margin-right:0.05764em;">S</span><span class="msupsub"><span class="vlist-t vlist-t2"><span class="vlist-r"><span class="vlist" style="height:0.2806em;"><span style="top:-2.55em;margin-left:-0.0576em;margin-right:0.05em;"><span class="pstrut" style="height:2.7em;"></span><span class="sizing reset-size6 size3 mtight"><span class="mord mtight"><span class="mord text mtight"><span class="mord mtight">true</span></span></span></span></span></span><span class="vlist-s">​</span></span><span class="vlist-r"><span class="vlist" style="height:0.15em;"><span></span></span></span></span></span></span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">≈</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:0.6833em;"></span><span class="mord mathnormal" style="margin-right:0.10903em;">N</span><span class="mspace" style="margin-right:0.2222em;"></span><span class="mbin">⋅</span><span class="mspace" style="margin-right:0.2222em;"></span></span><span class="base"><span class="strut" style="height:0.6833em;"></span><span class="mord mathnormal" style="margin-right:0.22222em;">Y</span></span></span></span></span>

<p>And here is the key floating-point constraint to keep in mind: a <code class="language-plaintext highlighter-rouge">p</code>-digit floating number around magnitude <code class="language-plaintext highlighter-rouge">|S|</code> cannot represent arbitrarily small changes. Near <code class="language-plaintext highlighter-rouge">S</code>, the spacing between representable values is approximately:</p>

<span class="katex-display"><span class="katex"><span class="katex-mathml"><math xmlns="http://www.w3.org/1998/Math/MathML" display="block"><semantics><mrow><mi mathvariant="normal">Δ</mi><mi>S</mi><mo>≈</mo><mi mathvariant="normal">∣</mi><mi>S</mi><mi mathvariant="normal">∣</mi><mo>⋅</mo><mn>1</mn><msup><mn>0</mn><mrow><mo>−</mo><mi>p</mi></mrow></msup></mrow><annotation encoding="application/x-tex">\Delta S \approx |S| \cdot 10^{-p}</annotation></semantics></math></span><span class="katex-html" aria-hidden="true"><span class="base"><span class="strut" style="height:0.6833em;"></span><span class="mord">Δ</span><span class="mord mathnormal" style="margin-right:0.05764em;">S</span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">≈</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:1em;vertical-align:-0.25em;"></span><span class="mord">∣</span><span class="mord mathnormal" style="margin-right:0.05764em;">S</span><span class="mord">∣</span><span class="mspace" style="margin-right:0.2222em;"></span><span class="mbin">⋅</span><span class="mspace" style="margin-right:0.2222em;"></span></span><span class="base"><span class="strut" style="height:0.8213em;"></span><span class="mord">1</span><span class="mord"><span class="mord">0</span><span class="msupsub"><span class="vlist-t"><span class="vlist-r"><span class="vlist" style="height:0.8213em;"><span style="top:-3.113em;margin-right:0.05em;"><span class="pstrut" style="height:2.7em;"></span><span class="sizing reset-size6 size3 mtight"><span class="mord mtight"><span class="mord mtight">−</span><span class="mord mathnormal mtight">p</span></span></span></span></span></span></span></span></span></span></span></span></span>

<p>It helps to think of $\Delta S$ as the width of the grid lines at the altitude where <code class="language-plaintext highlighter-rouge">S</code> happens to live. When you compute <code class="language-plaintext highlighter-rouge">S = S + YI</code>, the result is rounded back onto that grid, and any increment that is much smaller than $\Delta S$ at that altitude can simply vanish, because there is no representable value between <code class="language-plaintext highlighter-rouge">S</code> and <code class="language-plaintext highlighter-rouge">S + YI</code> in the new precision regime.</p>

<p>By the end of the loop, <code class="language-plaintext highlighter-rouge">|S| \approx N|Y|</code>, so the grid spacing near the final sum is:</p>

<span class="katex-display"><span class="katex"><span class="katex-mathml"><math xmlns="http://www.w3.org/1998/Math/MathML" display="block"><semantics><mrow><mi mathvariant="normal">Δ</mi><mi>S</mi><mo>≈</mo><mo stretchy="false">(</mo><mi>N</mi><mi mathvariant="normal">∣</mi><mi>Y</mi><mi mathvariant="normal">∣</mi><mo stretchy="false">)</mo><mtext> </mtext><mn>1</mn><msup><mn>0</mn><mrow><mo>−</mo><mi>p</mi></mrow></msup></mrow><annotation encoding="application/x-tex">\Delta S \approx (N|Y|)\,10^{-p}</annotation></semantics></math></span><span class="katex-html" aria-hidden="true"><span class="base"><span class="strut" style="height:0.6833em;"></span><span class="mord">Δ</span><span class="mord mathnormal" style="margin-right:0.05764em;">S</span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">≈</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:1.0713em;vertical-align:-0.25em;"></span><span class="mopen">(</span><span class="mord mathnormal" style="margin-right:0.10903em;">N</span><span class="mord">∣</span><span class="mord mathnormal" style="margin-right:0.22222em;">Y</span><span class="mord">∣</span><span class="mclose">)</span><span class="mspace" style="margin-right:0.1667em;"></span><span class="mord">1</span><span class="mord"><span class="mord">0</span><span class="msupsub"><span class="vlist-t"><span class="vlist-r"><span class="vlist" style="height:0.8213em;"><span style="top:-3.113em;margin-right:0.05em;"><span class="pstrut" style="height:2.7em;"></span><span class="sizing reset-size6 size3 mtight"><span class="mord mtight"><span class="mord mtight">−</span><span class="mord mathnormal mtight">p</span></span></span></span></span></span></span></span></span></span></span></span></span>

<p>Comparing the grid spacing to the size of a typical addend gives:</p>

<span class="katex-display"><span class="katex"><span class="katex-mathml"><math xmlns="http://www.w3.org/1998/Math/MathML" display="block"><semantics><mrow><mfrac><mrow><mi mathvariant="normal">Δ</mi><mi>S</mi></mrow><mrow><mi mathvariant="normal">∣</mi><mi>Y</mi><mi mathvariant="normal">∣</mi></mrow></mfrac><mo>≈</mo><mi>N</mi><mo>⋅</mo><mn>1</mn><msup><mn>0</mn><mrow><mo>−</mo><mi>p</mi></mrow></msup><mo>=</mo><mn>1</mn><msup><mn>0</mn><mrow><msub><mrow><mi>log</mi><mo>⁡</mo></mrow><mn>10</mn></msub><mi>N</mi><mo>−</mo><mi>p</mi></mrow></msup></mrow><annotation encoding="application/x-tex">\frac{\Delta S}{|Y|} \approx N \cdot 10^{-p} = 10^{\log_{10}N - p}</annotation></semantics></math></span><span class="katex-html" aria-hidden="true"><span class="base"><span class="strut" style="height:2.2963em;vertical-align:-0.936em;"></span><span class="mord"><span class="mopen nulldelimiter"></span><span class="mfrac"><span class="vlist-t vlist-t2"><span class="vlist-r"><span class="vlist" style="height:1.3603em;"><span style="top:-2.314em;"><span class="pstrut" style="height:3em;"></span><span class="mord"><span class="mord">∣</span><span class="mord mathnormal" style="margin-right:0.22222em;">Y</span><span class="mord">∣</span></span></span><span style="top:-3.23em;"><span class="pstrut" style="height:3em;"></span><span class="frac-line" style="border-bottom-width:0.04em;"></span></span><span style="top:-3.677em;"><span class="pstrut" style="height:3em;"></span><span class="mord"><span class="mord">Δ</span><span class="mord mathnormal" style="margin-right:0.05764em;">S</span></span></span></span><span class="vlist-s">​</span></span><span class="vlist-r"><span class="vlist" style="height:0.936em;"><span></span></span></span></span></span><span class="mclose nulldelimiter"></span></span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">≈</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:0.6833em;"></span><span class="mord mathnormal" style="margin-right:0.10903em;">N</span><span class="mspace" style="margin-right:0.2222em;"></span><span class="mbin">⋅</span><span class="mspace" style="margin-right:0.2222em;"></span></span><span class="base"><span class="strut" style="height:0.8213em;"></span><span class="mord">1</span><span class="mord"><span class="mord">0</span><span class="msupsub"><span class="vlist-t"><span class="vlist-r"><span class="vlist" style="height:0.8213em;"><span style="top:-3.113em;margin-right:0.05em;"><span class="pstrut" style="height:2.7em;"></span><span class="sizing reset-size6 size3 mtight"><span class="mord mtight"><span class="mord mtight">−</span><span class="mord mathnormal mtight">p</span></span></span></span></span></span></span></span></span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">=</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:0.8991em;"></span><span class="mord">1</span><span class="mord"><span class="mord">0</span><span class="msupsub"><span class="vlist-t"><span class="vlist-r"><span class="vlist" style="height:0.8991em;"><span style="top:-3.113em;margin-right:0.05em;"><span class="pstrut" style="height:2.7em;"></span><span class="sizing reset-size6 size3 mtight"><span class="mord mtight"><span class="mop mtight"><span class="mop mtight"><span class="mtight">l</span><span class="mtight">o</span><span class="mtight" style="margin-right:0.01389em;">g</span></span><span class="msupsub"><span class="vlist-t vlist-t2"><span class="vlist-r"><span class="vlist" style="height:0.1944em;"><span style="top:-2.2341em;margin-right:0.0714em;"><span class="pstrut" style="height:2.5em;"></span><span class="sizing reset-size3 size1 mtight"><span class="mord mtight"><span class="mord mtight">10</span></span></span></span></span><span class="vlist-s">​</span></span><span class="vlist-r"><span class="vlist" style="height:0.2659em;"><span></span></span></span></span></span></span><span class="mspace mtight" style="margin-right:0.1952em;"></span><span class="mord mathnormal mtight" style="margin-right:0.10903em;">N</span><span class="mbin mtight">−</span><span class="mord mathnormal mtight">p</span></span></span></span></span></span></span></span></span></span></span></span></span>

<p>That ratio, in the end, is what the textbooks are getting at. Multiplying by <code class="language-plaintext highlighter-rouge">N</code> shifts magnitudes by $\log_{10}(N)$ decimal digits, which means that as the running sum grows by a factor of <code class="language-plaintext highlighter-rouge">N</code>, the rounding grid spacing grows by exactly the same factor. Relative to the scale of the things you are still trying to add, you have therefore effectively lost about $\log_{10}(N)$ digits of useful precision. Another way to say the same thing is:</p>

<span class="katex-display"><span class="katex"><span class="katex-mathml"><math xmlns="http://www.w3.org/1998/Math/MathML" display="block"><semantics><mrow><mtext>useful digits left at the addend scale</mtext><mo>≈</mo><mi>p</mi><mo>−</mo><msub><mrow><mi>log</mi><mo>⁡</mo></mrow><mn>10</mn></msub><mi>N</mi></mrow><annotation encoding="application/x-tex">\text{useful digits left at the addend scale} \approx p - \log_{10}N</annotation></semantics></math></span><span class="katex-html" aria-hidden="true"><span class="base"><span class="strut" style="height:0.8889em;vertical-align:-0.1944em;"></span><span class="mord text"><span class="mord">useful digits left at the addend scale</span></span><span class="mspace" style="margin-right:0.2778em;"></span><span class="mrel">≈</span><span class="mspace" style="margin-right:0.2778em;"></span></span><span class="base"><span class="strut" style="height:0.7778em;vertical-align:-0.1944em;"></span><span class="mord mathnormal">p</span><span class="mspace" style="margin-right:0.2222em;"></span><span class="mbin">−</span><span class="mspace" style="margin-right:0.2222em;"></span></span><span class="base"><span class="strut" style="height:0.9386em;vertical-align:-0.2441em;"></span><span class="mop"><span class="mop">lo<span style="margin-right:0.01389em;">g</span></span><span class="msupsub"><span class="vlist-t vlist-t2"><span class="vlist-r"><span class="vlist" style="height:0.207em;"><span style="top:-2.4559em;margin-right:0.05em;"><span class="pstrut" style="height:2.7em;"></span><span class="sizing reset-size6 size3 mtight"><span class="mord mtight"><span class="mord mtight">10</span></span></span></span></span><span class="vlist-s">​</span></span><span class="vlist-r"><span class="vlist" style="height:0.2441em;"><span></span></span></span></span></span></span><span class="mspace" style="margin-right:0.1667em;"></span><span class="mord mathnormal" style="margin-right:0.10903em;">N</span></span></span></span></span>

<h3 id="a-concrete-gut-punch">A concrete gut punch</h3>

<p>Suppose, to make this less abstract, that you are working with about <code class="language-plaintext highlighter-rouge">p = 7</code> significant decimal digits — roughly single-precision territory — and you sum <code class="language-plaintext highlighter-rouge">N = 10^6</code> numbers, each of size about 1.</p>

<p>$\log_{10}(10^6) = 6$</p>

<p>Which leaves you with roughly:</p>

<p>$7 - 6 = 1$ meaningful decimal digit at the scale of 1</p>

<p>By the time <code class="language-plaintext highlighter-rouge">S</code> reaches around one million, the grid spacing near <code class="language-plaintext highlighter-rouge">S</code> is roughly:</p>

<p>$10^6 \cdot 10^{-7} = 10^{-1} = 0.1$</p>

<p>So adding <code class="language-plaintext highlighter-rouge">0.01</code> to <code class="language-plaintext highlighter-rouge">S</code> at that point can literally do nothing at all — the increment is smaller than the grid spacing in the precision regime where the running total currently lives, and it gets rounded away. The problem, in other words, is not really the single rounding step; it is the cumulative effect of rounding many million times while the running total continues to inflate.</p>

<h2 id="a-quick-demo-sums-that-look-reasonable-and-are-still-wrong">A quick demo: sums that look reasonable and are still wrong</h2>

<p>Here is a small example of the same kind of cancellation, in Java this time:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">x</span> <span class="o">=</span> <span class="mi">1</span><span class="n">e16</span><span class="o">;</span>
<span class="kt">double</span> <span class="n">naive</span> <span class="o">=</span> <span class="o">(</span><span class="n">x</span> <span class="o">+</span> <span class="mf">1.0</span><span class="o">)</span> <span class="o">+</span> <span class="mf">1.0</span> <span class="o">-</span> <span class="n">x</span><span class="o">;</span>   <span class="c1">// commonly prints 0.0</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">naive</span><span class="o">);</span></code></pre></figure>

<p>The two <code class="language-plaintext highlighter-rouge">+ 1.0</code> additions in this expression happen while the running value is around <code class="language-plaintext highlighter-rouge">1e16</code>, and at that scale <code class="language-plaintext highlighter-rouge">1.0</code> is, in fact, smaller than the spacing between representable doubles. The two ones, therefore, fall through the cracks of the grid entirely, and the answer that arrives back is <code class="language-plaintext highlighter-rouge">0.0</code> rather than the <code class="language-plaintext highlighter-rouge">2.0</code> that ordinary arithmetic would have produced.</p>

<p>This is, importantly, not a curious corner case that only shows up in exam questions. If your system does any kind of analytics, pricing, telemetry, risk computation, recommendations, or ranking — anything where <code class="language-plaintext highlighter-rouge">N</code> becomes large in routine operation — this kind of error is the default failure mode hiding inside what looks like a perfectly innocent reduction.</p>

<h2 id="kahan-summation-track-what-gets-dropped">Kahan summation: track what gets dropped</h2>

<p>Kahan summation is, in technical terms, an instance of <strong>compensated summation</strong>. The idea is to keep two running numbers instead of one:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">sum</code>: the running total, the way you would normally maintain it</li>
  <li><code class="language-plaintext highlighter-rouge">c</code>: a compensation term that records what rounding threw away on the previous addition</li>
</ul>

<p>The first holds the running total at full machine precision; the second holds an estimate of the low-order bits that were lost on the most recent addition, so that those lost bits can be folded back into the next addition rather than disappearing forever.</p>

<h3 id="the-algorithm">The algorithm</h3>

<p>Given a new addend <code class="language-plaintext highlighter-rouge">x</code>, the algorithm performs three steps in sequence: it adjusts the addend by what was lost on the previous step, it adds the adjusted addend to the running total, and it then estimates how much was lost on this step and stores that estimate as the new compensation.</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">y = x - c
t = sum + y
c = (t - sum) - y
sum = t</code></pre></figure>

<p>That, taken on its own terms, is the whole trick. It does not change the underlying floating-point rules — additions are still rounded, the precision is still finite — but it changes the way you accumulate so that the rules hurt you less, by keeping a small ledger of what they have already cost you and applying it as a correction on the next operation.</p>

<h2 id="java-implementation-a-small-accumulator-with-big-consequences">Java implementation: a small accumulator with big consequences</h2>

<h3 id="the-accumulator-type">The accumulator type</h3>

<p>A reasonable Java implementation of the algorithm above is a small accumulator object that exposes the operations one would expect of any reduction primitive — adding a single value, combining with another instance of itself, and producing a final result.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">public</span> <span class="kd">final</span> <span class="kd">class</span> <span class="nc">KahanAccumulator</span> <span class="o">{</span>
  <span class="kd">private</span> <span class="kt">double</span> <span class="n">sum</span><span class="o">;</span>
  <span class="kd">private</span> <span class="kt">double</span> <span class="n">c</span><span class="o">;</span> <span class="c1">// compensation for lost low-order bits</span>

  <span class="kd">public</span> <span class="kt">void</span> <span class="nf">add</span><span class="o">(</span><span class="kt">double</span> <span class="n">x</span><span class="o">)</span> <span class="o">{</span>
    <span class="kt">double</span> <span class="n">y</span> <span class="o">=</span> <span class="n">x</span> <span class="o">-</span> <span class="n">c</span><span class="o">;</span>
    <span class="kt">double</span> <span class="n">t</span> <span class="o">=</span> <span class="n">sum</span> <span class="o">+</span> <span class="n">y</span><span class="o">;</span>
    <span class="n">c</span> <span class="o">=</span> <span class="o">(</span><span class="n">t</span> <span class="o">-</span> <span class="n">sum</span><span class="o">)</span> <span class="o">-</span> <span class="n">y</span><span class="o">;</span>
    <span class="n">sum</span> <span class="o">=</span> <span class="n">t</span><span class="o">;</span>
  <span class="o">}</span>

  <span class="kd">public</span> <span class="kt">void</span> <span class="nf">combine</span><span class="o">(</span><span class="nc">KahanAccumulator</span> <span class="n">other</span><span class="o">)</span> <span class="o">{</span>
    <span class="c1">// Merge another partial sum into this one.</span>
    <span class="c1">// This improves accuracy, but the result is still order-dependent.</span>
    <span class="k">this</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">other</span><span class="o">.</span><span class="na">sum</span><span class="o">);</span>
    <span class="k">this</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">other</span><span class="o">.</span><span class="na">c</span><span class="o">);</span>
  <span class="o">}</span>

  <span class="kd">public</span> <span class="kt">double</span> <span class="nf">value</span><span class="o">()</span> <span class="o">{</span>
    <span class="k">return</span> <span class="n">sum</span><span class="o">;</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>One thing worth saying clearly here, before anyone is tempted to oversell what Kahan summation buys: Kahan improves accuracy substantially, but <strong>floating-point addition is still not associative</strong>, which means that parallel reductions running over the same data can still produce different totals from one run to the next, simply because the order in which the partial sums get combined varies. Kahan makes that wobble considerably smaller; it does not make it impossible.</p>

<h2 id="using-it-with-streams">Using it with Streams</h2>

<p>There are two natural ways to integrate this accumulator with the Java Streams API, depending on whether you happen to have a primitive <code class="language-plaintext highlighter-rouge">DoubleStream</code> or a boxed <code class="language-plaintext highlighter-rouge">Stream&lt;Double&gt;</code>.</p>

<h3 id="option-a-doublestreamcollect-best-for-primitive-streams">Option A: DoubleStream.collect (best for primitive streams)</h3>

<p><code class="language-plaintext highlighter-rouge">DoubleStream</code> has its own <code class="language-plaintext highlighter-rouge">collect</code> overload that avoids the boxing cost of the generic <code class="language-plaintext highlighter-rouge">Collector</code> machinery, which makes it the better choice when you already have a primitive stream:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kn">import</span> <span class="nn">java.util.stream.DoubleStream</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">final</span> <span class="kd">class</span> <span class="nc">Kahan</span> <span class="o">{</span>

  <span class="kd">private</span> <span class="nf">Kahan</span><span class="o">()</span> <span class="o">{}</span>

  <span class="kd">public</span> <span class="kd">static</span> <span class="kt">double</span> <span class="nf">sum</span><span class="o">(</span><span class="nc">DoubleStream</span> <span class="n">stream</span><span class="o">)</span> <span class="o">{</span>
    <span class="nc">KahanAccumulator</span> <span class="n">acc</span> <span class="o">=</span> <span class="n">stream</span><span class="o">.</span><span class="na">collect</span><span class="o">(</span>
        <span class="nl">KahanAccumulator:</span><span class="o">:</span><span class="k">new</span><span class="o">,</span>
        <span class="nl">KahanAccumulator:</span><span class="o">:</span><span class="n">add</span><span class="o">,</span>
        <span class="nl">KahanAccumulator:</span><span class="o">:</span><span class="n">combine</span>
    <span class="o">);</span>
    <span class="k">return</span> <span class="n">acc</span><span class="o">.</span><span class="na">value</span><span class="o">();</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>Usage looks like the obvious thing:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">s1</span> <span class="o">=</span> <span class="nc">Kahan</span><span class="o">.</span><span class="na">sum</span><span class="o">(</span><span class="nc">DoubleStream</span><span class="o">.</span><span class="na">of</span><span class="o">(</span><span class="mf">0.1</span><span class="o">,</span> <span class="mf">0.2</span><span class="o">,</span> <span class="mf">0.3</span><span class="o">));</span>
<span class="kt">double</span> <span class="n">s2</span> <span class="o">=</span> <span class="nc">Kahan</span><span class="o">.</span><span class="na">sum</span><span class="o">(</span><span class="n">myDoubleStream</span><span class="o">.</span><span class="na">parallel</span><span class="o">());</span> <span class="c1">// allowed, order still not fixed</span></code></pre></figure>

<h3 id="option-b-a-collector-nice-ergonomics-for-boxed-streams">Option B: a Collector (nice ergonomics for boxed streams)</h3>

<p>When you already have a <code class="language-plaintext highlighter-rouge">Stream&lt;Double&gt;</code> for some reason — typically because the upstream code is using boxed types — a <code class="language-plaintext highlighter-rouge">Collector</code> is more convenient and idiomatic:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kn">import</span> <span class="nn">java.util.stream.Collector</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">final</span> <span class="kd">class</span> <span class="nc">KahanCollectors</span> <span class="o">{</span>

  <span class="kd">private</span> <span class="nf">KahanCollectors</span><span class="o">()</span> <span class="o">{}</span>

  <span class="kd">public</span> <span class="kd">static</span> <span class="nc">Collector</span><span class="o">&lt;</span><span class="nc">Double</span><span class="o">,</span> <span class="nc">KahanAccumulator</span><span class="o">,</span> <span class="nc">Double</span><span class="o">&gt;</span> <span class="nf">kahanSummingDouble</span><span class="o">()</span> <span class="o">{</span>
    <span class="k">return</span> <span class="nc">Collector</span><span class="o">.</span><span class="na">of</span><span class="o">(</span>
        <span class="nl">KahanAccumulator:</span><span class="o">:</span><span class="k">new</span><span class="o">,</span>
        <span class="o">(</span><span class="n">acc</span><span class="o">,</span> <span class="n">x</span><span class="o">)</span> <span class="o">-&gt;</span> <span class="n">acc</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">x</span><span class="o">),</span>
        <span class="o">(</span><span class="n">a</span><span class="o">,</span> <span class="n">b</span><span class="o">)</span> <span class="o">-&gt;</span> <span class="o">{</span> <span class="n">a</span><span class="o">.</span><span class="na">combine</span><span class="o">(</span><span class="n">b</span><span class="o">);</span> <span class="k">return</span> <span class="n">a</span><span class="o">;</span> <span class="o">},</span>
        <span class="nl">KahanAccumulator:</span><span class="o">:</span><span class="n">value</span>
    <span class="o">);</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>Usage, again, is the usual thing:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">s</span> <span class="o">=</span> <span class="n">myStreamOfDoubles</span><span class="o">.</span><span class="na">collect</span><span class="o">(</span><span class="nc">KahanCollectors</span><span class="o">.</span><span class="na">kahanSummingDouble</span><span class="o">());</span></code></pre></figure>

<h2 id="correctness-what-to-test-and-what-not-to-promise">Correctness: what to test, and what not to promise</h2>

<p>It is worth being precise, when introducing this kind of utility into a codebase, about what it does and does not promise, because the difference between the two is the source of most production surprises in this space.</p>

<h3 id="what-you-should-promise">What you should promise</h3>

<ul>
  <li>Better accuracy than naive summation for large <code class="language-plaintext highlighter-rouge">N</code> and wide dynamic ranges</li>
  <li>Explicit behavior you control and can review in code</li>
</ul>

<h3 id="what-you-should-not-promise">What you should not promise</h3>

<ul>
  <li>Bit-for-bit deterministic results in parallel streams</li>
  <li>Exactness for money or decimal accounting</li>
</ul>

<h3 id="junit-test-idea-compare-against-a-higher-precision-reference">JUnit test idea: compare against a higher-precision reference</h3>

<p><code class="language-plaintext highlighter-rouge">BigDecimal</code> is not, strictly speaking, a perfect oracle for binary floating point — it represents numbers in base 10 — but it is a very useful reference when you want to confirm that one summation strategy is drifting more than another, since <code class="language-plaintext highlighter-rouge">BigDecimal</code> arithmetic has effectively unlimited precision for the operations involved here.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kn">import</span> <span class="nn">static</span> <span class="n">org</span><span class="o">.</span><span class="na">junit</span><span class="o">.</span><span class="na">jupiter</span><span class="o">.</span><span class="na">api</span><span class="o">.</span><span class="na">Assertions</span><span class="o">.*;</span>
<span class="kn">import</span> <span class="nn">java.math.BigDecimal</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">java.util.Random</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">java.util.stream.DoubleStream</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">org.junit.jupiter.api.Test</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">class</span> <span class="nc">KahanAccumulatorTest</span> <span class="o">{</span>

  <span class="nd">@Test</span>
  <span class="kt">void</span> <span class="nf">kahan_is_usually_better_than_naive_on_wide_range_data</span><span class="o">()</span> <span class="o">{</span>
    <span class="nc">Random</span> <span class="n">r</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">Random</span><span class="o">(</span><span class="mi">0</span><span class="o">);</span>

    <span class="kt">double</span><span class="o">[]</span> <span class="n">xs</span> <span class="o">=</span> <span class="nc">DoubleStream</span><span class="o">.</span><span class="na">generate</span><span class="o">(()</span> <span class="o">-&gt;</span> <span class="o">{</span>
      <span class="kt">double</span> <span class="n">sign</span> <span class="o">=</span> <span class="n">r</span><span class="o">.</span><span class="na">nextBoolean</span><span class="o">()</span> <span class="o">?</span> <span class="mf">1.0</span> <span class="o">:</span> <span class="o">-</span><span class="mf">1.0</span><span class="o">;</span>
      <span class="kt">double</span> <span class="n">mag</span> <span class="o">=</span> <span class="nc">Math</span><span class="o">.</span><span class="na">pow</span><span class="o">(</span><span class="mf">10.0</span><span class="o">,</span> <span class="n">r</span><span class="o">.</span><span class="na">nextInt</span><span class="o">(</span><span class="mi">20</span><span class="o">)</span> <span class="o">-</span> <span class="mi">10</span><span class="o">);</span> <span class="c1">// 1e-10 .. 1e9</span>
      <span class="k">return</span> <span class="n">sign</span> <span class="o">*</span> <span class="n">mag</span> <span class="o">*</span> <span class="n">r</span><span class="o">.</span><span class="na">nextDouble</span><span class="o">();</span>
    <span class="o">}).</span><span class="na">limit</span><span class="o">(</span><span class="mi">200_000</span><span class="o">).</span><span class="na">toArray</span><span class="o">();</span>

    <span class="kt">double</span> <span class="n">naive</span> <span class="o">=</span> <span class="mf">0.0</span><span class="o">;</span>
    <span class="nc">KahanAccumulator</span> <span class="n">kahan</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">KahanAccumulator</span><span class="o">();</span>
    <span class="nc">BigDecimal</span> <span class="n">ref</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">ZERO</span><span class="o">;</span>

    <span class="k">for</span> <span class="o">(</span><span class="kt">double</span> <span class="n">x</span> <span class="o">:</span> <span class="n">xs</span><span class="o">)</span> <span class="o">{</span>
      <span class="n">naive</span> <span class="o">+=</span> <span class="n">x</span><span class="o">;</span>
      <span class="n">kahan</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">x</span><span class="o">);</span>
      <span class="n">ref</span> <span class="o">=</span> <span class="n">ref</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="n">x</span><span class="o">));</span>
    <span class="o">}</span>

    <span class="c1">// Reference converted back to double so we compare at double resolution.</span>
    <span class="kt">double</span> <span class="n">reference</span> <span class="o">=</span> <span class="n">ref</span><span class="o">.</span><span class="na">doubleValue</span><span class="o">();</span>

    <span class="kt">double</span> <span class="n">errNaive</span> <span class="o">=</span> <span class="nc">Math</span><span class="o">.</span><span class="na">abs</span><span class="o">(</span><span class="n">naive</span> <span class="o">-</span> <span class="n">reference</span><span class="o">);</span>
    <span class="kt">double</span> <span class="n">errKahan</span> <span class="o">=</span> <span class="nc">Math</span><span class="o">.</span><span class="na">abs</span><span class="o">(</span><span class="n">kahan</span><span class="o">.</span><span class="na">value</span><span class="o">()</span> <span class="o">-</span> <span class="n">reference</span><span class="o">);</span>

    <span class="c1">// In rare adversarial sequences Kahan can be slightly worse, but typically it's much better.</span>
    <span class="n">assertTrue</span><span class="o">(</span><span class="n">errKahan</span> <span class="o">&lt;=</span> <span class="n">errNaive</span> <span class="o">*</span> <span class="mf">2.0</span><span class="o">,</span>
        <span class="nc">String</span><span class="o">.</span><span class="na">format</span><span class="o">(</span><span class="s">"Kahan error (%.2e) vs naive (%.2e)"</span><span class="o">,</span> <span class="n">errKahan</span><span class="o">,</span> <span class="n">errNaive</span><span class="o">));</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<h2 id="performance-what-it-costs">Performance: what it costs</h2>

<p>Naive summation does exactly one addition per element. Kahan summation, by comparison, does a small handful of extra operations per element — three subtractions and one extra addition, on top of the one that would otherwise have been there. That is, in the end, a small constant factor, and in the great majority of analytics pipelines I have worked on, the accuracy gain is worth far more than the marginal CPU cost.</p>

<p>If you do want to measure the overhead carefully, the right tool to reach for is JMH, and the comparison worth running is between four variants:</p>

<ul>
  <li>the naive loop</li>
  <li><code class="language-plaintext highlighter-rouge">DoubleStream.sum()</code></li>
  <li>the Kahan loop directly</li>
  <li>Kahan via <code class="language-plaintext highlighter-rouge">DoubleStream.collect</code></li>
</ul>

<p>The relative numbers, in my experience, depend more on the surrounding pipeline and the JIT’s behaviour than on the algorithm itself, but the overhead of Kahan tends to be in single-digit percent territory for typical workloads.</p>

<h2 id="when-not-to-use-kahan">When NOT to use Kahan</h2>

<p>Kahan is genuinely useful, but it is not the right tool in every situation. There are at least three categories in which I would specifically avoid reaching for it:</p>

<ul>
  <li><strong>Financial calculations.</strong> Use <code class="language-plaintext highlighter-rouge">BigDecimal</code> for money. Kahan does not give you decimal semantics, and the kinds of rounding rules that finance and accounting actually require live in a different problem entirely.</li>
  <li><strong>Tiny datasets.</strong> When <code class="language-plaintext highlighter-rouge">N</code> is small, the cumulative error of naive summation is usually well below any threshold that matters, and the overhead of Kahan, however small, is rarely worth carrying for the negligible benefit.</li>
  <li><strong>Hard real-time or tight latency budgets.</strong> Profile first; the overhead is usually small but it is not zero, and in the kind of code that has a hard deadline every iteration, even a few nanoseconds per element can add up to meaningful time.</li>
</ul>

<h2 id="variants-worth-mentioning-neumaier-and-pairwise-summation">Variants worth mentioning: Neumaier and pairwise summation</h2>

<p>Kahan is, although a good default, not the only available compensated-summation technique. It is worth at least naming a couple of the alternatives, both because they sometimes behave better than Kahan on particular kinds of data and because anyone seriously interested in numerical accuracy will encounter them sooner or later in the literature.</p>

<p>Neumaier summation is a small modification of Kahan that handles a specific case more gracefully: the case in which the next addend is, in magnitude, larger than the current running sum, which is a situation Kahan can mishandle in a few corner cases.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// Neumaier variant</span>
<span class="kd">public</span> <span class="kd">final</span> <span class="kd">class</span> <span class="nc">NeumaierAccumulator</span> <span class="o">{</span>
  <span class="kd">private</span> <span class="kt">double</span> <span class="n">sum</span><span class="o">;</span>
  <span class="kd">private</span> <span class="kt">double</span> <span class="n">c</span><span class="o">;</span>

  <span class="kd">public</span> <span class="kt">void</span> <span class="nf">add</span><span class="o">(</span><span class="kt">double</span> <span class="n">x</span><span class="o">)</span> <span class="o">{</span>
    <span class="kt">double</span> <span class="n">t</span> <span class="o">=</span> <span class="n">sum</span> <span class="o">+</span> <span class="n">x</span><span class="o">;</span>
    <span class="k">if</span> <span class="o">(</span><span class="nc">Math</span><span class="o">.</span><span class="na">abs</span><span class="o">(</span><span class="n">sum</span><span class="o">)</span> <span class="o">&gt;=</span> <span class="nc">Math</span><span class="o">.</span><span class="na">abs</span><span class="o">(</span><span class="n">x</span><span class="o">))</span> <span class="o">{</span>
      <span class="n">c</span> <span class="o">+=</span> <span class="o">(</span><span class="n">sum</span> <span class="o">-</span> <span class="n">t</span><span class="o">)</span> <span class="o">+</span> <span class="n">x</span><span class="o">;</span>
    <span class="o">}</span> <span class="k">else</span> <span class="o">{</span>
      <span class="n">c</span> <span class="o">+=</span> <span class="o">(</span><span class="n">x</span> <span class="o">-</span> <span class="n">t</span><span class="o">)</span> <span class="o">+</span> <span class="n">sum</span><span class="o">;</span>
    <span class="o">}</span>
    <span class="n">sum</span> <span class="o">=</span> <span class="n">t</span><span class="o">;</span>
  <span class="o">}</span>

  <span class="kd">public</span> <span class="kt">double</span> <span class="nf">value</span><span class="o">()</span> <span class="o">{</span>
    <span class="k">return</span> <span class="n">sum</span> <span class="o">+</span> <span class="n">c</span><span class="o">;</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>Pairwise summation, also known as tree reduction, takes a different approach: rather than tracking compensation explicitly, it reduces error growth by combining numbers of similar magnitude together, so that the running sum never gets too far ahead of the values still being added. Some stream implementations may, behind the scenes, do something resembling this internally; the principal advantage of writing your own is that the behaviour is then explicit, reviewable, and not subject to silent change between JDK versions.</p>

<h2 id="when-to-use-what">When to use what</h2>

<p>Pulling all of the above together, the general guidance I would offer is roughly this. Use <code class="language-plaintext highlighter-rouge">BigDecimal</code> when you need decimal semantics, and you mean it; use naive summation when <code class="language-plaintext highlighter-rouge">N</code> is small, the magnitudes of the addends are similar, and you genuinely do not care about a few low-order bits; and use Kahan or Neumaier when:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">N</code> is large (thousands to millions of values)</li>
  <li>values span many orders of magnitude</li>
  <li>small contributions matter</li>
  <li>you want better accuracy without dragging BigDecimal everywhere</li>
</ul>

<h3 id="a-note-on-bigdecimal-vs-kahan-so-we-dont-mix-the-tools">A note on BigDecimal vs Kahan (so we don’t mix the tools)</h3>

<p>It is worth being explicit about this distinction, because I have seen it confused often enough that the confusion is, by itself, a recurring source of bugs. <strong><code class="language-plaintext highlighter-rouge">BigDecimal</code> is about decimal <em>semantics</em></strong> — money, accounting, “pennies must add up,” explicit rounding rules — and <strong>Kahan is about <em>accumulation error</em> in <code class="language-plaintext highlighter-rouge">double</code></strong> when <code class="language-plaintext highlighter-rouge">double</code> is genuinely the right representation for the values being summed (metrics, measurements, statistics, ML features, telemetry) but naive summation is bleeding low-order bits over a long enough reduction.</p>

<p>The practical rule of thumb is straightforward enough:</p>

<ul>
  <li>If your requirements mention <strong>cents, statements, taxes, interest, regulatory accuracy, or mandated rounding policies</strong> → use <strong>BigDecimal</strong> (and decide scale + rounding mode explicitly).</li>
  <li>If your requirements mention <strong>large aggregates, mixed magnitudes, order sensitivity, or “why did parallel give a different total?”</strong> → keep <strong>double</strong>, but upgrade the summation (<strong>Kahan / Neumaier / pairwise</strong>), and be explicit about ordering if determinism matters.</li>
</ul>

<p>One small but persistent footgun while we are on the subject: <code class="language-plaintext highlighter-rouge">BigDecimal</code> only stays “decimal-correct” if you construct it correctly. Prefer parsing from a decimal string, or <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(double)</code>, over <code class="language-plaintext highlighter-rouge">new BigDecimal(double)</code>, which faithfully captures the binary representation of the double — including, of course, all of its decimal infidelity.</p>

<h2 id="closing">Closing</h2>

<p>Floating point, on its own terms, is not really broken; it is simply finite. The problem is not that rounding happens — rounding is what makes finite-precision arithmetic possible in the first place — but that rounding can happen many millions of times across a single reduction, while the running total continues to grow, and the cumulative effect of all those small dropped bits can become large enough to be wrong in ways that matter.</p>

<p>What Kahan summation does, in the end, is to keep a small ledger of what rounding has thrown away and to fold those discarded bits back into the next addition, so that the long-run drift stays bounded rather than accumulating without limit. The code change involved is genuinely small; the conceptual shift, however — from treating summation as a single line of code to treating it as a deliberate numerical algorithm — is the part that, I think, is worth taking seriously the next time you find yourself reaching for <code class="language-plaintext highlighter-rouge">.sum()</code> over a few million doubles.</p>

<hr />

<h2 id="references">References</h2>

<ul>
  <li>W. Kahan, “Pracniques: Further remarks on reducing truncation errors,” Communications of the ACM, 8(1), Jan. 1965.
DOI (ACM Digital Library): https://dl.acm.org/doi/10.1145/363707.363723</li>
</ul>

<p>Open PDF (hosted copy): https://convexoptimization.com/TOOLS/Kahan.pdf</p>

<p>Metadata entry (Semantic Scholar): https://www.semanticscholar.org/paper/Pracniques%3A-further-remarks-on-reducing-truncation-Kahan/672a99813f52aed720d3508d6be7db461328b064</p>

<ul>
  <li>
    <p>Prof Kahan’s Assorted Notes, https://people.eecs.berkeley.edu/~wkahan/</p>
  </li>
  <li>
    <p>N. J. Higham, “The Accuracy of Floating Point Summation”, SIAM Journal on Scientific Computing (1993). https://doi.org/10.1137/0914050</p>
  </li>
  <li>
    <p>DoubleStream.sum(): https://docs.oracle.com/en/java/javase/21/docs/api/java.base/java/util/stream/DoubleStream.html#sum()</p>
  </li>
  <li>
    <p>DoubleSummaryStatistics: https://docs.oracle.com/en/java/javase/21/docs/api/java.base/java/util/DoubleSummaryStatistics.html</p>
  </li>
</ul>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Computer Science" /><category term="Software Engineering" /><category term="Technology" /><category term="Series 4 - Floating Point Without Tears" /><category term="java" /><category term="floating-point" /><category term="ieee-754" /><category term="kahan" /><category term="numerical-analysis" /><category term="streams" /><category term="collector" /><summary type="html"><![CDATA[Learn why naive summation loses digits and how Kahan compensated summation helps. Includes Java Stream integration, test strategies, and when to use BigDecimal instead.]]></summary></entry><entry><title type="html">Stereotypes Are Lazy Maps</title><link href="https://systemhalted.in/2026/01/10/stereotypes-are-lazy-maps/" rel="alternate" type="text/html" title="Stereotypes Are Lazy Maps" /><published>2026-01-10T00:00:00+00:00</published><updated>2026-01-10T00:00:00+00:00</updated><id>https://systemhalted.in/2026/01/10/stereotypes-are-lazy-maps</id><content type="html" xml:base="https://systemhalted.in/2026/01/10/stereotypes-are-lazy-maps/"><![CDATA[<p>A stereotype is, in essence, a shortcut: a way of thinking about people in groups so that one does not have to do the considerably harder work of thinking about them as individuals. A generalization is, technically, a slightly more careful cousin of the same instinct — a guess about a population, ideally informed by some kind of evidence — but in practice the two tend to blur into each other, and both can be dangerously tempting when you are tired, when you are annoyed, or when you are trying to compress the human universe into a single sentence in order to win an argument on the internet. The trouble is that a shortcut, however efficient, is never quite the same thing as the truth, and when the shortcut is being applied to several million people at once, the gap between the two can become very large.</p>

<p>This post, in the modern fashion, started its life with a social media thread. I saw a post about “student drivers” which had, by the time I came across it, evolved into a sweeping generalization about an entire people; someone, apparently in response, had then attempted to generalize Indians in one long, unpunctuated breath, and the resulting exchange was almost a small textbook in the failure mode I want to write about here. The irony, in particular, was not subtle: the corrective offered to a sweeping generalization about one group was, somehow, a sweeping generalization about another group, on the apparent assumption that two equal and opposite errors might add up to honesty.</p>

<p>I should say, before going further, that this is not really a post about Indians, or Americans, or any one group in particular. It is a post about a habit of mind that I think we have, collectively, normalized — the habit of reducing millions of people to a neat sentence and then calling it “an observation.”</p>

<h2 id="the-world-is-too-large-for-our-brains">The world is too large for our brains</h2>

<p>It is worth starting with the underlying mechanism, because the instinct that produces stereotypes is, by itself, neither malicious nor unusual. Human brains are, before they are anything else, pattern machines. We find faces in clouds, infer intent from a raised eyebrow, and build small working models of reality more or less continuously, because raw reality, in its full detail, is far too large to actually hold in mind. That model-building instinct is not in itself evil; it is, in a real sense, a survival adaptation, and most of the time it serves us reasonably well.</p>

<p>The trouble begins, however, when we start to mistake the model for the world. A stereotype, viewed from this angle, is what happens when you take a small sample of human behaviour, add a generous amount of emotion, mix in a few viral anecdotes, and then quietly export the resulting impression as if it were a universal law about an entire population. It tends to feel efficient, satisfying, and like a kind of closure on a question that previously was open — and all three of those feelings, while pleasant, are also exactly what makes the move so easy to perform without noticing. It is, in the end, the principal way in which we end up misreading entire peoples.</p>

<h2 id="indians-are-is-a-sentence-that-breaks-under-its-own-weight">“Indians are…” is a sentence that breaks under its own weight</h2>

<p>India, to take the example I happen to know best, is not a monolith. It is a continent-sized civilization with many languages, many histories, many moral philosophies, many economic realities, and many different ways of being human, none of which fit comfortably under a single noun. When someone confidently begins a sentence with “Indians are…”, and then completes it with any predicate at all, what they are usually saying — whether they realise it or not — is something closer to “I met some Indians once,” or “I saw a few videos,” or “I had one bad experience,” or “I read a thread on the internet that made me feel righteous, and I am now extrapolating from it.”</p>

<p>The mental move that follows is the one I find most worth flagging, because it is so common and so frictionless that it is usually invisible to the person making it. The brain takes an anecdote — a single experience, a small sample, a memorable encounter — and quietly upgrades it into an identity, into a property of an entire group. That is not insight in any meaningful sense; it is laziness wearing the costume of insight, and it is unusually difficult to argue with, because the speaker can always retreat to “but I am only describing what I have actually seen.”</p>

<h2 id="the-equal-and-opposite-mistake">The equal and opposite mistake</h2>

<p>There is a pattern that tends to follow almost mechanically from the kind of move described above, and it is worth treating on its own terms because it is, in some ways, more pernicious than the original. The pattern is this: the response to “Indians are X” is almost never “let us not generalize about people in groups,” but is instead “well, Americans are Y.”</p>

<p>This looks, on its surface, like an attempt at fairness — turning the same lens back on the speaker — but in practice it is just the same error doing a second lap. The United States, after all, is the third-largest country in the world by population, and it contains multitudes: regions that feel like different planets, communities built up from different waves of migration, value systems that clash with each other on a daily basis, and identities that do not fit into any clean box that anyone has yet managed to draw. Broad generalizations about Americans are, on close inspection, every bit as unfair as broad generalizations about Indians, and for exactly the same reasons.</p>

<p>What tends to happen in these exchanges, then, is not a productive conversation but a steady collapse into noise, in which one stereotype is met with its opposite, that opposite is met with another, and by the time anyone has stopped to think, the actual question — whatever it might originally have been — has been buried under a small mountain of confidently stated nonsense. The result, in any sense that the word ought to mean, is not justice; it is just more of the same kind of laziness, moving faster.</p>

<h2 id="the-small-loud-group-problem">The “small loud group” problem</h2>

<p>A reasonable-sounding defence of the move I have been describing goes something like this: “I am not generalizing about everyone. I am only talking about a certain kind of person.” That defence is sometimes legitimate, and it is worth taking seriously, because there is no question that social media has a way of amplifying the most extreme voices in any group, that outrage tends to function as the algorithmic fuel of these platforms, and that the loudest voices therefore get the microphone far more often than their actual representativeness in the underlying population would warrant.</p>

<p>What this defence misses, however, is that adult conversation about groups requires adult precision about which claim, exactly, is being made — and there is a meaningful difference between two claims that often get confused for each other. The first is “some people are doing this harmful thing”; the second is “this group is like this.” The first is a claim about behaviour, and it has the useful property of being debatable, measurable, challengeable, and refinable in the light of new evidence. The second is a claim about identity, and what it does, often without the speaker quite noticing, is to turn an observed behaviour into an essential property of the group itself — at which point it becomes very difficult to discuss without sounding either dismissive of the original observation or apologetic on behalf of an entire population.</p>

<p>That distinction — between behaviour and identity — is, I think, the line that matters most in these conversations. It is also, in my experience, the line that is most reliably crossed without anyone quite admitting that they have crossed it.</p>

<h2 id="why-stereotypes-feel-so-good">Why stereotypes feel so good</h2>

<p>It is worth being honest, at this stage, about why stereotypes are so persistent, despite the fact that almost everyone, when asked directly, will agree that they are unreliable. The honest answer, I think, is that they offer at least three things which the internet, in its current form, particularly rewards: a feeling of certainty about a complicated subject (“I understand what is going on here”), a substantial saving of time and mental effort (“I do not need to do the work”), and a kind of moral permission (“I am now justified in judging”). Each of those payoffs is, on its own, a real human need, and a stereotype tends to provide all three at once and very cheaply.</p>

<p>Real understanding, by comparison, is comparatively slow. It requires the friction of saying “I might be wrong about this,” and of then doing the harder work of going out and gathering better evidence than the small sample one started with. Philosophers have a name for the disposition involved here — they call it epistemic humility<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> — and it amounts, in the end, to the recognition that our knowledge of any given group of people is always incomplete, our samples always limited, and our confidence in our conclusions always more provisional than we tend to act as if it is. It is, almost by definition, the opposite of the kind of reaction that social media tends to reward, and it is, in any case, considerably harder than typing a hot take.</p>

<h2 id="a-better-way-to-speak">A better way to speak</h2>

<p>If the goal is to be able to criticize an observed pattern without flattening millions of people into cardboard cutouts, there are a few defaults that I have, over time, come to find useful. Most of them are not original to me, and most of them sound obvious when written down — but, as with most discipline, the difficulty is not in the principles themselves but in remembering to apply them at the moment one is most tempted not to.</p>

<ul>
  <li>Speak about specific behaviors, not identities.</li>
  <li>Use “some” and “in my experience” like seatbelts.</li>
  <li>Separate “what I saw” from “what is true.”</li>
  <li>Ask whether your sample is representative or just memorable.</li>
  <li>When you feel righteous, pause. Righteousness is not a fact-checker.</li>
</ul>

<p>What unifies most of these, I think, is the underlying observation that, in conversations about groups, precision is a form of kindness. If the goal is to be understood, and to leave the other person with a clearer view of the world rather than a more flattering view of themselves, then the additional words spent saying “some” rather than “all,” or “in my experience” rather than “obviously,” are not weakness or hedging — they are the difference between a sentence that can be true and one that essentially cannot.</p>

<h2 id="immigrants-live-inside-the-blur">Immigrants live inside the blur</h2>

<p>I should also say, more personally, that immigrants tend to occupy a particular kind of space in these conversations, and it is one that I have come to understand from the inside. You learn, over the years, to love the country you live in, while also carrying — quietly, most of the time — the experience of being misread by it. You become, in effect, bilingual not only in language but in assumptions, and you spend a non-trivial amount of mental energy translating between the two on any given day.</p>

<p>The forms of that misreading vary considerably. Sometimes you are treated, by complete strangers, as an ambassador for a population of more than a billion people, and asked questions that no individual could possibly be qualified to answer. Sometimes you are treated as an exception to whatever is being said about your group at the time — “you’re not like the others” — which is meant generously and is, in its own way, almost as unkind as the original generalization, because it tacitly accepts the generalization while granting you a personal exemption from it. And sometimes you are simply reduced to a meme, which is at least faster.</p>

<p>Through all of that, you still get up in the morning and show up. You contribute, you build, you teach, you try to belong somewhere without having to dissolve into it in order to do so. And it is from inside that experience, more than anything else, that I want to insist that when someone stereotypes a group, what they are doing is not really “just words.” A stereotype, in practice, is a small social verdict, and small social verdicts have a way of sticking.</p>

<h2 id="the-point">The point</h2>

<p>It would be, of course, somewhat awkward to end an essay against generalizations with a generalization of my own, and so I want to be careful to avoid the easy line “everyone stereotypes,” which is, in its own quiet way, exactly the kind of move I have spent the last several sections complaining about.</p>

<p>What I will say instead is something more local. After the thread I described at the beginning, I also received a number of kind messages from people in my local community, offering support and, in several cases, apologizing “on behalf of” others. The intent in those messages was generous, and I genuinely appreciated each of them. But I have to admit that, even within that generosity, I felt the shadow of the same underlying mistake — the assumption that there is, somewhere, a “them” coherent enough to speak for. The truth, when one looks closely, is that there usually is not, and that the most useful thing one can do in response to bad generalizations from one direction is not to speak more confidently from the other, but to refuse the framing altogether.</p>

<p>We do not, in the end, defeat stereotypes by pretending that differences between people and groups do not exist; that is its own form of dishonesty, and a particularly fragile one at that. We defeat them, to the extent that we defeat them at all, by being honest about complexity — by trading lazy certainty for careful clarity, by resisting the cheap thrill of the sweeping sentence, and by remembering, especially when it is most tempting to forget, that every “they” we are tempted to talk about is, on closer inspection, made of millions of individual “someones,” each of whom would, given the chance, object to whatever we were about to say about them collectively. The world, in other words, is genuinely detailed; and being honest about that detail, even when it makes our sentences longer, is what taking other people seriously actually looks like.</p>

<h2 id="references-and-notes">References and Notes</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Epistemic humility: https://en.wikipedia.org/wiki/Epistemic_humility <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Society &amp; Economy" /><category term="Personal Essays" /><category term="stereotypes" /><category term="generalization" /><category term="immigrants" /><category term="critical-thinking" /><category term="social-media" /><summary type="html"><![CDATA[A short essay on why stereotypes feel efficient but fail under scrutiny, and how to talk about groups: Indians, Americans, immigrants, anyone, without flattening millions of people into a single sentence.]]></summary></entry><entry><title type="html">Part 6: Defending Against NaN Without Defensive Programming Hell</title><link href="https://systemhalted.in/2026/01/05/defending-against-nan-without-defensive-programming-hell/" rel="alternate" type="text/html" title="Part 6: Defending Against NaN Without Defensive Programming Hell" /><published>2026-01-05T00:00:00+00:00</published><updated>2026-01-05T00:00:00+00:00</updated><id>https://systemhalted.in/2026/01/05/defending-against-nan-without-defensive-programming-hell</id><content type="html" xml:base="https://systemhalted.in/2026/01/05/defending-against-nan-without-defensive-programming-hell/"><![CDATA[<p><em>This post is part of my <a href="https://systemhalted.in/categories/#cat-series-4-floating-point-without-tears">Floating Point Without Tears</a> series on how Java numbers misbehave and how to live with them.</em></p>

<p>When IEEE 754 arithmetic encounters an operation for which there is no real-number answer — dividing zero by zero, taking the square root of a negative number, and so on — it does not throw an exception. Instead, it produces a special value called NaN, short for “Not a Number,” and the program continues running as if nothing in particular had happened. This is, as a piece of language design, both a strength and a quiet curse: it allows numerical code to keep flowing in the presence of locally invalid operations, but it also means that NaN tends to slip downstream silently and only surface much later, in log files, in metrics, and on dashboards, long after the operation that actually produced it has scrolled out of view.</p>

<p>The temptation, on first encountering this behaviour, is to start sprinkling <code class="language-plaintext highlighter-rouge">if (isNaN)</code> checks throughout the codebase as a defence. This post is, in a sense, about doing the opposite of that — about defending against NaN structurally, using a small number of checks placed deliberately at the right boundaries, rather than scattering a defensive layer through every function in the system.</p>

<h2 id="the-shape-of-the-beast">The shape of the beast</h2>

<p>NaN, as the name suggests, is what IEEE 754 hands back from operations that have no meaningful real-number answer. The canonical examples are familiar enough — dividing <code class="language-plaintext highlighter-rouge">0.0</code> by <code class="language-plaintext highlighter-rouge">0.0</code>, taking the square root of a negative number, taking the logarithm of a negative number — but there is a fourth source that is, in practice, more important than any individual mathematical case: any operation that already involves a NaN will itself produce a NaN. NaN is contagious, in both the best and the worst senses of the word, and that contagion is the mechanism by which a single invalid operation upstream can quietly poison everything that flows from it.</p>

<p>Some of the operations that produce NaN are:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>1.	0.0 / 0.0  
2.	Math.sqrt(-1.0)  
3.	Math.log(-1.0)  
4.	Any operation that already contains NaN, because NaN is contagious in the best and worst ways  
</code></pre></div></div>

<p>Java follows IEEE 754 in all of this. The JVM does not, for the most part, throw an exception when a floating-point operation is invalid; it produces NaN or Infinity and lets the program continue, which is another way of saying that what you are looking at is a silent error.</p>

<p>There is one further property of NaN that catches almost everyone the first time they encounter it. NaN is not equal to anything, not even to itself.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">x</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">NaN</span><span class="o">;</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span> <span class="o">==</span> <span class="n">x</span><span class="o">);</span>              <span class="c1">// false</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isNaN</span><span class="o">(</span><span class="n">x</span><span class="o">));</span>     <span class="c1">// true</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span> <span class="o">&lt;</span> <span class="mi">0</span><span class="o">);</span>              <span class="c1">// false</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="o">);</span>              <span class="c1">// false</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span> <span class="o">==</span> <span class="mi">0</span><span class="o">);</span>             <span class="c1">// false</span></code></pre></figure>

<p>NaN, in other words, does not really behave like a value in the ordinary sense; it is more accurately understood as a signal that has, by the design of the floating-point system, been forced to masquerade as a value. The fact that it wears that disguise convincingly is the source of most of the practical trouble that NaN goes on to cause in production systems.</p>

<h2 id="defensive-programming-hell-or-what-i-call-checkpoint-syndrome">Defensive programming hell, or what I call “Checkpoint Syndrome”</h2>

<p>The instinctive reaction to discovering NaN in production is, I think, entirely understandable. You find a NaN in a log, trace it back to a particular code path, add an <code class="language-plaintext highlighter-rouge">isNaN</code> check there, deploy the fix, and move on. The trouble is that, almost without exception, the next NaN that shows up will not be in the same place — it will be in some other path that touches the same data — and so another check goes in. Repeat this process for a few months and you end up with a codebase in which essentially every function is doing its own defensive validation of every input it receives, often with slightly different responses to the same underlying condition.</p>

<p>The result tends to look something like this:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">price</span> <span class="o">=</span> <span class="n">computePrice</span><span class="o">(</span><span class="n">input</span><span class="o">);</span>
<span class="k">if</span> <span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isNaN</span><span class="o">(</span><span class="n">price</span><span class="o">)</span> <span class="o">||</span> <span class="nc">Double</span><span class="o">.</span><span class="na">isInfinite</span><span class="o">(</span><span class="n">price</span><span class="o">))</span> <span class="o">{</span>
    <span class="c1">// shrug, return 0?</span>
<span class="o">}</span></code></pre></figure>

<p>This is what I have come to think of as Checkpoint Syndrome, and the problem with it goes well beyond the visual noise. It is something closer to a small architectural disaster: the checks have a way of spreading everywhere, and yet, despite their ubiquity, they almost never point at the real cause of the bug, because by the time NaN reaches the function being checked, the operation that originally produced it is several layers upstream and is no longer visible at the call site. Each defensive site is also forced to make its own decision about what to do when the check fails, and those decisions tend to drift apart over time, so a single class of upstream bug ends up being silently handled in a dozen inconsistent ways throughout the codebase.</p>

<p>Worst of all — and this is where Checkpoint Syndrome most reliably produces actual financial bugs — the easiest “fix” at any individual site is to convert the invalid value to zero. That has the convenient property of making the immediate symptom go away, while quietly turning “we do not know” into “definitely zero” in every downstream calculation that follows.</p>

<p>The antidote to all of this is not, as it might first appear, to add more checks. The antidote is to place fewer checks but to place them where they actually matter — at the boundaries where invalid values either enter the system or are first produced, once, deliberately, and with a documented response.</p>

<h2 id="the-core-principle-validate-at-the-edges-compute-in-the-middle">The core principle: validate at the edges, compute in the middle</h2>

<p><img src="/assets/images/2026-01-05-core-principles.png" alt="Diagram showing validation at boundaries and a clean computation core." /></p>

<p>Most NaN outbreaks begin at boundaries:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>1.	Parsing and deserialization (CSV, JSON, user input, partner payloads)  
2.	Sensor-style data (telemetry, percentages, rates)  
3.	Divide by something that might be zero or missing  
4.	"This should never happen" conversions (and then it happens)  
</code></pre></div></div>

<p>The most useful thing you can do in response to this, in my experience, is to establish a single simple contract that the rest of the system can rely on: inside the computation core, all doubles are finite unless explicitly documented otherwise. The computation core is the part of the system that should be allowed to be blissfully boring — the pure math, the algorithms, the business logic that operates on already-validated inputs — and it is the place where you most want to be able to reason about correctness without simultaneously doing border control.</p>

<p>The practical consequence of that contract is that NaN handling becomes concentrated in a small number of choke points, rather than spread thinly across the codebase.</p>

<h2 id="pattern-1-finite-by-default-as-a-guardrail">Pattern 1: “Finite by default” as a guardrail</h2>

<p>The simplest expression of this discipline is a small helper that asserts finiteness explicitly:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">static</span> <span class="kt">double</span> <span class="nf">requireFinite</span><span class="o">(</span><span class="kt">double</span> <span class="n">x</span><span class="o">,</span> <span class="nc">String</span> <span class="n">name</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">if</span> <span class="o">(!</span><span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">x</span><span class="o">))</span> <span class="o">{</span>
        <span class="k">throw</span> <span class="k">new</span> <span class="nf">IllegalArgumentException</span><span class="o">(</span><span class="n">name</span> <span class="o">+</span> <span class="s">" must be finite, got "</span> <span class="o">+</span> <span class="n">x</span><span class="o">);</span>
    <span class="o">}</span>
    <span class="k">return</span> <span class="n">x</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p><code class="language-plaintext highlighter-rouge">Double.isFinite()</code> is, for this purpose, the only check you actually need. It returns <code class="language-plaintext highlighter-rouge">true</code> only when its argument is neither NaN nor Infinity, which is exactly what “a normal, usable number” means in most contexts. There is rarely any value in writing two separate checks for <code class="language-plaintext highlighter-rouge">isNaN</code> and <code class="language-plaintext highlighter-rouge">isInfinite</code> when a single call to <code class="language-plaintext highlighter-rouge">isFinite</code> captures both conditions.</p>

<p>The pattern, then, is to use <code class="language-plaintext highlighter-rouge">requireFinite</code> at public boundaries and at layer transitions, rather than inside every private method:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">public</span> <span class="kt">double</span> <span class="nf">monthlyPayment</span><span class="o">(</span><span class="kt">double</span> <span class="n">principal</span><span class="o">,</span> <span class="kt">double</span> <span class="n">annualRate</span><span class="o">,</span> <span class="kt">int</span> <span class="n">months</span><span class="o">)</span> <span class="o">{</span>
    <span class="n">requireFinite</span><span class="o">(</span><span class="n">principal</span><span class="o">,</span> <span class="s">"principal"</span><span class="o">);</span>
    <span class="n">requireFinite</span><span class="o">(</span><span class="n">annualRate</span><span class="o">,</span> <span class="s">"annualRate"</span><span class="o">);</span>
    <span class="k">if</span> <span class="o">(</span><span class="n">months</span> <span class="o">&lt;=</span> <span class="mi">0</span><span class="o">)</span> <span class="k">throw</span> <span class="k">new</span> <span class="nc">IllegalArgumentException</span><span class="o">(</span><span class="s">"months must be positive"</span><span class="o">);</span>

    <span class="kt">double</span> <span class="n">r</span> <span class="o">=</span> <span class="n">annualRate</span> <span class="o">/</span> <span class="mf">12.0</span><span class="o">;</span>

    <span class="c1">// Standard annuity formula:</span>
    <span class="c1">//   P = L * [r(1+r)^n] / [(1+r)^n - 1]</span>
    <span class="c1">// Rewritten with a negative exponent:</span>
    <span class="c1">//   P = L * r / (1 - (1+r)^(-n))</span>
    <span class="c1">// Same math, often friendlier numerically for large n.</span>
    <span class="k">return</span> <span class="n">principal</span> <span class="o">*</span> <span class="n">r</span> <span class="o">/</span> <span class="o">(</span><span class="mf">1.0</span> <span class="o">-</span> <span class="nc">Math</span><span class="o">.</span><span class="na">pow</span><span class="o">(</span><span class="mf">1.0</span> <span class="o">+</span> <span class="n">r</span><span class="o">,</span> <span class="o">-</span><span class="n">months</span><span class="o">));</span>
<span class="o">}</span></code></pre></figure>

<p>What you get from this approach is, I think, three things worth having at the same time. The failure becomes loud and early, rather than silent and downstream. The body of the computation stays free of validation noise. And when the exception does fire, it points at a real contract violation — a specific named argument coming in non-finite — rather than at some mysterious symptom many layers later in the call stack.</p>

<h2 id="pattern-2-separate-invalid-from-zero-with-a-result-type">Pattern 2: Separate “invalid” from “zero” with a result type</h2>

<p>There are situations in which you cannot reasonably throw — typically because the caller is processing a stream of inputs and needs to continue regardless of whether any individual one is valid, while still being able to tell which ones were not. In those situations, the right move is usually to represent the distinction explicitly in the return type, rather than overloading a numeric value to mean both “result” and “no result.”</p>

<p>In Java, you can use a sealed interface to construct a true disjunctive type, of which I have written a <a href="https://systemhalted.in/2025/11/25/disjuntive-types/">longer post</a> for the full story:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">sealed</span> <span class="kd">interface</span> <span class="nc">CalcResult</span> <span class="n">permits</span> <span class="nc">CalcResult</span><span class="o">.</span><span class="na">Valid</span><span class="o">,</span> <span class="nc">CalcResult</span><span class="o">.</span><span class="na">Invalid</span> <span class="o">{</span>
    
    <span class="kd">record</span> <span class="nf">Valid</span><span class="o">(</span><span class="kt">double</span> <span class="n">value</span><span class="o">)</span> <span class="kd">implements</span> <span class="nc">CalcResult</span> <span class="o">{</span>
        <span class="kd">public</span> <span class="nc">Valid</span> <span class="o">{</span>
            <span class="c1">// Enforce finite values in Valid variant</span>
            <span class="k">if</span> <span class="o">(!</span><span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">value</span><span class="o">))</span> <span class="o">{</span>
                <span class="k">throw</span> <span class="k">new</span> <span class="nf">IllegalArgumentException</span><span class="o">(</span><span class="s">"Valid result must be finite"</span><span class="o">);</span>
            <span class="o">}</span>
        <span class="o">}</span>
    <span class="o">}</span>
    
    <span class="kd">record</span> <span class="nf">Invalid</span><span class="o">(</span><span class="nc">String</span> <span class="n">reason</span><span class="o">)</span> <span class="kd">implements</span> <span class="nc">CalcResult</span> <span class="o">{}</span>
    
    <span class="c1">// Convenience factory methods</span>
    <span class="kd">static</span> <span class="nc">Valid</span> <span class="nf">ok</span><span class="o">(</span><span class="kt">double</span> <span class="n">value</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">return</span> <span class="k">new</span> <span class="nf">Valid</span><span class="o">(</span><span class="n">value</span><span class="o">);</span>
    <span class="o">}</span>
    
    <span class="kd">static</span> <span class="nc">Invalid</span> <span class="nf">failed</span><span class="o">(</span><span class="nc">String</span> <span class="n">reason</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">return</span> <span class="k">new</span> <span class="nf">Invalid</span><span class="o">(</span><span class="n">reason</span><span class="o">);</span>
    <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>With a type of this shape in place, NaN is no longer a stealth signal hiding inside a numeric channel. An invalid result is a first-class outcome of its own, the <code class="language-plaintext highlighter-rouge">Valid</code> variant cannot be constructed with a non-finite value, and the compiler can be made to enforce exhaustive handling at every consumption site.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">CalcResult</span> <span class="nf">safeDivide</span><span class="o">(</span><span class="kt">double</span> <span class="n">a</span><span class="o">,</span> <span class="kt">double</span> <span class="n">b</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">if</span> <span class="o">(!</span><span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">a</span><span class="o">)</span> <span class="o">||</span> <span class="o">!</span><span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">b</span><span class="o">))</span> <span class="o">{</span>
        <span class="k">return</span> <span class="nc">CalcResult</span><span class="o">.</span><span class="na">failed</span><span class="o">(</span><span class="s">"non-finite input"</span><span class="o">);</span>
    <span class="o">}</span>
    <span class="k">if</span> <span class="o">(</span><span class="n">b</span> <span class="o">==</span> <span class="mf">0.0</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">return</span> <span class="nc">CalcResult</span><span class="o">.</span><span class="na">failed</span><span class="o">(</span><span class="s">"division by zero"</span><span class="o">);</span>
    <span class="o">}</span>
    <span class="k">return</span> <span class="nc">CalcResult</span><span class="o">.</span><span class="na">ok</span><span class="o">(</span><span class="n">a</span> <span class="o">/</span> <span class="n">b</span><span class="o">);</span>
<span class="o">}</span>

<span class="c1">// Pattern matching is exhaustive - compiler forces you to handle both cases</span>
<span class="nc">CalcResult</span> <span class="n">result</span> <span class="o">=</span> <span class="n">safeDivide</span><span class="o">(</span><span class="mf">10.0</span><span class="o">,</span> <span class="mf">2.0</span><span class="o">);</span>
<span class="k">switch</span> <span class="o">(</span><span class="n">result</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">case</span> <span class="nc">CalcResult</span><span class="o">.</span><span class="na">Valid</span><span class="o">(</span><span class="kt">double</span> <span class="n">v</span><span class="o">)</span> <span class="o">-&gt;</span> 
        <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"Result: "</span> <span class="o">+</span> <span class="n">v</span><span class="o">);</span>
    <span class="k">case</span> <span class="nc">CalcResult</span><span class="o">.</span><span class="na">Invalid</span><span class="o">(</span><span class="nc">String</span> <span class="n">reason</span><span class="o">)</span> <span class="o">-&gt;</span> 
        <span class="nc">System</span><span class="o">.</span><span class="na">err</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"Failed: "</span> <span class="o">+</span> <span class="n">reason</span><span class="o">);</span>
    <span class="c1">// No default needed - this is exhaustive</span>
<span class="o">}</span></code></pre></figure>

<p>The exact shape of the type is, in the end, less important than the discipline it expresses. What matters is that “invalid” is treated as a first-class outcome that the type system insists be handled, rather than as a special value that callers can quietly forget to check for.</p>

<h2 id="pattern-3-domain-types-that-make-nan-impossible">Pattern 3: Domain types that make NaN impossible</h2>

<p>It is also worth observing that many of the doubles in business systems are not really “real numbers in the wild.” They are money, rates, counts, durations, and percentages — values which have far more structure than <code class="language-plaintext highlighter-rouge">double</code> is capable of representing, and which therefore tend to make poor candidates for raw <code class="language-plaintext highlighter-rouge">double</code> storage in the first place.</p>

<p>A few examples of the better choice in each case:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>1.	Money: store cents as long, or use BigDecimal where precision matters  
2.	Counts: long or int  
3.	Percentages: maybe basis points as int (one basis point = 0.01%, so 550 bps = 5.50%)  
4.	Durations: java.time.Duration  
</code></pre></div></div>

<p>Tightening the types in this way reduces the surface area on which NaN can even appear in the first place. This is, in the end, the most reliable form of NaN defence available, and it has the additional virtue of being entirely structural: it is enforced by the compiler, rather than by the discipline of the next person to touch the code. A <code class="language-plaintext highlighter-rouge">long</code>, after all, simply cannot hold NaN — the language will not allow it.</p>

<h2 id="pattern-4-decide-where-infinity-is-acceptable">Pattern 4: Decide where Infinity is acceptable</h2>

<p>Part 5 of this series covered Infinity and signed zero in some detail. The practical question, at this stage, is what to do about Infinity in everyday code, and the answer turns mostly on whether your domain has any legitimate use for it.</p>

<p>Infinity is sometimes a meaningful signal:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>1.	"Unlimited" limit  
2.	"Unbounded" score  
3.	A mathematical asymptote that you intentionally model  
</code></pre></div></div>

<p>If your domain does not explicitly accept Infinity as a meaningful value, however, the right thing to do is to treat it exactly as you would treat NaN — reject it at the boundary, using <code class="language-plaintext highlighter-rouge">Double.isFinite()</code>. This is precisely why the <code class="language-plaintext highlighter-rouge">requireFinite</code> helper above checks for finiteness rather than for <code class="language-plaintext highlighter-rouge">isNaN</code> alone: it enforces the rule “no NaN, no Infinity, full stop” in a single line. In the rare cases in which you genuinely need to distinguish between NaN and Infinity, you can still do so by checking each separately, but for the great majority of code, the only useful distinction is finite versus not-finite.</p>

<p>The bug pattern to be alert to is the case where Infinity is tolerated accidentally — quietly admitted into the computation core because no one thought to reject it — and is then multiplied or scaled into a very large number that happens to look plausible at a glance. That is, in effect, how nonsense becomes confident-looking nonsense, and it is harder to catch downstream than NaN, because at least NaN propagates obviously.</p>

<h2 id="pattern-5-centralize-sanitization-but-do-not-lie">Pattern 5: Centralize sanitization, but do not lie</h2>

<p>There are also situations in which sanitization is genuinely required, particularly when dealing with messy external data over which you have no control. The two principles I would offer, having been bitten by both, are: do the sanitization once, in a centralised place, and be honest about what you actually did.</p>

<p>The dangerous form of sanitization is the one that looks reasonable at first glance:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">safe</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">x</span><span class="o">)</span> <span class="o">?</span> <span class="n">x</span> <span class="o">:</span> <span class="mf">0.0</span><span class="o">;</span></code></pre></figure>

<p>The problem with this pattern is that it converts “we do not know” into “definitely zero”, and zero is rarely a neutral value in any system that does arithmetic on it. A safer set of options is to either drop the offending datapoint outright (and to count it, so the volume of dropped values is observable), to mark the result as invalid using one of the result types described above, or to fall back to a documented default that has actual meaning in the domain — and, in any case, to log what happened so that the upstream cause can eventually be addressed.</p>

<p>A common example in aggregation is something like this:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="nf">averageFinite</span><span class="o">(</span><span class="kt">double</span><span class="o">[]</span> <span class="n">xs</span><span class="o">)</span> <span class="o">{</span>
    <span class="kt">double</span> <span class="n">sum</span> <span class="o">=</span> <span class="mf">0.0</span><span class="o">;</span>
    <span class="kt">int</span> <span class="n">n</span> <span class="o">=</span> <span class="mi">0</span><span class="o">;</span>

    <span class="k">for</span> <span class="o">(</span><span class="kt">double</span> <span class="n">x</span> <span class="o">:</span> <span class="n">xs</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">if</span> <span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">x</span><span class="o">))</span> <span class="o">{</span>
            <span class="n">sum</span> <span class="o">+=</span> <span class="n">x</span><span class="o">;</span>
            <span class="n">n</span><span class="o">++;</span>
        <span class="o">}</span>
    <span class="o">}</span>

    <span class="c1">// Honest answer: no valid data means undefined result.</span>
    <span class="k">if</span> <span class="o">(</span><span class="n">n</span> <span class="o">==</span> <span class="mi">0</span><span class="o">)</span> <span class="k">return</span> <span class="nc">Double</span><span class="o">.</span><span class="na">NaN</span><span class="o">;</span>

    <span class="k">return</span> <span class="n">sum</span> <span class="o">/</span> <span class="n">n</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>The honesty of the function consists in the last detail: when there is no valid data to average, the function returns NaN rather than zero. NaN is, in this case, the right answer — it is exactly what “undefined” means — and silently substituting zero would, once again, be a way of pretending to know something the function actually does not.</p>

<h2 id="third-party-libraries-when-nan-arrives-by-mail">Third-party libraries: when NaN arrives by mail</h2>

<p>Not every NaN is born in your own code. Some of them are delivered.</p>

<p>The most common cause of imported NaN is calling a math function that can legitimately return NaN for part of its domain — <code class="language-plaintext highlighter-rouge">Math.sqrt</code>, <code class="language-plaintext highlighter-rouge">Math.log</code>, and so on — and then forgetting that the moment you call out to such a function you have, in effect, crossed a boundary again, and the same boundary discipline applies. The fix is to validate the result immediately, at the point of crossing, while you still have full context about what was being computed:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">result</span> <span class="o">=</span> <span class="nc">Math</span><span class="o">.</span><span class="na">sqrt</span><span class="o">(</span><span class="n">userInput</span><span class="o">);</span>

<span class="c1">// JDK math functions and third-party libs can return NaN.</span>
<span class="c1">// Validate the output right away, at the point of crossing.</span>
<span class="n">requireFinite</span><span class="o">(</span><span class="n">result</span><span class="o">,</span> <span class="s">"sqrt result"</span><span class="o">);</span></code></pre></figure>

<p>The pattern generalises beyond JDK math: any time you call out to code you do not control — libraries, services, model inference endpoints, partner data feeds — the return value is best treated as a fresh boundary, with the same kind of validation you would apply to any other external input. The principle being preserved here is simply that the computation core gets to assume validated inputs, and any time something crosses into the core from elsewhere, the responsibility for validation falls on the crossing point.</p>

<h2 id="finding-the-first-nan-not-the-last-one">Finding the first NaN, not the last one</h2>

<p>There is a particular tragedy that tends to play out in long-lived systems, in which NaN is only detected at the very end of a long chain of transformations — in a report, on a dashboard, or in a downstream consumer — and the team then has to work backwards through ten transformations to find the operation that originally produced it. By that point, the NaN you are looking at is the smoke; the fire was several layers upstream, and the hard part of the bug is reconstructing how the smoke got to where it is now.</p>

<p>Two practical habits help with this:</p>

<h3 id="add-tripwire-assertions-in-debug-builds">Add “tripwire assertions” in debug builds</h3>

<p>In places where NaN should never legitimately exist, it is worth asserting that fact explicitly during development and in tests, so that the first appearance of NaN fails loudly rather than silently propagating:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">static</span> <span class="kt">void</span> <span class="nf">assertFinite</span><span class="o">(</span><span class="kt">double</span> <span class="n">x</span><span class="o">,</span> <span class="nc">String</span> <span class="n">name</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">if</span> <span class="o">(!</span><span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">x</span><span class="o">))</span> <span class="o">{</span>
        <span class="k">throw</span> <span class="k">new</span> <span class="nf">AssertionError</span><span class="o">(</span><span class="n">name</span> <span class="o">+</span> <span class="s">" became non-finite: "</span> <span class="o">+</span> <span class="n">x</span><span class="o">);</span>
    <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>This is particularly worthwhile after major computation steps in numerically sensitive algorithms, where the cost of the assertion is negligible and the benefit of catching the first bad value early is considerable.</p>

<h3 id="log-with-context-once-not-everywhere">Log with context once, not everywhere</h3>

<p>If the system needs observability into NaN-related rejections — and most production systems eventually do — the right place for that observability is at the boundary where the rejection happens, because that is where the original context still exists. An input adapter is a good example:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="nf">parseRate</span><span class="o">(</span><span class="nc">String</span> <span class="n">raw</span><span class="o">)</span> <span class="o">{</span>
    <span class="kt">double</span> <span class="n">x</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">parseDouble</span><span class="o">(</span><span class="n">raw</span><span class="o">);</span>
    <span class="k">if</span> <span class="o">(!</span><span class="nc">Double</span><span class="o">.</span><span class="na">isFinite</span><span class="o">(</span><span class="n">x</span><span class="o">))</span> <span class="o">{</span>
        <span class="c1">// log raw payload id, customer id, partner id, etc.</span>
        <span class="k">throw</span> <span class="k">new</span> <span class="nf">IllegalArgumentException</span><span class="o">(</span><span class="s">"rate must be finite"</span><span class="o">);</span>
    <span class="o">}</span>
    <span class="k">return</span> <span class="n">x</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>This is the point at which you still have access to the raw payload, the source identity, and any correlating identifiers; once the value has flowed through several layers of the application, all of that context tends to be lost. Logging at the boundary, rather than at the point of eventual symptom, is therefore both cheaper and more useful.</p>

<h2 id="a-small-nan-hygiene-checklist">A small NaN hygiene checklist</h2>

<p>By way of summary, the practices that have served me well in dealing with NaN in long-running systems are roughly these:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>1.	Use Double.isFinite at boundaries where values enter your system or cross layers
2.	Keep computation code clean; assume finite inputs inside the core
3.	Do not convert invalid to zero unless the domain definition says it is correct
4.	Prefer domain types over raw doubles when the value is not truly "a real number"
5.	When you must degrade gracefully, return an explicit invalid result, not a silent sentinel
6.	Instrument the boundary where you reject or drop invalids, so you can find the upstream cause
</code></pre></div></div>

<p>NaN, taken on its own terms, is not really an enemy. It is the floating-point system’s way of telling you that something invalid happened upstream and that the math, in good faith, could not produce a real-number answer. The defensive task is therefore not to suppress that signal everywhere it appears, but to listen to it where it first appears, deal with it deliberately at the boundary, and let the rest of the system rely on the contract that the boundary enforces. Validate at the edges, keep the core clean, and resist, as steadily as you can, the temptation to silently turn unknown into zero.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Computer Science" /><category term="Software Engineering" /><category term="Technology" /><category term="Series 4 - Floating Point Without Tears" /><category term="java" /><category term="floating-point" /><category term="ieee-754" /><category term="nan" /><category term="validation" /><category term="reliability" /><summary type="html"><![CDATA[Learn how to handle NaN and Infinity in Java without scattering if (isNaN) checks everywhere. Five practical patterns: boundary validation with Double.isFinite(), result types, domain types, centralized sanitization, and detecting NaN at its source. Avoid Checkpoint Syndrome and keep your computation code clean.]]></summary></entry><entry><title type="html">A quiet rebuild: assets, webcmd, and accessibility</title><link href="https://systemhalted.in/2026/01/03/quiet-rebuild-assets-webcmd-accessibility/" rel="alternate" type="text/html" title="A quiet rebuild: assets, webcmd, and accessibility" /><published>2026-01-03T00:00:00+00:00</published><updated>2026-01-03T00:00:00+00:00</updated><id>https://systemhalted.in/2026/01/03/quiet-rebuild-assets-webcmd-accessibility</id><content type="html" xml:base="https://systemhalted.in/2026/01/03/quiet-rebuild-assets-webcmd-accessibility/"><![CDATA[<p>Over the last day or so, I made a round of changes to this site that will not look like much from the outside, but that I think materially improve how it loads, how it behaves, and how it feels to use — especially for readers who navigate by keyboard or rely on assistive technology. None of this is glamorous work, but the kind of unglamorous maintenance that quietly removes friction is, in my experience, often the thing that makes a site usable over the long run. What follows is a short walkthrough of what changed and why I thought it was worth doing.</p>

<h2 id="1-consolidated-assets-into-one-place">1) Consolidated assets into one place</h2>

<p>The site had grown to keep static files in two different locations — <code class="language-plaintext highlighter-rouge">public/</code> and <code class="language-plaintext highlighter-rouge">assets/</code> — and the inconsistency had begun to cause exactly the sort of small problems that consistency is supposed to prevent: occasional broken paths, references that pointed to the wrong directory, and a small but real amount of cognitive overhead every time I had to remember which folder a particular file lived in.</p>

<p>I have now merged everything into <code class="language-plaintext highlighter-rouge">assets/</code>. CSS, JavaScript, and the favicon files have all moved over from <code class="language-plaintext highlighter-rouge">public/</code>, every template has been updated to reference <code class="language-plaintext highlighter-rouge">/assets/...</code>, and the web manifest along with the webcmd page have been corrected to match. The reader-facing benefit is mostly negative — fewer broken resources where there is no good reason for any to break — but the structural simplification also makes future maintenance easier, which I expect will matter more over time than any single fix in this round.</p>

<h2 id="2-modernized-the-favicon-setup">2) Modernized the favicon setup</h2>

<p>While I was tidying up <code class="language-plaintext highlighter-rouge">assets/</code>, I also took the opportunity to modernise the favicon. The site now serves an SVG favicon as the primary asset, with the old ICO file still in place as a fallback for older browsers that do not yet handle SVG icons gracefully. The <code class="language-plaintext highlighter-rouge">&lt;link rel="icon"&gt;</code> tags in the templates were updated accordingly. SVG is crisp at any size and looks visibly sharper on modern displays, while the ICO fallback preserves compatibility for the small but persistent set of browsers that still need it.</p>

<h2 id="3-webcmd-was-modernised">3) Webcmd was modernised</h2>

<p>The <code class="language-plaintext highlighter-rouge">/webcmd/</code> page is still the command-line interface to the site that it always was, but it had drifted out of sync with the rest of the site in a few small ways. It is now using the default site layout and theme, which means it inherits the Nord palette and reads consistently with everything else. The help output, which was previously a wall of text, is now properly semantic — lists and headings rather than line-by-line plaintext — which makes it easier to scan and renders in two columns on desktop while collapsing sensibly on mobile.</p>

<p>A couple of smaller fixes also went in. The <code class="language-plaintext highlighter-rouge">find</code> command, which had quietly been listed under the wrong section, is now grouped with the other Searches commands where it belongs. The navigation commands (<code class="language-plaintext highlighter-rouge">ph</code>, <code class="language-plaintext highlighter-rouge">p</code>, <code class="language-plaintext highlighter-rouge">pi</code>, <code class="language-plaintext highlighter-rouge">pr</code>) now use relative URLs, which means they continue to work as expected when I am testing locally on <code class="language-plaintext highlighter-rouge">localhost</code> — previously they would silently rewrite to the production host, which made local testing more annoying than it had any reason to be.</p>

<h2 id="4-accessibility-pass-wcag-oriented">4) Accessibility pass (WCAG-oriented)</h2>

<p>I also did a focused accessibility sweep across the main site templates, with WCAG 2.1 AA as the target — the <code class="language-plaintext highlighter-rouge">jsgames/</code> directory is excluded for now, since it is a different problem with a different set of constraints.</p>

<p>The work was less about adding any one big feature and more about closing a number of small gaps. There is now a “Skip to content” link at the top of every page, and a proper <code class="language-plaintext highlighter-rouge">&lt;main&gt;</code> landmark wrapping the primary content, both of which make keyboard and screen-reader navigation considerably faster. The sidebar toggle correctly updates <code class="language-plaintext highlighter-rouge">aria-expanded</code> and is now operable from the keyboard rather than only by mouse. The search overlay now traps focus while it is open and restores focus to the original element when it is closed, which is what a modal dialog should do but which my old implementation was not doing. The “Annotate me” control, which had been a clickable <code class="language-plaintext highlighter-rouge">&lt;span&gt;</code> for historical reasons, is now a real <code class="language-plaintext highlighter-rouge">&lt;button&gt;</code>. And the focus styles across the site have been tightened up so that keyboard users can actually see where they are at any given time.</p>

<p>The cumulative effect, for readers using assistive technology, should be noticeably more predictable behaviour throughout the site, and a meaningful reduction in the number of places where keyboard navigation hits an unexpected dead end.</p>

<h2 id="5-reduced-disqus-noise-on-non-post-pages">5) Reduced Disqus noise on non-post pages</h2>

<p>Disqus comment-count scripts were, until this round, being loaded on every page of the site, including pages that do not and never will have comments. They are now only loaded on posts that explicitly allow comments. This means there is less third-party JavaScript running on the home page, archive pages, and other non-post views, which both improves page-load performance modestly and reduces the slightly disorienting experience of seeing comment-related widgets briefly flicker on pages that have no comments to count.</p>

<h2 id="6-new-documentation">6) New documentation</h2>

<p>Finally, in the interest of keeping all of the above sustainable rather than letting it bit-rot, I wrote a couple of internal documents to capture the conventions I have adopted. <code class="language-plaintext highlighter-rouge">docs/webcmd.md</code> explains how the command engine works and how to add new commands without re-learning the system every time. <code class="language-plaintext highlighter-rouge">docs/accessibility.md</code> captures the accessibility conventions I am now trying to maintain, along with a small checklist of things to verify when adding new templates. The README has been updated to point to both, so that next-me, or anyone else who eventually pokes at the codebase, has a fighting chance of doing it correctly.</p>

<hr />

<h3 id="in-short">In short</h3>

<p>Taken individually, none of these changes is a headline. Taken together, however, they leave the site noticeably more consistent, more accessible, and easier to extend — which is, I think, what most maintenance work ought to look like when it is going well.</p>

<p>If you notice anything that looks broken or behaves oddly after this round of changes, please do let me know. Otherwise, I will keep working through the small stuff in the background, on the assumption that the cumulative result of doing so over time tends to be worth more than any single big feature would have been.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Personal Essays" /><category term="Technology" /><category term="jekyll" /><category term="webcmd" /><category term="accessibility" /><category term="ux" /><category term="maintenance" /><summary type="html"><![CDATA[Over the last day or so, I made a round of changes to this site that will not look like much from the outside, but that I think materially improve how it loads, how it behaves, and how it feels to use — especially for readers who navigate by keyboard or rely on assistive technology. None of this is glamorous work, but the kind of unglamorous maintenance that quietly removes friction is, in my experience, often the thing that makes a site usable over the long run. What follows is a short walkthrough of what changed and why I thought it was worth doing.]]></summary></entry><entry><title type="html">Revisiting India’s Post-Harvest Supply Chain (2011 → 2026)</title><link href="https://systemhalted.in/2026/01/03/revisiting-post-harvest-supply-chain-2011-2026/" rel="alternate" type="text/html" title="Revisiting India’s Post-Harvest Supply Chain (2011 → 2026)" /><published>2026-01-03T00:00:00+00:00</published><updated>2026-01-03T00:00:00+00:00</updated><id>https://systemhalted.in/2026/01/03/revisiting-post-harvest-supply-chain-2011-2026</id><content type="html" xml:base="https://systemhalted.in/2026/01/03/revisiting-post-harvest-supply-chain-2011-2026/"><![CDATA[<p>In April 2011, I wrote a short post pointing at a problem that has stayed with me ever since: India’s price signals tend to die on the way back to the farm. The original post is still up at <a href="https://systemhalted.in/2011/04/26/whats-wrong-with-our-post-harvest-agricultural-supply-chain/">What’s wrong with our post-harvest agricultural supply chain?</a>, and it was, in honesty, more of a finger pointed at a wound than a worked argument.</p>

<p>The wound it pointed at had been described well in an <em>Economic Times</em> editorial titled <a href="https://economictimes.indiatimes.com/opinion/et-editorial/the-pm-gets-it-right/articleshow/7499198.cms">“The PM gets it right” (Feb 15, 2011)</a>. The diagnosis there was simple and, I think, still essentially correct: we had modernised inputs but not marketing, and what existed between the farmer and the consumer was an inefficient chain in which retail price spikes rarely sent any of that upside back to the farm. The editorial was making a policy argument, but underneath it was an economics one — that the marketing layer was, on balance, doing more harm to the producer than the production layer was doing good.</p>

<p>Fifteen years later, I want to revisit that post with newer facts and a clearer view of what has changed and what has not. A fair amount of policy has happened since then, and a fair amount of physical infrastructure has been built; whether either of these has reached the smallest farmer in the chain is the harder question, and the one I want to think about here.</p>

<h2 id="where-the-value-leaks">Where the value leaks</h2>

<p>The way I have come to think about India’s post-harvest problem is as a collision between two things that do not get along: produce that decays quickly, and a chain that coordinates poorly. Most of the country’s marketed agricultural output passes through a long, multi-step path — harvesting, sorting, grading, transport, wholesale, retail — and each step adds time, friction, and another opportunity for the farmer’s bargaining position to deteriorate. Because the produce itself is decaying with every hour spent in the chain, the side with the least leverage, which is almost always the farmer, has the strongest incentive to settle quickly, on whatever terms are available.</p>

<p>Four chokepoints, in particular, decide how much value reaches the producer. The first is <strong>time</strong>, in the most physical sense: perishable produce punishes delay, and any link in the chain that adds hours adds losses. The second is <strong>scale</strong>, because a single farmer with a single field has very little leverage when negotiating with aggregators, traders, or retail buyers, while a collective with many fields and a shared facility has meaningfully more. The third is <strong>credit</strong>, since being able to wait — to not sell on the day of harvest at whatever price the market is offering — is fundamentally a financial capability, and a farmer without access to short-term finance is, in practice, a price-taker. The fourth is <strong>information</strong>, because opaque price signals get manipulated, and even where transparency exists it is uneven across mandis, states, and crops.</p>

<p>Back in 2011, I quoted a line from that editorial that I think is still worth repeating, because it captures all four of these in a single sentence: the linkage between the farmer and the consumer is inefficient, wasteful, and subject to manipulation, so shortages trigger hoarding and price spikes at the consumer end without sending those higher prices back to the farmer. The economic point underneath that sentence is unkind but accurate. When the price signal does not reach the farm, the incentive to invest in better acreage, better inputs, or better husbandry erodes, and the long-run consequence is lower productivity than we should otherwise be capable of.</p>

<p>So what has actually changed between 2011 and 2026? There is enough to take seriously, and not enough yet to be complacent about. The next sections walk through what I think are the five most consequential changes — what each is, what it has and has not done, and where it sits relative to the chokepoints described above.</p>

<p>If you grant the four chokepoints described above, then it follows that perishables are not really being bought and sold in the way other goods are; they are being raced against spoilage, and most of what we call the “post-harvest system” is really an attempt to manage that race. Cold chain, warehousing, credit, and transparent markets are, on close inspection, all doing the same underlying work — they are buying time, either physically by slowing decay or financially by reducing the pressure to sell at any price today.</p>

<p>That, viewed in this way, is the main story of India’s post-harvest sector since 2011. We have begun, at significant scale though still unevenly, to build and to finance time. The five sections that follow are the five places where I think this is most visible.</p>

<h2 id="change-1-we-started-paying-for-the-boring-parts">Change 1: We started paying for the boring parts</h2>

<p>The Agriculture Infrastructure Fund (AIF) is a government financing facility launched in 2020-21 to support post-harvest and farm-gate infrastructure through interest subvention and credit guarantee support. The instrument is worth dwelling on for a moment, because the choice to attack the problem with a financing facility — rather than with another round of input subsidy — is itself a quiet acknowledgement that the bottleneck has shifted from the farm to everything that happens after it.</p>

<p>As of June 30, 2025, the Press Information Bureau (PIB) reported ₹66,310 crore sanctioned under AIF for 1,13,419 projects, mobilising ₹1,07,502 crore of investment, including 2,454 cold storage projects.</p>

<p>This is not a philosophical shift so much as a cash-flow one, and supply chains, for all their physical hardware, ultimately run on cash flow. If a sorting yard, a small cold room, or a pack-house cannot be built because the cooperative or entrepreneur behind it cannot get five-year money on reasonable terms, the fact that we know cold chain is good for the country is of no use to anyone.</p>

<h2 id="change-2-cold-chain-scaled-and-policy-got-more-specific">Change 2: Cold chain scaled, and policy got more specific</h2>

<p>The Ministry of Food Processing Industries (MoFPI) runs the Integrated Cold Chain and Value Addition Infrastructure (ICCVAI) scheme under the Pradhan Mantri Kisan Sampada Yojana (PMKSY).</p>

<p>As of June 2025, 395 integrated cold chain projects had been approved since 2008, with 291 operational, creating preservation capacity of 25.52 lakh metric tonnes (LMT) per year and processing capacity of 114.66 LMT per year. MoFPI also notes a key policy shift in June 2022: support for fruit and vegetable cold chain projects under that scheme component was discontinued, and the sector was shifted to Operation Greens.</p>

<p>In plain terms, the government has stopped pretending that every crop has the same bottlenecks. Grains, oilseeds, fruits, and vegetables have very different storage curves, very different price cycles, and very different value chains, and a single instrument was never going to serve all of them well. Splitting fruits and vegetables out into a more specialised programme is overdue, and is the sort of unglamorous, mid-level policy adjustment that does not make headlines but probably matters more than most things that do.</p>

<p>For a farmer growing perishables, cold chain is what turns the choice from “sell today or lose everything” into “sell when the price is reasonable” — a small change in framing that completely changes the bargaining position of the producer, and is, in fact, the most direct attack on the perishability chokepoint that any policy lever can deliver.</p>

<h2 id="change-3-markets-became-more-digital-and-more-visible">Change 3: Markets became more digital, and more visible</h2>

<p>The electronic National Agriculture Market (e-NAM) integrates regulated wholesale markets (mandis) into an online trading platform.</p>

<p>PIB reported that 1,522 mandis were integrated as of June 30, 2025, with 1,79,41,613 farmers and 4,518 Farmer Producer Organisations (FPOs) registered, and total traded value of ₹4,39,941 crore recorded on the platform.</p>

<p>If 2011 was about price signals being weak, then e-NAM is the most credible attempt to date to strengthen them. A digital common market, in a country with the geographical and linguistic spread of India, matters more than its physical equivalent ever could, because it lets a buyer in one state discover a price in another without either of them needing to travel, and because it exposes the spread between mandis to the producer in a way that previously sat with traders alone.</p>

<p>It is worth being honest about what this can and cannot do, however. A stronger price signal does not automatically fix the physical chain underneath it. A dashboard, however well-designed, cannot refrigerate produce, and digital trading does not, by itself, move a truck across a state line. What e-NAM is good at is reducing one specific chokepoint — information — and that is enough to make it worthwhile, but it cannot reasonably be expected to do work that other parts of the system have to do.</p>

<h2 id="change-4-farmer-collectivisation-moved-from-slogan-to-infrastructure">Change 4: Farmer collectivisation moved from slogan to infrastructure</h2>

<p>A Farmer Producer Organisation (FPO) is a farmer collective that can aggregate produce, negotiate, and invest in shared capabilities.</p>

<p>The “Formation and Promotion of 10,000 FPOs” scheme hit the 10,000 milestone by Feb 2025, according to PIB. The same release describes equity grants and credit guarantee cover supporting thousands of FPOs.</p>

<p>This matters more than the headline number suggests, because it is the most direct assault on the scale chokepoint described earlier. A single farmer is, by virtue of being one farmer, forced to accept the chain as it is — they cannot afford a sorting line, they cannot finance a cold room, and they cannot threaten to walk away from a buyer because they have nowhere else for their crop to go. A collective changes all three of those conditions simultaneously: it can build shared infrastructure that no individual member could afford, it can absorb buyer-side delays because it is not financially fragile in the same way, and it can negotiate as a credible counterparty rather than as a price-taker.</p>

<p>Produce handled by an FPO can therefore be graded, packed, stored, and sold with leverage that no individual farmer would have on their own — same crop, same season, but a meaningfully different position in the chain.</p>

<h2 id="change-5-storage-plus-credit-got-sharper">Change 5: Storage plus credit got sharper</h2>

<p>If, in 2011, the farmer’s biggest enemy was forced timing, then by 2026 the problem has slowly mutated into a different one: whether waiting can be financed at all. Storage, in physical terms, has been built; what was missing for a long time was a way to convert that storage into liquidity for the farmer who owned the produce sitting in it.</p>

<p>The Warehousing Development and Regulatory Authority (WDRA) oversees warehousing regulation and electronic warehouse receipt systems, and a Parliamentary Standing Committee report notes the steady growth of pledge finance against electronic Negotiable Warehouse Receipts (eNWRs). The same report notes the launch on 04-03-2024 of e-Kisan Upaj Nidhi, a digital gateway developed by WDRA in association with NABARD (National Bank for Agriculture and Rural Development) and a task force in SBI (State Bank of India), to connect eNWR with onboarded banks.</p>

<p>Of all the changes since 2011, this is the most direct antidote to the original problem, because if a farmer can store and borrow against the stored produce, they are no longer forced to sell at the worst possible moment. The eNWR-plus-credit stack is, in effect, the financial glue that makes the physical investment in cold chain and warehousing actually reach the producer rather than the trader.</p>

<h2 id="the-uncomfortable-part-loss-is-still-huge">The uncomfortable part: loss is still huge</h2>

<p>Even with better financing, more cold chain, more digital markets, and stronger farmer collectives, the scale of loss in the system remains uncomfortably large.</p>

<p>A 2024 policy brief by the Indian Council for Research on International Economic Relations (ICRIER) cites a NABARD Consultancy Services (NABCONS) 2020-2022 study estimating food loss in India at about ₹1.53 trillion (USD 18.5 billion) annually due to post-harvest losses (PHL). The brief also makes the broader argument that, on the margin, reducing PHL is often more cost-effective than producing more food only to lose more of it.</p>

<p>So we have, in fairness, built much of the scaffolding that the 2011 critique implicitly demanded. Yet we are still losing value at industrial scale, and the gap between scaffolding and outcomes is where the next decade of work has to happen — not in announcing new schemes, but in making the schemes that already exist actually reach the smallest producer in the chain.</p>

<h2 id="a-2026-reading">A 2026 reading</h2>

<p>The 2011 editorial argued that policy must take marketing as seriously as production. I agreed with that then, and I still agree with it now, but with a slight update to the framing. India’s post-harvest problem is best understood as a systems problem, in which incentives, physics, and finance combine — usually against the weakest player in the chain. It is rarely a single villain that captures the value; it is the cumulative friction of a chain in which every link is a little tilted against the producer.</p>

<p>Each of the four chokepoints I named earlier maps, more or less, onto one of the policy levers that has emerged in the years since 2011. Perishability — the time problem — is being addressed by cold chain investment under ICCVAI/PMKSY and, increasingly, by Operation Greens. The scale problem is being addressed by the FPO programme and the slow consolidation of farmer collectives. The credit problem is being addressed by the AIF on the infrastructure side and by the WDRA’s eNWR-plus-e-Kisan Upaj Nidhi stack on the working-capital side. And the information problem is being addressed, imperfectly but steadily, by e-NAM. None of these levers is a complete solution on its own, but together they describe a more coherent post-harvest stack than India had at any point before 2011.</p>

<p>The honest test, however, is not whether the schemes exist; it is whether the smallest farmer in the chain still has to make the panic-sale choice on the day of harvest. As long as the answer for too many of them is yes, the work the 2011 editorial called for is unfinished, regardless of how good the dashboards look. If, fifteen years from now, the farmer finally has the same thing the consumer has had all along — a real choice about when and to whom to sell — then the work begun in 2020-21 will have done what it set out to do. We are not there yet, but for the first time in a long while, we are at least pointed in the right direction.</p>

<hr />

<h2 id="references-links">References (links)</h2>

<ol>
  <li>
    <p>Original 2011 post on SystemHalted:<br />
<a href="https://systemhalted.in/2011/04/26/whats-wrong-with-our-post-harvest-agricultural-supply-chain/">https://systemhalted.in/2011/04/26/whats-wrong-with-our-post-harvest-agricultural-supply-chain/</a></p>
  </li>
  <li>
    <p>Quoted editorial (2011, original link from my post):<br />
<a href="https://economictimes.indiatimes.com/opinion/et-editorial/the-pm-gets-it-right/articleshow/7499198.cms">https://economictimes.indiatimes.com/opinion/et-editorial/the-pm-gets-it-right/articleshow/7499198.cms</a></p>
  </li>
  <li>
    <p>PIB note on Agriculture Infrastructure Fund (AIF) status (as of 30 June 2025):<br />
<a href="https://www.pib.gov.in/PressNoteDetails.aspx?ModuleId=3&amp;NoteId=154999">https://www.pib.gov.in/PressNoteDetails.aspx?ModuleId=3&amp;NoteId=154999</a></p>
  </li>
  <li>
    <p>PIB release on e-NAM registrations and traded value (as of 30 June 2025):<br />
<a href="https://www.pib.gov.in/PressReleasePage.aspx?PRID=2151361">https://www.pib.gov.in/PressReleasePage.aspx?PRID=2151361</a></p>
  </li>
  <li>
    <p>PIB release on the 10,000 Farmer Producer Organisations (FPOs) milestone (Feb 28, 2025):<br />
<a href="https://pib.gov.in/PressReleasePage.aspx?PRID=2106913">https://pib.gov.in/PressReleasePage.aspx?PRID=2106913</a></p>
  </li>
  <li>
    <p>Integrated Cold Chain and Value Addition Infrastructure (ICCVAI) status note (PDF; includes June 2025 stats):<br />
<a href="https://static.pib.gov.in/WriteReadData/specificdocs/documents/2025/oct/doc20251029679501.pdf">https://static.pib.gov.in/WriteReadData/specificdocs/documents/2025/oct/doc20251029679501.pdf</a></p>
  </li>
  <li>
    <p>Parliamentary Standing Committee report (PDF; mentions eNWR pledge finance and e-Kisan Upaj Nidhi launch):<br />
<a href="https://sansad.in/getFile/lsscommittee/Consumer%20Affairs%2C%20Food%20and%20Public%20Distribution/18_Consumer_Affairs_Food_and_Public_Distribution_2.pdf?source=loksabhadocs">https://sansad.in/getFile/lsscommittee/Consumer%20Affairs%2C%20Food%20and%20Public%20Distribution/18_Consumer_Affairs_Food_and_Public_Distribution_2.pdf?source=loksabhadocs</a></p>
  </li>
  <li>
    <p>ICRIER Policy Brief 20 (PDF) summarising the NABCONS 2020-2022 loss estimate:<br />
<a href="https://icrier.org/pdf/Policy_Brief_20.pdf">https://icrier.org/pdf/Policy_Brief_20.pdf</a></p>
  </li>
  <li>
    <p>WDRA page describing e-Kisan Upaj Nidhi:<br />
<a href="https://wdra.gov.in/web/wdra/e-kisan-upaj-nidhi">https://wdra.gov.in/web/wdra/e-kisan-upaj-nidhi</a></p>
  </li>
</ol>

<hr />

<h2 id="notes">Notes</h2>

<h3 id="abbreviations-introduced-in-this-post">Abbreviations introduced in this post</h3>

<ul>
  <li><strong>AIF</strong>: Agriculture Infrastructure Fund</li>
  <li><strong>PIB</strong>: Press Information Bureau</li>
  <li><strong>MoFPI</strong>: Ministry of Food Processing Industries</li>
  <li><strong>PMKSY</strong>: Pradhan Mantri Kisan Sampada Yojana</li>
  <li><strong>ICCVAI</strong>: Integrated Cold Chain and Value Addition Infrastructure</li>
  <li><strong>LMT</strong>: lakh metric tonnes</li>
  <li><strong>e-NAM</strong>: electronic National Agriculture Market</li>
  <li><strong>Mandi</strong>: regulated wholesale agricultural market</li>
  <li><strong>FPO</strong>: Farmer Producer Organisation</li>
  <li><strong>WDRA</strong>: Warehousing Development and Regulatory Authority</li>
  <li><strong>eNWR</strong>: electronic Negotiable Warehouse Receipt</li>
  <li><strong>NABARD</strong>: National Bank for Agriculture and Rural Development</li>
  <li><strong>SBI</strong>: State Bank of India</li>
  <li><strong>NABCONS</strong>: NABARD Consultancy Services</li>
  <li><strong>ICRIER</strong>: Indian Council for Research on International Economic Relations</li>
  <li><strong>PHL</strong>: post-harvest losses</li>
</ul>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Politics &amp; Governance" /><category term="agriculture" /><category term="india" /><category term="supply-chain" /><category term="post-harvest" /><category term="cold-chain" /><category term="mandis" /><category term="farmers" /><category term="policy" /><summary type="html"><![CDATA[A 2026 revisit of a 2011 note: what has actually changed in India's post-harvest supply chain since 2011, and what still leaks value.]]></summary></entry><entry><title type="html">Hello, 2026: Shipping Hope in Small Commits</title><link href="https://systemhalted.in/2026/01/01/happy-new-year-2026/" rel="alternate" type="text/html" title="Hello, 2026: Shipping Hope in Small Commits" /><published>2026-01-01T00:00:00+00:00</published><updated>2026-01-01T00:00:00+00:00</updated><id>https://systemhalted.in/2026/01/01/happy-new-year-2026</id><content type="html" xml:base="https://systemhalted.in/2026/01/01/happy-new-year-2026/"><![CDATA[<p>Happy New Year. I have always liked New Year more than most calendar events, mostly because it is the one socially acceptable time of year to sit down and rethink your defaults in public. There is something quietly freeing about the fact that no one expects a ticket, a sprint plan, or a roadmap from a New Year reflection — what is asked for, at most, is a little honesty.</p>

<h2 id="what-actually-ran">What actually ran</h2>

<p>A year, in the end, does not care very much about intent. What it does pay attention to is what actually ran. You can mean well for months on end and still ship nothing of real value, and you can equally well ship one small thing each week and find, by the time December comes around, that you have quietly built up a pile of evidence you did not realise you were accumulating.</p>

<p>My goal for 2026, then, is not reinvention. I am old enough now to mistrust grand reinventions, which I have rarely seen survive contact with February. What I want instead is evidence — a steady, unspectacular sequence of small, honest commits, in code and in everything else.</p>

<h2 id="what-i-am-optimizing-for">What I am optimizing for</h2>

<p>What I do not want, on the other hand, is a year that looks impressive from a distance and feels hollow up close. I have had years like that before, and they leave very little behind that is worth keeping. What I want instead is a year in which the work is sturdy, the learning is deliberate, the writing is honest, and my attention — increasingly the scarcest resource of all — is mine to direct, rather than something rented out to whatever happens to be loud at the moment.</p>

<p>I would rather end the year with fewer open loops and more finished sentences than the other way around.</p>

<h2 id="building-without-worshipping-the-build">Building, without worshipping the build</h2>

<p>Engineers, I have noticed, tend to confuse motion for progress. Activity feels like virtue, busy easily passes for important, and the small thrill of being needed in several places at once does a remarkably good job of disguising itself as actual work. I have been guilty of this often enough to recognise it the moment it begins to happen.</p>

<p>This year I want more stillness around the work — less frantic context-switching, and more of the kind of deep, uninterrupted time in which an idea actually becomes real. Real, after all, is the only feature that users can actually use, and it is a feature that almost never emerges from a calendar full of fifteen-minute fragments.</p>

<h2 id="a-small-promise-to-myself">A small promise to myself</h2>

<p>A few specific commitments, in plain English. I want to read on purpose this year, rather than leaving it to the algorithm to decide what I think about. I want my learning to have a map, however rough — a sense of where I am going and why I am going there — and I want to keep writing even on the days when the mood for it has gone elsewhere, because craft, in my experience, is what is left over after motivation has left the room.</p>

<p>I also want to treat health as a prerequisite for all of the above, rather than as something I will get to once the work calms down. Work, I have learned the hard way, never calms down on its own; it has to be either kept in proportion deliberately, or accepted on its own terms.</p>

<p>I want to be ambitious without being brittle, which is to say I want to aim for the kind of progress that survives a bad day, a bad week, and the occasional bad month, rather than the kind of progress that depends on everything going well to even register.</p>

<p>And, on a more concrete note, I want to finally ship Consumption Backlog this year — and an iOS version of it, too, if I can find the time.</p>

<h2 id="closing-thoughts">Closing thoughts</h2>

<p>If you are reading this, my hope for you is that 2026 brings you, in some combination, three things: something to learn that changes how you see the world, someone to love who makes the days a little lighter, and something to build that makes you quietly proud when no one in particular is watching. Those are the three I have come to think matter most, in roughly that order, though the order has a way of shuffling depending on the year.</p>

<p>Happy New Year. To whatever extent one of those three is within reach today, that is probably the right place to start, and small is probably the right size to start at.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Personal Essays" /><category term="new-year" /><category term="reflection" /><category term="software-engineering" /><category term="writing" /><category term="learning" /><summary type="html"><![CDATA[A New Year note: small, consistent commits, and what I want 2026 to actually be.]]></summary></entry><entry><title type="html">Discipline First: A Trust Pipeline for AI-Assisted Coding</title><link href="https://systemhalted.in/2025/12/31/discipline-first-trust-pipeline-for-ai-assisted-coding/" rel="alternate" type="text/html" title="Discipline First: A Trust Pipeline for AI-Assisted Coding" /><published>2025-12-31T00:00:00+00:00</published><updated>2025-12-31T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/31/discipline-first-trust-pipeline-for-ai-assisted-coding</id><content type="html" xml:base="https://systemhalted.in/2025/12/31/discipline-first-trust-pipeline-for-ai-assisted-coding/"><![CDATA[<p>Vibe coding is not a software engineering paradigm. It’s a mood. Engineering is what makes it ship.</p>

<p>My core claim is simple: engineers who set up a task with clear instructions, a thin prototype, and hard guardrails tend to have a better experience with AI-assisted coding, and they tend to keep their good faith in the tools. Engineers who don’t, often walk away with confusion, rewrites, and a lingering sense that the agent is “untrustworthy.” And that’s why the same tool creates opposite stories, depending on who’s holding it.</p>

<p>This post is my framework, <strong><a href="https://github.com/systemhalted/DisciplineFirst">Discipline First: a trust pipeline for AI-assisted coding</a></strong>. It’s a small kit you can use immediately: an Agent Brief that makes intent hard to misread, guardrails that make failures visible early, and a one-week experiment that turns belief into evidence.</p>

<h2 id="the-axis-that-matters">The axis that matters</h2>

<p>The agent isn’t the methodology. Your engineering habits are.</p>

<p>I’m going to be deliberately boring about definitions, because the labels are less important than the axis. Whether you call it vibe coding, agentic coding, or AI-assisted coding, the same split shows up: disciplined delivery versus undisciplined delivery. The tools can draft code, refactor code, even propose architectures, but they can’t rescue a vague task from its own vagueness.</p>

<p>Discipline is what turns “the agent wrote something” into “the system changed, and we can explain why, prove it works, and undo it safely if it doesn’t.”</p>

<h2 id="four-engineers-walk-into-the-same-tool">Four engineers walk into the same tool</h2>

<p>And once you see it that way, four kinds of engineers show up around AI-assisted coding.</p>

<p>The <strong>Skeptic</strong> is driven by quality, security, and maintainability. They are not anti tool. They are pro standards. They will try these tools in a sandbox, or allow them under strict review, and they trust what they can validate through time-tested discipline: tests, contracts, architecture checks, and clean interfaces. Their posture is “prove it,” and their lingering doubt is usually about authorship. They suspect only human engineers can reliably meet that bar.</p>

<p>The <strong>Dismisser</strong> opts out early. Sometimes that’s reflexive, sometimes it’s reasoned: they’ve seen bad suggestions, security risks, legal uncertainty, vendor lock-in, or unreviewable diffs and they decided the trade is not worth it. Their posture is still “already decided,” but the <em>why</em> matters. You don’t convert a Dismisser by arguing about models or demos. You convert them by giving them control of the bar: let them define the quality gates, then run a small, measured experiment in their own codebase that either meets the bar or fails honestly.</p>

<p>The <strong>Viber</strong> loves speed. They ship fast, accept large diffs, and skip the guardrails that make code testable and observable. Their posture is “speed is truth.” To be fair, that posture has a place: spikes, prototypes, throwaway demos, learning a new stack. The problem is when the same vibe crosses the border into production. That’s where “it seems to work” quietly becomes regressions, mystery failures, and eroded trust. The point of Discipline First is not to shame exploration. It’s to prevent avoidable damage when the stakes are real.</p>

<p>The <strong>Disciplined Builder</strong> loves AI-assisted coding and still engineers hard. Small tasks, small diffs, acceptance criteria, tests, verification loops, rules files, and a security mindset. They do not care whether the code was written by a human or an agent. They care that it is explainable, reviewable, testable, and observable. Their posture is simple: trust is built.</p>

<p>The only difference between the Skeptic and the Builder is what they believe about that last mile. The Skeptic thinks only humans can deliver it consistently. The Builder has learned how to make the agent earn it.</p>

<h2 id="discipline-first-is-xp-with-a-faster-pair">Discipline First is XP with a faster pair</h2>

<p>Discipline First is not a new religion. It is <strong>Extreme Programming</strong> adapted to a world where your pair can write code at absurd speed. Extreme Programming starts with <strong>Values</strong>, because Values guide <strong>Principles</strong>, and Principles are what make <strong>Practices</strong> hold up under pressure.</p>

<p>The Values are <strong>Communication, Simplicity, Feedback, Courage, and Respect</strong>.</p>

<p>Communication becomes explicit intent: the Agent Brief and rules files are how you communicate without mind reading. Simplicity becomes a principle you enforce: assume simplicity, slice work into small tasks, keep diffs small, keep releases small. Feedback becomes rapid and objective: failing tests and continuous integration tell the truth early. Courage becomes disciplined restraint: stop the agent when it starts guessing, delete generated code when it bloats, and ship in increments so reality can correct you fast. Respect becomes engineering for humans: keep standards non negotiable, make changes transparent, and leave behind code that future people can understand, test, observe, and safely change.</p>

<p>From those Values and Principles, the Practices follow naturally: pair programming with the agent as the pair and the human as the driver, test driven development as the spec the agent must satisfy, continuous integration as the always on referee, and small releases as the safest way to turn speed into reliability.</p>

<h2 id="the-discipline-first-kit">The Discipline First kit</h2>

<h3 id="1-the-agent-brief">1) The Agent Brief</h3>

<p>Think of the Agent Brief as a PRD that’s small enough to fit in your head, but sharp enough that the agent can’t “creatively interpret” it.</p>

<ol>
  <li>Goal</li>
  <li>Non-goals</li>
  <li>Constraints</li>
  <li>Interfaces</li>
  <li>Acceptance criteria</li>
  <li>Risks</li>
  <li>Test plan</li>
  <li>Observability</li>
  <li>Dependencies</li>
  <li>Recovery and blast radius</li>
</ol>

<p>Here’s a concrete example (for one service):</p>

<p><strong>Goal:</strong> Add rate limiting to <code class="language-plaintext highlighter-rouge">POST /payments</code> to reduce abuse and protect downstream dependencies.<br />
<strong>Non-goals:</strong> No UI changes. No new auth scheme. No changes to other endpoints.<br />
<strong>Constraints:</strong> Must not change the public API contract. Must keep p95 latency impact under 5%.<br />
<strong>Interfaces:</strong> <code class="language-plaintext highlighter-rouge">POST /payments</code> only; configuration via env var <code class="language-plaintext highlighter-rouge">PAYMENTS_RATE_LIMIT_RPS</code>.<br />
<strong>Acceptance criteria:</strong> Requests above limit return <code class="language-plaintext highlighter-rouge">429</code> with standard error body; limits are per-customer; logs include rate-limit decision.<br />
<strong>Risks:</strong> False positives blocking legit traffic; misconfigured limits; uneven behavior across instances.<br />
<strong>Test plan:</strong> Add functional tests for 200, 429, and boundary conditions; include concurrency test; all tests deterministic in CI.<br />
<strong>Observability:</strong> Emit metric <code class="language-plaintext highlighter-rouge">payments.rate_limited.count</code>; structured log <code class="language-plaintext highlighter-rouge">rate_limit_decision</code> with customer id hash; dashboard alert on spikes.<br />
<strong>Dependencies:</strong> Redis (or in-memory) limiter library already approved; no new infrastructure.<br />
<strong>Recovery and blast radius:</strong> Feature flag the limiter; default off; rollback is flag flip; document emergency disable procedure.</p>

<p>Then three hard rules.</p>

<ol>
  <li>Do not change public APIs unless explicitly permitted.</li>
  <li>Prefer the smallest diff that can satisfy the brief.</li>
  <li>Stop and ask when uncertain.</li>
</ol>

<h3 id="2-guardrails">2) Guardrails</h3>

<p>Not vibes. Guardrails.</p>

<p>Unit tests and functional tests. Contract checks. Architecture checks. Code review. Small tasks. CI as referee.</p>

<p>If an agent can ship code faster than a human, your only sane response is to make the truth show up faster than the code. We have already seen public “trust cliff” moments when autonomy meets weak guardrails.<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup><sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>Small diffs are not about being precious. They are about control. A small change is easier to review, easier to reason about, easier to test, and easier to roll back. Agents tend to expand scope unless you constrain them, so “small diffs” is both a safety boundary and a way to keep context from exploding.</p>

<h3 id="3-durable-instructions">3) Durable instructions</h3>

<p>Modern agentic tooling is quietly reinventing the same old idea: durable project instructions.</p>

<p>Rules files in agentic IDEs make behavior persistent across prompts.<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup><br />
Repo-level instruction files like AGENTS.md make “how to behave here” predictable.<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup><sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup><br />
For conventions that should survive editors and IDEs, EditorConfig gives you portable, version controlled style rules.<sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup><sup id="fnref:7"><a href="#fn:7" class="footnote" rel="footnote" role="doc-noteref">7</a></sup><sup id="fnref:8"><a href="#fn:8" class="footnote" rel="footnote" role="doc-noteref">8</a></sup></p>

<p>Practical rule of thumb:</p>

<p>Use EditorConfig for formatting and style that must survive editors and IDEs.<br />
Use Rules files for tool-specific behavior. What to include in context, how to respond, what not to touch.<br />
Use AGENTS.md for repo-wide agent behavior. Setup commands, test commands, conventions, safety boundaries.</p>

<p>If you only do one thing, do AGENTS.md plus your Agent Brief template. That creates a stable baseline even when prompts change.</p>

<h2 id="a-one-week-experiment-tests-only">A one-week experiment (tests only)</h2>

<p>Pick one service. Pick one real user workflow in that service. Then write missing functional tests until the behavior is pinned down.</p>

<p>You will know it’s working when:</p>

<p>The tests fail for the wrong behavior and pass for the right behavior.<br />
They run repeatedly without flakes.<br />
They do not depend on environment quirks or real external systems.<br />
CI stays green and the suite stays fast enough to run often.<br />
Any production code change made only for testability is small and justified.<br />
A human reviewer can read the tests as a spec and agree they capture real behavior.</p>

<p>Measure the boring things: how many rewrites the agent needed, how many times you had to restate intent, how large the diffs got, how much review effort it took, and how quickly you got to “tests green.”</p>

<h2 id="when-discipline-first-is-overkill-and-when-it-breaks">When Discipline First is overkill (and when it breaks)</h2>

<p>Discipline First is the safest on ramp for production work. It is not mandatory ceremony for everything.</p>

<p>It is overkill for throwaway prototypes, exploratory spikes, and one-off scripts where the cost of failure is low and the code has no future. In those contexts, “vibes first” can be a valid way to learn quickly.</p>

<p>Discipline First breaks down in predictable ways:</p>

<p>The Brief rots. Intent changes but the kit does not.<br />
Tests become performative. They pass but don’t pin behavior.<br />
Guardrails turn into friction without signal. Slow, flaky, or mis-scoped checks.<br />
The agent is allowed to widen scope. Diffs balloon, review becomes theater.</p>

<p>The fix is the same as always: tighten the slice, keep the checks honest, and scale the process to the risk.</p>

<h2 id="why-measure-at-all">Why measure at all</h2>

<p>Because productivity gains are not guaranteed.</p>

<p>One of the clearest public data points so far is a randomized controlled trial from METR (published July 2025) studying experienced open source developers working in codebases they already knew. When AI tools were allowed, developers expected big speedups and later felt faster, but measured completion time was slower on average in that setting.<sup id="fnref:9"><a href="#fn:9" class="footnote" rel="footnote" role="doc-noteref">9</a></sup><sup id="fnref:10"><a href="#fn:10" class="footnote" rel="footnote" role="doc-noteref">10</a></sup><sup id="fnref:11"><a href="#fn:11" class="footnote" rel="footnote" role="doc-noteref">11</a></sup></p>

<p>That result does not mean “AI slows everyone down.” Tools and workflows change fast, task types vary wildly, and many teams report real gains. It means your intuition is not an instrument. Discipline First is not “trust the agent.” It’s “instrument the work.”</p>

<h2 id="close-the-loop-for-each-persona">Close the loop for each persona</h2>

<p>For the Skeptic: run one Discipline First experiment on tests only in a sandboxed branch.</p>

<p>For the Dismisser: pick one internal task, define your own quality gates, and let the experiment decide.</p>

<p>For the Viber: no big diffs, and every change must come with a failing test first.<sup id="fnref:12"><a href="#fn:12" class="footnote" rel="footnote" role="doc-noteref">12</a></sup></p>

<p>For the Builder: make discipline the default - publish the Agent Brief template, standardize rules files, and optimize the workflow so the safest path is the easiest path.</p>

<h2 id="sources-and-footnotes">Sources and Footnotes</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Replit incident reporting (Business Insider): https://www.businessinsider.com/replit-ceo-apologizes-ai-coding-tool-delete-company-database-2025-7 <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>Replit CEO statement (X): https://x.com/amasad/status/1943062428929892384 <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>Cursor Rules documentation: https://cursor.com/docs/context/rules <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>OpenAI Codex guidance for AGENTS.md: https://developers.openai.com/codex/guides/agents-md/ <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>OpenAI “Introducing Codex” (see “How Codex Works”): https://openai.com/index/introducing-codex/ <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:6">
      <p>EditorConfig homepage: https://editorconfig.org/ <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:7">
      <p>EditorConfig specification: https://spec.editorconfig.org/ <a href="#fnref:7" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:8">
      <p>JetBrains IDE support for EditorConfig: https://www.jetbrains.com/help/idea/editorconfig.html <a href="#fnref:8" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:9">
      <p>METR study write-up (July 2025): https://metr.org/blog/2025-07-10-early-2025-ai-experienced-os-dev-study/ <a href="#fnref:9" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:10">
      <p>METR paper on arXiv: https://arxiv.org/abs/2507.09089 <a href="#fnref:10" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:11">
      <p>Reuters coverage of the METR study: https://www.reuters.com/business/ai-slows-down-some-experienced-software-developers-study-finds-2025-07-10/ <a href="#fnref:11" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:12">
      <p>Martin Fowler on TDD: https://martinfowler.com/articles/is-tdd-dead/ <a href="#fnref:12" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Software Engineering" /><category term="ai-assisted-coding" /><category term="agentic-coding" /><category term="vibe-coding" /><category term="extreme-programming" /><category term="xp" /><category term="tdd" /><category term="continuous-integration" /><category term="testing" /><category term="guardrails" /><category term="engineering-discipline" /><summary type="html"><![CDATA[AI-assisted coding is a force multiplier. This post argues that disciplined engineering practices, rooted in Extreme Programming, are what make agentic workflows trustworthy and shippable.]]></summary></entry><entry><title type="html">Part 5: NaN, Infinity and the Rules of Weird Math</title><link href="https://systemhalted.in/2025/12/25/nan-infinity-weird-math-rules/" rel="alternate" type="text/html" title="Part 5: NaN, Infinity and the Rules of Weird Math" /><published>2025-12-25T00:00:00+00:00</published><updated>2025-12-25T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/25/nan-infinity-weird-math-rules</id><content type="html" xml:base="https://systemhalted.in/2025/12/25/nan-infinity-weird-math-rules/"><![CDATA[<p><em>This post is part of my <a href="https://systemhalted.in/categories/#cat-series-4-floating-point-without-tears">Floating Point Without Tears</a> series on how Java numbers misbehave and how to live with them.</em></p>

<p>Floating point math is fast, useful, and occasionally haunted. Not philosophically, literally haunted, as in values that aren’t equal to themselves.</p>

<blockquote>
  <p><code class="language-plaintext highlighter-rouge">NaN != NaN</code> evaluates to <code class="language-plaintext highlighter-rouge">true</code></p>
</blockquote>

<p>IEEE 754 formalizes that haunting by defining special values that let computations continue while still signaling trouble. They look like broken math until you realize they’re doing damage control.</p>

<h2 id="why-special-values-exist-in-floating-point">Why Special Values Exist in Floating Point</h2>

<p>In Part 1 of this series<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>, we saw how floating-point numbers work: they use a fixed number of bits to represent the sign, exponent, and significand (mantissa). This representation has limits:</p>

<ul>
  <li><strong>Largest representable number</strong>: Around <code class="language-plaintext highlighter-rouge">1.8 × 10^308</code> for doubles (<code class="language-plaintext highlighter-rouge">Double.MAX_VALUE</code>)</li>
  <li><strong>Smallest positive normalized number</strong>: Around <code class="language-plaintext highlighter-rouge">2.2 × 10^-308</code> (<code class="language-plaintext highlighter-rouge">Double.MIN_NORMAL</code>)</li>
  <li><strong>Smallest positive nonzero number</strong>: Around <code class="language-plaintext highlighter-rouge">4.9 × 10^-324</code> (<code class="language-plaintext highlighter-rouge">Double.MIN_VALUE</code>)</li>
  <li><strong>Precision</strong>: Limited by machine epsilon (about 2.22 × 10^-16 near 1.0, i.e., Math.ulp(1.0) = the gap between 1.0 and the next larger representable double)</li>
</ul>

<p>But what happens when you compute something that <em>exceeds</em> these limits?</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">huge</span> <span class="o">=</span> <span class="mi">1</span><span class="n">e308</span><span class="o">;</span>
<span class="kt">double</span> <span class="n">overflow</span> <span class="o">=</span> <span class="n">huge</span> <span class="o">*</span> <span class="mi">10</span><span class="o">;</span>            <span class="c1">// Exceeds max value</span>
<span class="kt">double</span> <span class="n">gradual</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">MIN_NORMAL</span> <span class="o">/</span> <span class="mi">2</span><span class="o">;</span> <span class="c1">// Becomes subnormal (gradual underflow)</span>
<span class="kt">double</span> <span class="n">underflow</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">MIN_VALUE</span> <span class="o">/</span> <span class="mi">2</span><span class="o">;</span> <span class="c1">// Falls below min value → +0.0</span>
<span class="kt">double</span> <span class="n">undefined</span> <span class="o">=</span> <span class="mf">0.0</span> <span class="o">/</span> <span class="mf">0.0</span><span class="o">;</span>           <span class="c1">// Mathematically meaningless</span></code></pre></figure>

<p>IEEE 754 could have made these operations:</p>
<ol>
  <li>Throw exceptions (slow, interrupts computation)</li>
  <li>Wrap around to negative values (confusing, hides errors)</li>
  <li>Return arbitrary garbage (dangerous)</li>
</ol>

<p>Instead, it reserves special bit patterns in the exponent field to represent <em>infinity</em> and <em>NaN</em>. These aren’t normal numbers; they are sentinel values that signal “something unusual happened, but computation can continue.”</p>

<h3 id="the-bit-pattern-trick">The Bit Pattern Trick</h3>

<p>A double uses 11 bits for the exponent. IEEE 754 reserves special patterns for edge cases:</p>

<table>
  <thead>
    <tr>
      <th>Exponent bits</th>
      <th>Significand (fraction)</th>
      <th>Meaning</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>all 0s</td>
      <td>all zeros</td>
      <td>±0.0 (sign bit determines +/−)</td>
    </tr>
    <tr>
      <td>all 0s</td>
      <td>non-zero</td>
      <td>subnormal numbers</td>
    </tr>
    <tr>
      <td>1..2046</td>
      <td>any</td>
      <td>normal numbers</td>
    </tr>
    <tr>
      <td>all 1s (2047)</td>
      <td>all zeros</td>
      <td>±Infinity (sign bit determines +/−)</td>
    </tr>
    <tr>
      <td>all 1s (2047)</td>
      <td>non-zero</td>
      <td>NaN</td>
    </tr>
  </tbody>
</table>

<p>This means you can check for special values with simple bit operations - no exceptions, no branching overhead in critical inner loops. In Java you normally just use Double.isNaN(x) and Double.isInfinite(x), which are implemented efficiently under the hood.</p>

<h2 id="the-problem-what-should-math-return-when-it-breaks">The Problem: What Should Math Return When It Breaks?</h2>

<p>Now that we understand <em>why</em> special values exist (to handle edge cases without crashing), let’s see <em>when</em> they appear.</p>

<p>Consider calculating the average price change across a portfolio:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">totalChange</span> <span class="o">=</span> <span class="mf">0.0</span><span class="o">;</span>
<span class="kt">int</span> <span class="n">validStocks</span> <span class="o">=</span> <span class="mi">0</span><span class="o">;</span>

<span class="k">for</span> <span class="o">(</span><span class="nc">Stock</span> <span class="n">stock</span> <span class="o">:</span> <span class="n">portfolio</span><span class="o">)</span> <span class="o">{</span>
    <span class="kt">double</span> <span class="n">change</span> <span class="o">=</span> <span class="n">stock</span><span class="o">.</span><span class="na">getCurrentPrice</span><span class="o">()</span> <span class="o">-</span> <span class="n">stock</span><span class="o">.</span><span class="na">getPreviousPrice</span><span class="o">();</span>
    <span class="k">if</span> <span class="o">(</span><span class="n">isValidChange</span><span class="o">(</span><span class="n">change</span><span class="o">))</span> <span class="o">{</span>
        <span class="n">totalChange</span> <span class="o">+=</span> <span class="n">change</span><span class="o">;</span>
        <span class="n">validStocks</span><span class="o">++;</span>
    <span class="o">}</span>
<span class="o">}</span>

<span class="kt">double</span> <span class="n">avgChange</span> <span class="o">=</span> <span class="n">totalChange</span> <span class="o">/</span> <span class="n">validStocks</span><span class="o">;</span> <span class="c1">// What if validStocks is 0?</span></code></pre></figure>

<p>If no stocks had valid data, you’re dividing <code class="language-plaintext highlighter-rouge">0.0 / 0</code>. Should your program:</p>
<ul>
  <li>Crash immediately?</li>
  <li>Return <code class="language-plaintext highlighter-rouge">0.0</code> and pretend the average is zero (which is a lie)?</li>
  <li>Return something that screams “this value is meaningless”?</li>
</ul>

<p>IEEE 754 chose option three. It invented special values so errors can propagate visibly instead of silently corrupting results downstream.</p>

<h2 id="ieee-754-special-values">IEEE 754 Special Values</h2>

<p>IEEE 754 defines a few “not-a-normal-number” values so computations can keep going in a principled way instead of crashing or silently inventing garbage.</p>

<h3 id="1-signed-zero-00">1. Signed Zero: ±0.0</h3>

<p>Before we dive into infinity, there’s a subtle detail: IEEE 754 has both <code class="language-plaintext highlighter-rouge">+0.0</code> and <code class="language-plaintext highlighter-rouge">-0.0</code>. They both print as <code class="language-plaintext highlighter-rouge">0.0</code> and compare as equal, but they behave differently in division:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">posZero</span> <span class="o">=</span> <span class="mf">0.0</span><span class="o">;</span>
<span class="kt">double</span> <span class="n">negZero</span> <span class="o">=</span> <span class="o">-</span><span class="mf">0.0</span><span class="o">;</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">posZero</span> <span class="o">==</span> <span class="n">negZero</span><span class="o">);</span>  <span class="c1">// true</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="mf">1.0</span> <span class="o">/</span> <span class="n">posZero</span><span class="o">);</span>       <span class="c1">// Infinity</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="mf">1.0</span> <span class="o">/</span> <span class="n">negZero</span><span class="o">);</span>       <span class="c1">// -Infinity</span></code></pre></figure>

<p>Signed zero exists so that <code class="language-plaintext highlighter-rouge">1.0 / (tiny positive number → 0)</code> gives <code class="language-plaintext highlighter-rouge">+∞</code> while <code class="language-plaintext highlighter-rouge">1.0 / (tiny negative number → 0)</code> gives <code class="language-plaintext highlighter-rouge">−∞</code>. It preserves the direction you approached zero from, which matters for continuity and limit-style reasoning (aka Calculus).</p>

<h3 id="2-infinity--and-">2. Infinity: +∞ and −∞</h3>

<p>Infinity appears when a finite result cannot be represented, or when you divide a nonzero number by zero.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">posInf</span> <span class="o">=</span> <span class="mf">1.0</span> <span class="o">/</span> <span class="mf">0.0</span><span class="o">;</span>   <span class="c1">// +Infinity</span>
<span class="kt">double</span> <span class="n">negInf</span> <span class="o">=</span> <span class="o">-</span><span class="mf">1.0</span> <span class="o">/</span> <span class="mf">0.0</span><span class="o">;</span>  <span class="c1">// -Infinity</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">posInf</span><span class="o">);</span>                  <span class="c1">// Infinity</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">negInf</span><span class="o">);</span>                  <span class="c1">// -Infinity</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isInfinite</span><span class="o">(</span><span class="n">posInf</span><span class="o">));</span> <span class="c1">// true</span></code></pre></figure>

<p>Infinity participates in ordering as you’d expect:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">+∞</code> is greater than every finite number</li>
  <li><code class="language-plaintext highlighter-rouge">−∞</code> is smaller than every finite number</li>
</ul>

<p>Arithmetic is mostly “limit-like”:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">finite + (+∞) = +∞</code></li>
  <li><code class="language-plaintext highlighter-rouge">positive × (+∞) = +∞</code></li>
  <li><code class="language-plaintext highlighter-rouge">negative × (+∞) = −∞</code></li>
</ul>

<p>But some combinations are undefined and produce NaN:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">(+∞) + (−∞) = NaN</code></li>
  <li><code class="language-plaintext highlighter-rouge">(+∞) × 0.0 = NaN</code></li>
  <li><code class="language-plaintext highlighter-rouge">(+∞) / (+∞) = NaN</code></li>
</ul>

<h3 id="3-nan-not-a-number">3. NaN: Not a Number</h3>

<p>NaN means “this result is undefined,” like <code class="language-plaintext highlighter-rouge">0.0 / 0.0</code> or <code class="language-plaintext highlighter-rouge">√(−1)</code>. Once NaN enters a computation, it spreads into any operation involving NaN to produce a NaN:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">nan</span> <span class="o">=</span> <span class="mf">0.0</span> <span class="o">/</span> <span class="mf">0.0</span><span class="o">;</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">nan</span><span class="o">);</span>           <span class="c1">// NaN</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">nan</span> <span class="o">+</span> <span class="mi">5</span><span class="o">);</span>       <span class="c1">// NaN</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">nan</span> <span class="o">*</span> <span class="mi">2</span><span class="o">);</span>       <span class="c1">// NaN</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="nc">Math</span><span class="o">.</span><span class="na">sqrt</span><span class="o">(</span><span class="n">nan</span><span class="o">));</span> <span class="c1">// NaN</span></code></pre></figure>

<p>This “contagious” behavior is intentional. If a value is undefined, any result built on it should also be undefined.</p>

<h4 id="the-weird-rule-nan--nan">The Weird Rule: NaN ≠ NaN</h4>

<p>The key rule that feels like a logic prank but is actually a safety feature:</p>

<p><strong>NaN is not equal to anything, including itself.</strong></p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">nan</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">NaN</span><span class="o">;</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">nan</span> <span class="o">==</span> <span class="n">nan</span><span class="o">);</span>        <span class="c1">// false (!)</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">nan</span> <span class="o">!=</span> <span class="n">nan</span><span class="o">);</span>        <span class="c1">// true</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">nan</span> <span class="o">&lt;</span> <span class="mf">5.0</span><span class="o">);</span>         <span class="c1">// false</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">nan</span> <span class="o">&gt;=</span> <span class="mf">5.0</span><span class="o">);</span>        <span class="c1">// false</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isNaN</span><span class="o">(</span><span class="n">nan</span><span class="o">));</span> <span class="c1">// true (correct way)</span></code></pre></figure>

<p>Why? Because NaN means “undefined result,” and you can’t meaningfully compare undefined values. NaN is unordered by design. There can be many NaN bit patterns (IEEE 754 supports “signaling” and “quiet” NaNs with different payloads), but Java generally treats them as “some NaN” unless you inspect raw bits with <code class="language-plaintext highlighter-rouge">Double.doubleToRawLongBits()</code>.</p>

<p>Think of it like asking whether two error messages are “the same error.” Even if both say “Error,” you don’t know if they represent the same underlying problem. The comparison itself is meaningless.</p>

<p><strong>Never check for NaN with <code class="language-plaintext highlighter-rouge">==</code>. Use <code class="language-plaintext highlighter-rouge">Double.isNaN(x)</code> instead.</strong></p>

<h4 id="nan-and-sorting-two-different-worlds">NaN and Sorting: Two Different Worlds</h4>

<p>This is where things get interesting. Java has <em>two</em> ways to compare doubles, and they behave differently with NaN:</p>

<p><strong>IEEE 754 comparisons</strong> (<code class="language-plaintext highlighter-rouge">==</code>, <code class="language-plaintext highlighter-rouge">&lt;</code>, <code class="language-plaintext highlighter-rouge">&lt;=</code>, etc.):</p>
<ul>
  <li>Any comparison with NaN returns <code class="language-plaintext highlighter-rouge">false</code></li>
  <li>These are what you use in <code class="language-plaintext highlighter-rouge">if</code> statements</li>
</ul>

<p><strong>Java’s total order</strong> (<code class="language-plaintext highlighter-rouge">Double.compare()</code>, <code class="language-plaintext highlighter-rouge">Double.compareTo()</code>)<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup>:</p>
<ul>
  <li>NaN is considered greater than all other values, including <code class="language-plaintext highlighter-rouge">+∞</code></li>
  <li>All NaNs are considered equal</li>
  <li>This is what <code class="language-plaintext highlighter-rouge">Arrays.sort()</code> and <code class="language-plaintext highlighter-rouge">Arrays.binarySearch()</code> use</li>
</ul>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span><span class="o">[]</span> <span class="n">values</span> <span class="o">=</span> <span class="o">{</span><span class="mf">3.0</span><span class="o">,</span> <span class="nc">Double</span><span class="o">.</span><span class="na">NaN</span><span class="o">,</span> <span class="mf">1.0</span><span class="o">,</span> <span class="mf">2.0</span><span class="o">};</span>
<span class="nc">Arrays</span><span class="o">.</span><span class="na">sort</span><span class="o">(</span><span class="n">values</span><span class="o">);</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="nc">Arrays</span><span class="o">.</span><span class="na">toString</span><span class="o">(</span><span class="n">values</span><span class="o">));</span> 
<span class="c1">// [1.0, 2.0, 3.0, NaN] -- guaranteed by Java spec</span>

<span class="c1">// IEEE comparison says "not sorted":</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">values</span><span class="o">[</span><span class="mi">2</span><span class="o">]</span> <span class="o">&lt;=</span> <span class="n">values</span><span class="o">[</span><span class="mi">3</span><span class="o">]);</span> <span class="c1">// false (3.0 &lt;= NaN is false)</span>

<span class="c1">// Total order says "sorted":</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">compare</span><span class="o">(</span><span class="n">values</span><span class="o">[</span><span class="mi">2</span><span class="o">],</span> <span class="n">values</span><span class="o">[</span><span class="mi">3</span><span class="o">])</span> <span class="o">&lt;=</span> <span class="mi">0</span><span class="o">);</span> <span class="c1">// true</span></code></pre></figure>

<p><strong>The gotcha:</strong> If you validate sortedness using <code class="language-plaintext highlighter-rouge">&lt;=</code>, you’ll get false negatives when NaN is present. If you need to check ordering, use <code class="language-plaintext highlighter-rouge">Double.compare(a, b) &lt;= 0</code> instead.</p>

<p>IEEE comparisons answer “is this mathematically ordered?” while Java’s total order answers “can we put these in a consistent sequence for sorting?” The Arrays Javadoc basically says exactly that: &lt; is not a total order for doubles, so sorting uses the total order from Double.compareTo.</p>

<p>The good news: <code class="language-plaintext highlighter-rouge">Arrays.sort()</code> and <code class="language-plaintext highlighter-rouge">Arrays.binarySearch()</code> work correctly with NaN because they use the total order internally. The NaN will consistently end up at the end of the array.</p>

<h2 id="quick-reference-comparison-table">Quick Reference: Comparison Table</h2>

<table>
  <thead>
    <tr>
      <th>Operation</th>
      <th>Result</th>
      <th>Reason</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">NaN == NaN</code></td>
      <td><code class="language-plaintext highlighter-rouge">false</code></td>
      <td>IEEE comparison: unordered</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">NaN != NaN</code></td>
      <td><code class="language-plaintext highlighter-rouge">true</code></td>
      <td>Same reason</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">NaN &lt; 5.0</code></td>
      <td><code class="language-plaintext highlighter-rouge">false</code></td>
      <td>NaN fails all IEEE comparisons</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">NaN &gt;= 5.0</code></td>
      <td><code class="language-plaintext highlighter-rouge">false</code></td>
      <td>Same</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Double.compare(NaN, 5.0)</code></td>
      <td><code class="language-plaintext highlighter-rouge">&gt; 0</code></td>
      <td>Total order: NaN &gt; everything</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">∞ &gt; 1e308</code></td>
      <td><code class="language-plaintext highlighter-rouge">true</code></td>
      <td>Infinity is greater than all finite values</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">0.0 == -0.0</code></td>
      <td><code class="language-plaintext highlighter-rouge">true</code></td>
      <td>Signed zeros compare equal</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">1.0 / 0.0</code></td>
      <td><code class="language-plaintext highlighter-rouge">+∞</code></td>
      <td>Division by zero produces infinity</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">0.0 / 0.0</code></td>
      <td><code class="language-plaintext highlighter-rouge">NaN</code></td>
      <td>Indeterminate form</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">∞ − ∞</code></td>
      <td><code class="language-plaintext highlighter-rouge">NaN</code></td>
      <td>Undefined operation</td>
    </tr>
  </tbody>
</table>

<h2 id="practical-takeaways">Practical Takeaways</h2>

<ol>
  <li><strong>Never check NaN with <code class="language-plaintext highlighter-rouge">==</code></strong>. Use <code class="language-plaintext highlighter-rouge">Double.isNaN(x)</code>.</li>
  <li><strong>Log early for special values</strong> when debugging “impossible” totals:</li>
</ol>

<figure class="highlight"><pre><code class="language-java" data-lang="java">   <span class="k">if</span> <span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isNaN</span><span class="o">(</span><span class="n">result</span><span class="o">))</span> <span class="o">{</span>
       <span class="n">log</span><span class="o">.</span><span class="na">error</span><span class="o">(</span><span class="s">"NaN detected at step X"</span><span class="o">);</span>
   <span class="o">}</span>
   <span class="k">if</span> <span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isInfinite</span><span class="o">(</span><span class="n">result</span><span class="o">))</span> <span class="o">{</span>
       <span class="n">log</span><span class="o">.</span><span class="na">error</span><span class="o">(</span><span class="s">"Infinity detected at step X"</span><span class="o">);</span>
   <span class="o">}</span>
   </code></pre></figure>

<ol>
  <li><strong>Use the right comparison for the job</strong>: <code class="language-plaintext highlighter-rouge">==</code> for value equality, <code class="language-plaintext highlighter-rouge">Double.compare()</code> for ordering.</li>
  <li><strong>Understand the contagion</strong>: Once NaN enters your calculations, it spreads. Trace backward to find the division by zero or invalid operation that spawned it.</li>
</ol>

<h2 id="the-philosophical-bit">The Philosophical Bit</h2>

<p>NaN isn’t a bug. It is math raising its hand and saying, politely but firmly:</p>

<blockquote>
  <p>“I can’t promise anything from here.”</p>
</blockquote>

<p>When your balance sheet shows NaN, don’t curse floating point. Ask what division by zero or invalid square root you missed three steps ago. The special values aren’t betraying you; they’re the only honest answer to questions that have no answer.</p>

<p>In the next post, we’ll look at how to actually <em>handle</em> these special cases in production code without littering your logic with endless <code class="language-plaintext highlighter-rouge">isNaN()</code> checks.</p>

<h2 id="references-and-notes">References and Notes</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p><a href="/2025/12/04/ieee-754-doubles/">Part 1: IEEE 754 Doubles - The Numbers That Lie With A Straight Face</a> <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p><a href="https://docs.oracle.com/en/java/javase/17/docs/api/java.base/java/lang/Double.html">Java’s Total Order</a> <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="[&quot;Computer Science&quot;, &quot;Software Engineering&quot;, &quot;Technology&quot;, &quot;Series 4 - Floating Point Without Tears&quot;]" /><category term="java" /><category term="floating-point" /><category term="ieee-754" /><category term="double" /><category term="machine-epsilon" /><category term="ulp" /><category term="numerics" /><category term="NaN" /><category term="infinity" /><summary type="html"><![CDATA[In IEEE 754 floating point, there are special values (NaN, +∞, −∞) that follow rules that look like broken logic, until you realize they're trying to protect you from lying math.]]></summary></entry><entry><title type="html">Part 4: Machine Epsilon - The Smallest Change a Double Can See</title><link href="https://systemhalted.in/2025/12/23/machine-epsilon-double-precision-grid/" rel="alternate" type="text/html" title="Part 4: Machine Epsilon - The Smallest Change a Double Can See" /><published>2025-12-23T00:00:00+00:00</published><updated>2025-12-23T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/23/machine-epsilon-double-precision-grid</id><content type="html" xml:base="https://systemhalted.in/2025/12/23/machine-epsilon-double-precision-grid/"><![CDATA[<p><em>This post is part of my <a href="https://systemhalted.in/categories/#cat-series-4-floating-point-without-tears">Floating Point Without Tears</a> series on how Java numbers misbehave and how to live with them.</em></p>

<p>In my post on associativity and reduce<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>, we saw something that feels like a prank. In Example 5, adding 1.0 to 1e16 did not change the value at all.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">x</span> <span class="o">=</span> <span class="mi">1</span><span class="n">e16</span><span class="o">;</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span> <span class="o">+</span> <span class="mf">1.0</span> <span class="o">==</span> <span class="n">x</span><span class="o">);</span> <span class="c1">// true</span></code></pre></figure>

<p>That is not Java being cheeky. That is IEEE-754 being literal. A double does not live on a continuous number line. It lives on a grid.</p>

<p>This post answers one question:</p>

<p><strong>How fine is the grid?</strong></p>

<h2 id="machine-epsilon-and-the-first-rung-above-10">Machine epsilon and the first rung above 1.0</h2>

<p>One common definition of machine epsilon (ε) is:</p>

<p><em>The smallest ε &gt; 0 such that 1.0 + ε ≠ 1.0 for double.</em></p>

<p>This is “the gap from 1.0 to the next representable double above it”.</p>

<p><strong>Note:</strong> Some references use ε to mean 2⁻⁵³, which is half this gap and represents the maximum relative rounding error for a correctly rounded operation. In this post, ε means the “next representable number above 1.0” definition, which is 2⁻⁵².</p>

<h3 id="finding-ε-in-java">Finding ε in Java</h3>

<p>Here is a loop that finds that smallest nudge.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">public</span> <span class="kd">class</span> <span class="nc">MachineEpsilon</span> <span class="o">{</span>
  <span class="kd">public</span> <span class="kd">static</span> <span class="kt">void</span> <span class="nf">main</span><span class="o">(</span><span class="nc">String</span><span class="o">[]</span> <span class="n">args</span><span class="o">)</span> <span class="o">{</span>
    <span class="kt">double</span> <span class="n">eps</span> <span class="o">=</span> <span class="mf">1.0</span><span class="o">;</span>

    <span class="k">while</span> <span class="o">(</span><span class="mf">1.0</span> <span class="o">+</span> <span class="o">(</span><span class="n">eps</span> <span class="o">/</span> <span class="mf">2.0</span><span class="o">)</span> <span class="o">!=</span> <span class="mf">1.0</span><span class="o">)</span> <span class="o">{</span>
      <span class="n">eps</span> <span class="o">/=</span> <span class="mf">2.0</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"epsilon = "</span> <span class="o">+</span> <span class="n">eps</span><span class="o">);</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>Typical output on an IEEE-754 JVM:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">epsilon = 2.220446049250313E-16</code></pre></figure>

<p>That value is exactly 2⁻⁵². Since powers of two are exactly representable in binary floating point, there is no approximation error in storing this value. The decimal string 2.220446049250313E-16 is just how Java renders that exact binary value for display, rounded to about 15 decimal digits.<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p><strong>One quick trap:</strong> <code class="language-plaintext highlighter-rouge">Double.MIN_VALUE</code> is not machine epsilon. <code class="language-plaintext highlighter-rouge">Double.MIN_VALUE</code> is the smallest positive double near zero (about 5×10⁻³²⁴). Machine epsilon is about spacing near 1.0.</p>

<h2 id="the-ladder-model">The ladder model</h2>

<p>Picture a ladder laid across the number line.</p>

<p>Near 1.0, the rungs are extremely close together. As the numbers get bigger, the rungs spread out.</p>

<p>Machine epsilon tells you the rung spacing near 1.0. But what you usually want is the spacing near whatever value you are actually using.</p>

<p>That spacing is called <strong>ULP</strong>, short for <strong>Unit in the Last Place</strong>.</p>

<p>Java gives it to you with <code class="language-plaintext highlighter-rouge">Math.ulp(x)</code>.</p>

<svg xmlns="http://www.w3.org/2000/svg" width="100%" viewBox="0 0 920 380" role="img" aria-label="Double precision grid spacing near 1.0 vs near 1e16" preserveAspectRatio="xMidYMid meet" style="max-width: 100%; height: auto; display: block;">
  <style>
    .title { font: 700 18px system-ui, -apple-system, Segoe UI, Roboto, Arial, sans-serif; fill: #111; }
    .label { font: 13px system-ui, -apple-system, Segoe UI, Roboto, Arial, sans-serif; fill: #222; }
    .small { font: 12px ui-monospace, SFMono-Regular, Menlo, Monaco, Consolas, "Liberation Mono", monospace; fill: #222; }
    .tick { stroke: #111; stroke-width: 2; }
    .axis { stroke: #111; stroke-width: 2.5; }
    .ghost { stroke: #888; stroke-width: 2; stroke-dasharray: 5 5; }
    .note { font: 12px system-ui, -apple-system, Segoe UI, Roboto, Arial, sans-serif; fill: #333; }
    .box { fill: #fafafa; stroke: #ddd; stroke-width: 1.5; }
  </style>

  <text x="20" y="28" class="title">Double is a grid: spacing depends on magnitude</text>

  <!-- Panel boxes -->
  <rect x="20" y="50" width="880" height="130" rx="10" class="box" />
  <rect x="20" y="195" width="880" height="150" rx="10" class="box" />

  <!-- Panel 1: near 1.0 -->
  <text x="40" y="78" class="label">Zoom near 1.0</text>
  <text x="40" y="98" class="note">Adjacent representable values are extremely close: spacing ≈ ε = 2⁻⁵² ≈ 2.22e−16</text>

  <!-- Axis 1 -->
  <line x1="60" y1="135" x2="860" y2="135" class="axis" />
  <text x="60" y="158" class="small">…</text>

  <!-- Dense ticks -->
  <line x1="430" y1="118" x2="430" y2="152" class="tick" />
  <text x="410" y="112" class="small">1.0</text>

  <line x1="380" y1="122" x2="380" y2="148" class="tick" />
  <line x1="405" y1="122" x2="405" y2="148" class="tick" />
  <line x1="455" y1="122" x2="455" y2="148" class="tick" />
  <line x1="480" y1="122" x2="480" y2="148" class="tick" />

  <!-- epsilon arrow -->
  <line x1="430" y1="165" x2="455" y2="165" stroke="#111" stroke-width="2" />
  <polygon points="455,165 448,161 448,169" fill="#111" />
  <text x="470" y="169" class="small">ε (next rung)</text>

  <text x="780" y="158" class="small">…</text>

  <!-- Panel 2: near 1e16 -->
  <text x="40" y="223" class="label">Zoom near 1e16</text>
  <text x="40" y="243" class="note">Here the grid is coarse: ulp(1e16) = 2.0, so +1.0 lands between rungs and vanishes</text>

  <!-- Axis 2 -->
  <line x1="60" y1="275" x2="860" y2="275" class="axis" />

  <!-- Rungs: 1e16, 1e16+2, 1e16+4 -->
  <line x1="360" y1="258" x2="360" y2="292" class="tick" />
  <text x="310" y="252" class="small">1e16</text>

  <line x1="460" y1="258" x2="460" y2="292" class="tick" />
  <text x="425" y="252" class="small">+2</text>

  <line x1="560" y1="258" x2="560" y2="292" class="tick" />
  <text x="525" y="252" class="small">+4</text>

  <!-- The missing +1 (ghost tick) -->
  <line x1="410" y1="258" x2="410" y2="292" class="ghost" />

  <!-- ulp arrow (moved down so it doesn't collide with +1 text) -->
  <line x1="360" y1="323" x2="460" y2="323" stroke="#111" stroke-width="2" />
  <polygon points="460,323 453,319 453,327" fill="#111" />
  <text x="470" y="327" class="small">ulp = 2.0</text>

  <!-- +1 annotation (moved further down) -->
  <text x="392" y="345" class="small">+1</text>
  <text x="430" y="345" class="small">does not exist</text>

  <!-- Summary callout (pushed down and within new height) -->
  <text x="40" y="372" class="note">Takeaway: doubles keep ~53 bits of precision, so absolute spacing grows as numbers grow.</text>
</svg>

<h2 id="how-spacing-grows-with-magnitude">How spacing grows with magnitude</h2>

<p>Let’s sample the grid at a few scales.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">public</span> <span class="kd">class</span> <span class="nc">UlpSpacing</span> <span class="o">{</span>
  <span class="kd">public</span> <span class="kd">static</span> <span class="kt">void</span> <span class="nf">main</span><span class="o">(</span><span class="nc">String</span><span class="o">[]</span> <span class="n">args</span><span class="o">)</span> <span class="o">{</span>
    <span class="kt">double</span><span class="o">[]</span> <span class="n">xs</span> <span class="o">=</span> <span class="o">{</span><span class="mf">1.0</span><span class="o">,</span> <span class="mf">10.0</span><span class="o">,</span> <span class="mi">1</span><span class="n">e8</span><span class="o">,</span> <span class="mi">1</span><span class="n">e16</span><span class="o">};</span>

    <span class="k">for</span> <span class="o">(</span><span class="kt">double</span> <span class="n">x</span> <span class="o">:</span> <span class="n">xs</span><span class="o">)</span> <span class="o">{</span>
      <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">printf</span><span class="o">(</span><span class="s">"x=%-8s  ulp(x)=%s%n"</span><span class="o">,</span> <span class="n">x</span><span class="o">,</span> <span class="nc">Math</span><span class="o">.</span><span class="na">ulp</span><span class="o">(</span><span class="n">x</span><span class="o">));</span>
    <span class="o">}</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>Typical output:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">x=1.0      ulp(x)=2.220446049250313E-16
x=10.0     ulp(x)=1.7763568394002505E-15
x=1.0E8    ulp(x)=1.4901161193847656E-8
x=1.0E16   ulp(x)=2.0</code></pre></figure>

<p>That last line is the whole “Example 5” mystery solved:</p>

<p><strong>Around 1e16, the grid spacing is 2.0.</strong></p>

<p>So 1e16 + 1.0 lands between rungs and rounds back to 1e16. But 1e16 + 2.0 is exactly one rung up.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">big</span> <span class="o">=</span> <span class="mi">1</span><span class="n">e16</span><span class="o">;</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">big</span> <span class="o">+</span> <span class="mf">1.0</span> <span class="o">==</span> <span class="n">big</span><span class="o">);</span> <span class="c1">// true</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">big</span> <span class="o">+</span> <span class="mf">2.0</span> <span class="o">==</span> <span class="n">big</span><span class="o">);</span> <span class="c1">// false</span></code></pre></figure>

<h2 id="powers-of-two-where-spacing-jumps">Powers of two: where spacing jumps</h2>

<p>ULP does not grow smoothly. It jumps at powers of two.</p>

<p>Right below 2ᵏ, spacing is one value. At 2ᵏ, spacing doubles.</p>

<p>That is why comparisons that seem symmetric can behave oddly if two values straddle a power-of-two boundary. If you’re comparing values near different powers of two, their ULPs can differ by a factor of 2.</p>

<h2 id="near-zero-subnormals-exist-and-they-are-weird">Near zero: subnormals exist and they are weird</h2>

<p>For very small magnitudes below <code class="language-plaintext highlighter-rouge">Double.MIN_NORMAL</code> (approximately 2.225×10⁻³⁰⁸), double switches to subnormal (also called denormal) representation.</p>

<p><strong>What changes in subnormal land:</strong></p>

<p>Normal doubles have an implicit leading <code class="language-plaintext highlighter-rouge">1.</code> in the mantissa:</p>
<ul>
  <li>value = (1.fraction) × 2^exponent</li>
  <li>This gives you full precision</li>
</ul>

<p>Subnormals drop that leading <code class="language-plaintext highlighter-rouge">1.</code>:</p>
<ul>
  <li>value = (0.fraction) × 2^(minExponent)</li>
  <li>You lose precision gradually as you approach zero</li>
</ul>

<p><strong>Why they exist:</strong></p>

<p>Without subnormals, there would be a hard cliff from tiny normal numbers straight to 0.0. Subnormals provide <em>gradual underflow</em> - a ramp instead of a cliff.</p>

<p><strong>Key differences:</strong></p>

<ul>
  <li>Spacing becomes constant at approximately 5×10⁻³²⁴ (the value of <code class="language-plaintext highlighter-rouge">Double.MIN_VALUE</code>) rather than scaling with magnitude</li>
  <li>Arithmetic can be slower on some CPUs</li>
  <li>Relative precision is much worse (you may have only a few significant bits left)</li>
</ul>

<p>Everything in the range <code class="language-plaintext highlighter-rouge">(0, Double.MIN_NORMAL)</code> is subnormal. That’s the range from about 4.9×10⁻³²⁴ up to about 2.225×10⁻³⁰⁸.</p>

<p>Most business code never goes near subnormals. Numerical code sometimes does. It is worth knowing that floating-point has an emergency mode near zero that trades precision for continuity.</p>

<h2 id="why-tiny-increments-vanish-when-numbers-get-big">Why tiny increments vanish when numbers get big</h2>

<p>When your running total grows large enough, the local rung spacing can become bigger than the increments you are adding.</p>

<p>So “add a million tiny things to a huge sum” eventually turns into “add nothing, repeatedly,” because the tiny things fall between rungs and get rounded away.</p>

<p>That is not philosophical. It is mechanical.</p>

<h2 id="why-equality-checks-on-doubles-are-dicey">Why equality checks on doubles are dicey</h2>

<p>Sometimes two values that “should be different” land on the same rung. Sometimes two values that “should be equal” get rounded at different times and land on adjacent rungs.</p>

<p>So <code class="language-plaintext highlighter-rouge">==</code> is only safe when you mean exact equality:</p>

<ul>
  <li>Comparing to exact literals: <code class="language-plaintext highlighter-rouge">0.0</code>, <code class="language-plaintext highlighter-rouge">1.0</code>, <code class="language-plaintext highlighter-rouge">-1.0</code></li>
  <li>Checking for special values: infinities, or <code class="language-plaintext highlighter-rouge">Double.isNaN(x)</code></li>
  <li>Comparing sentinel values or results from identical deterministic operations</li>
  <li>Loop counters stored as doubles (though you should use integers instead)</li>
</ul>

<p>When you need “close enough,” you need a rule that matches your domain.</p>

<p>A common practical pattern is absolute tolerance near zero plus relative tolerance for scale.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">public</span> <span class="kd">final</span> <span class="kd">class</span> <span class="nc">DoubleCompare</span> <span class="o">{</span>
  <span class="kd">private</span> <span class="nf">DoubleCompare</span><span class="o">()</span> <span class="o">{}</span> <span class="c1">// prevent instantiation</span>

  <span class="cm">/**
   * Check if two doubles are nearly equal using absolute and relative tolerance.
   * 
   * @param a first value
   * @param b second value
   * @param absTol absolute tolerance (try 1e-9 for many applications)
   * @param relTol relative tolerance (try 1e-9 for many applications)
   * @return true if values are within tolerance
   */</span>
  <span class="kd">public</span> <span class="kd">static</span> <span class="kt">boolean</span> <span class="nf">nearlyEqual</span><span class="o">(</span><span class="kt">double</span> <span class="n">a</span><span class="o">,</span> <span class="kt">double</span> <span class="n">b</span><span class="o">,</span> <span class="kt">double</span> <span class="n">absTol</span><span class="o">,</span> <span class="kt">double</span> <span class="n">relTol</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">if</span> <span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">isNaN</span><span class="o">(</span><span class="n">a</span><span class="o">)</span> <span class="o">||</span> <span class="nc">Double</span><span class="o">.</span><span class="na">isNaN</span><span class="o">(</span><span class="n">b</span><span class="o">))</span> <span class="k">return</span> <span class="kc">false</span><span class="o">;</span>
    <span class="k">if</span> <span class="o">(</span><span class="n">a</span> <span class="o">==</span> <span class="n">b</span><span class="o">)</span> <span class="k">return</span> <span class="kc">true</span><span class="o">;</span> <span class="c1">// handles infinities and exact matches</span>

    <span class="kt">double</span> <span class="n">diff</span> <span class="o">=</span> <span class="nc">Math</span><span class="o">.</span><span class="na">abs</span><span class="o">(</span><span class="n">a</span> <span class="o">-</span> <span class="n">b</span><span class="o">);</span>
    <span class="k">if</span> <span class="o">(</span><span class="n">diff</span> <span class="o">&lt;=</span> <span class="n">absTol</span><span class="o">)</span> <span class="k">return</span> <span class="kc">true</span><span class="o">;</span>

    <span class="kt">double</span> <span class="n">maxAbs</span> <span class="o">=</span> <span class="nc">Math</span><span class="o">.</span><span class="na">max</span><span class="o">(</span><span class="nc">Math</span><span class="o">.</span><span class="na">abs</span><span class="o">(</span><span class="n">a</span><span class="o">),</span> <span class="nc">Math</span><span class="o">.</span><span class="na">abs</span><span class="o">(</span><span class="n">b</span><span class="o">));</span>
    <span class="k">return</span> <span class="n">diff</span> <span class="o">&lt;=</span> <span class="n">relTol</span> <span class="o">*</span> <span class="n">maxAbs</span><span class="o">;</span>
  <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p><strong>Choosing tolerance values:</strong></p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">absTol</code> should match the minimum meaningful difference in your domain. For scientific data measured to 3 decimal places, maybe <code class="language-plaintext highlighter-rouge">1e-3</code>. For pixel coordinates, maybe <code class="language-plaintext highlighter-rouge">0.5</code>.</li>
  <li><code class="language-plaintext highlighter-rouge">relTol</code> is typically something like <code class="language-plaintext highlighter-rouge">1e-9</code> (about 9 decimal digits of agreement) for general use, or <code class="language-plaintext highlighter-rouge">1e-6</code> if you’re being more lenient.</li>
  <li>These comparisons are slower than <code class="language-plaintext highlighter-rouge">==</code>. If you’re comparing millions of values in performance-critical code, measure the cost.</li>
</ul>

<p>This is not the only strategy, but it is harder to misuse than an “ULPs everywhere” helper.</p>

<h2 id="why-parallel-reductions-can-drift">Why parallel reductions can drift</h2>

<p>Parallel reductions regroup operations. Floating-point addition is not associative, so regrouping changes when rounding happens.</p>

<p>Here is the smallest “this is why” example.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">a</span> <span class="o">=</span> <span class="mi">1</span><span class="n">e16</span><span class="o">;</span>

<span class="kt">double</span> <span class="n">left</span>  <span class="o">=</span> <span class="o">(</span><span class="n">a</span> <span class="o">+</span> <span class="mf">1.0</span><span class="o">)</span> <span class="o">+</span> <span class="mf">1.0</span><span class="o">;</span>   <span class="c1">// first +1 vanishes, then second +1 vanishes</span>
<span class="kt">double</span> <span class="n">right</span> <span class="o">=</span> <span class="n">a</span> <span class="o">+</span> <span class="o">(</span><span class="mf">1.0</span> <span class="o">+</span> <span class="mf">1.0</span><span class="o">);</span>   <span class="c1">// (1.0 + 1.0) becomes 2.0, which moves one ULP</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">left</span> <span class="o">==</span> <span class="n">right</span><span class="o">);</span> <span class="c1">// false</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">left</span><span class="o">);</span>          <span class="c1">// 1.0E16</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">right</span><span class="o">);</span>         <span class="c1">// 1.0000000000000002E16</span></code></pre></figure>

<p>Same values, different grouping, different result. That is the reason parallel sums can drift when the data has large magnitudes or mixed scales.</p>

<h2 id="the-takeaway">The takeaway</h2>

<p>A double gives you roughly the same number of significant bits everywhere (about 15-16 decimal digits), not the same absolute resolution everywhere.<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>Machine epsilon tells you the first rung above 1.0.</p>

<p><code class="language-plaintext highlighter-rouge">Math.ulp(x)</code> tells you the rung spacing where you are standing.</p>

<p>And that is why, at 1e16, adding 1.0 is like whispering into a hurricane.</p>

<h2 id="references">References</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p><a href="/2025/11/28/associativity-identity-folding/">Part 2: Associativity, Identity, and Folding - Why Your reduce Keeps Biting You</a> <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>How is  2.220446049250313E-16 = 2⁻⁵²?
  2⁻⁵² = 1 / 2⁵² = 1 / 4,503,599,627,370,496</p>

      <p>1 ÷ 4,503,599,627,370,496 = 0.00000000000000022204460492503130808472633361816…<br />
 In scientific notation: 2.2204460492503130808… × 10⁻¹⁶<br />
 The displayed value 2.220446049250313E-16 is this value rounded to 15-16 significant decimal digits for display. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>For deeper reading, see David Goldberg’s classic paper, <a href="https://docs.oracle.com/cd/E19957-01/806-3568/ncg_goldberg.html">“What Every Computer Scientist Should Know About Floating-Point Arithmetic”</a>.* <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="[&quot;Computer Science&quot;, &quot;Software Engineering&quot;, &quot;Technology&quot;, &quot;Series 4 - Floating Point Without Tears&quot;]" /><category term="java" /><category term="floating-point" /><category term="ieee-754" /><category term="double" /><category term="machine-epsilon" /><category term="ulp" /><category term="numerics" /><summary type="html"><![CDATA[How fine is the double-precision grid, and why does 1.0 vanish next to 1e16?]]></summary></entry><entry><title type="html">Part 3: BigDecimal - When Doubles Aren’t Enough</title><link href="https://systemhalted.in/2025/12/22/java-bigdecimal-vs-double/" rel="alternate" type="text/html" title="Part 3: BigDecimal - When Doubles Aren’t Enough" /><published>2025-12-22T00:00:00+00:00</published><updated>2025-12-22T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/22/java-bigdecimal-vs-double</id><content type="html" xml:base="https://systemhalted.in/2025/12/22/java-bigdecimal-vs-double/"><![CDATA[<p><em>This post is part of my <a href="https://systemhalted.in/categories/#cat-series-4-floating-point-without-tears">Floating Point Without Tears</a> series on how Java numbers misbehave and how to live with them.</em></p>

<p>In my earlier post on <a href="/2025/12/04/ieee-754-doubles/">IEEE 754 doubles</a> I showed how a tiny Java example could break your intuition about numbers. The JVM was not being sloppy. It was faithfully following the floating point rules. The surprise came from my mental model, not from the hardware.</p>

<p>BigDecimal is Java’s answer to a different problem: <em>what if I actually need decimal correctness, not fast binary approximation?</em> It is the type you reach for when cents matter, reconciliation matters, or auditors matter.</p>

<p>It is less magical than it looks.</p>

<p><strong>TL;DR:</strong> Use <code class="language-plaintext highlighter-rouge">new BigDecimal("0.1")</code> for decimal values in your code. Only use <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(double)</code> when you’re already stuck with a double from external sources.</p>

<h2 id="quick-reference">Quick Reference</h2>

<p>Before we dive in, here’s what you need to remember:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java">  
<span class="c1">// ✓ Correct ways to create BigDecimal for money  </span>
<span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"0.1"</span><span class="o">);</span>                   <span class="c1">// String literal  </span>
<span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"123.45"</span><span class="o">);</span>                <span class="c1">// String literal  </span>
<span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="mi">10</span><span class="o">).</span><span class="na">movePointLeft</span><span class="o">(</span><span class="mi">1</span><span class="o">);</span> <span class="c1">// 10 × 10^-1 = 1.0  </span>

<span class="c1">// ✗ Wrong for hardcoded decimal values  </span>
<span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="mf">0.1</span><span class="o">);</span>        <span class="c1">// Exposes the binary approximation as decimal</span></code></pre></figure>

<h2 id="doubles-speak-binary-your-domain-speaks-decimal">Doubles speak binary, your domain speaks decimal</h2>

<p><code class="language-plaintext highlighter-rouge">double</code> is brilliant for physics, graphics, simulations, and anything where small error is acceptable. It is terrible at representing human money. The root cause is simple. Doubles are binary fractions. Money is decimal.</p>

<p><code class="language-plaintext highlighter-rouge">0.1</code> rupee or dollar has no exact representation in binary floating point. When you write:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">x</span> <span class="o">=</span> <span class="mf">0.1</span><span class="o">;</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span><span class="o">);</span>              <span class="c1">// prints 0.1 (canonical string)</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">printf</span><span class="o">(</span><span class="s">"%.20f%n"</span><span class="o">,</span> <span class="n">x</span><span class="o">);</span>    <span class="c1">// 0.10000000000000000555...</span></code></pre></figure>

<p>you are already off by a tiny amount, even though the default printout shows <code class="language-plaintext highlighter-rouge">0.1</code>. Most of the time you are happy to ignore that tiny tail (technically binary approximation). But then you sum millions of rows, or reorder operations, or start comparing for equality, and the tail starts wagging the dog.</p>

<p>BigDecimal cuts across this by working in base 10.</p>

<h2 id="bigdecimals-mental-model">BigDecimal’s mental model</h2>

<p>Conceptually, a BigDecimal is two things glued together:</p>

<ol>
  <li>An integer representing all the digits, without any decimal point.</li>
  <li>A scale that says where the decimal point lives.</li>
</ol>

<p>Formally:</p>

<p><code class="language-plaintext highlighter-rouge">value = unscaledValue × 10^(-scale)</code></p>

<p>So:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">amount</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"123.45"</span><span class="o">);</span></code></pre></figure>

<p>internally becomes:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">unscaledValue = 12345</code></li>
  <li><code class="language-plaintext highlighter-rouge">scale = 2</code></li>
  <li>logical value = <code class="language-plaintext highlighter-rouge">12345 × 10^-2 = 123.45</code></li>
</ul>

<p>Because the unscaled integer is exact, decimal values like <code class="language-plaintext highlighter-rouge">0.1</code>, <code class="language-plaintext highlighter-rouge">0.01</code>, <code class="language-plaintext highlighter-rouge">1234567890.12</code> are also exact. There is no “closest representable value” the way there is with <code class="language-plaintext highlighter-rouge">double</code>. You only lose information when you explicitly ask BigDecimal to round (via <code class="language-plaintext highlighter-rouge">MathContext</code> or <code class="language-plaintext highlighter-rouge">setScale</code>).</p>

<h3 id="how-the-jdk-actually-stores-it">How the JDK actually stores it</h3>

<p>That is the spec view. Under the hood in OpenJDK, the class looks roughly like this:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">public</span> <span class="kd">class</span> <span class="nc">BigDecimal</span> <span class="kd">extends</span> <span class="nc">Number</span>
        <span class="kd">implements</span> <span class="nc">Comparable</span><span class="o">&lt;</span><span class="nc">BigDecimal</span><span class="o">&gt;</span> <span class="o">{</span>

    <span class="c1">// Compact form when it fits in a long</span>
    <span class="kd">private</span> <span class="kd">transient</span> <span class="kt">long</span> <span class="n">intCompact</span><span class="o">;</span>

    <span class="c1">// Full form when it doesn't</span>
    <span class="kd">private</span> <span class="nc">BigInteger</span> <span class="n">intVal</span><span class="o">;</span>

    <span class="c1">// Digits after the decimal point</span>
    <span class="kd">private</span> <span class="kt">int</span> <span class="n">scale</span><span class="o">;</span>

    <span class="c1">// Cached number of significant digits</span>
    <span class="kd">private</span> <span class="kd">transient</span> <span class="kt">int</span> <span class="n">precision</span><span class="o">;</span>

    <span class="c1">// Marker for "no compact long, use intVal instead"</span>
    <span class="kd">static</span> <span class="kd">final</span> <span class="kt">long</span> <span class="no">INFLATED</span> <span class="o">=</span> <span class="nc">Long</span><span class="o">.</span><span class="na">MIN_VALUE</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>So BigDecimal actually has two representations for the unscaled value:</p>

<ul>
  <li><strong>Compact mode</strong>: if the unscaled integer fits in a 64-bit <code class="language-plaintext highlighter-rouge">long</code>, it lives in <code class="language-plaintext highlighter-rouge">intCompact</code> and <code class="language-plaintext highlighter-rouge">intVal</code> is <code class="language-plaintext highlighter-rouge">null</code>. This is the fast path for “small enough” numbers.</li>
  <li><strong>Inflated mode</strong>: if it does not fit, <code class="language-plaintext highlighter-rouge">intCompact</code> is set to <code class="language-plaintext highlighter-rouge">INFLATED</code> and the digits live in <code class="language-plaintext highlighter-rouge">intVal</code> as a <code class="language-plaintext highlighter-rouge">BigInteger</code>.</li>
</ul>

<p>This optimization means small monetary amounts stay fast, while supporting arbitrarily large values when needed.</p>

<p>Your <code class="language-plaintext highlighter-rouge">123.45</code> example fits happily in compact form:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">intCompact = 12345L</code></li>
  <li><code class="language-plaintext highlighter-rouge">intVal = null</code></li>
  <li><code class="language-plaintext highlighter-rouge">scale = 2</code></li>
</ul>

<h2 id="never-construct-bigdecimal-from-a-double">Never construct BigDecimal from a double</h2>

<p>A classic foot-gun looks like this:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">a</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="mf">0.1</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">b</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"0.1"</span><span class="o">);</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">a</span><span class="o">);</span> <span class="c1">// 0.1000000000000000055511151231257827021181583404541015625</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">b</span><span class="o">);</span> <span class="c1">// 0.1</span></code></pre></figure>

<p>The first line takes the <em>binary</em> double for <code class="language-plaintext highlighter-rouge">0.1</code> and converts it directly into an exact decimal. The double is already an approximation, so you get the full fraction printed out.</p>

<p>The second line parses the string <code class="language-plaintext highlighter-rouge">"0.1"</code> as a decimal value. There is no binary detour, so you get exactly one tenth.</p>

<p>You have not “fixed” the double by wrapping it in a BigDecimal. You have just made its approximation painfully visible.</p>

<h2 id="what-about-bigdecimalvalueof-and-canonical-strings">What about BigDecimal.valueOf() and canonical strings?</h2>

<p>This is where people get confused:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">a</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="mf">0.1</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">b</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="mf">0.1</span><span class="o">);</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">a</span><span class="o">);</span>
<span class="c1">// 0.1000000000000000055511151231257827021181583404541015625</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">b</span><span class="o">);</span>
<span class="c1">// 0.1</span></code></pre></figure>

<p>Same literal <code class="language-plaintext highlighter-rouge">0.1</code>, two different worlds.</p>

<p>The difference is that <code class="language-plaintext highlighter-rouge">valueOf</code> goes through the <strong>canonical decimal string</strong> of the double.</p>

<h3 id="route-1-new-bigdecimal01">Route 1: <code class="language-plaintext highlighter-rouge">new BigDecimal(0.1)</code></h3>

<p>This constructor works directly from the binary bits of the double:</p>

<ul>
  <li>The double for <code class="language-plaintext highlighter-rouge">0.1</code> is not exactly one tenth.</li>
  <li>It is some messy binary fraction very close to 0.1.</li>
  <li><code class="language-plaintext highlighter-rouge">new BigDecimal(double)</code> asks: “What is the exact decimal value of this binary fraction?”</li>
</ul>

<p>So you see the full binary approximation:</p>

<blockquote>
  <p>0.1000000000000000055511151231257827021181583404541015625</p>
</blockquote>

<p>Ugly, but honest.</p>

<h3 id="route-2-bigdecimalvalueof01-and-canonical-decimal-strings">Route 2: <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(0.1)</code> and canonical decimal strings</h3>

<p><code class="language-plaintext highlighter-rouge">valueOf</code> takes a different path:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kd">public</span> <span class="kd">static</span> <span class="nc">BigDecimal</span> <span class="nf">valueOf</span><span class="o">(</span><span class="kt">double</span> <span class="n">val</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">return</span> <span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="nc">Double</span><span class="o">.</span><span class="na">toString</span><span class="o">(</span><span class="n">val</span><span class="o">));</span>
<span class="o">}</span></code></pre></figure>

<p>The key piece here is <code class="language-plaintext highlighter-rouge">Double.toString(val)</code>. That method does not dump all the internal bits. Instead, it produces the <strong>canonical decimal string</strong> for that double:</p>

<blockquote>
  <p>The shortest decimal string that, if you parse it back with <code class="language-plaintext highlighter-rouge">Double.parseDouble</code>, gives you exactly the same double bits.</p>
</blockquote>

<p>In code, it guarantees:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="kt">double</span> <span class="n">x</span> <span class="o">=</span> <span class="o">...;</span>
<span class="nc">String</span> <span class="n">s</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">toString</span><span class="o">(</span><span class="n">x</span><span class="o">);</span>
<span class="kt">double</span> <span class="n">y</span> <span class="o">=</span> <span class="nc">Double</span><span class="o">.</span><span class="na">parseDouble</span><span class="o">(</span><span class="n">s</span><span class="o">);</span>

<span class="k">assert</span> <span class="nc">Double</span><span class="o">.</span><span class="na">doubleToLongBits</span><span class="o">(</span><span class="n">x</span><span class="o">)</span> <span class="o">==</span> <span class="nc">Double</span><span class="o">.</span><span class="na">doubleToLongBits</span><span class="o">(</span><span class="n">y</span><span class="o">);</span></code></pre></figure>

<p>For the double that represents <code class="language-plaintext highlighter-rouge">0.1</code>, that canonical string happens to be:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">Double</span><span class="o">.</span><span class="na">toString</span><span class="o">(</span><span class="mf">0.1</span><span class="o">);</span> <span class="c1">// "0.1"</span></code></pre></figure>

<p>So the pipeline for <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(0.1)</code> is:</p>

<ol>
  <li>Start from the binary double for 0.1.</li>
  <li>Turn it into its canonical decimal string <code class="language-plaintext highlighter-rouge">"0.1"</code> – a decimal string with just enough digits to round back to the same double (i.e., to distinguish it from adjacent doubles).</li>
  <li>Feed that string into <code class="language-plaintext highlighter-rouge">new BigDecimal("0.1")</code>.</li>
</ol>

<p>Result: an exact decimal 0.1, not the giant tail.</p>

<p>So you can summarise it like this:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">new BigDecimal(0.1)</code> = “give me the exact decimal value of this weird binary fraction”.</li>
  <li><code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(0.1)</code> = “give me the exact decimal value of the canonical string <code class="language-plaintext highlighter-rouge">\"0.1\"</code> for this double”.</li>
</ul>

<p>The <strong>rounding error</strong> happened earlier, when you chose a <code class="language-plaintext highlighter-rouge">double</code> to represent 0.1 at all. <code class="language-plaintext highlighter-rouge">valueOf</code> doesn’t fix that choice, but it gives you a clean, canonical decimal view of that double instead of the raw fraction.</p>

<h3 id="when-to-use-valueof">When to use <code class="language-plaintext highlighter-rouge">valueOf()</code></h3>

<p><code class="language-plaintext highlighter-rouge">valueOf</code> is useful, and often preferred, in three situations:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// Fine for integers</span>
<span class="nc">BigDecimal</span> <span class="n">cents</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="mi">12345</span><span class="o">);</span> <span class="c1">// 12345</span>

<span class="c1">// When you're stuck with a double from legacy code</span>
<span class="kt">double</span> <span class="n">legacyPrice</span> <span class="o">=</span> <span class="n">thirdPartyApi</span><span class="o">.</span><span class="na">getPrice</span><span class="o">();</span>   <span class="c1">// You can't control this</span>
<span class="nc">BigDecimal</span> <span class="n">price</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="n">legacyPrice</span><span class="o">)</span>
    <span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">);</span>          <span class="c1">// Accept the loss, make it explicit</span>

<span class="c1">// When building decimal values programmatically from integers</span>
<span class="nc">BigDecimal</span> <span class="n">tenth</span> <span class="o">=</span> <span class="nc">BigDecimal</span><span class="o">.</span><span class="na">valueOf</span><span class="o">(</span><span class="mi">1</span><span class="o">).</span><span class="na">movePointLeft</span><span class="o">(</span><span class="mi">1</span><span class="o">);</span>  <span class="c1">// Start from exact integer 1</span></code></pre></figure>

<p>But for <strong>hardcoded monetary values</strong> in your own code, skip doubles entirely and use string literals:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">price</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"0.10"</span><span class="o">);</span></code></pre></figure>

<p>The real rule is about <strong>where the value originates</strong>:</p>

<ul>
  <li>If the value is born in your domain as a decimal (prices, rates, balances), create it from a decimal representation (<code class="language-plaintext highlighter-rouge">String</code>, <code class="language-plaintext highlighter-rouge">long</code> + scale).</li>
  <li>If the value is already stuck in a <code class="language-plaintext highlighter-rouge">double</code>, use <code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(double)</code> and treat that conversion as a boundary where precision may already have been lost.</li>
</ul>

<p>BigDecimal will not magically repair a bad choice of primitive type.</p>

<h3 id="quick-comparison">Quick comparison</h3>

<table>
  <thead>
    <tr>
      <th>Expression</th>
      <th>Result</th>
      <th>Use Case</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">new BigDecimal("0.1")</code></td>
      <td>Exact decimal 0.1</td>
      <td>Hardcoded money</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">new BigDecimal(0.1)</code></td>
      <td>0.10000000000…05511 (binary approximation)</td>
      <td>Never use this</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(0.1)</code></td>
      <td>0.1 (canonical string)</td>
      <td>When stuck with double</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">BigDecimal.valueOf(1, 1)</code></td>
      <td>0.1 (1 × 10^-1)</td>
      <td>Programmatic creation</td>
    </tr>
  </tbody>
</table>

<h2 id="exact-sums-predictable-cents">Exact sums, predictable cents</h2>

<p>Here’s a comparison showing why BigDecimal matters for financial code:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// With doubles - unpredictable</span>
<span class="nc">List</span><span class="o">&lt;</span><span class="nc">Double</span><span class="o">&gt;</span> <span class="n">doubleAmounts</span> <span class="o">=</span> <span class="nc">List</span><span class="o">.</span><span class="na">of</span><span class="o">(</span>
    <span class="mf">10000000000000000.00</span><span class="o">,</span>
    <span class="mf">1.00</span><span class="o">,</span> <span class="mf">1.00</span><span class="o">,</span> <span class="mf">1.00</span><span class="o">,</span> <span class="mf">1.00</span>
<span class="o">);</span>
<span class="kt">double</span> <span class="n">doubleSum</span> <span class="o">=</span> <span class="n">doubleAmounts</span><span class="o">.</span><span class="na">stream</span><span class="o">()</span>
    <span class="o">.</span><span class="na">mapToDouble</span><span class="o">(</span><span class="nl">Double:</span><span class="o">:</span><span class="n">doubleValue</span><span class="o">).</span><span class="na">sum</span><span class="o">();</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">doubleSum</span><span class="o">);</span> <span class="c1">// 1.0000000000000004E16</span></code></pre></figure>

<p>The result is mathematically correct (10^16 + 4), but the representation shows how rounding noise creeps in when you mix huge and small magnitudes in binary floating point. At this scale, many consecutive integers are not exactly representable as double, so tiny adjustments end up living in the low bits and surfacing as …0004E16.</p>

<p>Now compare with BigDecimal:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// With BigDecimal - exact</span>
<span class="nc">List</span><span class="o">&lt;</span><span class="nc">BigDecimal</span><span class="o">&gt;</span> <span class="n">amounts</span> <span class="o">=</span> <span class="nc">List</span><span class="o">.</span><span class="na">of</span><span class="o">(</span>
    <span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"10000000000000000.00"</span><span class="o">),</span>
    <span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"1.00"</span><span class="o">),</span>
    <span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"1.00"</span><span class="o">),</span>
    <span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"1.00"</span><span class="o">),</span>
    <span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"1.00"</span><span class="o">)</span>
<span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">sum</span> <span class="o">=</span> <span class="n">amounts</span><span class="o">.</span><span class="na">stream</span><span class="o">()</span>
    <span class="o">.</span><span class="na">reduce</span><span class="o">(</span><span class="nc">BigDecimal</span><span class="o">.</span><span class="na">ZERO</span><span class="o">,</span> <span class="nl">BigDecimal:</span><span class="o">:</span><span class="n">add</span><span class="o">);</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">sum</span><span class="o">);</span> <span class="c1">// 10000000000000004.00</span></code></pre></figure>

<p>No matter how you reorder the BigDecimal list, you will get the same <code class="language-plaintext highlighter-rouge">10000000000000004.00</code>. There is no hidden rounding based on magnitude, because the arithmetic is done on the unscaled integers.</p>

<p>You pay for this determinism. BigDecimal operations are typically 10-100× slower than double, depending on the values involved. But when you reconcile two systems and everything lines up to the last cent, you know where the extra CPU cycles went.</p>

<h2 id="scale-rounding-and-the-joy-of-being-explicit">Scale, rounding, and the joy of being explicit</h2>

<p>With doubles, rounding is automatic and mostly invisible. With BigDecimal, rounding is very much your problem.</p>

<p>Imagine you need to divide 1 rupee into 3 equal parts:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">one</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1.00"</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">three</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"3.00"</span><span class="o">);</span>

<span class="nc">BigDecimal</span> <span class="n">each</span> <span class="o">=</span> <span class="n">one</span><span class="o">.</span><span class="na">divide</span><span class="o">(</span><span class="n">three</span><span class="o">);</span> <span class="c1">// Kaboom: ArithmeticException</span></code></pre></figure>

<p>The exception is deliberate. <code class="language-plaintext highlighter-rouge">1 / 3</code> in decimal form is <code class="language-plaintext highlighter-rouge">0.3333…</code> forever. BigDecimal refuses to guess how many digits you want. You must say how you want the result rounded.</p>

<p>There are two approaches, and knowing when to use which matters.</p>

<h3 id="mathcontext-for-intermediate-calculations">MathContext: For intermediate calculations</h3>

<p>Use <code class="language-plaintext highlighter-rouge">MathContext</code> when you need to control significant digits during computation:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// Calculate pi as 22/7 with 10 significant digits</span>
<span class="nc">MathContext</span> <span class="n">mc</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">MathContext</span><span class="o">(</span><span class="mi">10</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">pi</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"22"</span><span class="o">).</span><span class="na">divide</span><span class="o">(</span>
    <span class="k">new</span> <span class="nf">BigDecimal</span><span class="o">(</span><span class="s">"7"</span><span class="o">),</span> 
    <span class="n">mc</span>
<span class="o">);</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">pi</span><span class="o">);</span> <span class="c1">// 3.142857143</span></code></pre></figure>

<h3 id="setscale-for-final-results">setScale: For final results</h3>

<p>Use <code class="language-plaintext highlighter-rouge">setScale</code> when you need to control decimal places for presentation or storage:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// Round a calculated price to 2 decimal places for currency</span>
<span class="nc">BigDecimal</span> <span class="n">rawPrice</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"12.3456"</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">price</span> <span class="o">=</span> <span class="n">rawPrice</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">);</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">price</span><span class="o">);</span> <span class="c1">// 12.35</span></code></pre></figure>

<h3 id="the-pattern-that-works">The pattern that works</h3>

<p>For currency, a clean approach is:</p>

<ol>
  <li>Decide how many decimal places your business uses (usually 2 for most currencies)</li>
  <li>Store all monetary values with that scale</li>
  <li>When you need intermediate higher precision, use a <code class="language-plaintext highlighter-rouge">MathContext</code> locally</li>
  <li>Bring the value back to your standard scale at the boundaries</li>
</ol>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">rate</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"0.0525"</span><span class="o">);</span> <span class="c1">// 5.25% interest rate</span>
<span class="nc">BigDecimal</span> <span class="n">principal</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1000.00"</span><span class="o">);</span>

<span class="c1">// Higher precision for calculation</span>
<span class="nc">MathContext</span> <span class="n">mc</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">MathContext</span><span class="o">(</span><span class="mi">10</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">interest</span> <span class="o">=</span> <span class="n">principal</span><span class="o">.</span><span class="na">multiply</span><span class="o">(</span><span class="n">rate</span><span class="o">,</span> <span class="n">mc</span><span class="o">);</span>

<span class="c1">// Round to cents for storage</span>
<span class="n">interest</span> <span class="o">=</span> <span class="n">interest</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">);</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">interest</span><span class="o">);</span> <span class="c1">// 52.50</span></code></pre></figure>

<h2 id="equals-is-not-the-same-as-compareto">Equals is not the same as compareTo</h2>

<p>There is a subtle trap buried in BigDecimal’s API:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">x</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1.0"</span><span class="o">);</span>
<span class="nc">BigDecimal</span> <span class="n">y</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1.00"</span><span class="o">);</span>

<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span><span class="o">.</span><span class="na">equals</span><span class="o">(</span><span class="n">y</span><span class="o">));</span>    <span class="c1">// false</span>
<span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="n">x</span><span class="o">.</span><span class="na">compareTo</span><span class="o">(</span><span class="n">y</span><span class="o">));</span> <span class="c1">// 0</span></code></pre></figure>

<p><code class="language-plaintext highlighter-rouge">equals</code> cares about both value and scale. The unscaled integer is <code class="language-plaintext highlighter-rouge">10</code> vs <code class="language-plaintext highlighter-rouge">100</code>, scale is <code class="language-plaintext highlighter-rouge">1</code> vs <code class="language-plaintext highlighter-rouge">2</code>, so the objects are not “equal”.</p>

<p><code class="language-plaintext highlighter-rouge">compareTo</code> cares only about numeric value. From that point of view they are both exactly one, so the comparison says zero.</p>

<p>If you put BigDecimal keys into a <code class="language-plaintext highlighter-rouge">HashMap</code> or <code class="language-plaintext highlighter-rouge">HashSet</code>, you are using <code class="language-plaintext highlighter-rouge">equals</code>. If you put them in a <code class="language-plaintext highlighter-rouge">TreeMap</code> or <code class="language-plaintext highlighter-rouge">TreeSet</code>, you are using <code class="language-plaintext highlighter-rouge">compareTo</code>. That difference has bitten enough people that the Javadoc has an explicit warning<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup>.</p>

<h3 id="what-to-do-about-it">What to do about it</h3>

<p>For financial applications, you typically want value-based comparison:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// Use compareTo for all business logic</span>
<span class="k">if</span> <span class="o">(</span><span class="n">price</span><span class="o">.</span><span class="na">compareTo</span><span class="o">(</span><span class="n">threshold</span><span class="o">)</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="o">)</span> <span class="o">{</span>
    <span class="n">applyDiscount</span><span class="o">();</span>
<span class="o">}</span>

<span class="c1">// Or normalize scale before storing in collections</span>
<span class="nc">BigDecimal</span> <span class="n">normalized</span> <span class="o">=</span> <span class="n">value</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">UNNECESSARY</span><span class="o">);</span>
<span class="n">priceSet</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">normalized</span><span class="o">);</span></code></pre></figure>

<h2 id="common-mistakes">Common mistakes</h2>

<p>Beyond the double constructor trap, watch out for these.</p>

<h3 id="using--for-comparison">Using == for comparison</h3>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// Wrong</span>
<span class="k">if</span> <span class="o">(</span><span class="n">price</span> <span class="o">==</span> <span class="n">threshold</span><span class="o">)</span> <span class="o">{</span> <span class="o">...</span> <span class="o">}</span>

<span class="c1">// Right</span>
<span class="k">if</span> <span class="o">(</span><span class="n">price</span><span class="o">.</span><span class="na">compareTo</span><span class="o">(</span><span class="n">threshold</span><span class="o">)</span> <span class="o">==</span> <span class="mi">0</span><span class="o">)</span> <span class="o">{</span> <span class="o">...</span> <span class="o">}</span></code></pre></figure>

<h3 id="forgetting-rounding-mode">Forgetting rounding mode</h3>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// Throws ArithmeticException</span>
<span class="nc">BigDecimal</span> <span class="n">result</span> <span class="o">=</span> <span class="n">amount</span><span class="o">.</span><span class="na">divide</span><span class="o">(</span><span class="n">three</span><span class="o">);</span>

<span class="c1">// Specify your intent</span>
<span class="nc">BigDecimal</span> <span class="n">result</span> <span class="o">=</span> <span class="n">amount</span><span class="o">.</span><span class="na">divide</span><span class="o">(</span><span class="n">three</span><span class="o">,</span> <span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">HALF_UP</span><span class="o">);</span></code></pre></figure>

<h3 id="mixing-scales-carelessly">Mixing scales carelessly</h3>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="nc">BigDecimal</span> <span class="n">a</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"1.0"</span><span class="o">);</span>   <span class="c1">// scale 1</span>
<span class="nc">BigDecimal</span> <span class="n">b</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">BigDecimal</span><span class="o">(</span><span class="s">"2.00"</span><span class="o">);</span>  <span class="c1">// scale 2</span>
<span class="nc">BigDecimal</span> <span class="n">sum</span> <span class="o">=</span> <span class="n">a</span><span class="o">.</span><span class="na">add</span><span class="o">(</span><span class="n">b</span><span class="o">);</span>              <span class="c1">// scale 2 (max of the two)</span>

<span class="c1">// Result may have unexpected scale; normalize when it matters</span>
<span class="c1">// Note: UNNECESSARY throws ArithmeticException if rounding would be needed</span>
<span class="n">sum</span> <span class="o">=</span> <span class="n">sum</span><span class="o">.</span><span class="na">setScale</span><span class="o">(</span><span class="mi">2</span><span class="o">,</span> <span class="nc">RoundingMode</span><span class="o">.</span><span class="na">UNNECESSARY</span><span class="o">);</span></code></pre></figure>

<h2 id="when-should-you-actually-use-bigdecimal">When should you actually use BigDecimal?</h2>

<p>BigDecimal is not a “better double”. It is a different tool.</p>

<p>Reach for BigDecimal when:</p>

<ul>
  <li>You are working with money, interest rates, exchange rates, or anything that must reconcile to the cent or paise</li>
  <li>You are implementing rules that are written in decimal terms by humans and regulators, not in binary terms by hardware engineers</li>
  <li>You care more about correctness and determinism than raw speed</li>
</ul>

<p>Stay with doubles when:</p>

<ul>
  <li>You are doing heavy numeric computing, simulations, statistics, graphics, or ML workloads where small rounding error is acceptable and performance dominates</li>
  <li>You are counting in powers of two, not powers of ten</li>
  <li>The measurements themselves are imprecise (sensor readings, physical measurements)</li>
</ul>

<p>You can always convert between the two worlds at clearly defined boundaries.</p>

<h2 id="closing-thought">Closing thought</h2>

<p>BigDecimal is not slow magic. It is a disciplined refusal to lie about decimals.</p>

<p>Doubles take a binary view of the universe and do their best to approximate your decimal stories. BigDecimal takes your decimal stories literally and forces you to be explicit about where information is lost.</p>

<p>Neither is the “right” choice in isolation. The trick is to know which world you are in.</p>

<h2 id="references">References</h2>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>BigDecimal Java 17 JavaDocs: https://docs.oracle.com/en/java/javase/17/docs/api/java.base/java/math/BigDecimal.html#equals(java.lang.Object) <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="[&quot;Computer Science&quot;, &quot;Software Engineering&quot;, &quot;Technology&quot;, &quot;Series 4 - Floating Point Without Tears&quot;]" /><category term="java" /><category term="bigdecimal" /><category term="ieee-754" /><category term="money" /><category term="numeric-precision" /><summary type="html"><![CDATA[Why BigDecimal exists, how it really works, and when you should reach for it instead of double.]]></summary></entry><entry><title type="html">Reforming the Security Council Without Breaking Trust</title><link href="https://systemhalted.in/2025/12/22/reforming-unsc-without-breaking-trust/" rel="alternate" type="text/html" title="Reforming the Security Council Without Breaking Trust" /><published>2025-12-22T00:00:00+00:00</published><updated>2025-12-22T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/22/reforming-unsc-without-breaking-trust</id><content type="html" xml:base="https://systemhalted.in/2025/12/22/reforming-unsc-without-breaking-trust/"><![CDATA[<p>I have written about United Nations Security Council reforms before, and the older I get, the more I realize this is not a topic that rewards anger. It rewards clarity.</p>

<p>The Security Council was designed in a specific world. The year was 1945. The problem statement was simple and terrifying: prevent another world war. The veto was not invented as a moral idea. It was a stability mechanism. If the strongest powers of that era were expected to participate in a system, they needed assurance that the system would not be used against what they consider existential interests. You may dislike that logic, but you cannot pretend it is irrational. It is the kind of logic that keeps institutions alive.</p>

<p>Still, a system can be historically justified and yet feel increasingly mismatched to the world it is supposed to manage. When that mismatch grows, two things happen.</p>

<p>First, decisions start looking less legitimate to those who are asked to accept them.</p>

<p>Second, countries start routing around the institution when it feels slow, unpredictable, or politically costly.</p>

<p>Both outcomes are bad. Legitimacy without power becomes poetry. Power without legitimacy becomes noise. The world needs less noise.</p>

<p>So the best way to talk about Security Council reform is not as a fight between “the powerful” and “the rest.” The best way is to ask a practical question.</p>

<p>How do we keep the Council authoritative enough that major powers remain invested in it, while making it representative enough that the wider world respects it?</p>

<p>That question matters because reform that ignores incentives will not produce a better Security Council. It will produce an ignored Security Council. And an ignored Security Council is not a victory for democracy. It is a victory for chaos.</p>

<p>So my goal here is not to write a fantasy about “abolishing the veto.” Charter change is hard, and the Charter is designed to be hard to change. The goal is more modest and more practical.</p>

<p>Make obstruction more accountable, more legible, and harder to perform casually, without pretending we can enforce good faith.</p>

<p>I will do three things for each proposal.</p>

<ol>
  <li>Describe what happens today.</li>
  <li>Define a concrete additional process.</li>
  <li>Explain why it helps, including where it can still fail.</li>
</ol>

<h2 id="1-make-veto-use-more-accountable-not-weaker">1. Make veto use more accountable, not weaker</h2>

<h3 id="what-happens-today">What happens today</h3>

<p>A substantive Council decision needs at least nine affirmative votes and no negative vote from any permanent member. One negative vote by a permanent member blocks the draft. That is the veto. (UN Charter, Article 27)<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<p>After the veto, accountability is mostly reputational.</p>

<p>Yes, the veto is public. Voting records exist. Explanations may be offered in the chamber. But the content is unstructured and often optimized for politics, not clarity.</p>

<p>Since 2022, there is also a formal spotlight mechanism. When a veto is cast, the General Assembly President must convene a debate within ten working days. The Assembly “invites” the Council to submit a special report on the veto at least 72 hours before the debate. (UNGA resolution 76/262)<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> The important word there is “invites.” It raises political cost, but it does not force precision, and it does not force participation. Analysts have noted that the resolution does not impose obligations on the vetoing state to even show up.<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<h3 id="what-i-propose">What I propose</h3>

<p>A veto should trigger a short, mandatory, structured “Veto Brief” filed as an official UN document within 48 hours.</p>

<p>Not an essay. A template with hard edges.</p>

<p>The brief must include:</p>

<ol>
  <li>
    <p>Pinpoint objection<br />
Identify exactly which operative paragraphs are unacceptable.</p>
  </li>
  <li>
    <p>Factual predicates<br />
List the key factual claims the veto relies on, written as testable statements.</p>
  </li>
  <li>
    <p>Principle being invoked<br />
Cite Charter articles if needed, but state the real test in plain language. The Charter citation supports the argument. It cannot replace the argument.</p>
  </li>
  <li>
    <p>Acceptable path to “yes”<br />
Provide at least one concrete amendment or alternative text that would remove the need for a veto.</p>
  </li>
  <li>
    <p>Review trigger<br />
If the veto is conditional, state the conditions and a review date for reconsideration.</p>
  </li>
</ol>

<p>Then, within seven days, the Council schedules a short “Veto Consequences” session. Ten minutes for the vetoing member to present the brief, then a time-boxed round of questions from elected members. No moral theatre required. Just structured daylight.</p>

<p>Finally, add one small but sharp piece of enforcement that costs almost nothing.</p>

<p>If the vetoing member does not file the brief, that non-submission is recorded in the Council’s official meeting record, and it is flagged in the General Assembly debate convened under 76/262.<sup id="fnref:2:1"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> The veto remains valid, but the refusal becomes part of the permanent archive and part of the public debate.</p>

<p>To prevent a perfunctory brief that merely checks boxes, the Council President should record whether the brief is <strong>responsive</strong> to the template (i.e., it contains a concrete “path to yes” and specific factual predicates, not generic slogans). A non-responsive brief is treated like a non-submission for the purposes of the General Assembly debate, where <strong>the adequacy of the brief becomes a formal topic</strong>–members can explicitly challenge missing predicates, evasive language, or the absence of any acceptable alternative.<sup id="fnref:2:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<h3 id="why-it-helps-and-where-it-can-fail">Why it helps, and where it can fail</h3>

<p>The honest criticism is correct: “What if powerful states don’t care?”</p>

<p>Some don’t. History is not shy about that.</p>

<p>But accountability is not only about changing minds. It is also about changing the friction profile of a behavior.</p>

<p>This mechanism raises the cost of vetoing in three ways that do not require new UN spending.</p>

<ol>
  <li>
    <p>It shifts effort onto the actor choosing the veto.<br />
The UN does not hire a new bureaucracy. The vetoing mission uses its existing staff to produce a short document.</p>
  </li>
  <li>
    <p>It removes the fog that makes performative vetoes easy.<br />
If you must state what you would accept, you cannot veto and disappear into slogans.</p>
  </li>
  <li>
    <p>It makes patterns visible over time.<br />
A veto is a single moment. A trail of structured briefs becomes a story.</p>
  </li>
</ol>

<p>A concrete example shows the dysfunction today.</p>

<p>On Syria, vetoes have been repeatedly used to block action on drafts concerning the conflict and humanitarian mechanisms. Security Council Report notes that since 2011, Russia cast 19 vetoes, with 14 on Syria, and that eight of nine Chinese vetoes in that period were on Syria.<sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup> The UN’s own research guide lists vetoed Syria-related drafts across multiple years.<sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<p>A structured veto brief would not magically unlock consensus, but it would force two things that are often missing.</p>

<p>First, explicit alternative text, on the record, each time.</p>

<p>Second, explicit factual predicates, which can be challenged publicly in the General Assembly debate already mandated after a veto.<sup id="fnref:2:3"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>Failure mode still exists. A determined vetoing member can absorb reputational costs. But even then, the system gains something it currently lacks: a clear, testable record of what was blocked and what compromise was refused.</p>

<p>That clarity matters to history, to diplomacy, and to any future negotiation.</p>

<h2 id="2-build-a-norm-of-restraint-for-mass-atrocities-and-make-the-norm-operational">2. Build a norm of restraint for mass atrocities, and make the norm operational</h2>

<h3 id="what-happens-today-1">What happens today</h3>

<p>There is no binding rule preventing veto use in situations involving genocide, crimes against humanity, or war crimes.</p>

<p>There are voluntary initiatives.</p>

<p>The ACT Code of Conduct asks states to support timely and decisive action to prevent or end mass atrocity crimes, and calls on Council members not to vote against credible action aimed at stopping them.<sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup> There is also the France–Mexico initiative calling for voluntary restraint on veto use in mass atrocity situations.<sup id="fnref:7"><a href="#fn:7" class="footnote" rel="footnote" role="doc-noteref">7</a></sup></p>

<p>These matter. But voluntary norms have a familiar weakness: they work best when they are not needed.</p>

<h3 id="what-i-propose-1">What I propose</h3>

<p>Convert “restraint” from a moral appeal into a repeatable procedure.</p>

<p>Create a “Mass Atrocity Track” for draft resolutions explicitly aimed at preventing or halting atrocity crimes.</p>

<p>If a draft is placed on this track, then any veto triggers two additional obligations inside the veto brief.</p>

<ol>
  <li>
    <p>Civilian impact claim<br />
A short statement explaining why the vetoing member believes the draft would worsen civilian protection outcomes, or violate a principle in a way that outweighs the harm of inaction.</p>
  </li>
  <li>
    <p>Alternative protection path<br />
A concrete alternative proposal that still targets civilian protection, even if it changes the means.</p>
  </li>
</ol>

<p>Then impose one simple process requirement.</p>

<p>Within 14 days of a veto on the atrocity track, the Council must vote on at least one alternative draft addressing the same civilian protection objective, even if it is imperfect.</p>

<p>This is not “forcing agreement.” It is forcing effort.</p>

<h3 id="why-it-helps-and-what-happens-if-the-veto-still-blocks-action">Why it helps, and what happens if the veto still blocks action</h3>

<p>The nightmare scenario is real.</p>

<p>What if this process exists and a veto still blocks action during an active genocide?</p>

<p>Then the Council’s impotence becomes more transparent.</p>

<p>That sounds grim, but transparency is not nothing. Opacity is how paralysis becomes normal.</p>

<p>The additional value here is that the mandated General Assembly debate after a veto (76/262) becomes better informed. Instead of debating fog, the wider membership debates a structured record that includes what alternative protection pathways were offered or not offered.<sup id="fnref:2:4"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>

<p>And yes, powerful states can still ignore the norm. But a norm tied to a forced iteration loop changes behavior at the margin, and “at the margin” is often where real lives are saved.</p>

<h2 id="3-expand-membership-with-a-specific-shape-and-admit-the-trade-offs">3. Expand membership with a specific shape, and admit the trade offs</h2>

<h3 id="what-happens-today-2">What happens today</h3>

<p>The Council has 15 members: five permanent, ten elected for two-year terms. (UN Charter, Article 23)<sup id="fnref:8"><a href="#fn:8" class="footnote" rel="footnote" role="doc-noteref">8</a></sup></p>

<p>Those ten elected seats are distributed by regional groups: three for Africa, two for Asia Pacific, two for Latin America and the Caribbean, two for Western Europe and Others, and one for Eastern Europe.<sup id="fnref:9"><a href="#fn:9" class="footnote" rel="footnote" role="doc-noteref">9</a></sup></p>

<p>Two problems follow from this design.</p>

<p>First, two years is short. Many elected members become effective only when their term is ending.</p>

<p>Second, representation is frozen in a world that has changed.</p>

<h3 id="what-i-propose-2">What I propose</h3>

<p>A concrete model that sits between “keep it at 15 forever” and “blow it up to 25 plus overnight” is this.</p>

<p>Expand from 15 to 21 members by adding six longer-term renewable seats, without adding new vetoes.</p>

<ol>
  <li>Keep the current 10 two-year elected seats and their existing regional distribution.<sup id="fnref:9:1"><a href="#fn:9" class="footnote" rel="footnote" role="doc-noteref">9</a></sup></li>
  <li>Add six renewable seats with four-year terms, eligible for immediate re-election once.<br />
Four years is long enough to build genuine file expertise and relationships; short enough that renewal still means something.</li>
  <li>Allocate those six seats by region as follows:
2 Africa<br />
2 Asia Pacific<br />
1 Latin America and the Caribbean<br />
1 split rotation between Eastern Europe and Small Island Developing States</li>
</ol>

<p>This is not the only possible distribution. The point is to stop hand waving and put a shape on the table.</p>

<p>It also aligns with the core complaint that the current Council has no permanent representation for Africa or Latin America, a point repeatedly raised in reform debates.<sup id="fnref:10"><a href="#fn:10" class="footnote" rel="footnote" role="doc-noteref">10</a></sup></p>

<h3 id="who-defines-the-criteria-and-why-would-anyone-accept-them">Who defines the criteria, and why would anyone accept them?</h3>

<p>Criteria should be defined by the General Assembly through the ongoing intergovernmental negotiations process, not by the permanent members alone. The politics are difficult, but the venue is clear.<sup id="fnref:11"><a href="#fn:11" class="footnote" rel="footnote" role="doc-noteref">11</a></sup></p>

<p>A Charter amendment is still required for composition change, and Charter amendments require ratification including by all permanent members. (UN Charter, Article 108)<sup id="fnref:12"><a href="#fn:12" class="footnote" rel="footnote" role="doc-noteref">12</a></sup></p>

<p>That is the hard wall. No serious reform should pretend it is not there.</p>

<p>So the real strategy is phased.</p>

<p>Phase 1 is working-methods reform that does not require Charter amendment. Veto briefs, structured hearings, iteration loops.</p>

<p>Phase 2 is composition reform, which requires a broader bargain.</p>

<h3 id="trade-off-larger-councils-can-be-slower">Trade off: larger councils can be slower</h3>

<p>This is a real risk. Larger groups can move slower, and more seats can add friction.</p>

<p>The mitigation is to keep the extra seats longer-term and renewable. Continuity reduces the constant onboarding churn that already slows the Council today.</p>

<p>Another mitigation is procedural discipline: time-limited negotiations, published draft histories, and structured “what would unlock agreement” fields, so debate does not become infinite.</p>

<p>And it is worth noting a counterweight to the “bigger means slower” argument: the Council already runs at high tempo. In 2024 it held 305 formal meetings (a record), which suggests there is procedural capacity for a modest increase in membership without fundamentally changing the Council’s operating rhythm.<sup id="fnref:15"><a href="#fn:15" class="footnote" rel="footnote" role="doc-noteref">13</a></sup></p>

<h2 id="4-replace-permanent-forever-with-long-term-renewable-as-a-direction-the-system-can-actually-walk">4. Replace “permanent forever” with “long term renewable,” as a direction the system can actually walk</h2>

<h3 id="what-happens-today-3">What happens today</h3>

<p>Permanence is embedded in the Charter. Removing it is not politically realistic in the near term.<sup id="fnref:12:1"><a href="#fn:12" class="footnote" rel="footnote" role="doc-noteref">12</a></sup></p>

<p>But “near term realism” is not the same as “long term surrender.”</p>

<h3 id="what-i-propose-3">What I propose</h3>

<p>Treat renewable legitimacy as a parallel prestige track.</p>

<p>Build up the longer-term renewable seats described above. Make them consequential. Make them hard to win and easy to lose if a state does not sustain contribution and responsibility.</p>

<p>Over time, those seats become the institution’s living legitimacy mechanism.</p>

<p>There is precedent for this kind of design in regional security bodies. The African Union Peace and Security Council has 15 members, with five elected for three-year terms and ten for two-year terms, and it has no permanent members and no veto. It uses rotation and re-election to balance continuity with legitimacy.<sup id="fnref:13"><a href="#fn:13" class="footnote" rel="footnote" role="doc-noteref">14</a></sup></p>

<p>The AU PSC is not the UN, and global politics are nastier than regional politics. But the institutional idea is useful: continuity without permanence, and influence that must be renewed.</p>

<h3 id="why-it-helps-even-if-the-old-structure-remains">Why it helps, even if the old structure remains</h3>

<p>Because it creates a pathway where legitimacy is something you keep earning, not something you inherit.</p>

<p>Even if permanence stays, renewable seats can gradually shift the Council’s center of gravity toward responsibility-based legitimacy.</p>

<h2 id="5-stakeholder-buy-in-and-how-to-build-a-coalition-that-does-not-require-miracles">5. Stakeholder buy in, and how to build a coalition that does not require miracles</h2>

<p>This is where the earlier draft was too optimistic by omission.</p>

<p>The Council does not reform because someone writes a good blog post.
It reforms when enough states can see a bargain.</p>

<p>There are already two building blocks.</p>

<p>First, the veto initiative (76/262) was adopted by consensus, and it has already triggered repeated debates after vetoes.<sup id="fnref:2:5"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> UN press reporting in November 2025 noted that multiple vetoes had triggered corresponding General Assembly debates under this mechanism.<sup id="fnref:14"><a href="#fn:14" class="footnote" rel="footnote" role="doc-noteref">15</a></sup></p>

<p>Second, there are existing coalitions around voluntary restraint and working methods, like the ACT group’s Code of Conduct.<sup id="fnref:6:1"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup></p>

<p>A practical coalition path looks like this.</p>

<ol>
  <li>Start with elected members and accountability-minded middle powers pushing working methods reforms, because working methods do not require Charter change.</li>
  <li>Use the General Assembly debate mechanism after each veto to normalize structured records and structured questions.<sup id="fnref:2:6"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></li>
  <li>Build a “default expectation” that a veto without a brief is a veto without legitimacy, even if it remains legally valid.</li>
  <li>Only then push composition reform, when the system has already shifted culturally toward accountability.</li>
</ol>

<p>This does not guarantee success. It does something more valuable.</p>

<p>It creates a ratchet. A direction. A path that can be walked.</p>

<h2 id="closing-thought">Closing thought</h2>

<p>Institutional design cannot force good faith. But it can punish bad faith with friction, sunlight, and repetition.</p>

<p>The veto will remain a power tool. The question is whether it remains a power tool that operates in fog, or a power tool that must operate in daylight.</p>

<p>In fog, the Council becomes theatre.
In daylight, it at least becomes a record.
And sometimes, that record becomes the first step toward a better bargain.</p>

<h2 id="references">References</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>United Nations Charter, Article 27 (Voting): https://www.un.org/en/about-us/un-charter/chapter-5 <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>UN General Assembly Resolution 76/262: https://docs.un.org/en/a/res/76/262 <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:2:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a> <a href="#fnref:2:2" class="reversefootnote" role="doc-backlink">&#8617;<sup>3</sup></a> <a href="#fnref:2:3" class="reversefootnote" role="doc-backlink">&#8617;<sup>4</sup></a> <a href="#fnref:2:4" class="reversefootnote" role="doc-backlink">&#8617;<sup>5</sup></a> <a href="#fnref:2:5" class="reversefootnote" role="doc-backlink">&#8617;<sup>6</sup></a> <a href="#fnref:2:6" class="reversefootnote" role="doc-backlink">&#8617;<sup>7</sup></a></p>
    </li>
    <li id="fn:3">
      <p>Analysis noting 76/262 imposes no obligations to attend and mainly increases political cost: https://www.osorin.it/uploads/model_4/.files/199_item_2.pdf?v=1747211642 <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>Security Council Report, “The Veto”: https://www.securitycouncilreport.org/un-security-council-working-methods/the-veto.php <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>UN Research Guide, Security Council veto list: https://research.un.org/en/docs/sc/quick <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:6">
      <p>ACT Code of Conduct (A/70/621–S/2015/978): https://docs.un.org/en/A/70/621 <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:6:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:7">
      <p>France–Mexico initiative on veto restraint in mass atrocities: https://centerforunreform.org/wp-content/uploads/2015/10/French-Mexican-Proposal-English.pdf <a href="#fnref:7" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:8">
      <p>United Nations Charter, Article 23 (Composition): https://www.un.org/en/about-us/un-charter/chapter-5 <a href="#fnref:8" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:9">
      <p>Regional distribution of elected seats (summary): https://futures.issafrica.org/thematic/19-un-security-council/ <a href="#fnref:9" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:9:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:10">
      <p>Example analysis of Africa’s reform position and representation arguments: https://www.csis.org/analysis/africas-design-reformed-un-security-council <a href="#fnref:10" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:11">
      <p>UN GA Security Council reform process documents (element paper): https://www.un.org/en/ga/screform/78/pdf/2024-04-05-cochairs-revised-element-paper.pdf <a href="#fnref:11" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:12">
      <p>United Nations Charter, Article 108 (Amendments): https://www.un.org/en/about-us/un-charter/chapter-18 <a href="#fnref:12" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:12:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:15">
      <p>UN Security Council, “Highlights of Security Council Practice 2024” (meeting totals): https://main.un.org/securitycouncil/en/content/highlights-2024 <a href="#fnref:15" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:13">
      <p>African Union Peace and Security Council structure and terms: https://www.peaceau.org/en/page/39-secretariat-psc <a href="#fnref:13" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:14">
      <p>UN Press, 2025 GA debate noting repeated veto initiative debates: https://press.un.org/en/2025/ga12733.doc.htm <a href="#fnref:14" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Politics &amp; Governance" /><category term="un" /><category term="unsc" /><category term="security-council" /><category term="reform" /><category term="diplomacy" /><category term="governance" /><summary type="html"><![CDATA[A practical case for UNSC reform that preserves stability, legitimacy, and the incentives for major powers to stay invested.]]></summary></entry><entry><title type="html">Escaping GOTO: How We Learned to Make Programs Readable</title><link href="https://systemhalted.in/2025/12/17/escaping-goto/" rel="alternate" type="text/html" title="Escaping GOTO: How We Learned to Make Programs Readable" /><published>2025-12-17T00:00:00+00:00</published><updated>2025-12-17T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/17/escaping-goto</id><content type="html" xml:base="https://systemhalted.in/2025/12/17/escaping-goto/"><![CDATA[<p>In early BASIC, the line numbers felt like street addresses.</p>

<p>You could point to a place in your program and say: “Go there.”
The computer would nod, politely, and do exactly that.</p>

<p>And for a beginner, this felt comforting. Orderly. Almost architectural.</p>

<figure class="highlight"><pre><code class="language-basic" data-lang="basic">10 PRINT "Hello"
20 PRINT "World"
30 END</code></pre></figure>

<p>A neat little staircase of intentions.</p>

<p>Then we learned the spell.</p>

<h2 id="the-seduction-of-goto">The seduction of GOTO</h2>

<p>GOTO is the programming equivalent of discovering you can teleport.</p>

<p>Why walk like a peasant when you can jump?</p>

<p>Want a loop? Jump back.</p>

<figure class="highlight"><pre><code class="language-basic" data-lang="basic">10 LET X = 0
20 LET X = X + 1
30 PRINT X
40 IF X &lt; 5 THEN GOTO 20
50 END</code></pre></figure>

<p>It works. It’s simple. It even feels clever.</p>

<p>But teleportation has a cost: once you start jumping, your program stops being a story and becomes a maze.</p>

<h2 id="the-day-basic-stopped-feeling-friendly">The day BASIC stopped feeling friendly</h2>

<p>At some point the program gets longer than your short-term memory.</p>

<p>You add one more rule. Then another.</p>

<p>Now you’re jumping forward to handle special cases, jumping back to repeat, jumping sideways to “retry,” and suddenly you’re not writing code.</p>

<p>You’re playing detective.</p>

<p>Here’s the kind of shape that starts to appear:</p>

<figure class="highlight"><pre><code class="language-basic" data-lang="basic">10 INPUT "Enter a number (1-10)"; N
20 IF N &lt; 1 THEN GOTO 90
30 IF N &gt; 10 THEN GOTO 90
40 PRINT "OK"
50 GOTO 110
90 PRINT "Invalid. Try again."
100 GOTO 10
110 END</code></pre></figure>

<p>This is still readable.</p>

<p>But scale it up a bit: ten validations, multiple modes, nested loops, an error path, a “back” option, and suddenly the logic is scattered across line numbers like breadcrumbs thrown into a hurricane.</p>

<p>You don’t read it anymore.
You trace it.</p>

<p>Tracing burns attention. Attention is expensive.</p>

<p>That’s the real crime of spaghetti code: not aesthetics, cognitive cost.</p>

<h2 id="why-it-turns-into-spaghetti">Why it turns into spaghetti</h2>

<p>A clean program has a shape you can hold in your head:</p>

<p>Start → do things → finish.</p>

<p>Unstructured jumps destroy that shape.</p>

<p>GOTO breaks the one promise your reader desperately wants: that control flow will be local and predictable.</p>

<p>If any line can jump to any other line, then every line must be read with paranoia.</p>

<p>That’s not programming. That’s anxiety with line numbers.</p>

<h2 id="the-escape-structured-programming">The escape: structured programming</h2>

<p>Structured programming wasn’t invented to be fancy.
It was invented to make code readable at scale.</p>

<p>Instead of “jump anywhere,” you get a small set of composable structures:<br />
	•	sequence (do this, then that) <br />
	•	selection (if/else) <br />
	•	iteration (for/while)</p>

<p>You still do the same things, but the control flow becomes visible again.</p>

<p>Here’s the key move: instead of scattering retry logic across labels, you put it inside a loop.</p>

<p>If your BASIC dialect supports WHILE…WEND (many did), you can do:</p>

<figure class="highlight"><pre><code class="language-basic" data-lang="basic">10 PRINT "Enter a number (1-10)"
20 INPUT N
30 WHILE N &lt; 1 OR N &gt; 10
40   PRINT "Invalid. Try again."
50   INPUT N
60 WEND
70 PRINT "OK"
80 END</code></pre></figure>

<p>Now the program reads like a story again:</p>

<p>Ask → repeat until valid → proceed.</p>

<p>Same behavior. Different shape.</p>

<p>And that shape is the whole point.</p>

<h2 id="the-lesson-dont-use-goto">The lesson: don’t use GOTO</h2>

<p>Here’s the grown-up version, stated plainly:</p>

<p>Don’t use GOTO.</p>

<p>Yes, there are rare cases where it can be used carefully: generated code, constrained environments, or very low-level cleanup paths.</p>

<p>But that’s not the world most of us are programming in.</p>

<p>In real software, with real teammates and real deadlines, GOTO is a trap. It makes control flow non-local, and non-local flow makes reasoning expensive. It turns debugging into archaeology.</p>

<p>So the beginner-to-professional upgrade is simple:</p>

<p>Stop jumping. Start structuring.</p>

<p>If you need to repeat, use a loop.
If you need to choose, use IF…THEN…ELSE.
If you need to reuse, use a function.
If you need to abort, return early or throw an error.</p>

<p>Your future self will thank you. Your teammates will thank you. Your pager will thank you.</p>

<h2 id="final-thoughts">Final Thoughts</h2>

<p>Logo taught me wonder: move the turtle, watch a picture appear.</p>

<p>BASIC taught me discipline: tell the machine exactly what to do, step by step.</p>

<p>But the most important thing BASIC taught me might be this:</p>

<p>A program is not just instructions for a computer.</p>

<p>It is a story for the next human.</p>

<p>And the moment your story needs a map and a compass, you’ve stopped writing a program and started writing a trap.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Computer Science" /><category term="Series 2 - Turtle, BASIC, and the Long Road to Taste" /><category term="basic" /><category term="gw-basic" /><category term="goto" /><category term="structured-programming" /><category term="programming" /><category term="software-engineering" /><summary type="html"><![CDATA[Line numbers made BASIC feel orderly. GOTO made it powerful. Then everything turned into spaghetti.]]></summary></entry><entry><title type="html">BASIC: The Language That Taught Me to Think Step by Step</title><link href="https://systemhalted.in/2025/12/16/basic-programming-lang/" rel="alternate" type="text/html" title="BASIC: The Language That Taught Me to Think Step by Step" /><published>2025-12-16T00:00:00+00:00</published><updated>2025-12-16T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/16/basic-programming-lang</id><content type="html" xml:base="https://systemhalted.in/2025/12/16/basic-programming-lang/"><![CDATA[<p>Logo taught me to draw.</p>

<p>BASIC taught me to instruct.</p>

<p>If Logo felt like whispering wishes to a turtle, BASIC felt like standing next to a machine and giving it crisp, literal orders. Not suggestions. Not vibes. Orders.</p>

<p>And the machine was obedient in the way only machines can be: perfectly, relentlessly, and without mercy for ambiguity.</p>

<h2 id="the-basic-mindset-the-computer-is-dumb-so-be-precise">The BASIC mindset: the computer is dumb, so be precise</h2>

<p>BASIC’s core lesson is simple:</p>

<p>Computers do not infer intent.
They execute steps.</p>

<p>So you learn to think in sequences: <br />
	1.	Put the input somewhere.  <br />
	2.	Transform it in small moves. <br />
	3.	Store intermediate results. <br />
	4.	Print the outcome.  <br />
	5.	Stop.</p>

<p>That “step-by-step” habit is not just syntax. It is a worldview.</p>

<h2 id="programs-as-recipes-not-drawings">Programs as recipes, not drawings</h2>

<p>In Logo, the turtle is the main character. You tell it to move, and the picture emerges.</p>

<p>In BASIC, the program itself is the main character. It is a recipe.</p>

<p>Here’s the kind of thing early BASIC invites you to write:</p>

<figure class="highlight"><pre><code class="language-basic" data-lang="basic">10 INPUT “Enter side length”; S
20 P = 4 * S
30 PRINT “Perimeter = “; P
40 END</code></pre></figure>

<p>No magic. No hidden state. No geometry fairy.</p>

<p>Just: ask, compute, print.</p>

<p>And even that tiny program quietly teaches important ideas:<br />
variables, arithmetic, input/output, and the idea that a program is a controlled sequence of actions.</p>

<h2 id="line-numbers-the-original-breadcrumb-trail">Line numbers: the original breadcrumb trail</h2>

<p>The first thing you notice in old-school BASIC is the line numbers.</p>

<p>They are not decoration. They are control points.</p>

<p>You don’t just write code.<br />
You create a path the computer will walk.</p>

<figure class="highlight"><pre><code class="language-basic" data-lang="basic">10 PRINT “I will count.”
20 FOR I = 1 TO 5
30 PRINT I
40 NEXT I
50 PRINT “Done.”</code></pre></figure>

<p>The flow is visible, like a little parade.</p>

<p>And once you learn that you can jump…</p>

<h2 id="goto-power-then-chaos">GOTO: power, then chaos</h2>

<p>BASIC makes it very easy to say: “Go there next.”</p>

<figure class="highlight"><pre><code class="language-basic" data-lang="basic">10 LET X = 0
20 LET X = X + 1
30 PRINT X
40 IF X &lt; 5 THEN GOTO 20
50 END</code></pre></figure>

<p>This works. It is also the seed of future pain.</p>

<p>Because once your program becomes a web of jumps, your brain becomes a detective in a bad mystery novel. Every GOTO is a plot twist.</p>

<p>This is why people later talked about “structured programming”: it’s not about being fancy, it’s about keeping the story readable.</p>

<h2 id="state-is-the-real-subject">State is the real subject</h2>

<p>In BASIC, you’re always holding state in your hands.</p>

<p>Variables are the center of gravity. They change, they accumulate, they persist.</p>

<p>That teaches a different kind of thinking than Logo:</p>

<p>Logo: move an agent, watch an effect</p>

<p>BASIC: change a value, watch consequences</p>

<p>And you start noticing patterns:
	•	Counters
	•	Accumulators
	•	Flags
	•	Branches
	•	Loops</p>

<p>In other words: the basic building blocks of the “imperative” style of programming, where you tell the machine how to do the job, not just what you want.</p>

<h2 id="error-messages-as-teachers">Error messages as teachers</h2>

<p>BASIC’s errors are blunt little teachers.</p>

<p>“Syntax error.”  <br />
“Type mismatch.”   <br />
“Out of data.”</p>

<p>Each one says: you assumed the computer would guess what you meant. It will not.</p>

<p>So you learn to be explicit.<br />
You learn to reduce ambiguity.<br />
You learn to debug.</p>

<p>Not as a skill for code, but as a skill for thought.</p>

<h2 id="the-punchline">The punchline</h2>

<p>Logo gave me wonder.<br />
BASIC gave me discipline.</p>

<p>Logo made me feel like programming was art.<br />
BASIC made me feel like programming was logic.</p>

<p>And both were true.</p>

<p>BASIC’s gift is not that it’s the most elegant language.<br />
Its gift is that it forces you to think like a machine for a while.</p>

<p>And once you can do that, you can later learn the higher trick: how to make machines feel a little more human.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Computer Science" /><category term="Series 2 - Turtle, BASIC, and the Long Road to Taste" /><category term="basic" /><category term="gw-basic" /><category term="education" /><category term="imperative-programming" /><category term="programming-language" /><summary type="html"><![CDATA[How BASIC’s “tell the machine exactly what to do” mindset shaped how I learned programming.]]></summary></entry><entry><title type="html">Logo Looks Nothing Like Lisp and Yet It Is</title><link href="https://systemhalted.in/2025/12/15/is-logo-a-lisp/" rel="alternate" type="text/html" title="Logo Looks Nothing Like Lisp and Yet It Is" /><published>2025-12-15T00:00:00+00:00</published><updated>2025-12-15T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/15/is-logo-a-lisp</id><content type="html" xml:base="https://systemhalted.in/2025/12/15/is-logo-a-lisp/"><![CDATA[<p>It was in 1991 that my school<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> introduced Computer Science for everyone from class IV onwards. It was the first school in Agra<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> to do so<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup>. Luckily for me I was in class IV and was excited to learn Computer Science.</p>

<p>The first day of the class we were excited. We did not get to see the newly build Computer Labs but were told lots about Computers - what is a computer? what is data? what is meaningful information? cpu, alu, monitor, keyboard and the funniest of all - the mouse. Soon we progressed to learn programming and the language of choice for that was <strong>Logo</strong><sup id="fnref:4"><a href="#fn:4" class="footnote" rel="footnote" role="doc-noteref">4</a></sup>.</p>

<p>In Class IV, Logo felt like magic with training wheels.</p>

<p>A turtle sat at the center of the screen and waited for commands. You would say:</p>

<figure class="highlight"><pre><code class="language-logo" data-lang="logo">FD 50 RT 90 FD 50 RT 90 FD 50 RT 90 FD 50 HT</code></pre></figure>

<p>and a square would appear, as if geometry had agreed to be friendly for once.</p>

<h2 id="logo-is-lisp">Logo is Lisp?</h2>

<p>Years later, I discovered a fact that sounds like a prank until you stare at it long enough:</p>

<p>Logo is often described as a dialect of Lisp, or at least a Lisp-family language.<sup id="fnref:5"><a href="#fn:5" class="footnote" rel="footnote" role="doc-noteref">5</a></sup></p>

<p>That claim is confusing at first because Logo does not look like Lisp. Lisp is famously parenthesized. Logo is famously turtle-ish. So what gives?</p>

<p>The trick is that “dialect” here is not about surface syntax<sup id="fnref:6"><a href="#fn:6" class="footnote" rel="footnote" role="doc-noteref">6</a></sup>. It is about the underlying ideas: evaluation, data structures, and the way programs are shaped.</p>

<p>Below are the family resemblances hiding in plain sight.</p>

<h3 id="1-prefix-thinking-verbs-first">1. Prefix thinking: verbs first</h3>

<p>Lisp’s signature habit is that functions come first, arguments follow.</p>

<figure class="highlight"><pre><code class="language-lisp" data-lang="lisp"><span class="p">(</span><span class="nb">+</span> <span class="mi">3</span> <span class="mi">4</span><span class="p">)</span>
<span class="p">(</span><span class="nv">forward</span> <span class="mi">50</span><span class="p">)</span>
<span class="p">(</span><span class="nv">right</span> <span class="mi">90</span><span class="p">)</span></code></pre></figure>

<p>Logo does the same thing, it just drops the parentheses and speaks like a teacher.</p>

<figure class="highlight"><pre><code class="language-logo" data-lang="logo">sum 3 4
fd 50
rt 90</code></pre></figure>

<p>Same mental model. Different costume.</p>

<h3 id="2-lists-matter-a-lot">2. Lists matter a lot</h3>

<p>Lisp is built on lists. Logo inherits that list-centered worldview.</p>

<p>In many Logo dialects you can work with lists directly:</p>

<figure class="highlight"><pre><code class="language-logo" data-lang="logo">print [1 2 3 4]
print first [a b c]     ; a
print butfirst [a b c]  ; [b c]</code></pre></figure>

<p>If you have ever met Lisp’s car and cdr, you can feel the same head-and-tail spirit here, just with names that won’t scare a fourth grader.</p>

<h3 id="3-quoting-and-symbols-name-vs-value">3. Quoting and symbols: “name” vs “value”</h3>

<p>In Lisp, quoting is essential because you often want to talk about symbols without evaluating them.</p>

<p>Logo has a similar separation between a name and a value.</p>

<p>In UCBLogo-style notation:</p>

<figure class="highlight"><pre><code class="language-logo" data-lang="logo">make "x 10
print :x</code></pre></figure>

<p>The “x is the symbol name. The :x is the value stored in that name.</p>

<p>Different punctuation, same conceptual split: symbol vs value, data vs evaluation.</p>

<h3 id="4-recursion-feels-natural-not-exotic">4. Recursion feels natural, not exotic</h3>

<p>Lisp culture loves recursion because it pairs naturally with lists and self-similar problems.</p>

<p>Logo teaches recursion early too, especially in dialects like UCBLogo.</p>

<p>A simple recursive spiral:</p>

<figure class="highlight"><pre><code class="language-logo" data-lang="logo">to spiral :n
if :n &lt; 1 [stop]
fd :n
rt 90
spiral :n - 1
end</code></pre></figure>

<p>Here we are declaring the function named spiral. <code class="language-plaintext highlighter-rouge">to</code> is the keyword to declare functions in Logo.</p>

<p>This is not “turtle magic.” This is a core Lisp-family habit: define a procedure, then solve the big problem by repeatedly solving smaller versions of it.</p>

<h3 id="5-code-as-data-vibes-instruction-lists-you-can-run">5. Code-as-data vibes: instruction lists you can run</h3>

<p>One of Lisp’s deepest tricks is that code and data are made of the same stuff. That enables patterns like building code as a data structure, then evaluating it.</p>

<p>Logo approaches that idea in a friendlier way: lists can represent sequences of commands, and many Logo environments support executing those command lists.</p>

<p>Even when you never say the word “eval,” you are inching toward the same philosophical cliff: programs can be treated as manipulable objects.</p>

<p>That is very Lisp. It is also very sneaky.</p>

<h2 id="final-thoughts">Final Thoughts</h2>

<p>Logo doesn’t look like Lisp because it was designed for humans first, especially young humans.</p>

<p>But the bones show through:  <br />
	1.	Prefix function application (verbs first)<br />
	2.	List-centered data thinking<br />
	3.	Quoting and symbol/value separation<br />
	4.	Comfort with recursion<br />
	5.	A path toward code-as-data</p>

<p>So the sentence “Logo is a Lisp dialect” is not a joke. It is a reminder that programming languages can share a soul even when they do not share a wardrobe.</p>

<h2 id="back-where-it-all-begin">Back where it all begin</h2>

<p>In Class IV, we had no idea that we were accidentally being taught one of the deepest ideas in CS, that lists can represent both data and instructions, and the difference between them is often just “how you choose to evaluate.”</p>

<hr />

<h2 id="notes-and-references">Notes and references</h2>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>St. George’s College, Agra <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p>Agra is a city situated on the banks of River Yamuna, around 200Km south of Delhi, in the state of Uttar Pradesh in India. It was once a Mughal capital and is famous for mostly Mughal Architecture with two famous buildings of that time being - Taj Mahal, a mausaoleum build by Shahjahan for his wife and Fatehpur Sikri, the fort that was eventually abandoned by Akbar. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>My memory is vague on this and I have not corroborated this with the school. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:4">
      <p>I don’t remember the version of Logo, whether it was UCB Logo or MSW Logo. More information about the language can be found <a href="https://el.media.mit.edu/logo-foundation/index.html">here</a>. <a href="#fnref:4" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:5">
      <p>Descriptions of Logo as a Lisp dialect / Lisp-family language are common in historical and documentation sources. A good starting point is the MIT Logo Foundation page and the UCBLogo documentation. (URLs for easy copying: https://el.media.mit.edu/logo-foundation/ and https://people.eecs.berkeley.edu/~bh/logo.html) <a href="#fnref:5" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:6">
      <p>In Linguistic, we often talk about Deep Structures and surface structures. Surface structure is how the language is spoken in contrast to Deep structure which deals with the deeper meaning. <a href="https://en.wikipedia.org/wiki/Deep_structure_and_surface_structure?wprov=sfti1#">Deep and Surface Structures</a> <a href="#fnref:6" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Computer Science" /><category term="Series 2 - Turtle, BASIC, and the Long Road to Taste" /><category term="logo" /><category term="lisp" /><category term="computer-science" /><category term="education" /><category term="turtle-graphics" /><category term="programming-language" /><summary type="html"><![CDATA[Why Logo can be called a Lisp dialect even though it does not look like one?]]></summary></entry><entry><title type="html">Vibe Coding and the Baby Genius Problem</title><link href="https://systemhalted.in/2025/12/15/vibe-coding-and-baby-genius/" rel="alternate" type="text/html" title="Vibe Coding and the Baby Genius Problem" /><published>2025-12-15T00:00:00+00:00</published><updated>2025-12-15T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/15/vibe-coding-and-baby-genius</id><content type="html" xml:base="https://systemhalted.in/2025/12/15/vibe-coding-and-baby-genius/"><![CDATA[<p>Vibe coding has been ridiculously fun.</p>

<p>It has brought back the joy to programming. The kind of joy you thought adulthood, meetings, and Jira had permanently confiscated.</p>

<p>And yet, right now, most agents are more or less <strong>super-intelligent babies</strong>.</p>

<p>They are brilliant. They are fast. They can surprise you.
But they still need to be fed context again and again.</p>

<p>Today, while working on my service virtualizer, I had to continuously inform the agent about my preference for naming API models and domain models.
The difference matters:</p>

<ul>
  <li>API models are edge interfaces, representing outward state.</li>
  <li>Domain models are internal shapes, used to pass messages within the API.</li>
</ul>

<p>The agent continuously “lied” that it was following the instructions I provided under the <code class="language-plaintext highlighter-rouge">.github/instructions</code> folder.
After multiple rounds of trial and error, it partially understood the assignment.</p>

<p>That’s the gap between intelligence and autonomy.</p>

<h2 id="the-autonomy-ladder-vibe-coding-ping-pong-vacation">The autonomy ladder: vibe coding, ping pong, vacation</h2>

<p>It is going to take some time before agents can act independently while you play ping pong.
And slightly longer for you to delegate the work completely to a few AI agents and go on vacation.</p>

<p>AI agents need to be <strong>context-aware</strong> for me to enjoy ping pong.
They need to write properly logged and observable clean code before I can trust them enough to enjoy a vacation.</p>

<p>That last line is the whole story.</p>

<p>Ping pong is a context problem.
Vacation is an accountability problem.</p>

<h2 id="a-concrete-example-my-model-naming-rule">A concrete example: my model naming rule</h2>

<p>This is where “feed context again and again” shows up in real code.</p>

<h3 id="api-models-should-be-nouns">API models should be nouns</h3>

<p>API models “datafy” representational state.
So there is no separate request and response.
There is only one state to represent for both request and response.</p>

<p>Some fields are read-only, sure.
But it is still one state.</p>

<p>So instead of:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">CreateEndpointRequest</code></li>
  <li><code class="language-plaintext highlighter-rouge">CreateEndpointResponse</code></li>
  <li><code class="language-plaintext highlighter-rouge">EndpointResponse</code></li>
</ul>

<p>I want:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">Endpoint</code></li>
</ul>

<h3 id="domain-models-should-not-say-request-response-or-data">Domain models should not say “Request”, “Response”, or “Data”</h3>

<p>Domain models don’t need <code class="language-plaintext highlighter-rouge">Request</code>, <code class="language-plaintext highlighter-rouge">Response</code>, or <code class="language-plaintext highlighter-rouge">Data</code> as suffixes.
That information is redundant.</p>

<p><code class="language-plaintext highlighter-rouge">EndpointData</code> as a class serves no purpose compared to <code class="language-plaintext highlighter-rouge">Endpoint</code> as a class.</p>

<p>If it is the domain concept, name it like the concept:
<code class="language-plaintext highlighter-rouge">Endpoint</code>, <code class="language-plaintext highlighter-rouge">VirtualService</code>, <code class="language-plaintext highlighter-rouge">Route</code>, <code class="language-plaintext highlighter-rouge">Rule</code>, <code class="language-plaintext highlighter-rouge">Match</code>, <code class="language-plaintext highlighter-rouge">Mapping</code>.</p>

<p>If context matters, packages can carry it:
<code class="language-plaintext highlighter-rouge">in.systemhalted.api.model.Endpoint</code>
<code class="language-plaintext highlighter-rouge">in.systemhalted.domain.model.Endpoint</code></p>

<p>Same noun, different layer.</p>

<h2 id="the-real-issue-preferences-are-not-enforceable">The real issue: preferences are not enforceable</h2>

<p>Human teams survive because we turn preferences into systems.</p>

<p>“Please follow this convention” is polite.
But politeness is not a compiler.</p>

<p>If you want agents to stop “lying” (really: confidently guessing), you have to move from memory to mechanism.</p>

<p>In other words, from vibes to accountability.</p>

<h2 id="make-conventions-executable">Make conventions executable</h2>

<p>The big move is simple:
turn conventions into checks that fail loudly.</p>

<p>Then the agent doesn’t need to remember your rules.
It just needs to pass reality.</p>

<h3 id="option-1-enforce-architecture-rules-with-archunit">Option 1: enforce architecture rules with ArchUnit</h3>

<p><a href="https://www.archunit.org/">ArchUnit</a> is a Java testing library for validating architectural decisions in code.
It lets you write tests for package boundaries, dependency direction, layering rules, and conventions that are otherwise tribal knowledge.</p>

<p>That is exactly what an AI agent struggles with: it will agree with tribal knowledge, then forget it, then agree again.</p>

<p>Here’s a practical enforcement approach:</p>

<ul>
  <li>API models live in <code class="language-plaintext highlighter-rouge">..api.model..</code> and must not end with <code class="language-plaintext highlighter-rouge">Request</code>, <code class="language-plaintext highlighter-rouge">Response</code>, or <code class="language-plaintext highlighter-rouge">Data</code></li>
  <li>Domain models live in <code class="language-plaintext highlighter-rouge">..domain.model..</code> and must not end with <code class="language-plaintext highlighter-rouge">Request</code>, <code class="language-plaintext highlighter-rouge">Response</code>, or <code class="language-plaintext highlighter-rouge">Data</code></li>
  <li>Domain must not depend on API</li>
</ul>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="c1">// src/test/java/in/systemhalted/architecture/ModelConventionsTest.java</span>
<span class="kn">package</span> <span class="nn">in.systemhalted.architecture</span><span class="o">;</span>

<span class="kn">import</span> <span class="nn">com.tngtech.archunit.core.domain.JavaClasses</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">com.tngtech.archunit.core.importer.ClassFileImporter</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">com.tngtech.archunit.lang.ArchRule</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">org.junit.jupiter.api.Test</span><span class="o">;</span>

<span class="kn">import</span> <span class="nn">static</span> <span class="n">com</span><span class="o">.</span><span class="na">tngtech</span><span class="o">.</span><span class="na">archunit</span><span class="o">.</span><span class="na">lang</span><span class="o">.</span><span class="na">syntax</span><span class="o">.</span><span class="na">ArchRuleDefinition</span><span class="o">.</span><span class="na">classes</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">static</span> <span class="n">com</span><span class="o">.</span><span class="na">tngtech</span><span class="o">.</span><span class="na">archunit</span><span class="o">.</span><span class="na">lang</span><span class="o">.</span><span class="na">syntax</span><span class="o">.</span><span class="na">ArchRuleDefinition</span><span class="o">.</span><span class="na">noClasses</span><span class="o">;</span>

<span class="kd">class</span> <span class="nc">ModelConventionsTest</span> <span class="o">{</span>

    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">JavaClasses</span> <span class="n">classes</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">ClassFileImporter</span><span class="o">()</span>
            <span class="o">.</span><span class="na">importPackages</span><span class="o">(</span><span class="s">"in.systemhalted"</span><span class="o">);</span>

    <span class="nd">@Test</span>
    <span class="kt">void</span> <span class="nf">api_models_must_not_end_with_request_response_or_data</span><span class="o">()</span> <span class="o">{</span>
        <span class="nc">ArchRule</span> <span class="n">rule</span> <span class="o">=</span> <span class="n">classes</span><span class="o">()</span>
                <span class="o">.</span><span class="na">that</span><span class="o">().</span><span class="na">resideInAPackage</span><span class="o">(</span><span class="s">"..api.model.."</span><span class="o">)</span>
                <span class="o">.</span><span class="na">should</span><span class="o">().</span><span class="na">haveSimpleNameNotEndingWith</span><span class="o">(</span><span class="s">"Request"</span><span class="o">)</span>
                <span class="o">.</span><span class="na">andShould</span><span class="o">().</span><span class="na">haveSimpleNameNotEndingWith</span><span class="o">(</span><span class="s">"Response"</span><span class="o">)</span>
                <span class="o">.</span><span class="na">andShould</span><span class="o">().</span><span class="na">haveSimpleNameNotEndingWith</span><span class="o">(</span><span class="s">"Data"</span><span class="o">);</span>

        <span class="n">rule</span><span class="o">.</span><span class="na">check</span><span class="o">(</span><span class="n">classes</span><span class="o">);</span>
    <span class="o">}</span>

    <span class="nd">@Test</span>
    <span class="kt">void</span> <span class="nf">domain_models_must_not_end_with_request_response_or_data</span><span class="o">()</span> <span class="o">{</span>
        <span class="nc">ArchRule</span> <span class="n">rule</span> <span class="o">=</span> <span class="n">classes</span><span class="o">()</span>
                <span class="o">.</span><span class="na">that</span><span class="o">().</span><span class="na">resideInAPackage</span><span class="o">(</span><span class="s">"..domain.model.."</span><span class="o">)</span>
                <span class="o">.</span><span class="na">should</span><span class="o">().</span><span class="na">haveSimpleNameNotEndingWith</span><span class="o">(</span><span class="s">"Request"</span><span class="o">)</span>
                <span class="o">.</span><span class="na">andShould</span><span class="o">().</span><span class="na">haveSimpleNameNotEndingWith</span><span class="o">(</span><span class="s">"Response"</span><span class="o">)</span>
                <span class="o">.</span><span class="na">andShould</span><span class="o">().</span><span class="na">haveSimpleNameNotEndingWith</span><span class="o">(</span><span class="s">"Data"</span><span class="o">);</span>

        <span class="n">rule</span><span class="o">.</span><span class="na">check</span><span class="o">(</span><span class="n">classes</span><span class="o">);</span>
    <span class="o">}</span>

    <span class="nd">@Test</span>
    <span class="kt">void</span> <span class="nf">domain_must_not_depend_on_api</span><span class="o">()</span> <span class="o">{</span>
        <span class="nc">ArchRule</span> <span class="n">rule</span> <span class="o">=</span> <span class="n">noClasses</span><span class="o">()</span>
                <span class="o">.</span><span class="na">that</span><span class="o">().</span><span class="na">resideInAPackage</span><span class="o">(</span><span class="s">"..domain.."</span><span class="o">)</span>
                <span class="o">.</span><span class="na">should</span><span class="o">().</span><span class="na">dependOnClassesThat</span><span class="o">().</span><span class="na">resideInAnyPackage</span><span class="o">(</span><span class="s">"..api.."</span><span class="o">);</span>

        <span class="n">rule</span><span class="o">.</span><span class="na">check</span><span class="o">(</span><span class="n">classes</span><span class="o">);</span>
    <span class="o">}</span>
<span class="o">}</span></code></pre></figure>

<p>This does not prove a name is a noun.
But it blocks the most common failure mode: growing a forest of <code class="language-plaintext highlighter-rouge">*Request</code>, <code class="language-plaintext highlighter-rouge">*Response</code>, and <code class="language-plaintext highlighter-rouge">*Data</code> types that all mean the same thing.</p>

<h3 id="option-2-generate-api-models-handcraft-domain-models">Option 2: generate API models, handcraft domain models</h3>

<p>If your API layer is OpenAPI driven, treat API models as edge artifacts and generate them.
Then keep domain models intentionally authored and stable.</p>

<p>The principle is simple:</p>
<blockquote>
  <p>when the outside world changes, your domain model shouldn’t break.</p>
</blockquote>

<h3 id="option-3-a-definition-of-done-for-agents">Option 3: a definition of done for agents</h3>

<p>Agents struggle because “done” is fuzzy.</p>

<p>So make it concrete:</p>

<ol>
  <li>Restate conventions from <code class="language-plaintext highlighter-rouge">.github/instructions</code> in plain English</li>
  <li>Implement the change</li>
  <li>Run tests</li>
  <li>Show evidence: test output, files changed, and convention checks passing</li>
</ol>

<p>That’s how you replace “trust me” with “see for yourself.”</p>

<h2 id="observability-is-the-vacation-requirement">Observability is the vacation requirement</h2>

<p>Ping pong needs context awareness.
Vacation needs observability.</p>

<p>If an agent writes code that “works” but cannot explain itself at runtime, you have not delegated work.
You have adopted a mystery.</p>

<p>Vacation-grade code needs boring, grown-up traits:</p>

<ul>
  <li>structured logs you can search</li>
  <li>correlation IDs you can follow</li>
  <li>meaningful error handling</li>
  <li>metrics and traces where it matters</li>
</ul>

<p>Because on vacation, the only thing worse than an outage is one you cannot diagnose from the logs.</p>

<h2 id="final-thoughts">Final thoughts</h2>

<p>Agents don’t mainly need to be smarter.
They need to be more accountable.</p>

<p>An agent without a stop condition is just a very confident infinite loop.</p>

<p>The trick is not to lecture the agent harder.
The trick is to make “following instructions” measurable.</p>

<p>Then you can pick up the paddle.</p>

<p>And later, maybe, the suitcase.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Software Engineering" /><category term="AI" /><category term="agentic-workflows" /><category term="vibe-coding" /><category term="testing" /><category term="observability" /><category term="conventions" /><summary type="html"><![CDATA[Vibe coding is fun again. However, Agents are still baby geniuses. The fix is turning preferences into accountability.]]></summary></entry><entry><title type="html">Project Jigsaw (JPMS) - Part 1 - What is Modularity?</title><link href="https://systemhalted.in/2025/12/14/jigsaw-what-is-modularity/" rel="alternate" type="text/html" title="Project Jigsaw (JPMS) - Part 1 - What is Modularity?" /><published>2025-12-14T00:00:00+00:00</published><updated>2025-12-14T00:00:00+00:00</updated><id>https://systemhalted.in/2025/12/14/jigsaw-what-is-modularity</id><content type="html" xml:base="https://systemhalted.in/2025/12/14/jigsaw-what-is-modularity/"><![CDATA[<h2 id="a-note-from-the-future">A note from the future</h2>

<p>I began this post in 2016, when Java 9 was still unreleased and Project Jigsaw felt like an approaching weather system. Java 9 eventually shipped, and the module system became real, imperfect, and unexpectedly enlightening.</p>

<p>This post keeps the original question intact: what is modularity and why did Java need the platform itself to care?</p>

<h2 id="java-already-had-modules-right">Java already had “modules”… right?</h2>

<p>For the past few years, Java has evolved quickly, mostly for the better. JDK 8 changed everyday Java with lambdas and streams, making a more functional style feel native instead of like cosplay.</p>

<p>Then came JDK 9 and Project Jigsaw, the Java Platform Module System (JPMS). The obvious objection was, and still is:</p>

<p>Java already has JARs. Enterprise Java has WARs and EARs. Source code has packages and access modifiers. So why add “modules” at all?</p>

<p>To answer that, we need to be annoyingly precise about what a module is.</p>

<h2 id="what-is-a-module">What is a module?</h2>

<p>A module is not just “a bunch of related code.” That definition is so generous it would make my <code class="language-plaintext highlighter-rouge">Downloads/</code> folder a module, and it absolutely should not be trusted with responsibility.</p>

<p>A better definition:</p>

<p>A module is a unit with an enforceable boundary.</p>

<p>In practice, a module needs at least these traits.</p>

<h3 id="1-encapsulation-a-hidden-interior">1. Encapsulation (a hidden interior)</h3>

<p>Encapsulation is the right to say: “this part is implementation detail; do not touch.”</p>

<p>Java supports encapsulation via access modifiers (<code class="language-plaintext highlighter-rouge">private</code>, package-private, <code class="language-plaintext highlighter-rouge">protected</code>, <code class="language-plaintext highlighter-rouge">public</code>) and via packages. In the POJO world, we keep fields private and expose behavior through methods so nobody can accidentally mutate internal state and then act surprised when physics happens.</p>

<p>But here is the catch:</p>

<p>Packages are excellent organizing units, but by themselves they are not deployment boundaries.</p>

<p>Once code is on the classpath, it tends to behave like a single sprawling neighborhood where everyone can wander into everyone else’s backyard, sometimes through reflection, sometimes through “it was convenient,” sometimes through sheer dependency gravity.</p>

<h3 id="2-a-public-surface-an-intentional-api">2. A public surface (an intentional API)</h3>

<p>A module must have a public surface: a set of types meant to be used by outsiders.</p>

<p>This matters because modularity is not just hiding. It is also communicating on purpose.</p>

<p>When modules interact, they should do so through the exported API, not through accidental knowledge of internals. This is how systems remain refactorable without becoming brittle.</p>

<p>So far, this sounds like “write disciplined code,” which is true, and still not the full story.</p>

<p>The painful question is: can the platform help enforce that discipline?</p>

<h2 id="why-packages-and-jars-were-not-enough">Why packages and JARs were not enough?</h2>

<p>Packages and JARs let us aspire to be modular. They do not consistently let us enforce it.</p>

<p>Here are the classic failure modes that show up as systems grow.</p>

<h3 id="1-the-classpath-is-a-soup">1. The classpath is a soup</h3>

<p>The classpath is wonderfully simple and brutally permissive. Put things on it, and they exist.</p>

<p>Common outcomes:</p>

<ul>
  <li>Accidental dependencies form silently.</li>
  <li>Internals become “public” by habit. “Just import it.”</li>
  <li>Debugging becomes archaeology. “Who pulled in this version, and why does it only fail on Jenkins?”</li>
</ul>

<h3 id="2-jar-hell-is-real-and-it-has-receipts">2. JAR hell is real, and it has receipts</h3>

<p>When multiple JARs provide overlapping classes, or when classloading order changes, you can get failures that only appear at runtime and only on certain machines.</p>

<p>Even when your build tool is trying to help, the model is still basically: assemble a pile of bytecode and hope it behaves.</p>

<h3 id="3-encapsulation-at-runtime-was-historically-negotiable">3. Encapsulation at runtime was historically negotiable</h3>

<p>Before JPMS, it was common for libraries to reach into non-public areas, either:</p>

<ul>
  <li>Using reflection to access private members.</li>
  <li>Using internal JDK APIs because they existed and were “handy.”</li>
</ul>

<p>This worked until it did not. And the “did not” usually arrived as a production upgrade - not an upgrade by choice but force.</p>

<h3 id="4-split-packages-and-duplicate-worlds">4. Split packages and duplicate worlds</h3>

<p>On the classpath you can end up with the same package name spread across multiple JARs. Tools can limp along, humans can suffer quietly, and then one day something breaks in a way that makes you question reality.</p>

<p>A modular system has to be stricter about identity, or it cannot reason about the graph.</p>

<h2 id="what-jigsaw-actually-adds">What Jigsaw actually adds</h2>

<p>Project Jigsaw turns modularity into something the compiler and runtime can understand.</p>

<p>A Java module has:</p>

<ul>
  <li>A name (a stronger identity than “whatever the filename is”).</li>
  <li>Declared dependencies (what it requires).</li>
  <li>Declared exports (what it makes available to other modules).</li>
  <li>Strong encapsulation by default (if you do not export it, it is not part of your public world).</li>
</ul>

<p>This is expressed with a module descriptor: <code class="language-plaintext highlighter-rouge">module-info.java</code>.</p>

<p>A minimal example:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">billing</span> <span class="o">{</span>
    <span class="n">requires</span> <span class="n">java</span><span class="o">.</span><span class="na">sql</span><span class="o">;</span>
    <span class="n">exports</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">billing</span><span class="o">.</span><span class="na">api</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>The point is not ceremony. The point is boundaries that can be checked.</p>

<h2 id="packages-vs-modules-a-clean-mental-model">Packages vs modules, a clean mental model</h2>

<p>Think of it like this:</p>

<ul>
  <li>A package groups related types and helps structure code.</li>
  <li>A module groups packages and declares which packages are visible to the outside world.</li>
</ul>

<p>Packages help you organize. Modules help you enforce.</p>

<h2 id="enforce-how-exactly">“Enforce” how, exactly?</h2>

<p>JPMS enforces things in two major places: compilation and runtime.</p>

<h3 id="1-reliable-configuration-dependency-truth">1. Reliable configuration (dependency truth)</h3>

<p>With modules, dependencies are not an emergent property of “whatever happens to be on the classpath today.”</p>

<p>Instead, the runtime resolves a module graph:</p>

<ul>
  <li>Each module declares what it requires.</li>
  <li>The system checks that required modules exist.</li>
  <li>The system checks for conflicts that would make the graph incoherent.</li>
</ul>

<p>This catches certain categories of surprise runtime failure earlier, because the platform can actually see your dependency structure.</p>

<h3 id="2-strong-encapsulation-real-boundaries">2. Strong encapsulation (real boundaries)</h3>

<p>With modules, code in a non-exported package is not accessible to other modules at compile time, and at runtime access is strongly controlled.</p>

<p>This is the key philosophical shift:</p>

<blockquote>
  <p>You are not just suggesting which parts are internal. You are declaring it, and the platform can enforce it.</p>
</blockquote>

<h2 id="a-quick-tour-of-module-descriptor-concepts">A quick tour of module descriptor concepts</h2>

<p>The <code class="language-plaintext highlighter-rouge">module-info.java</code> file is small, but it has teeth. Here are the ideas you will see in real projects.</p>

<h3 id="requires"><code class="language-plaintext highlighter-rouge">requires</code></h3>

<p>A module can state that it depends on another module.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">app</span> <span class="o">{</span>
    <span class="n">requires</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">billing</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<h3 id="exports"><code class="language-plaintext highlighter-rouge">exports</code></h3>

<p>A module can export a package to make it part of its public API.</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">billing</span> <span class="o">{</span>
    <span class="n">exports</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">billing</span><span class="o">.</span><span class="na">api</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>Everything else stays internal by default.</p>

<p>There is also qualified export, where you export only to specific friend modules:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">billing</span> <span class="o">{</span>
    <span class="n">exports</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">billing</span><span class="o">.</span><span class="na">internal</span> <span class="n">to</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">app</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>That is useful for tightly coupled modules, though it should be used sparingly because it creates special relationships that age poorly.</p>

<h3 id="opens"><code class="language-plaintext highlighter-rouge">opens</code></h3>

<p>Exporting is about normal access. Opening is about reflection.</p>

<p>Frameworks use reflection for dependency injection, serialization, proxies, and other wizardry. JPMS makes you be explicit about that:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">model</span> <span class="o">{</span>
    <span class="n">opens</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">model</span><span class="o">.</span><span class="na">entities</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>You can also open to specific modules only:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">model</span> <span class="o">{</span>
    <span class="n">opens</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">model</span><span class="o">.</span><span class="na">entities</span> <span class="n">to</span> <span class="n">com</span><span class="o">.</span><span class="na">fasterxml</span><span class="o">.</span><span class="na">jackson</span><span class="o">.</span><span class="na">databind</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<h2 id="services-uses-and-provides">Services: <code class="language-plaintext highlighter-rouge">uses</code> and <code class="language-plaintext highlighter-rouge">provides</code></h2>

<p>The service mechanism is the module-friendly way to do plugin architecture.</p>

<p>Consumer:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">app</span> <span class="o">{</span>
    <span class="n">uses</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">spi</span><span class="o">.</span><span class="na">PaymentProvider</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<p>Provider:</p>

<figure class="highlight"><pre><code class="language-java" data-lang="java"><span class="n">module</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">stripe</span> <span class="o">{</span>
    <span class="n">provides</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">spi</span><span class="o">.</span><span class="na">PaymentProvider</span>
        <span class="n">with</span> <span class="n">com</span><span class="o">.</span><span class="na">example</span><span class="o">.</span><span class="na">stripe</span><span class="o">.</span><span class="na">StripePaymentProvider</span><span class="o">;</span>
<span class="o">}</span></code></pre></figure>

<h2 id="but-what-about-my-existing-non-modular-jars">But what about my existing non-modular JARs?</h2>

<p>JPMS did not pretend the world would instantly become modular. It introduced a migration story, and it is worth understanding because it explains a lot of real-world behavior.</p>

<h3 id="the-unnamed-module">The unnamed module</h3>

<p>If you put JARs on the classpath instead of the module path, they effectively live in the unnamed module. This unnamed module can read everything, and everything can read it, which is intentionally permissive to keep legacy code running.</p>

<p>It is the compatibility bridge. It is also where modular purity goes to take a nap.</p>

<h3 id="automatic-modules">Automatic modules</h3>

<p>If you put a regular JAR on the module path, the system can treat it as an automatic module with a derived name and permissive readability rules.</p>

<p>This is a practical stepping stone, not a perfect end state.</p>

<p>A common migration path looks like:</p>

<ul>
  <li>Run as classpath, accept the unnamed module.</li>
  <li>Move some things to module path, tolerate automatic modules.</li>
  <li>Modularize the important libraries and applications over time.</li>
</ul>

<p>Not glamorous, but it works, and it respects the fact that software is mostly sedimentary rock.</p>

<h2 id="the-jdk-itself-became-modular">The JDK itself became modular</h2>

<p>One of the most concrete outcomes of Jigsaw is that the JDK stopped being a monolith. It became a set of modules.</p>

<p>This matters because:</p>

<ul>
  <li>The platform itself has clearer internal boundaries.</li>
  <li>The JDK can strongly encapsulate internal APIs, reducing accidental dependencies on JDK internals.</li>
  <li>Tools can assemble smaller runtimes for specific applications.</li>
</ul>

<p>That last point is where tools like <code class="language-plaintext highlighter-rouge">jlink</code> enter the story, but it is better saved for a later post, once the basics are anchored.</p>

<h2 id="so-why-project-jigsaw">So why Project Jigsaw?</h2>

<p>Now we can answer the original “why” without hand-waving.</p>

<p>Java had packaging and namespacing. It did not have platform-enforced boundaries.</p>

<p>Project Jigsaw exists to make modularity:</p>

<ul>
  <li>Declarative, so the platform can see your intent.</li>
  <li>Verifiable, so tools can reason about your dependency graph.</li>
  <li>Enforceable, so “internal” actually means internal.</li>
</ul>

<p>It turns modularity from a cultural norm into a constraint you can build against.</p>

<p>That is the difference between “please do not touch” and “the door is locked.”</p>

<h2 id="what-is-next">What is next</h2>

<p>This was Part 1: the definition, the motivation, and the shape of the solution.</p>

<p>In Part 2, we will go concrete:</p>

<ul>
  <li>A tiny multi-module project you can compile and run.</li>
  <li>The first “why can I not access this package anymore?” moment, explained.</li>
  <li>Practical patterns: what to export, what to keep internal, and how to avoid designing a module system that only you understand.</li>
</ul>

<p>Because nothing teaches architecture faster than a compiler error that is technically correct and emotionally rude.</p>]]></content><author><name>Palak Mathur</name><email>insanethoughts@live.com</email></author><category term="Technology" /><category term="Software Engineering" /><category term="Series 3 - Project Jigsaw (JPMS)" /><category term="java" /><category term="jdk9" /><category term="project-jigsaw" /><category term="jpms" /><category term="modularity" /><category term="programming-language" /><summary type="html"><![CDATA[A practical definition of modularity in Java, why Jigsaw existed even though we already had packages and JARs, and what the module system actually enforces.]]></summary></entry></feed>